


HLS low latency (LL-HLS) is an extension of the HTTP Live Streaming protocol that reduces glass-to-glass delay from 10 to 30 seconds down to 2 to 5 seconds by using partial segments, blocking playlist reloads, and rendition reports. It preserves HLS compatibility with standard CDNs and players while approaching the interactivity of WebRTC. For scenarios where sub-second latency is critical, VideoSDK's Interactive Live Streaming offers an alternative with sub-second delay built on WebRTC.
Introduction
Sub-second latency is the difference between a live stream that feels alive and one that feels like a recording. When a football fan watching a stream hears their neighbor cheer a goal several seconds before seeing it on screen, the illusion of "live" breaks. The same applies to live commerce, where a host asks a question and waits for chat responses that arrive awkwardly late, or to remote education, where a teacher poses a quiz and students see it seconds after the clock starts.
HLS low latency, formally known as LL-HLS, is Apple's answer to this problem. Introduced in the HLS specification revision of 2020, it extends the widely deployed HLS protocol with mechanisms that shrink end-to-end delay from the typical 10 to 30 seconds down to a target of 2 to 5 seconds. It does this without abandoning the CDN-friendly, HTTP-based architecture that made HLS the dominant streaming protocol in the first place.
By the end of this article, you will understand how LL-HLS works at the protocol level, how it compares to traditional HLS and to WebRTC-based approaches like VideoSDK's Interactive Live Streaming, how to configure a CDN for LL-HLS delivery, and what trade-offs you accept when you chase lower latency over the HLS stack.
What is HLS Low Latency?
HLS low latency (LL-HLS) is defined as an extension to the HTTP Live Streaming protocol that enables glass-to-glass latency in the range of 2 to 5 seconds while maintaining backward compatibility with existing HLS infrastructure. It works by introducing partial segments, blocking playlist reloads, and rendition reports into the HLS manifest and segment delivery flow.
The original HLS protocol, introduced by Apple in 2009, was designed for reliability over latency. It segments media into files of 6 to 10 seconds, publishes a playlist that lists those segments, and instructs the player to download them sequentially. The result is a robust stream that handles network fluctuations gracefully but introduces significant delay. The player must buffer several segments before playback begins, and each segment adds to the cumulative latency.
Apple addressed this gap in the 2020 revision of the HLS specification. The revision introduced LL-HLS as a set of optional features that encoders, origin servers, CDNs, and players can implement to reduce latency without breaking compatibility with non-LL-HLS clients. A player that does not support LL-HLS simply ignores the new features and falls back to standard HLS behavior.
The core goal of LL-HLS is to achieve 2 to 5 seconds of glass-to-glass latency. This is not sub-second, and it does not compete with WebRTC for real-time interactivity. Instead, it occupies a middle ground: low enough for near-live experiences like sports commentary and live commerce, while retaining the scalability and CDN compatibility that make HLS the default choice for large-scale streaming.
Core Technical Mechanisms of HLS Low Latency
LL-HLS relies on three core mechanisms working together: blocking playlist reloads, partial segments, and rendition reports with delta updates. Each addresses a specific source of latency in the traditional HLS pipeline.
Blocking Playlist Reload
In traditional HLS, the player polls the playlist at regular intervals to discover new segments. If the playlist has not been updated, the player receives the same version and waits before requesting it again. This polling interval adds latency because the player may discover a new segment seconds after it becomes available.
Blocking playlist reload solves this by allowing the player to send a request with a query parameter indicating the expected next media sequence number. The origin server holds the request open until the next segment or partial segment is ready, then responds immediately. This eliminates the polling gap and ensures the player learns about new content the moment it is published.
The mechanism relies on HTTP long-polling. The player includes a query parameter specifying the media sequence number it expects. If that sequence is not yet available, the server blocks the response until it is. This reduces the discovery latency from the polling interval (typically 1 to 3 seconds) to near zero.
Partial Segments (Parts)
Partial segments are the single most impactful innovation in LL-HLS. Instead of waiting for a full segment (typically 2 to 6 seconds of media) to be encoded and published, the encoder splits each segment into smaller parts of 200 to 500 milliseconds and publishes them as they are produced.
The playlist includes references to these parts using the EXT-X-PART tag. A player that supports LL-HLS reads the part URIs and begins downloading them immediately, before the parent segment is complete. This means the player can start playback or buffering with just a few hundred milliseconds of media, rather than waiting for a full segment.
The trade-off is increased request volume. A 6-second segment split into 200-millisecond parts generates 30 HTTP requests per segment instead of one. This places higher demand on the CDN and the player's request pipeline, but it dramatically reduces the time between encoding and playback.
Rendition Report and Delta Updates
When a stream offers multiple renditions (different bitrates or resolutions), the player needs to know the current state of each rendition's playlist to make switching decisions. In traditional HLS, the player must fetch each rendition's playlist separately, adding latency and request overhead.
LL-HLS introduces the EXT-X-RENDITION-REPORT tag, which allows the master playlist or a media playlist to include information about the current state of other renditions. This consolidated response tells the player what media sequence and part number each rendition has reached, enabling faster adaptation decisions without additional requests.
Delta updates complement this by allowing the server to indicate that a playlist has not changed since the last request using the EXT-X-SKIP tag. The player can skip reprocessing the entire playlist and focus only on what is new. This reduces parsing overhead and speeds up the update cycle.
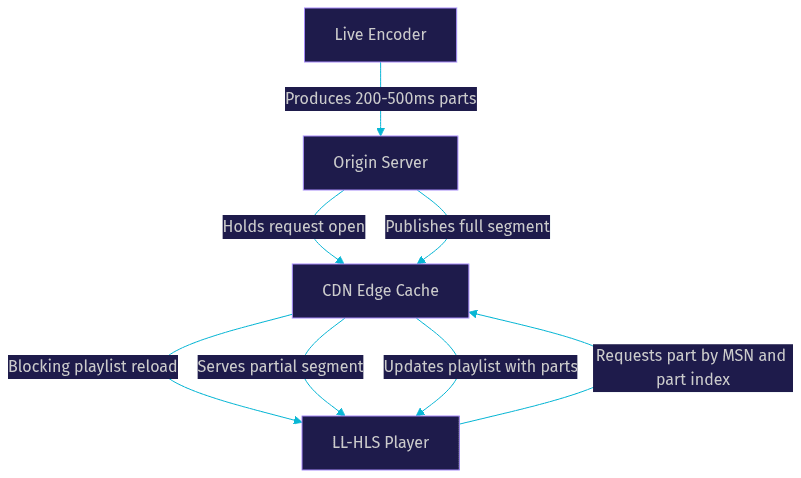
The following diagram shows how these mechanisms interact across the streaming pipeline for a single partial segment:
LL-HLS vs Traditional HLS: Side-by-Side Comparison
The difference between LL-HLS and traditional HLS is not just a latency number. It affects segment size, playlist behavior, CDN requirements, and player compatibility. Understanding these differences helps you decide whether the latency reduction justifies the operational complexity.
| Dimension | Traditional HLS | LL-HLS |
|---|---|---|
| Glass-to-glass latency | 10 to 30 seconds | 2 to 5 seconds |
| Segment size | 6 to 10 seconds | 2 to 6 seconds with parts |
| Partial segments | Not supported | 200 to 500 milliseconds |
| Playlist updates | Polling at fixed intervals | Blocking reload, instant notification |
| Rendition reports | Separate playlist fetches | Consolidated in single response |
| CDN compatibility | Universal | Requires query-string and blocking support |
| Player support | Universal | Requires LL-HLS-aware player |
| Request volume | Low (1 per segment) | High (1 per part, 10 to 30x more) |
| DRM support | Mature, widely supported | Limited or unsupported on many CDNs |
| Best for | Large-scale one-to-many broadcast | Near-live experiences needing 2 to 5s latency |
HLS low latency wins when you need latency low enough for near-real-time engagement but cannot justify the infrastructure cost and complexity of WebRTC. It trades off increased request volume, stricter CDN requirements, and limited DRM support for that latency reduction.
For use cases where even 2 to 5 seconds is too much, such as interactive live streaming where viewers join the stage or vote in real time, VideoSDK's Interactive Live Streaming provides sub-second latency built on WebRTC. The ILS mode uses the same SDK surface as VideoSDK's video calling, switched via a mode change, and supports host, co-host, and viewer roles with dynamic promotion.
Enabling LL-HLS on a CDN
Configuring a CDN for LL-HLS delivery is where most implementation effort goes. The CDN must handle query parameters, blocking requests, and cache policies that differ from standard HLS. Getting this wrong can negate all the latency benefits of the protocol.
Required Query Parameters
LL-HLS introduces three query parameters that the player sends with playlist requests: the media sequence number, the part number, and a skip directive. These parameters tell the origin server what state the player is in and what it expects next.
The media sequence number parameter tells the server which media sequence the player is waiting for. The part number parameter specifies which partial segment within that sequence the player wants. The skip directive indicates that the player supports delta updates and does not need the full playlist if nothing has changed.
Your CDN must be configured to whitelist these query parameters and forward them to the origin server. If the CDN strips or ignores them, the blocking reload mechanism breaks, and the player falls back to polling behavior with standard HLS latency. This is the single most common configuration error in LL-HLS deployments.
Cache-Control Settings
Cache policies for LL-HLS must differentiate between playlist files and media segments. Playlists change frequently and must have short time-to-live values at the edge cache, typically 1 to 3 seconds, so that updated playlists with new partial segments are available quickly.
Init segments and full media segments can have longer cache durations since they are immutable once published. A typical configuration sets a TTL of several hours or more for segments and init segments, matching standard HLS behavior.
The key principle is that playlists must be revalidated or refreshed aggressively, while segments can be cached normally. Some CDNs offer specialized LL-HLS configurations that handle this automatically, but others require manual cache-rule setup.
CDN Compatibility Checklist
Before committing to LL-HLS on a specific CDN, verify three things: the edge cache supports query-string forwarding for the LL-HLS parameters, the CDN supports HTTP/2 or HTTP/3 for the increased request volume, and TLS is properly configured for long-polling connections. Major CDNs including Akamai, Cloudflare, Fastly, and AWS CloudFront have documented LL-HLS support, but implementation details vary.
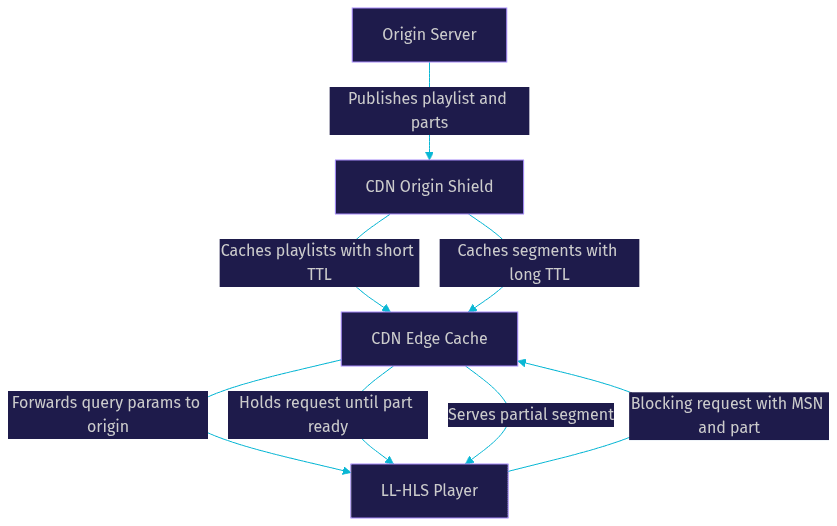
The following diagram illustrates the CDN configuration flow for LL-HLS:
Player Support and Fallback Strategies
Player support for LL-HLS has matured significantly since the specification was published, but it is not universal. Knowing which players support it and how unsupported players behave is essential for production deployments.
The most widely used LL-HLS-capable player is hls.js, the open-source JavaScript library that powers web-based HLS playback for many major streaming platforms. It has supported LL-HLS features since version 1.0, including blocking playlist reloads and partial segment fetching. Apple's AVPlayer on iOS and tvOS supports LL-HLS natively for content authored with the appropriate manifest tags. Dolby's streaming player and several commercial SDKs also offer LL-HLS support.
One of the design strengths of LL-HLS is its backward compatibility. A player that does not understand the LL-HLS extension tags simply ignores them. The EXT-X-PART, EXT-X-RENDITION-REPORT, and EXT-X-SKIP tags are ignored, and the player falls back to standard HLS behavior using the full segment URIs that are always present in the playlist alongside the partial segment references.
This means you can publish a single manifest that serves both LL-HLS-capable players and legacy players. The legacy player experiences standard HLS latency, while the LL-HLS player gets the reduced latency. There is no need to maintain separate endpoints or manifests.
The fallback is graceful but not silent. Viewers on legacy players will experience higher latency, which may be noticeable in interactive scenarios. If your use case requires consistent low latency across all viewers, consider a player-side capability check and a prompt to upgrade, or use a WebRTC-based solution like VideoSDK's ILS where latency is consistently sub-second regardless of player implementation.
Practical Tips for Production Deployments
Moving LL-HLS from a test environment to production introduces challenges that the specification does not fully address. Network conditions, monitoring, buffering, and security all require careful consideration.
Network-Quality Considerations
LL-HLS is more sensitive to network instability than traditional HLS. The smaller partial segments and faster playlist updates mean the player has less buffer to absorb bandwidth fluctuations. On stable, high-bandwidth connections, this is not a problem. On moderate or unstable connections, the player may experience more frequent rebuffering events.
If your audience includes viewers on mobile networks or in regions with variable connectivity, consider offering both LL-HLS and standard HLS endpoints. The player can attempt LL-HLS first and fall back to standard HLS if rebuffering exceeds a threshold. This hybrid approach preserves the latency benefit for well-connected viewers while maintaining stability for everyone else.
Monitoring Latency
Glass-to-glass latency is the metric that matters, and it is harder to measure than you might expect. It is the time between a frame being captured by the camera and that same frame being displayed on the viewer's screen. This spans the entire pipeline: capture, encoding, origin processing, CDN delivery, player buffering, and display.
A practical approach is to embed a timestamp in the video feed at capture time, either as a visible clock or as metadata, and compare it to the player's wall-clock time at display. Several commercial monitoring tools automate this process, but a manual spot-check with a visible clock is a good starting point.
Monitor not just average latency but also latency variance. If your glass-to-glass latency swings between 2 seconds and 8 seconds during a stream, the viewer experience is worse than a consistent 4-second latency. Variance often indicates issues with encoder throughput, CDN cache behavior, or player buffer management.
Handling Buffering Spikes
When the player encounters a buffering spike, it has two options: wait for more data, which increases latency, or reduce buffer, which risks playback stalls. LL-HLS players typically implement adaptive buffer management that adjusts the target buffer size based on current network conditions.
Configure your player to allow a buffer floor of at least 1 to 2 seconds to avoid stalls, with a ceiling that prevents latency from growing unbounded. If latency exceeds your target by more than 2 seconds, the player should seek to the live edge to catch up, accepting a brief discontinuity rather than letting latency accumulate.
Security Considerations
DRM support in LL-HLS is an ongoing challenge. Many CDN implementations do not yet support DRM-encrypted partial segments, because the key rotation and license exchange mechanisms were designed for full-segment granularity. If your content requires DRM, verify with your CDN and DRM provider that LL-HLS is supported before committing to it.
For content that does not require DRM but still needs access control, token-based authentication at the CDN edge works with LL-HLS. Ensure your token validation logic accounts for the query parameters that LL-HLS players send, so that authenticated requests are not rejected as malformed.
Real-World Use Cases
Live Sports Commentary
Live sports is the canonical use case for HLS low latency. When a stream lags behind real-time by 10 or more seconds, viewers following along on social media or with friends on the phone experience spoilers before seeing the action. LL-HLS reduces this gap to 2 to 5 seconds, close enough that the social experience feels synchronized. Sports broadcasters who need even lower latency for interactive features like live betting or real-time polls often combine LL-HLS delivery with WebRTC-based interactive overlays.
Interactive Live Commerce
Live commerce platforms depend on the host being able to interact with viewers in near real time. A host demonstrates a product, asks if viewers have questions, and reads chat responses. If the latency is 15 seconds, the host has moved on to the next product before the first question arrives. LL-HLS at 2 to 5 seconds makes the interaction feel natural, though truly interactive commerce where viewers join the stream as co-hosts benefits from VideoSDK's Interactive Live Streaming with sub-second latency.
Remote Education
In remote education, a teacher poses a quiz question and waits for student responses. High latency means the teacher either waits awkwardly or moves on before students have responded. LL-HLS brings the delay down to a range where live quizzes and Q&A sessions feel responsive. For fully interactive classrooms where students speak and share video, a real-time communication SDK like VideoSDK's video calling is more appropriate than any HLS variant.
Definitions Glossary
LL-HLS (Low Latency HLS): An extension to the HTTP Live Streaming protocol that reduces glass-to-glass latency to 2 to 5 seconds using partial segments, blocking playlist reloads, and rendition reports.
Partial Segment (Part): A sub-division of an HLS segment, typically 200 to 500 milliseconds, published to the playlist as soon as it is encoded so the player can begin downloading before the full segment is complete.
Blocking Playlist Reload: An LL-HLS mechanism where the player sends a request with an expected media sequence number and the server holds the response open until that sequence is available, eliminating polling delay.
Rendition Report: An LL-HLS feature using the EXT-X-RENDITION-REPORT tag to consolidate playlist state information for multiple renditions into a single response, reducing the number of requests the player must make.
Glass-to-Glass Latency: The total time from a video frame being captured by a camera to that frame being displayed on the viewer's screen, spanning encoding, CDN delivery, and player buffering.
Interactive Live Streaming (ILS): VideoSDK's low-latency streaming mode built on WebRTC that achieves sub-second latency by allowing viewers to be promoted to active speakers, suitable for scenarios where even LL-HLS latency is too high.
Key Takeaways
- HLS low latency (LL-HLS) reduces glass-to-glass latency from 10 to 30 seconds down to 2 to 5 seconds by using partial segments, blocking playlist reloads, and rendition reports.
- LL-HLS maintains backward compatibility with standard HLS, so legacy players gracefully fall back to normal latency without errors.
- CDN configuration is the most critical implementation step: query parameters must be whitelisted, playlists need short cache TTLs, and the CDN must support blocking requests.
- LL-HLS trades increased request volume and limited DRM support for its latency reduction, making it best suited for near-live experiences rather than true real-time interactivity.
- For use cases requiring sub-second latency where viewers interact directly, VideoSDK's Interactive Live Streaming provides a WebRTC-based alternative with host, co-host, and viewer roles.
Conclusion
HLS low latency is the pragmatic path for streaming teams who need to reduce live delay without abandoning the HLS ecosystem. It works with existing CDNs, existing players, and existing encoding pipelines, with extensions that any modern streaming stack can adopt. The 2 to 5 second latency target it achieves is enough for sports, commerce, and education use cases where traditional HLS feels sluggish but WebRTC feels like overkill.
If your use case demands true sub-second interactivity, where viewers become participants and every second counts, explore VideoSDK's Interactive Live Streaming as a complementary or alternative approach. You can also browse VideoSDK's code samples to see how ILS works in practice, or join the VideoSDK Discord community to discuss streaming architecture with other developers.
What are you building with low-latency streaming? Drop a comment below, I would love to hear whether you are going the LL-HLS route or exploring WebRTC-based alternatives.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ