


A low latency network is a network engineered to keep round-trip delay, jitter, and packet loss low enough for real-time interaction, typically under 100 milliseconds and often in single-digit milliseconds for demanding workloads. It combines purpose-built global backbones, edge presence, intelligent traffic steering, and modern congestion control. VideoSDK delivers this class of performance for real-time video and audio through its global real-time infrastructure, keeping interactive sessions responsive at scale.
Introduction to Low Latency Network
Every interactive application lives or dies by one number: the time it takes for a packet to travel from your user's device to your infrastructure and back. When that round-trip time creeps past 150 milliseconds, conversations become awkward, game inputs feel sluggish, and remote control loops become unsafe. A low latency network is a network deliberately designed, provisioned, and operated to keep that number as small and as stable as possible.
For most of the internet's history, content delivery was optimized for throughput, not timeliness. Traditional CDN-based delivery pushes cached files to servers near users, which works brilliantly for static images, video-on-demand segments, and software downloads. But a CDN is fundamentally a one-way distribution system. It cannot help when two people in different continents need to hear each other's voices within a fraction of a second, or when a factory controller needs to correct a robotic arm before it crashes.
That gap is why purpose-built low latency networks exist. Instead of caching content, they optimize the live path: the route packets take, the queues they wait in, the congestion signals they respond to, and the physical distance they travel. Sub-100 millisecond latency is the practical threshold for natural conversation, and modern real-time platforms routinely operate well below it. As of 2026, real-time communication providers such as VideoSDK target sub-300 millisecond end-to-end media latency for interactive video, with the network portion of that budget often in the tens of milliseconds.
The distinction matters to developers because you cannot fix a slow network at the application layer. You can compress video, adapt bitrates, and hide jitter with buffers, but physics and routing ultimately set your floor. Understanding how low latency networks work helps you choose infrastructure, diagnose performance problems, and set realistic expectations for your users.
Core Technologies Enabling Ultra-Low Latency
Ultra-low latency is not one technology but a stack of cooperating techniques spanning routing, link-layer scheduling, and transport-layer congestion control. Each attacks a different source of delay.
Software-Defined Real-Time Network (SDRTN)
A software-defined real-time network replaces static routing with continuous, adaptive path selection. Instead of following the default Border Gateway Protocol path, which can be circuitous and congested, an SDRTN monitors the health of every route across a private global underlay and steers each media stream onto the best available path in real time. Machine-learning models predict congestion before it happens, and traffic is rerouted around packet loss, jitter spikes, and outages within seconds.
Agora's SDRTN is the best-known commercial example, routing real-time media across a dedicated global mesh rather than the public internet. The same principle applies to any real-time platform: VideoSDK's global infrastructure routes participant media through optimized points of presence, so a call between Manila and Toronto avoids the congested transit links a default internet path would take. The result is lower and, critically, more predictable latency.
Time-Sensitive Networking (TSN) and Deterministic Networking (DetNet)
Where SDRTN optimizes best-effort paths, Time-Sensitive Networking makes latency a hard guarantee. TSN is a set of IEEE 802.1 standards that adds time synchronization, traffic shaping, and scheduled queuing to standard Ethernet, so critical frames are guaranteed a transmission slot with bounded delay and near-zero jitter. The IETF's Deterministic Networking (DetNet) work extends similar guarantees to the network layer, combining explicit routes, resource reservation, and protection paths.
These technologies dominate industrial automation, where a programmable logic controller must receive sensor data within a fixed microsecond-scale window or an assembly line stops. They also appear in 5G fronthaul, where radio units and baseband processors exchange timing-critical streams. For consumer internet applications TSN is rarely visible, but it defines the ceiling of what deterministic networking can achieve: latency that is not just low on average, but low always.
L4S and Advanced Congestion Control
The third lever is congestion control. Classic loss-based algorithms like Reno and CUBIC keep increasing their sending rate until packets drop, which fills router buffers and creates bufferbloat, the hidden latency spike that makes a video call stutter whenever someone starts a large download. The IETF's L4S architecture (Low Latency, Low Loss, Scalable Throughput) fixes this by giving flows accurate early congestion signals through Explicit Congestion Notification, so senders back off gently before queues build. The Prague congestion control is the L4S counterpart for end hosts, while Google's BBR models available bandwidth and round-trip time directly instead of waiting for loss, and DCTCP applies fine-grained ECN in data centers. Together these algorithms cut queuing delay, often the largest controllable component of end-to-end latency.
Architectural Pillars of a Low Latency Network
Technology standards only matter when they sit on top of sound physical and operational architecture. Three pillars define every serious low latency network.
Global Fiber Backbone and Edge Presence
Latency is bounded by physics: light in fiber travels roughly 200 kilometers per millisecond, so the shortest possible round trip between two points is set by distance. That is why low latency networks invest heavily in terrestrial and subsea fiber routes that shorten physical paths, and in edge points of presence placed close to population centers. When a user in Mumbai connects to a real-time session, terminating their media at a Mumbai edge POP instead of a Virginia data center removes tens of milliseconds from every packet's journey.
The hyperscalers illustrate the scale of this investment. AWS's global network interconnects regions with private long-haul fiber, and Azure and Google operate comparable backbones with hundreds of edge locations. Real-time platforms ride on or replicate this pattern: VideoSDK's infrastructure places media processing near users across regions, so the first network hop is short and the long-haul portion travels over optimized private paths rather than congested public transit.
Intelligent Traffic Steering and Real-Time Monitoring
A short path is not always the best path. A direct route through a congested exchange point can be worse than a slightly longer route over clean fiber. Intelligent traffic steering solves this with continuous telemetry: every edge POP measures round-trip time, jitter, and loss toward every other POP, feeding a global view of network health. AI-driven path selection then assigns each stream to the best route and reassigns it dynamically when conditions change, whether from congestion, a fiber cut, or regional outage. This is the operational heart of an SDRTN, and it is what separates a network that is fast on average from one that is fast during the Super Bowl.
Queuing Discipline and Active Queue Management
The most overlooked latency source is the queue inside every router. When buffers are large and managed passively, packets wait behind bulk traffic, adding hundreds of milliseconds of delay even on an otherwise fast link. Active Queue Management attacks this. Algorithms like CoDel and PIE detect standing queues and drop or mark packets early, signaling senders to slow down before bufferbloat forms. Priority queuing goes further by classifying traffic, so a voice packet is scheduled ahead of a file transfer on the same link. Combined with DiffServ marking, AQM ensures that even shared infrastructure treats latency-sensitive flows with the urgency they require.
Designing for Low Latency: Best-Practice Checklist
When you architect a real-time application, your job is to control everything you can at the design stage. This checklist covers the decisions with the largest latency impact.
Choose the right transport. TCP's head-of-line blocking and retransmission behavior make it a poor fit for live media, where a late packet is worse than a lost one. Real-time media uses UDP-based transports like RTP, while QUIC offers a modern middle ground for connection-oriented traffic, combining TCP-like reliability with UDP-like latency behavior and faster handshakes. Match the transport to the workload: reliability for signaling, timeliness for media.
Mark traffic for priority handling. DiffServ and DSCP marking let routers classify your packets into expedited or assured forwarding classes. A voice stream marked for expedited forwarding is queued ahead of best-effort traffic on any DiffServ-aware path. It costs nothing at the application layer and pays off on every congested hop.
Deploy compute close to users. Edge computing moves processing from a central region to PoPs near your users, cutting both network distance and the blast radius of regional failures. For latency-sensitive logic like media mixing, turn detection, or game state arbitration, every kilometer of separation is roughly five microseconds of one-way fiber delay, and real-world routing adds far more.
Minimize connection setup cost. TLS handshakes add full round trips before any application data flows. Enable TLS session resumption so returning clients skip the full handshake, and prefer QUIC, which combines transport and cryptographic negotiation into fewer round trips. For frequently reconnecting clients, these savings compound.
Monitor latency continuously. Track round-trip time, jitter, and packet loss as first-class metrics with synthetic probes running from the regions your users occupy. Latency problems are invisible until they are measured, and a baseline lets you distinguish a network regression from a code regression. Tools and dashboards that show per-region RTT distributions, not just averages, are worth the setup effort.
Real-World Use Cases
Different applications stress a low latency network in different ways, and the requirements vary by orders of magnitude.
Interactive Gaming and Live Streaming
Competitive gaming is the most latency-visible use case in consumer software. Players perceive input lag above roughly 50 milliseconds, and professional esports demands less. A low latency network improves this on two fronts: shorter physical paths reduce baseline RTT, and intelligent steering prevents the jitter spikes that cause rubber-banding. Live streaming adds a second challenge, because traditional HLS delivery buffers 10 to 30 seconds of video for stability. Interactive live streaming collapses that to sub-second delay, which is what VideoSDK's interactive live streaming mode is built for, letting viewers react, vote, and join the stage in real time instead of watching the past.
Industrial IoT and Tactile Internet
At the extreme end of the requirements spectrum sit industrial control loops and the tactile internet, the vision of remote touch and manipulation. A human sense of touch tolerates around one millisecond of end-to-end delay, and industrial motion control needs similarly tight windows with guaranteed bounds, not averages. This is precisely where TSN and DetNet earn their complexity: scheduled queuing and reserved paths mean a critical control frame is never waiting behind best-effort traffic. 5G integration extends these guarantees wirelessly, connecting mobile robots and automated guided vehicles to deterministic wired backbones.
Real-Time Collaboration and Conversational AI
Between gaming and industrial control sits the everyday case: video calls, voice rooms, and increasingly, conversations with AI voice agents. Human conversation tolerates roughly 150 milliseconds of one-way delay before turn-taking degrades, so every millisecond of network latency directly affects how natural an interaction feels. Conversational AI compounds the challenge, because the user's speech must traverse speech-to-text, an LLM, and text-to-speech before a reply begins, leaving a small budget for the network. Platforms like Agora's SDRTN and VideoSDK's real-time infrastructure exist for exactly this workload, and VideoSDK's AI voice agent support runs these pipelines close to users so the network consumes as little of the latency budget as possible.
Measuring and Visualizing Latency
You cannot optimize what you cannot see. Latency measurement starts with the basics: ping gives raw round-trip time, traceroute reveals per-hop delay and shows exactly where a path degrades, and synthetic probes run continuous measurements from vantage points near your users to catch regressions before they generate support tickets. For real-time media, the metrics that matter are RTT distribution (not just the mean), jitter, and packet loss, because codecs and jitter buffers respond to each differently.
The mental model that ties these together is the packet's journey. A packet leaving a client device first crosses the access network, which on Wi-Fi alone can contribute more jitter than the entire rest of the path. It then reaches an edge POP, where it is classified, possibly decrypted, and steered onto a backbone route. The core backbone contributes propagation delay proportional to distance, and finally the packet arrives at its destination, where processing and queuing add the last increments.
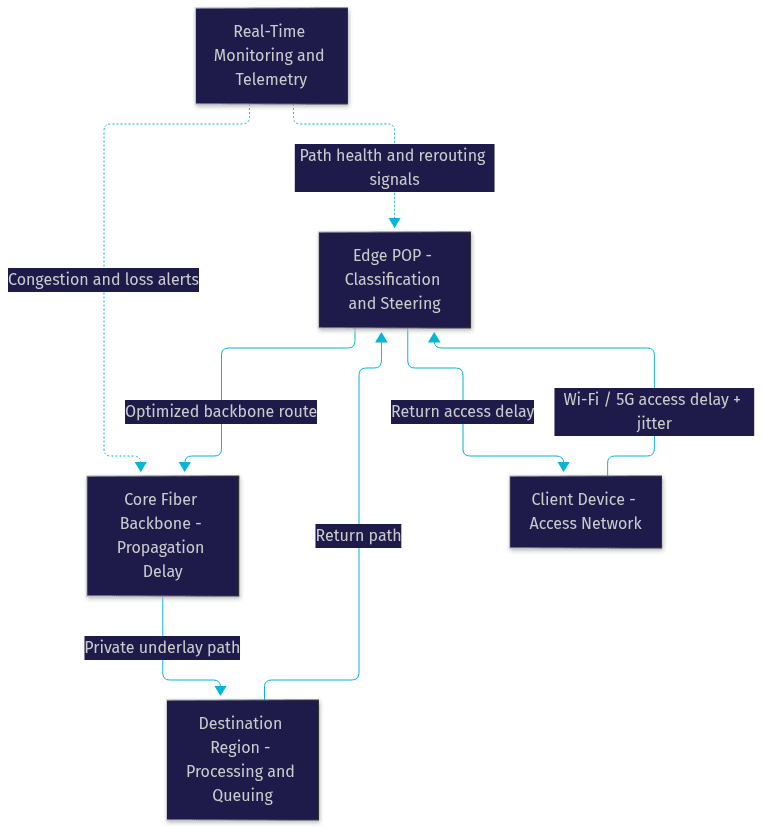
Each arrow in this flow is a latency contributor you can measure and attack separately. When diagnosing a slow session, walk this path in order: access network first, edge POP second, backbone third. In practice, the access network and the last queue before the client account for a surprising share of total delay, which is why AQM and edge placement matter as much as fiber routes.
Future Trends Shaping Low Latency Networks
Three trends are reshaping what developers can expect from network infrastructure through the rest of the decade.
First, 5G and emerging 6G research are converging with edge computing. 5G's low-latency air interface and network slicing only pay off when compute sits near the radio, so operators are deploying edge data centers inside metro areas, promising single-digit millisecond round trips from device to edge for mobile users. As these deployments mature, mobile real-time applications get a latency profile closer to fiber than to legacy cellular.
Second, satellite constellations are changing the geography of low latency. Early low-earth-orbit systems already deliver round-trip times in the tens of milliseconds, far below geostationary satellite links, and bring real-time-quality connectivity to regions that terrestrial fiber ignores. For globally distributed user bases, satellite backhaul becomes a genuine low latency option rather than a last resort.
Third, AI-driven network orchestration is moving from path selection to full-stack autonomy. Beyond the machine-learning routing inside today's SDRTNs, operators are experimenting with reinforcement-learning agents that manage queue thresholds, predict demand surges, and pre-provision capacity before congestion appears. The trajectory is clear: networks that once reacted to problems will increasingly prevent them, and the latency floor will keep dropping for applications built on top.
Definitions Glossary
Low latency network: A network engineered to minimize round-trip delay, jitter, and packet loss for interactive workloads, typically targeting sub-100 millisecond performance and often much lower.
SDRTN (Software-Defined Real-Time Network): A global network architecture that uses real-time telemetry and machine-learning routing to steer media streams along the best available path, exemplified commercially by Agora's SDRTN.
TSN (Time-Sensitive Networking): A set of IEEE 802.1 standards that add time synchronization and scheduled queuing to Ethernet, guaranteeing bounded latency for critical traffic in industrial and 5G fronthaul settings.
L4S (Low Latency, Low Loss, Scalable Throughput): An IETF architecture that uses accurate early congestion signals so flows like those using Prague or BBR congestion control avoid bufferbloat and keep queuing delay minimal.
Bufferbloat: The latency spike caused by large router buffers filling with bulk traffic, which active queue management algorithms such as CoDel and PIE are designed to prevent.
Interactive Live Streaming (ILS): A streaming mode with sub-second delay in which the audience can interact, vote, and be promoted to active participants, as supported by VideoSDK's live streaming capabilities.
Key Takeaways
- A low latency network is purpose-built infrastructure that minimizes round-trip time, jitter, and packet loss, and it cannot be substituted by a traditional throughput-optimized CDN.
- The core enabling technologies are software-defined real-time routing (SDRTN), deterministic standards (TSN and DetNet), and modern congestion control (L4S, Prague, BBR, DCTCP) that eliminate bufferbloat.
- The architectural pillars are a global fiber backbone with dense edge presence, intelligent traffic steering driven by real-time telemetry, and active queue management with priority queuing.
- Design decisions with the biggest latency impact are transport choice, DiffServ marking, edge compute placement, TLS session resumption with QUIC, and continuous RTT, jitter, and loss monitoring.
- VideoSDK's real-time infrastructure applies these same principles for developers, delivering sub-second interactive live streaming and low-latency video calling across its global network without you building the underlay yourself.
Conclusion
A low latency network is not a single product but a discipline: shorten the physical path, steer around congestion, keep queues shallow, and measure relentlessly. Whether you are building a multiplayer game, an industrial control system, or a video calling app, the network sets the floor your user experience stands on, and no amount of application-layer cleverness lowers it. Start with the checklist above: pick the right transport, mark your traffic for priority, deploy close to your users, and monitor RTT, jitter, and loss continuously. If you would rather not build and operate the underlay yourself, VideoSDK's video calling SDK and real-time infrastructure handle the hard parts, from global routing to adaptive streaming, so you can focus on your application. You can explore the code samples or sign up free at app.videosdk.live to see the latency for yourself. What are you building that needs a low latency network? Drop a comment, I'd love to hear what kind of real-time use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ