


A load balancer for WebSocket traffic distributes real-time connections across multiple servers, maintains sticky sessions, performs health checks, and ensures low latency and high availability. Use HAProxy, Nginx, or Envoy with TCP mode and session persistence, then monitor health and scale horizontally.
Real-time features are now table stakes. Chat applications, multiplayer games, live trading dashboards, and collaborative editors all depend on WebSocket connections that stay open for hours, pushing data the instant it changes. Unlike a normal web request, a WebSocket connection is a long-lived, bidirectional TCP stream, and that single difference changes everything about how you scale it.
When your WebSocket traffic outgrows one server, a naive load balancing setup fails in painful ways: latency spikes during peak hours, authenticated connections drop mid-session, and a single server restart becomes a customer-visible outage. The fix is a load balancer configured specifically for WebSocket semantics, with session persistence, proper health checks, and a failover strategy.
This guide walks through the full picture: what a load balancer websocket setup actually does, how to choose between HAProxy, Nginx, Envoy, and cloud-native options, how to configure sticky sessions, and how to scale from a thousand connections to a hundred thousand without losing sleep.
What Is a Load Balancer WebSocket?
A load balancer websocket setup is a distribution layer that routes long-lived, bidirectional WebSocket connections across a pool of backend servers. A WebSocket connection is defined as a persistent TCP stream that begins with an HTTP handshake and then upgrades into a raw, full-duplex channel. Because the connection never closes under normal operation, the balancer must treat it as a continuous stream rather than a sequence of independent requests.
This is where WebSocket load balancing differs fundamentally from HTTP load balancing. Standard HTTP balancing is stateless: each request is independent, so any server can handle any request. WebSocket balancing is stateful: once a client's connection lands on a specific server, all subsequent frames on that connection must flow through the same server. If the balancer redirects mid-stream, the connection breaks and the client must reconnect, re-authenticate, and re-establish state.
A WebSocket load balancer therefore carries three core responsibilities. First, distribution: spreading new connections evenly so no single server saturates. Second, stickiness: ensuring an established connection stays pinned to its origin server for its entire lifetime. Third, health checking: detecting dead or degraded backends and failing over without dropping every client at once.
Core Components
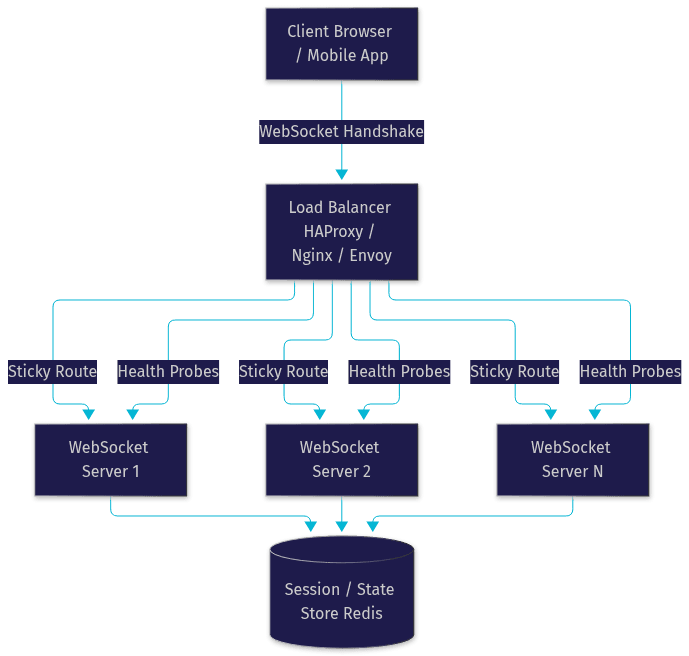
Every production WebSocket load balancing stack has four pieces. The front-end balancer terminates client connections, handles TLS, and routes traffic. The backend WebSocket servers hold the actual live connections and application state. The health-check service continuously probes backends and reports their status to the balancer. Finally, the session store, typically Redis, shares authentication tokens and connection state across servers so that a reconnecting client can resume on any healthy node.
Choosing a Load Balancer for WebSocket Traffic
Choosing the right load balancer for WebSocket traffic depends on five criteria: protocol support, TCP versus HTTP mode, sticky-session capabilities, TLS termination behavior, and raw throughput performance. Not every balancer handles these equally, and the wrong choice surfaces as mysterious disconnects or failed handshakes in production.
HAProxy is the most widely deployed option for raw TCP WebSocket load balancing. It operates in TCP mode, where it treats the connection as an opaque byte stream, adds minimal overhead, and offers fine-grained control over stickiness and health checks. Nginx is the strongest choice when you want the same layer to also serve static assets and reverse-proxy HTTP traffic, since it handles WebSocket upgrade headers cleanly. Envoy excels in modern service-mesh environments, offering observability and dynamic configuration that suit microservice architectures. Cloud-native options like AWS Application Load Balancer and Google Cloud Load Balancing remove operational burden but give you less control over failover timing and session behavior.
| Load Balancer | Mode | Stickiness | Best For |
| | --- | --- | --- | --- |
| HAProxy | TCP or HTTP | Cookie and table-based | High-throughput raw TCP WebSocket routing |
| Nginx | HTTP with upgrade | Cookie or IP hash | Mixed HTTP plus WebSocket serving at one edge |
| Envoy | TCP or HTTP | Consistent hashing | Microservices and service-mesh deployments |
| AWS ALB | HTTP | Sticky target groups | Teams fully invested in AWS managed services |
| GCP Cloud LB | HTTP or proxy | Session affinity | GCP-native deployments wanting zero ops |
For most teams running dedicated real-time infrastructure, HAProxy in TCP mode is the pragmatic default: it is battle-tested, transparent about failures, and fast enough that the balancer itself almost never becomes the bottleneck.
HAProxy Deep Dive
HAProxy earns its popularity for WebSocket load balancing through three traits. It performs health checks at both the TCP connect level and the application level, so a backend that accepts sockets but is functionally broken gets pulled from rotation. It supports multiple stickiness mechanisms, including inserted cookies and sticky tables, letting you match affinity strategy to your authentication model. And its statistics page exposes per-backend connection counts and error rates in real time, which is exactly the visibility you need when diagnosing a connection storm.
Configuring Sticky Sessions
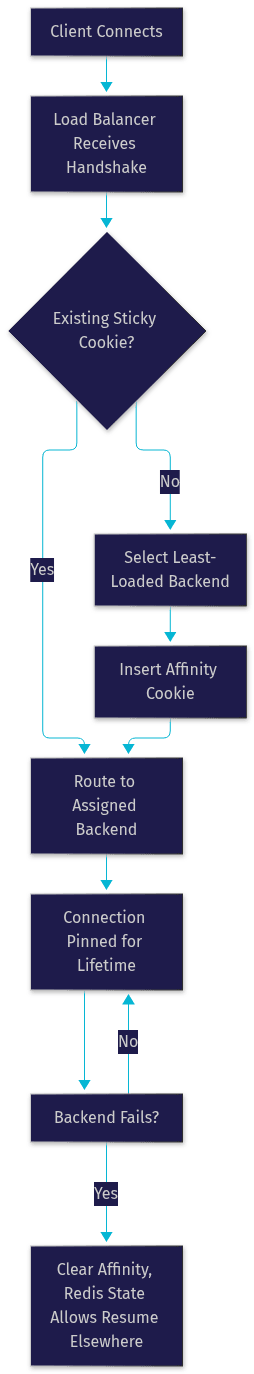
Sticky sessions are the mechanism that keeps a WebSocket connection attached to the backend server that accepted it. Without stickiness, a balancer that re-evaluates routing on every frame would scatter a single logical conversation across multiple servers, none of which holds the complete connection state. For authenticated WebSocket streams, session affinity is not optional; it is the difference between a working app and a flood of reconnection loops.
Three techniques dominate. Cookie-based affinity has the balancer insert a cookie identifying the chosen backend, so any reconnect from the same client returns to the same server. Source-IP hashing derives the backend choice from the client's IP address, which works without cookies but breaks when large populations share a single egress IP, such as corporate networks or mobile carriers. Redis-backed session state decouples affinity from routing entirely: any server can resume a session by reading shared state from Redis, which trades a small latency cost for full flexibility.
The trade-offs matter. Cookie affinity is simple but couples your failover to cookie lifetime. IP hashing is stateless but coarse-grained. Shared session state is the most robust but adds infrastructure. Avoid stickiness altogether only when your application is fully stateless at the connection level, meaning every frame can be processed by any server without prior context, which is rare in practice.
Health Checks and Failover
Health checks for WebSocket backends come in two levels, and you need both. A TCP health check simply verifies that the backend accepts connections on its port. It catches crashed processes and network partitions but misses subtler failures: a server that accepts sockets while its event loop is jammed will pass a TCP check while serving nothing. An application-level check sends a WebSocket ping and expects a pong within a timeout, verifying that the server can actually process frames. The WebSocket protocol's built-in ping and pong frames make this straightforward to implement.
Graceful shutdown is the other half of reliable failover. When a backend needs to restart or deploy, it should announce its departure so the balancer stops routing new connections to it, then close existing connections gently, giving clients time to reconnect to a healthy node. Without graceful shutdown, every deploy becomes a simultaneous disconnect event for every client on that server.
Automatic failover strategy follows a simple rule: detect fast, drain slowly, reconnect cheaply. Set health-check intervals tight enough to catch a dead backend within seconds, use connection draining windows of tens of seconds during deploys, and make client reconnection logic exponential-backoff based so a recovered backend is not instantly crushed by a thundering herd of returning connections.
Scaling Patterns
Horizontal scaling is the primary pattern for WebSocket growth: add more WebSocket server instances behind the balancer and let distribution even out the load. Because each connection is pinned to one server, capacity scales nearly linearly with node count, limited mainly by the balancer's own connection-tracking overhead and your total bandwidth.
Connection pooling at the balancer level helps when clients open many short-lived connections, such as browser tabs that reconnect frequently. Reusing established backend connections reduces handshake cost and TCP churn, though for long-lived WebSocket streams the benefit is smaller than in request-response systems.
The pattern that unlocks true scale is a message broker for state sharing. When every WebSocket server subscribes to a Redis Pub/Sub channel (or a similar broker like NATS), a message published by any server reaches clients connected to every server. This means user A on server one can send a message to user B on server five without either server knowing where the other user lives. The broker becomes the nervous system; the servers become stateless connection endpoints.
Consider a concrete scenario: scaling from 1,000 to 100,000 concurrent connections. At 1,000 connections, a single server with a Redis-backed session store handles everything comfortably. At 10,000, add two more servers and a dedicated load balancer with cookie affinity. At 100,000, you are running perhaps fifteen to twenty WebSocket servers, each holding five to eight thousand connections, all subscribed to the same broker channels, with the balancer distributing new handshakes by least-connection count. The architecture that got you to 1,000 does not survive to 100,000, but the transition is incremental at each stage.
Horizontal Scaling Checklist
- Verify the balancer distributes by least-connections, not round-robin, so hot servers cool down.
- Confirm session state lives in Redis or the broker, not in server memory alone.
- Test that a server removal drains connections without a mass disconnect event.
- Check that the balancer's own connection limit exceeds your peak concurrent target with headroom.
- Load-test at 120 percent of expected peak before adding traffic.
- Validate that client reconnection logic uses jittered exponential backoff.
Monitoring, Metrics, and Alerting
You cannot manage what you cannot measure, and WebSocket infrastructure fails quietly before it fails loudly. Four metric families matter most. Active connection counts per backend reveal uneven distribution and approaching capacity. Frame latency, measured from publish to delivery, exposes degradation before users complain. Error rates, including failed handshakes and abnormal closures, point at authentication or TLS problems. TCP retransmit counts signal network-level trouble between balancer and backends.
The standard tooling stack is Prometheus for collection, Grafana for dashboards, and the HAProxy statistics page for immediate operational visibility. Prometheus scrapes balancer and backend metrics on a fixed interval; Grafana turns them into panels showing connection trends, backend health over time, and latency percentiles. The HAProxy stats page gives you a live, per-backend view that is invaluable during incidents.
Set alert thresholds that trigger proactive scaling rather than reactive firefighting. Alert when any backend exceeds 80 percent of its connection capacity, when handshake failure rate exceeds one percent over five minutes, or when frame latency percentiles double their baseline. Each alert should map to a runbook action: add a backend, investigate a certificate, or check broker saturation.
Common Pitfalls and Troubleshooting
The most common WebSocket load balancing failure is unexpected disconnects after a balancer restart. The cause is usually in-memory session affinity: the balancer's sticky table lived only in its own memory, so a restart wiped every mapping and every live connection. The fix is cookie-based affinity or an external session store, so routing decisions survive balancer restarts.
TLS termination issues cause handshake failures that masquerade as application bugs. When the balancer terminates TLS and forwards plain TCP to backends, the backend must expect unencrypted traffic; a mismatch produces handshakes that open and immediately close. Certificate expiry on the balancer produces a different signature: all new connections fail while existing ones keep working, because established streams do not re-verify the certificate. Automate certificate renewal and alert on expiry.
Sticky-session misconfiguration leads to authentication errors that look random. A client reconnects, lands on a different server, and its authentication token is not recognized because session state was local to the original server. The diagnosis path is consistent: correlate the client's reconnect timestamps with balancer logs showing which backend handled each connection, then confirm whether session state is actually shared.
For general diagnosis, start with the balancer's statistics page to spot unhealthy backends, then move to per-backend connection counts to spot distribution skew, then to application logs filtered by abnormal closure codes. The WebSocket close code tells you who initiated the closure and often why, which narrows the search dramatically.
Best-Practice Checklist
- Run the balancer in TCP mode for dedicated WebSocket traffic.
- Use cookie-based or Redis-backed affinity, never memory-only stickiness.
- Enable both TCP and application-level (ping/pong) health checks.
- Implement graceful shutdown with connection draining on every backend.
- Share session and presence state through Redis or a message broker.
- Terminate TLS at the balancer with automated certificate renewal.
- Distribute by least-connections rather than round-robin.
- Monitor active connections, latency percentiles, and handshake failures in Prometheus and Grafana.
- Load-test at 120 percent of peak before each major scaling step.
Definitions Glossary
Sticky Session: A routing policy that keeps a client's connection attached to the same backend server for the connection's lifetime, preventing mid-stream breaks in stateful WebSocket traffic.
TCP Mode: A load balancer operating mode that treats traffic as an opaque byte stream, ideal for WebSocket connections after the initial HTTP handshake completes.
Health Check: A periodic probe, at the TCP or application level, that determines whether a backend server is fit to receive new connections.
Graceful Shutdown: The process of removing a backend from rotation, draining its existing connections gently, and letting clients reconnect to healthy nodes without a mass disconnect.
Redis Pub/Sub: A publish-subscribe messaging mechanism that lets multiple WebSocket servers exchange events, enabling horizontal scaling without servers knowing each client's location.
Connection Draining: A failover window in which a departing backend stops accepting new connections while existing ones complete naturally or are redirected.
Key Takeaways
- WebSocket load balancing is stateful: connections must stay pinned to their origin server, making sticky sessions mandatory for authenticated real-time traffic.
- HAProxy in TCP mode is the pragmatic default for dedicated WebSocket infrastructure, while Nginx and Envoy suit mixed-traffic and microservice environments respectively.
- Health checks need both a TCP layer and an application-level ping/pong layer to catch jammed servers that still accept sockets.
- Horizontal scaling to 100,000 connections requires a message broker like Redis Pub/Sub so any server can reach any client.
- Monitoring active connections, latency percentiles, and handshake failure rates in Prometheus and Grafana turns silent degradation into actionable alerts.
Conclusion
A properly configured load balancer websocket setup is the foundation of reliable real-time communication: it distributes long-lived connections, keeps them sticky, checks backend health continuously, and fails over without dropping your users. Get TCP mode, session affinity, graceful shutdown, and shared state right, and scaling from thousands to hundreds of thousands of connections becomes an operational routine rather than a crisis.
If you are building real-time features and want the media layer handled for you, explore VideoSDK's video and audio calling SDKs, which manage rooms, participants, and streams so you can focus on your application. Start with the VideoSDK quickstart or grab a free API key at app.videosdk.live/login.
What are you building with real-time connections? Drop a comment, I'd love to hear what kind of WebSocket scaling challenge you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ