


A text to speech AI voice is a synthetic voice generated by a neural network that converts written text into natural-sounding spoken audio. Modern neural text-to-speech systems produce speech nearly indistinguishable from human recordings, support 100+ languages, and can be integrated into apps through a speech synthesis API. VideoSDK extends this capability further by letting developers pipe TTS output directly into real-time audio and video rooms for live AI voice agents.
AI-generated speech has quietly become one of the most widely deployed interfaces in software. Every navigation app, virtual assistant, e-learning platform, and podcast tool you use today leans on synthetic speech to some degree. What changed in the last few years is quality: neural text to speech AI voice systems now cross the threshold where most listeners cannot tell the difference between synthetic and recorded human speech.
For developers and content teams, this shift matters commercially. Producing an hour of professional voiceover used to require a studio session, a voice actor, and a turnaround measured in days. A speech synthesis API can now generate the same output in seconds, at a fraction of the cost, in dozens of languages from a single text source.
This guide covers how the technology works, how to evaluate providers, how to implement a text to speech AI voice workflow end to end, and which advanced features are worth adopting in 2026. Whether you are building an AI voice agent, narrating an e-learning course, or adding accessibility audio to your product, you will find a practical path forward here.
What Is Text to Speech AI Voice?
Text to speech AI voice is defined as computer-generated speech produced by machine learning models that convert written text into audible, human-like voice output. Unlike older rule-based systems that stitched together recorded audio fragments, modern AI voice generation uses deep neural networks that learn the patterns of human speech directly from large datasets of recorded audio.
Traditional TTS, known as concatenative synthesis, worked by joining pre-recorded word and phoneme snippets. It sounded robotic because prosody, the rhythm and melody of speech, could not be smoothly assembled from fragments. Neural text-to-speech replaced this with end-to-end models that generate speech waveforms directly, capturing natural intonation, breathing, and emphasis.
A neural TTS pipeline has three core components. First, text preprocessing normalizes the input: expanding abbreviations, converting numbers to words, and splitting sentences into phonetic units. Second, an acoustic model maps those phonetic units to acoustic features such as pitch, duration, and energy, effectively deciding how the sentence should sound. Third, a vocoder converts those acoustic features into the actual audio waveform you hear. Providers like ElevenLabs, OpenAI TTS, Google Cloud TTS, and AWS Polly each implement this pipeline with proprietary models, and the differences between them show up mainly in naturalness, latency, and language coverage.
Key Benefits of Using Text to Speech AI Voice
The value of a text to speech AI voice goes far beyond novelty. Four benefits drive most adoption decisions.
Speed and Cost Efficiency
Professional voiceover production typically costs between $100 and $500 per finished minute once studio time, talent, and editing are included. A cloud TTS service generates the same audio for a few cents per minute, with no scheduling, no retakes, and instant revision cycles. If a script changes, regenerating the audio takes seconds rather than another studio booking. For content teams producing weekly podcasts, course libraries, or product videos, this compounds into a dramatic reduction in both production time and budget.
Multilingual Reach
Leading AI voice generator platforms support 100 or more languages and dialects, often with multiple voice options per language. A single English script can be localized into Spanish, Hindi, German, and Japanese without hiring four voice actors. This unlocks market expansion that was previously reserved for well-funded publishers. For global products, multilingual TTS also enables dynamic content, such as reading localized news or weather updates aloud, that would be impossible to pre-record at scale.
Consistency and Brand Voice
Voice cloning lets you create a custom synthetic voice from a short sample of recorded speech, then use that voice indefinitely. This means your brand sounds identical across every video, course, and support call, forever. It also solves the continuity problem in human production: when a voice actor leaves or a series spans years, a cloned voice keeps narration consistent. Many organizations now treat their synthetic brand voice as a digital asset with documented usage guidelines.
Accessibility and Inclusion
AI voice makes written content audible for visually impaired users, people with reading disabilities such as dyslexia, and anyone consuming content hands-free. Beyond the ethical case, accessibility audio increasingly carries legal weight. Regulations such as the Americans with Disabilities Act and the European Accessibility Act push publishers and e-learning providers toward audio equivalents of text content. Synthetic narration is the only economically viable way to meet those requirements across large content libraries.
Choosing the Right AI Voice Provider
Selecting a speech synthesis API is a decision with long-term consequences, because voice consistency and integration depth lock you in once content is produced. Evaluate providers across four dimensions.
Voice Quality and Naturalness
Quality is measurable. The industry-standard metric is the Mean Opinion Score (MOS), where human listeners rate speech samples on a scale of 1 to 5. Top neural TTS models now score above 4.5, approaching the 4.7 to 4.9 range typical of genuine human recordings. Independent evaluations, such as those published on Artificial Analysis, compare leading models on naturalness and word accuracy. Always audition a provider with your own text, because quality varies by language, voice, and content type.
Voice Library Size and Customization
A large voice library matters when you need distinct characters, multiple languages, or regional accents. Look for 1000+ voices where available, but weight customization more heavily than raw count. SSML support, the Speech Synthesis Markup Language that lets you control pauses, emphasis, and pronunciation, is essential for production work. Emotion and tone controls, such as adjusting speaking style between cheerful, serious, or empathetic, separate premium providers from basic ones.
Pricing Models and Licensing
Most cloud TTS services offer a free tier for evaluation, then charge per character or per audio minute. Compare the effective cost per finished minute at your real volume, not the headline rate. Critically, verify commercial usage rights: some voices are licensed only for personal or internal use, and cloned voices may require consent agreements from the original speaker. Enterprise plans often add indemnification and usage analytics.
Integration Options
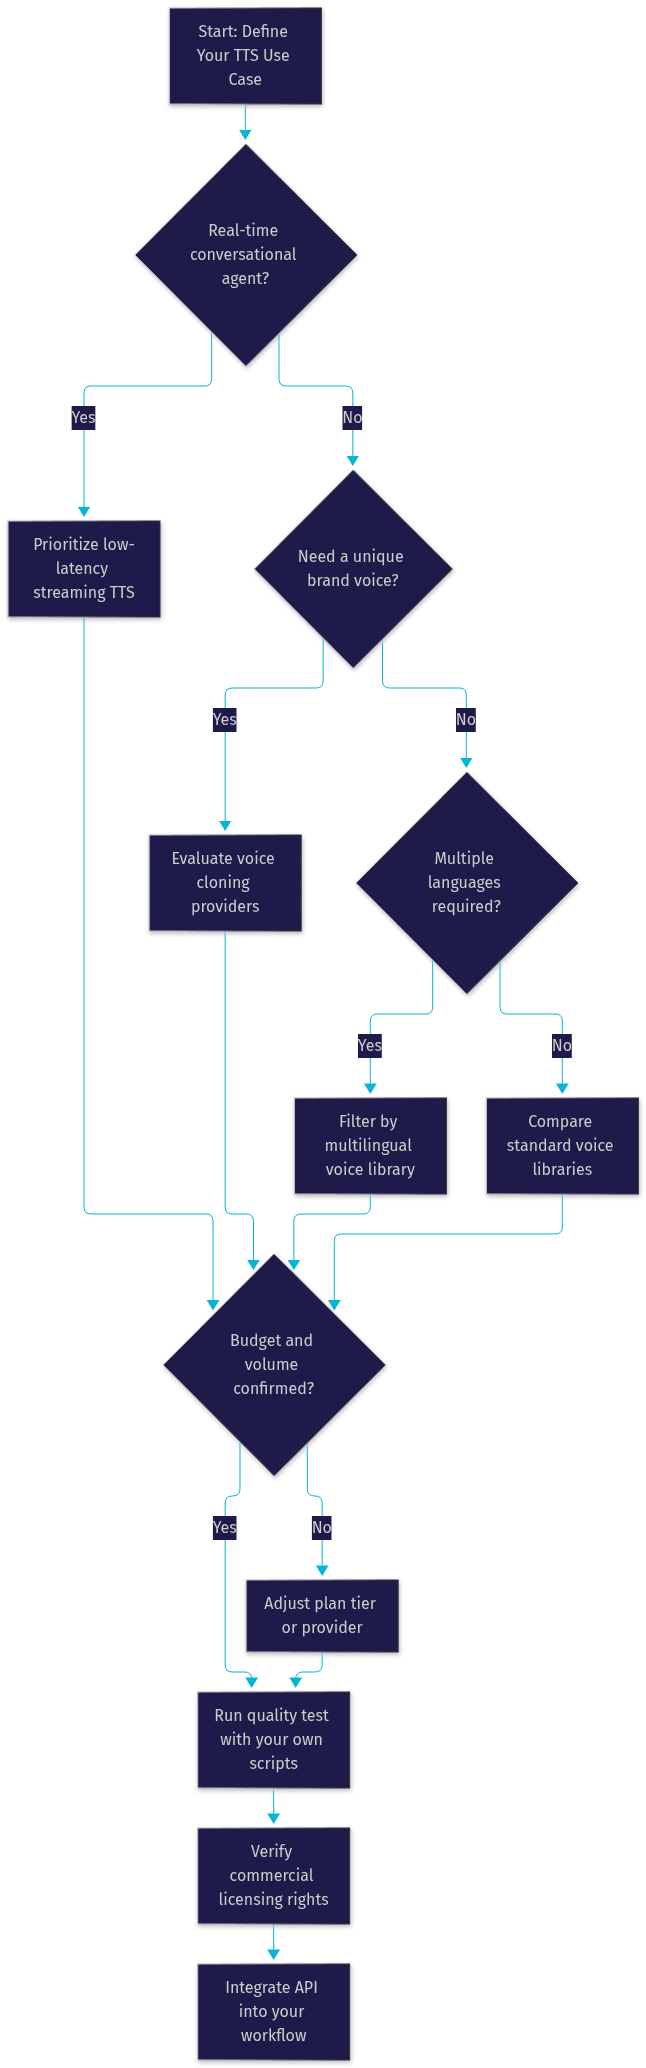
A provider should fit your stack, not force a rewrite. Look for REST APIs, official SDKs for your platforms, streaming support for low-latency use cases, and compatibility across web, mobile, and desktop. If you are building real-time voice agents, latency matters most: the time from text input to first audio byte should be well under a second for conversational experiences.
The decision path below summarizes how to narrow your choice:
How to Implement Text to Speech AI Voice in Your Workflow
Implementation is where most teams either succeed smoothly or stall. The workflow below applies whether you are narrating a podcast or powering a live AI voice agent.
Step-by-Step Setup
First, prepare your text. Clean the source material by expanding abbreviations, spelling out numbers and symbols, and splitting long passages into sentence-level chunks. Text normalization is the step most teams skip, and it is the most common cause of awkward output.
Second, select your voice. Audition several candidates against a representative sample of your actual content, not the provider's demo text. Choose the voice that matches your brand tone and target audience.
Third, apply SSML tags to shape delivery. Insert pauses at natural thought breaks, mark words that need emphasis, and add phonetic pronunciations for domain-specific terms, product names, and acronyms. A pronunciation dictionary maintained alongside your scripts pays off permanently.
Fourth, generate the audio through the provider's speech synthesis API, requesting the output format that matches your downstream pipeline, typically a compressed format for streaming delivery or a lossless format for post-production.
Fifth, post-process. Normalize loudness across episodes or modules, trim leading and trailing silence, and spot-check pronunciation of proper nouns. Batch processing keeps this efficient at scale.
For teams building interactive or agent-driven experiences, the architecture looks like this:
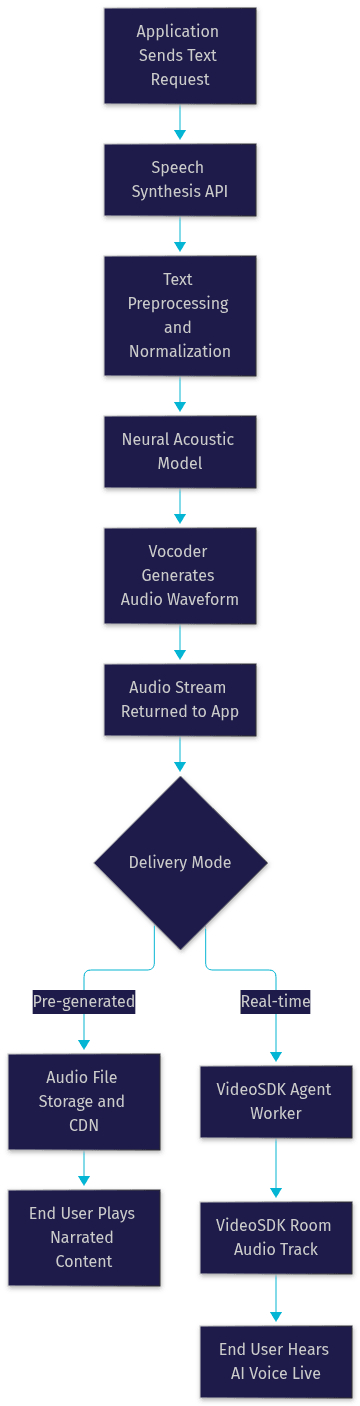
The real-time branch is where platforms like VideoSDK's AI Agents come in: the Agent Worker manages the session, pipes TTS output into the room's audio track, and participants hear the AI voice with sub-second latency, whether they join from a browser, a mobile app, or a phone line through SIP telephony integration.
Best Practices for Natural-Sounding Output
Punctuation is your prosody control. Commas create short pauses, periods create full stops, and ellipses create hesitation. Write scripts the way you would say them aloud, not the way you would write an essay.
Use explicit pause markers around lists, after rhetorical questions, and between contrasting clauses. Keep sentences short; long sentences force the model to compress breath points and sound rushed. Maintain a pronunciation dictionary for every recurring term, and regenerate audio whenever you edit a script rather than patching audio by hand. Finally, listen to output at normal playback speed on the target device, because flaws invisible in a quick desktop check become obvious on earbuds.
Real-World Use Cases
Podcast Production
Solo podcasters use AI voiceover to produce interview-style shows, narrate show notes, or generate full episodes from written scripts. The workflow is simple: write the script, apply SSML for pacing, generate the audio, and publish. Some shows blend a cloned host voice for narration with human guests, cutting production time from days to hours.
E-Learning Narration
Course platforms face a scale problem: hundreds of modules, frequent content updates, and learners in many languages. Neural TTS lets them narrate every module instantly, regenerate only the changed lessons after an update, and localize the entire catalog without re-recording. Consistent narration across a course also improves learner comprehension, because the brain adapts to a single voice's rhythm.
Video Marketing
Product and marketing videos use AI voice for explainer narration, localized ad variants, and rapid A/B testing of scripts. When you can regenerate narration in minutes, testing three value propositions becomes practical, something no human-talent workflow can match on turnaround.
Accessibility Transcripts
Publishers convert articles, documentation, and PDFs into audio versions for visually impaired readers and compliance requirements. Because generation is automated, every new article ships with an audio version by default rather than as an afterthought.
Advanced Features to Leverage
Voice Cloning and Custom Voice Creation
Modern cloning needs only a few minutes of clean reference audio to produce a convincing custom voice. Use cases include brand voices, multilingual versions of a single spokesperson, and continuity for serialized content. Treat cloning ethically: clone only voices you own or have documented consent for, and check your provider's consent requirements before generating anything public-facing.
Real-Time Streaming TTS
Streaming synthesis returns audio as it is generated rather than waiting for the full clip, cutting perceived latency from seconds to a few hundred milliseconds. This is the enabling technology for conversational AI, live agents, and interactive voice response systems. If your product involves dialogue, insist on streaming output from your provider.
Emotion and Tone Control
Premium models accept style parameters that shift delivery between neutral, excited, empathetic, or serious registers. Support lines benefit from empathetic tone; marketing benefits from energetic delivery; compliance content needs measured, neutral speech. Combined with SSML, tone control gives you director-level influence over synthetic performances.
Multi-Speaker Dialogues
Some APIs generate conversations between multiple distinct voices in a single call, assigning lines to different synthetic speakers. This powers audio dramas, training simulations, and demo dialogues without coordinating multiple recordings. For live multi-agent scenarios, VideoSDK's agent framework supports multi-agent switching, where different AI voices handle different conversation stages inside the same room.
Measuring Success and Optimizing Performance
Track four indicators. Listener retention: do audiences stay with synthetic narration as long as human narration? A/B test both where possible. Conversion rates: for marketing audio, compare AI-voiced variants against each other and against human controls. SEO impact: audio content increases time on page and enables indexing of spoken content, so monitor engagement metrics on pages where you add narration. Cost per finished minute: calculate your all-in cost including API spend, editing time, and storage, and re-evaluate quarterly as provider pricing shifts.
Future Trends in Text to Speech AI Voice
Three trends will shape the next two years. Multimodal AI models are merging speech generation with vision and reasoning, so a single agent will see a slide, discuss it aloud, and respond to a listener's tone. Deepfake detection is becoming a compliance requirement: expect watermarking and disclosure standards for synthetic voices to tighten, especially in news and political content. Edge-device TTS is moving high-quality synthesis onto phones and cars, enabling offline narration and privacy-preserving voice interfaces without a network round trip. Providers that expose these capabilities through clean APIs will define the next generation of voice-first products.
Definitions Glossary
Neural Text-to-Speech: Speech synthesis generated by deep neural networks that learn prosody and intonation from recorded human speech, producing far more natural output than older fragment-based systems.
Speech Synthesis API: A cloud service interface that accepts text and returns generated audio, letting developers embed AI voice into applications without building synthesis models themselves.
Voice Cloning: Creating a custom synthetic voice from a short sample of a person's recorded speech, enabling consistent brand or character voices across unlimited content.
SSML (Speech Synthesis Markup Language): A markup standard for controlling how synthesized speech is delivered, including pauses, emphasis, pronunciation, and speaking rate.
Vocoder: The final stage of a TTS pipeline that converts acoustic features produced by the neural model into an audible audio waveform.
Agent Worker: In VideoSDK's AI agent architecture, the Python process that manages an agent session, running the speech-to-text, LLM, and text-to-speech pipeline and delivering the AI voice into a real-time room.
Key Takeaways
- Neural text to speech AI voice systems now score near-human on naturalness benchmarks, making synthetic narration viable for production-quality podcasts, courses, and marketing videos.
- Provider selection should weigh quality metrics like MOS scores, voice library depth, SSML customization, licensing terms, and integration options, in that order of consequence.
- A disciplined workflow of text normalization, voice auditioning, SSML markup, and post-processing is what separates natural-sounding output from obviously synthetic audio.
- Real-time streaming TTS is the enabling technology for conversational AI, and platforms like VideoSDK let developers deliver AI voice into live audio and video rooms with sub-second latency.
- Measure success with listener retention, conversion rates, SEO engagement, and cost per finished minute, and re-evaluate your provider quarterly.
Conclusion
Text to speech AI voice technology has crossed from impressive demo to dependable production tool. It cuts narration costs by orders of magnitude, scales across 100+ languages from a single script, keeps your brand voice consistent indefinitely, and makes accessibility audio practical at any content volume. The teams that win with it are the ones that treat voice quality, licensing, and workflow discipline seriously rather than accepting default settings. Start by auditioning two or three providers with your own scripts, then experiment with a small project before scaling. If you are building interactive voice experiences, explore VideoSDK's AI Agents documentation to see how to deliver a text to speech AI voice into live rooms, or grab the free tier at app.videosdk.live and start building. What are you building with AI voice? Drop a comment, I'd love to hear what kind of text to speech use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ