


AI voice text to speech (TTS) is the process of using deep learning models to convert written text into natural-sounding human speech. Unlike traditional concatenative TTS, neural TTS models analyze linguistic context to produce expressive, human-like audio. Developers can integrate these capabilities via REST APIs or SDKs, and platforms like VideoSDK provide unified AI Voice Agent pipelines to streamline real-time speech synthesis in production applications.
The surge of AI-driven voice generation has fundamentally changed how developers build interactive applications. From conversational agents to accessibility tools and dynamic content narration, the ability to generate human-like speech on demand is no longer a novelty but a core infrastructure requirement. However, navigating the landscape of neural TTS models, latency constraints, and provider pricing can be daunting. Developers need a clear roadmap to choose the right models, integrate them efficiently, and manage the trade-offs between quality and speed. This guide breaks down everything you need to know about AI voice text to speech, from the underlying neural network architecture to comparing leading providers and integrating them into your stack using tools like the VideoSDK AI Agent SDK.
Understanding AI Voice Text to Speech
AI voice text to speech is defined as the technology that converts written text into spoken audio using artificial intelligence and deep learning techniques. It works by processing input text through neural networks that predict the appropriate phonemes, intonation, and rhythm required for natural speech. Traditional TTS systems relied on concatenative synthesis, stitching together pre-recorded audio fragments, which often sounded robotic and lacked emotional nuance. Modern AI-driven TTS, or neural TTS, generates audio waveforms from scratch based on linguistic context. This shift allows for highly expressive, multilingual speech generation that can be customized through voice cloning. VideoSDK provides access to these advanced TTS capabilities through its AI Voice Agent pipeline, enabling developers to build real-time conversational interfaces without managing the underlying machine learning infrastructure.
How the Technology Works
Neural Networks Behind TTS
Modern neural TTS systems typically use an encoder-decoder architecture. The encoder analyzes the input text and converts it into a sequence of linguistic features. The decoder then uses these features to generate a mel-spectrogram, which is a visual representation of the spectrum of frequencies in the audio as they vary over time. Finally, a vocoder converts the spectrogram into an actual audio waveform. Recent advancements have also introduced diffusion models, which iteratively refine random noise into a clean audio signal based on the text conditioning, offering superior audio quality and naturalness.
Model Types and Their Trade-offs
TTS models generally fall into three families: standard, high-quality, and real-time. Standard models offer a balance of speed and quality suitable for basic notifications. High-quality models prioritize naturalness and expressiveness, making them ideal for audiobooks or premium narration, but they introduce higher latency. Real-time models are optimized for sub-second response times, which is critical for conversational AI where users expect immediate feedback. Choosing the right model family depends entirely on your application's latency budget and user experience goals.
Voice Cloning Basics
Voice cloning allows developers to create a custom TTS voice from a short audio sample of a target speaker. The neural network extracts the unique vocal characteristics, such as timbre, pitch, and accent, from the sample and applies them to the TTS model. This enables applications to generate speech in a specific person's voice without recording thousands of hours of new audio. While powerful, developers must navigate ethical considerations and ensure they have explicit consent to clone a voice.
Key Benefits for Developers
Integrating AI voice TTS offers several practical advantages for developers. Scalability is a major benefit, as cloud-based APIs can handle thousands of concurrent requests without requiring you to provision GPU hardware. Multilingual support allows a single application to serve a global audience by dynamically switching between languages and accents. Rapid prototyping is another key advantage, as developers can use prebuilt voices to test conversational flows before investing in custom voice development. Furthermore, modern TTS APIs provide fine-grained control over speech rate, pitch, and pronunciation, enabling highly tailored user experiences.
Choosing the Right Model
Quality vs. Latency
The most critical decision when selecting a TTS model is the trade-off between audio quality and latency. If you are building an interactive voice assistant, latency is paramount. Users will abandon a conversation if the agent takes more than a second to respond. In this scenario, you should prioritize real-time or streaming models. Conversely, if you are generating audio for a pre-recorded video or an audiobook, you can afford higher latency to achieve maximum naturalness and emotional expressiveness.
Multilingual Support Needs
Language coverage varies significantly across providers. Some platforms excel in English but offer limited support for regional languages. If your application targets a global audience, you need a provider with robust multilingual TTS models that can handle different phonetic rules and accents natively. Verify that the provider supports the specific languages and dialects your users speak before committing to an integration.
Custom Voice Requirements
Deciding between a generic library voice and a custom cloned voice depends on your brand identity. Generic voices are free to use and require no setup, making them perfect for internal tools or generic applications. Custom voices, however, provide a unique brand asset. If your application is a customer-facing product where brand consistency is crucial, investing in voice cloning to create a proprietary voice can significantly enhance user engagement and brand recall.
Integrating AI Voice TTS into Applications
API vs. SDK Integration Paths
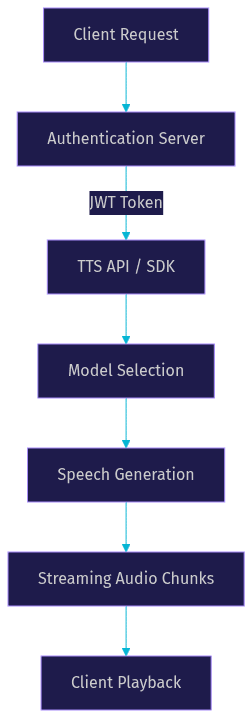
Developers can integrate TTS capabilities via direct HTTP REST APIs or language-specific SDKs. REST APIs offer maximum flexibility and language agnosticism, allowing you to call the service from any backend. However, they require you to handle audio buffering and streaming logic manually. SDKs, such as the VideoSDK Python SDK, provide higher-level abstractions, handling authentication, streaming, and error recovery automatically. For complex real-time applications, an SDK is usually the safer and faster path to production.
Authentication and Security
TTS APIs require authentication to manage usage and billing. The standard approach involves generating a short-lived JSON Web Token (JWT) on your backend using your API key and secret. This token is then passed to the client or used in direct server-to-server calls. Never expose your primary API secret in client-side code. Always route sensitive operations through a secure backend token server to prevent unauthorized usage and billing surprises.
Streaming vs. Batch Output
Batch output generates the entire audio file for a given text block before returning it to the client. This is suitable for pre-recorded content but introduces unacceptable latency for conversational AI. Streaming output sends audio chunks to the client as they are generated. This allows the client to start playback almost immediately, creating a seamless conversational experience. For any interactive voice agent, streaming is a mandatory requirement.
Managing Latency in Production
Even with streaming models, network conditions can cause latency spikes. Developers can mitigate this by pre-fetching common responses or using client-side buffering to smooth out network jitter. Another effective technique is connection pooling on the backend to reduce the overhead of establishing new TLS connections for every TTS request. VideoSDK's AI Agent architecture handles much of this complexity by managing the pipeline between speech-to-text, LLM, and TTS providers, ensuring optimal data flow.
Best Practices and Common Gotchas
Text Pre-processing and SSML
Raw text often contains abbreviations, numbers, or special characters that TTS models can mispronounce. Text pre-processing normalizes this input before synthesis. For finer control, developers use Speech Synthesis Markup Language (SSML). SSML allows you to define pauses, adjust emphasis, and specify phonetic pronunciations. Using SSML effectively can elevate a robotic response into a highly natural, conversational statement. The W3C SSML specification provides the standard tags supported by most major providers.
Rate Limits and Throttling
All commercial TTS APIs enforce rate limits to protect their infrastructure. If your application sends a burst of requests, you may hit these limits and receive throttling errors. Implement exponential backoff and retry logic in your integration layer to handle these gracefully. Monitor your API usage dashboards to understand your consumption patterns and request quota increases before you hit hard limits during peak traffic.
Audio Format Choices
The audio format you choose impacts both latency and quality. MP3 is widely supported and offers good compression, making it suitable for web applications. WAV provides uncompressed, lossless audio but results in larger file sizes and higher bandwidth consumption. Opus is increasingly popular for real-time communication because it offers excellent compression with very low latency, making it the preferred choice for WebRTC-based applications and voice agents.
Error Handling Strategies
Network failures and model timeouts are inevitable in production. Your application should degrade gracefully when TTS synthesis fails. If a high-quality model times out, fall back to a faster, standard model. If all TTS providers fail, ensure your voice agent can communicate the error to the user through alternative channels, such as text chat. Robust error handling ensures your application remains responsive even when downstream services experience issues.
Comparing Leading Providers
Amazon Polly
Amazon Polly is a mature cloud TTS service known for its reliability and deep integration with the AWS ecosystem. It supports dozens of languages and offers both standard and neural voices. Polly excels in high-volume, batch processing scenarios and provides robust SSML support. Its pricing is competitive, making it a solid choice for enterprise applications already running on AWS infrastructure.
Google Cloud Text-to-Speech
Google Cloud TTS offers high-quality neural voices powered by its Gemini and WaveNet models. It provides excellent naturalness and supports a wide array of languages. Google's API is developer-friendly, with strong documentation and seamless integration with other Google Cloud services. It is particularly strong in applications requiring high-fidelity audio and precise pronunciation control.
ElevenLabs
ElevenLabs has set the industry standard for expressive, emotional AI voice generation. Their models capture subtle breathing, pauses, and emotional inflections better than most competitors. ElevenLabs also offers a highly accessible voice cloning workflow, requiring only a minute of clean audio to create a convincing custom voice. They are the go-to provider for premium content creation, audiobooks, and highly engaging conversational agents.
Inworld AI
Inworld AI focuses on real-time, low-latency streaming TTS, specifically tailored for gaming and interactive media. Their models are designed to handle rapid context switching and emotional modulation on the fly. If your application involves non-player characters (NPCs) or highly dynamic conversational agents where response time is measured in milliseconds, Inworld is a strong contender.
OpenAI TTS
OpenAI's TTS API provides versatile models that are incredibly simple to integrate. Known for their natural sound and ease of use, OpenAI's models integrate seamlessly with their broader LLM ecosystem. According to the OpenAI TTS documentation, the API supports multiple voices optimized for different tones. It is an excellent choice for developers already using OpenAI for their LLM layer, as it simplifies the stack.
VideoSDK AI Agent SDK (Unified Wrapper)
Managing multiple TTS providers can become complex. The VideoSDK AI Agent SDK acts as a unified wrapper, allowing developers to swap between TTS providers like ElevenLabs, OpenAI, or Deepgram without rewriting application logic. This abstraction is invaluable for A/B testing voice quality or implementing fallback chains. By using VideoSDK, you can focus on the conversational flow and user experience while the SDK manages the underlying provider connections and streaming protocols.
[LINKABLE ASSET — comparison table]
| Provider | Latency | Languages | Custom Voice | Ideal Use-Case |
|---|---|---|---|---|
| Amazon Polly | Medium | 60+ | Yes (Premium) | Enterprise batch processing |
| Google Cloud TTS | Medium | 50+ | Yes (Premium) | High-fidelity applications |
| ElevenLabs | Low-Medium | 30+ | Yes (Accessible) | Premium content, audiobooks |
| Inworld AI | Very Low | 10+ | Yes | Gaming, real-time NPCs |
| OpenAI TTS | Low | 50+ | No | LLM-integrated chatbots |
| VideoSDK Agents | Variable | N/A | N/A | Unified multi-provider orchestration |
Cost and Pricing Considerations
TTS pricing is typically based on the number of characters or audio minutes processed. Standard models are significantly cheaper than high-quality or custom voices. When budgeting, consider the hidden costs of failed requests and retries. If your application has high traffic, negotiate enterprise pricing or consider providers that offer caching for common phrases. For real-time applications, the cost of streaming can also add up due to sustained connection times. Using a unified SDK like VideoSDK can help optimize costs by allowing you to route traffic to the most cost-effective provider dynamically.
Future Trends in AI Voice TTS
Real-time Emotion Control
Emerging models are moving beyond static voice profiles to offer real-time emotion control. Developers will soon be able to pass parameters like "happy," "sad," or "urgent" to the TTS API, and the model will modulate the tone accordingly. This capability will make conversational agents significantly more empathetic and context-aware.
Edge Inference
Running TTS models locally on devices is becoming viable. Edge inference cuts down network latency to near zero and reduces cloud computing costs. While model sizes are still a constraint, advancements in model quantization are making it possible to run high-quality neural TTS on modern smartphones and edge gateways.
Multimodal Voice-AI Integration
The future of AI voice is not just audio. Multimodal integration combines speech synthesis with visual avatars. Platforms are beginning to offer APIs that generate lip-synced video alongside TTS audio. VideoSDK supports this trajectory by allowing developers to integrate virtual avatars and custom video tracks into their real-time communication pipelines, creating fully immersive conversational experiences.
Definitions Glossary
Neural TTS: A speech synthesis method that uses deep learning models to generate audio waveforms from text, producing more natural and expressive speech than traditional concatenative methods.
Voice Cloning: The process of training a TTS model on a short audio sample of a specific person to generate speech that mimics their unique vocal characteristics.
SSML (Speech Synthesis Markup Language): An XML-based markup language that allows developers to control aspects of speech synthesis like pronunciation, pitch, rate, and pauses.
Vocoder: A component in neural TTS systems that converts a mel-spectrogram (a visual representation of audio frequencies) into a playable audio waveform.
Streaming TTS: A method of delivering synthesized speech where audio chunks are sent to the client as they are generated, reducing the time to first audio playback.
Key Takeaways
- AI voice text to speech relies on neural networks to generate natural, expressive audio from text, replacing older robotic-sounding concatenative methods.
- Developers must balance the trade-off between audio quality and latency, choosing real-time streaming models for conversational agents and high-quality models for pre-recorded content.
- Voice cloning enables the creation of custom brand voices from short audio samples, but requires careful ethical consideration and consent.
- Using a unified wrapper like the VideoSDK AI Agent SDK simplifies multi-provider orchestration, allowing developers to swap TTS engines without rewriting application logic.
- Future advancements in real-time emotion control, edge inference, and multimodal avatars will make AI voice applications more immersive and responsive.
Conclusion
AI voice text to speech has evolved from a robotic novelty into a sophisticated, neural-driven infrastructure component. By understanding the underlying technology, evaluating the trade-offs between quality and latency, and selecting the right provider, developers can build highly engaging voice applications. Whether you are building a conversational agent, an accessibility tool, or a gaming NPC, integrating these models efficiently is key to a great user experience. Explore the VideoSDK AI Agent documentation to see how you can orchestrate STT, LLM, and TTS providers in a unified pipeline. What are you building with AI voice? Drop a comment, I'd love to hear what kind of voice agent use case you're working on. You can start for free at app.videosdk.live/login.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ