


The best IBM Speech to Text alternatives in 2026 are open-source offline engines like Vibe Transcribe and Handy for privacy-critical workloads, and cloud services like Google Cloud Speech-to-Text and Microsoft Azure Speech Services for accuracy and scale. Choose based on latency needs, data residency rules, and budget. VideoSDK also integrates leading STT providers directly into real-time voice and AI agent pipelines.
Speech-to-text has moved from a nice-to-have feature to core infrastructure. Developers now embed transcription into customer support analytics, meeting capture, voice agents, and accessibility tooling. IBM Watson Speech to Text was an early leader here, but its pricing structure, customization overhead, and cloud-only posture push many teams to evaluate other options.
The good news is that the market has matured dramatically. Open-source models now rival commercial accuracy, and cloud providers compete aggressively on latency and language coverage. This guide breaks down the strongest IBM Speech to Text alternatives, compares them across the criteria that actually matter to engineering teams, and gives you a practical migration path.
Why Look for an IBM Speech to Text Alternative?
Teams move away from IBM's speech service for four recurring reasons. Cost is the first: usage-based pricing that scales with audio minutes becomes expensive at high volume, and enterprise contracts add procurement friction. Second, data privacy: IBM's service processes audio in its cloud regions, which is a problem for healthcare, legal, and financial workloads governed by strict data residency rules. Third, platform lock-in: IBM's customization model ties your trained language models to its ecosystem, making migration costly once you have invested in domain tuning. Fourth, feature gaps: modern alternatives offer real-time streaming with sub-second latency, broader SDK coverage, and prebuilt integrations with LLM pipelines that IBM's offering does not match out of the box.
None of this means IBM's service is bad. It means the decision should be re-evaluated as your requirements evolve, especially now that open-source engines deliver competitive accuracy at zero licensing cost.
Key Criteria for Choosing an Alternative
Evaluating speech recognition alternatives requires a structured scorecard. These six criteria cover the dimensions that determine whether a solution survives production.
Accuracy and language coverage
Accuracy is measured by word error rate (WER) on audio that resembles your actual workload: domain vocabulary, accents, background noise, and telephony-quality audio. A provider that benchmarks well on clean studio audio may fail on call-center recordings. Language coverage matters too. Google and Azure support over 100 languages and variants, while smaller engines cover a handful. Verify accuracy claims against independent benchmarks such as Artificial Analysis's Speech Arena rather than vendor marketing pages.
Latency and real-time capabilities
Batch transcription (upload a file, get a transcript) tolerates seconds of delay. Real-time use cases like voice agents and live captioning need sub-500ms round trips. Cloud streaming APIs from Deepgram, Google, and Azure handle this well. Self-hosted open-source models can achieve comparable latency if you provision GPU hardware, but that is an operational commitment.
Pricing model (pay-as-you-you-go vs subscription)
Most cloud STT providers charge per audio minute or per second of processed audio, with tiered discounts at volume. Open-source engines cost nothing in licensing but cost real money in infrastructure and maintenance. Model your expected monthly audio volume and compare total cost of ownership, not sticker price.
On-premise vs cloud deployment
On-premise speech recognition keeps audio inside your network, satisfying strict compliance regimes. Open-source Whisper-family engines run entirely offline. Some commercial providers also offer private deployments, but usually at enterprise pricing.
Privacy and data residency
Check where audio is processed and stored, whether providers retain your data for model training, and whether you can pin processing to specific regions. For GDPR, HIPAA, or sovereign-cloud requirements, this criterion alone can eliminate half the field.
Extensibility and SDK support
Look for client libraries in your stack's languages, webhooks for batch completion, custom vocabulary injection, and speaker diarization. If you are building voice agents, consider platforms like VideoSDK's AI agent infrastructure, which abstracts STT, LLM, and TTS provider selection into one pipeline so you can swap engines without rewriting your application.
Open-Source Alternatives Overview
Open-source speech-to-text has become genuinely production-grade. Two projects stand out for developers who want full control.
Vibe Transcribe
Vibe Transcribe is an offline transcription application built on OpenAI's Whisper model family. It runs entirely on your local machine, which means no audio ever leaves your device. That makes it a strong fit for journalists, researchers, and developers handling sensitive recordings. It supports the major desktop platforms and leverages community-driven model improvements, so accuracy tracks the underlying Whisper releases. The trade-off is speed on CPU-only machines: long recordings can take time, though GPU acceleration changes that significantly. For developers, Vibe demonstrates that Whisper-class accuracy is achievable with zero API spend and zero data exposure, which is exactly the combination that motivates many IBM migrations.
Handy
Handy takes a similar offline-first philosophy with an MIT license, making it attractive for developers who want to inspect, fork, and embed the code. Its interface focuses on the practical transcription workflow: record or import audio, transcribe, edit, and export. Because it is MIT-licensed, teams can integrate its approach into internal tooling without licensing review. It suits developers building dictation tools or batch transcription utilities where a full commercial SDK is overkill. Like all local Whisper deployments, its accuracy is strong on general speech but benefits from custom fine-tuning for specialized vocabulary.
Both projects prove the same point: the open-source floor has risen to where, for many workloads, the best IBM Speech to Text alternative costs nothing and runs on hardware you already own.
Cloud-Based Commercial Alternatives
When you need scale, streaming latency, or broad language coverage, commercial cloud STT remains the pragmatic choice.
Google Cloud Speech-to-Text
Google's offering is the accuracy benchmark for many workloads, with support for over 100 languages and variants, automatic punctuation, speaker diarization, and domain-specific model selection. Its streaming API supports real-time transcription suitable for live captioning and voice interfaces. Pricing follows a per-second or per-minute usage model with a free monthly allowance, and custom model adaptation lets you boost domain vocabulary. Its main drawback is the same as any hyperscaler: audio is processed in Google's cloud, which may conflict with strict residency requirements.
Microsoft Azure Speech Services
Azure Speech Services combines strong real-time streaming with deep customization. Custom Speech lets you train models on your own audio datasets, which is the closest replacement for IBM's language model customization, and its integration with the broader Azure ecosystem (Logic Apps, Bot Framework, Teams telephony) makes it a natural fit for enterprises already on Microsoft infrastructure. It supports batch and streaming modes, broad language coverage, and containerized deployment for on-premise scenarios, a rare capability among hyperscalers.
Comparison Table
The table below contrasts the five solutions across the criteria that matter most. Treat accuracy figures as directional and validate against your own audio samples.
| Solution | Accuracy | Latency | Cost | Privacy | SDK breadth |
|---|---|---|---|---|---|
| IBM Watson STT | Strong, customizable | Moderate streaming | Usage-based, enterprise tiers | Cloud regions, configurable | Good |
| Vibe Transcribe | Strong (Whisper-based) | Slow on CPU, fast on GPU | Free, local compute only | Fully offline | Desktop app, no API |
| Handy | Strong (Whisper-based) | Local, hardware-dependent | Free, MIT license | Fully offline | Source available, embeddable |
| Google Cloud STT | Excellent, 100+ languages | Sub-second streaming | Per-minute, free allowance | Cloud processing, residency options | Excellent |
| Azure Speech | Excellent, custom models | Sub-second streaming | Per-minute, free tier | Cloud plus container option | Excellent |
The most important row depends on your constraint. If privacy drives the migration, the offline options win outright. If latency and language coverage dominate, Google and Azure lead.
The architecture difference between these two families is worth visualizing, because it determines where your audio data lives and where processing happens:
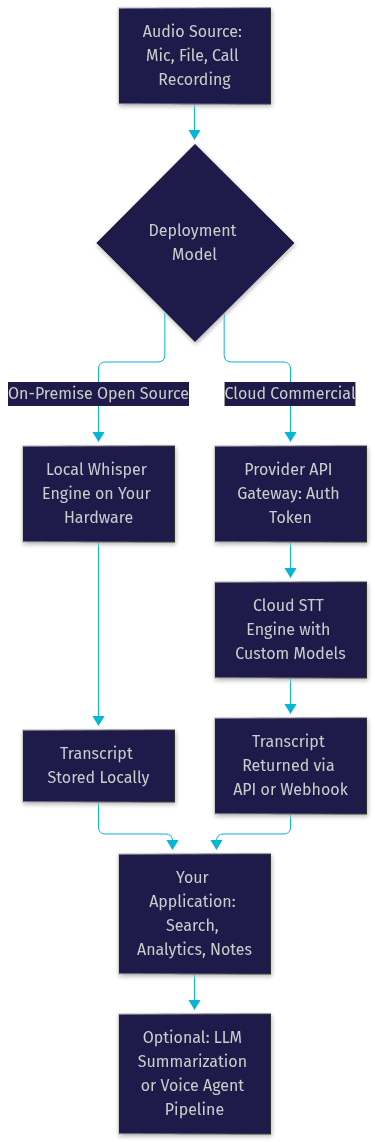
In the on-premise path, audio never crosses your network boundary. In the cloud path, you trade data locality for elastic scale, streaming latency, and managed model improvements.
Integration Considerations
Migrating STT providers is an integration project as much as a model swap. Plan for these four areas.
API authentication and token management
Every cloud provider uses credential-based authentication, typically short-lived tokens issued from a service account. Centralize credential storage in your secrets manager, rotate keys on a schedule, and never embed credentials in client-side code. When you decommission IBM, revoke its keys immediately to avoid orphaned billing.
Streaming vs batch transcription
Batch APIs accept files and return transcripts asynchronously, often via webhooks. Streaming APIs accept a continuous audio stream and return partial results in real time. Your use case dictates the choice: meeting archives are batch; live agents and captioning are streaming. Some providers price these differently, so confirm the model before committing.
Handling audio formats and sample rates
Providers differ in supported formats and sample rates. Telephony audio at 8 kHz behaves differently from 16 kHz studio audio, and accuracy drops when engines receive unexpected formats. Build a normalization layer that converts, resamples, and validates audio before it reaches the STT engine, so switching providers does not require reworking your ingestion pipeline.
Error handling and fallback strategies
Production systems need graceful degradation. Implement retry logic with exponential backoff for transient failures, queue unprocessed audio for retry, and consider a fallback provider for critical workloads. If you are building real-time voice agents, VideoSDK's agent pipeline supports fallback adapters so a primary STT provider failing mid-session does not break the user experience.
Cost and Privacy Implications
Model two scenarios to understand the economics. At low volume, say under a few hundred audio hours per month, cloud per-minute pricing is cheap and operationally simple; open-source infrastructure costs more than you save. At high volume, thousands of hours monthly, the math flips: a self-hosted Whisper deployment on a single GPU can process enormous volumes for the cost of hardware and electricity, with zero per-minute fees.
Privacy economics are simpler. On-premise engines keep every recording inside your perimeter, eliminating data processing agreements, residency audits, and breach exposure from third-party processors. For regulated industries, that risk reduction often justifies the operational overhead by itself. Cloud providers counter with region pinning and no-training guarantees, which satisfy many but not all compliance regimes.
Making the Switch: Practical Steps
A structured migration reduces risk. Follow this sequence.
- Evaluate requirements. Document your latency budget, language needs, volume, privacy constraints, and current IBM spend. This scorecard drives the shortlist.
- Run a pilot. Select two candidates and transcribe a representative sample of your real audio, including your worst-case recordings.
- Benchmark accuracy. Measure word error rate against human-verified reference transcripts for each candidate, not vendor benchmarks.
- Update integration code. Swap the provider client, adapt audio normalization, and update credential management. Isolate the STT call behind an internal interface so future swaps are cheap.
- Decommission IBM keys. After validation, revoke IBM credentials, remove them from secrets stores, and confirm billing stops.
Most teams complete this in two to four weeks, with the benchmarking phase consuming the most calendar time.
Definitions Glossary
Word Error Rate (WER): The standard accuracy metric for speech recognition, calculated from substitutions, deletions, and insertions relative to a reference transcript. Lower WER means more accurate transcription.
Streaming transcription: Real-time speech recognition that processes audio as it arrives and returns partial results within seconds, required for live captioning and voice agents.
Batch transcription: Asynchronous processing where complete audio files are submitted and transcripts are returned later, suited to archives and recorded media.
Speaker diarization: The ability of an STT system to separate and label multiple speakers within a single audio stream, essential for meeting and call transcription.
On-premise speech recognition: Speech-to-text processing that runs entirely on infrastructure you control, keeping audio data inside your network boundary.
Agent pipeline: In VideoSDK's AI agent architecture, the chained sequence of speech-to-text, language model, and text-to-speech processing that powers a real-time voice agent.
Key Takeaways
- Open-source Whisper-based engines like Vibe Transcribe and Handy now deliver competitive accuracy with zero licensing cost and fully offline processing.
- Google Cloud Speech-to-Text and Azure Speech Services lead on streaming latency, language coverage, and SDK breadth, with Azure offering containerized on-premise deployment.
- Privacy-critical workloads favor on-premise engines because audio never leaves your network, eliminating third-party processor risk.
- Cost economics flip at scale: cloud per-minute pricing wins at low volume, self-hosted GPUs win at high volume.
- A structured migration (requirements, pilot, benchmark, integration, key decommission) reduces risk and typically completes in two to four weeks.
Conclusion
The IBM Speech to Text alternative landscape in 2026 is strong from both ends: open-source engines for full control and privacy, and hyperscaler APIs for accuracy and scale. Start by benchmarking the open-source options on your own audio, since the cost of testing them is nearly zero. If you are building real-time voice experiences, explore how VideoSDK's AI agent infrastructure lets you plug leading STT providers into a production-ready voice pipeline, and check the code samples to get moving quickly. Sign up free at app.videosdk.live and start building. What are you building with speech recognition? Drop a comment, I'd love to hear which STT engine you chose and why.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ