


Google real time speech to text is the streaming recognition capability of Google Cloud Speech-to-Text, which converts live audio into text with sub-second latency using gRPC or REST streaming endpoints. It supports speaker diarization, automatic punctuation, 85+ languages, and custom vocabulary biasing, and it now includes the Gemini 3.5 Transcribe model for intelligent transcription. This guide covers how it works, what it costs, and how to implement it well, and you can explore the VideoSDK real-time transcription docs for embedding transcription directly into live video and audio calls.
Sub-second transcription is no longer a nice-to-have. Live captions, voice assistants, call-center analytics, and accessibility tools all fail if the text lags seconds behind the speech. Developers building these products need speech recognition that behaves like a conversation partner, not a batch job.
Google's real-time speech-to-text offering, part of Google Cloud's Speech-to-Text API family, is one of the most widely used streaming recognition engines in production today. Its streaming mode delivers interim results while the user is still speaking, which is exactly what interactive applications require. With the arrival of Gemini 3.5 Transcribe, Google is also pushing the boundary between transcription and language understanding, which changes what developers can build on top of it.
By the end of this guide, you will understand the architecture, features, pricing, accuracy trade-offs, and implementation best practices for Google real time speech to text, plus how it compares to Azure, AWS, Deepgram, and OpenAI Whisper.
What Is Google Real-Time Speech-to-Text?
Google real time speech to text is defined as the streaming recognition mode of Google Cloud Speech-to-Text, a managed API that converts live audio into text as it is being spoken. Unlike batch transcription, which processes a completed audio file after the fact, streaming recognition sends audio in small chunks to Google's inference servers and returns partial, then final, transcription results continuously.
The service sits within Google Cloud AI alongside the broader Speech-to-Text product family. Core capabilities include low-latency streaming recognition, automatic punctuation and capitalization, speaker diarization (labeling which speaker said which words), word-level timestamps, automatic language detection, and speech adaptation for biasing recognition toward custom vocabularies like product names or domain jargon.
The newest addition is Gemini 3.5 Transcribe, a model that goes beyond raw transcription into what Google calls intelligent transcription: removing filler words, formatting speech into readable text, and supporting function calling on the transcribed content. For developers, this means the line between a speech API and a language model API is deliberately blurring, and real-time pipelines can now produce output that is closer to a clean, structured document than a raw word stream.
How Google Real-Time Speech-to-Text Works
Google real time speech to text works by establishing a persistent streaming connection between your client application and Google's inference infrastructure, then continuously sending audio chunks and receiving incremental transcription results. The typical flow runs from client to a gRPC or REST streaming endpoint, into Google's speech recognition servers, and back as structured JSON responses containing transcripts, confidence scores, and timestamps.
The client captures audio, encodes it in a supported format, and opens a bidirectional streaming session. Google recommends gRPC for real-time use because it supports bidirectional streaming natively, while REST streaming works but adds overhead. Audio is typically sent in chunks of roughly 100 milliseconds, and the service returns interim results as recognition progresses, followed by a final result when the utterance ends or the stream closes.
Authentication is handled through Google Cloud IAM. Your application authenticates using a service account with the appropriate Speech-to-Text role, and credentials are exchanged for short-lived access tokens. Never embed long-lived service account keys in client-side code; generate tokens server-side and scope them narrowly.
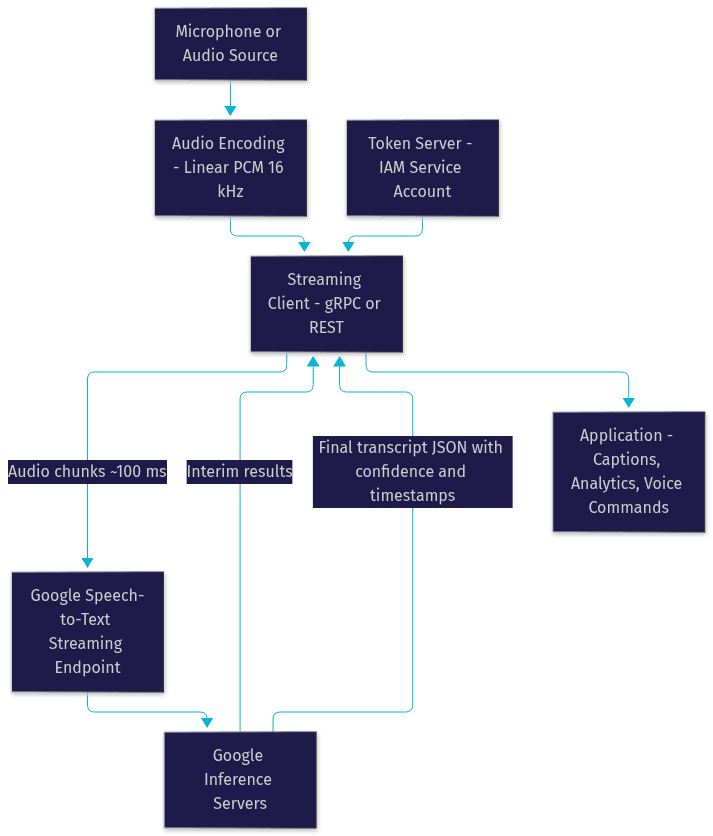
The JSON response contains the recognized text, a confidence score between zero and one, word-level timing information, and, when diarization is enabled, speaker labels. Your application decides how to render interim versus final results, which is a key UX decision for live captioning.
Key Features for Real-Time Use
Google's streaming Speech-to-Text earns its place in production systems through a specific set of real-time capabilities. Here are the ones that matter most to developers building interactive applications.
Low-Latency Streaming Results
The streaming mode returns interim results while speech is ongoing, so your UI can show text almost as fast as it is spoken. Reported latency for interim results is typically in the hundreds of milliseconds range, well under the one-second threshold that interactive applications demand. This is the single feature that separates streaming recognition from batch transcription.
Automatic Punctuation and Filtering
The service inserts punctuation and capitalization automatically, which saves you from post-processing. Profanity filtering can be enabled per request, useful for customer-facing captioning. In practice, teams building public-facing live captions almost always enable punctuation immediately, since unpunctuated interim text reads poorly on screen.
Speaker Diarization and Word Timestamps
Diarization labels each recognized word with a speaker number, letting you reconstruct who said what in a multi-speaker conversation. Word-level timestamps let you sync captions to audio playback, build searchable transcripts, and highlight the current word in accessibility interfaces. Note that diarization works best with clear speaker separation and can degrade on overlapping speech.
Custom Vocabulary and Speech Adaptation
Speech adaptation lets you bias recognition toward domain-specific terms: product names, acronyms, medical vocabulary, or regional names. You supply phrases and boost weights, and the recognizer prioritizes those terms during decoding. For telehealth or legal transcription, this feature often makes the difference between usable and unusable output.
Multi-Language Support and Auto-Detect
Google Speech-to-Text supports more than 85 languages and variants, and streaming can automatically detect the spoken language when you specify multiple candidates. This matters for global call centers and multilingual meeting platforms where you cannot predict the caller's language in advance.
Confidence Scores and Alternatives
Every result includes a confidence score, and you can request alternative hypotheses for ambiguous utterances. Applications can use low-confidence flags to trigger human review or to prompt users to repeat a voice command, which is a common pattern in voice assistant design.
Pricing and Cost Considerations
Google Speech-to-Text pricing is metered per minute of audio processed, with different rates for standard and enhanced models. The free tier provides 60 minutes per month at no charge, which is enough for prototyping and small pilots.
Enhanced models, which improve accuracy on noisy or domain-specific audio, cost more per minute than standard models. Diarization adds an additional per-minute charge on top of the base recognition cost, so a fully featured real-time pipeline with diarization and an enhanced model can cost meaningfully more than a bare streaming setup. Volume discounts apply at scale, and committed-use contracts reduce per-minute rates for high-volume call-center workloads.
A simple cost example illustrates the shape of the bill. Imagine a webinar platform running 500 hours of live captioning per month using an enhanced model with diarization enabled. You would multiply the monthly minutes by the enhanced recognition rate, then add the diarization surcharge for the same minutes. The diarization line item is the one that surprises teams most often, because it applies to every minute, not just the minutes where multiple speakers are active.
For real-time video call applications, also consider that transcription minutes scale with concurrent participants. A ten-person meeting where every participant's audio is transcribed consumes ten minutes of STT billing per wall-clock minute. This is where embedding transcription through a platform like VideoSDK, which includes real-time transcription as part of its communication SDKs, can simplify both the integration and the cost model.
Performance and Accuracy
Accuracy for Google's streaming recognition is typically measured in word error rate (WER), the percentage of words that are substituted, deleted, or inserted relative to a reference transcript. Google's own documentation reports that enhanced models reduce WER significantly compared to standard models, particularly on noisy audio and domain-specific vocabulary. Independent benchmarks, such as those tracked by Artificial Analysis for speech models, generally place Google's recognition quality among the leading commercial providers, though exact rankings shift as new models ship.
Streaming recognition usually carries a modest accuracy penalty compared to batch recognition, because the model has less future context available while decoding. The gap narrows with enhanced models and good audio quality.
Three factors dominate real-world accuracy. First, audio quality: a clean 16 kHz signal from a decent microphone beats a compressed, noisy phone line every time. Second, sample rate: recognition is optimized around 16 kHz for speech, and resampling from unusual rates can degrade results. Third, background noise: music, keyboard clicks, and crosstalk all raise WER, and while the enhanced models are more robust, they are not magic. Teams deploying call-center transcription should test on their actual call audio, not studio recordings, before committing to a model tier.
Implementation Best Practices
Getting good results from Google real time speech to text is mostly about respecting the constraints of streaming systems. These practices come from production deployments, not quickstarts.
Choose the Right Audio Format
Use Linear PCM at a 16 kHz sample rate with 16-bit samples for streaming speech recognition. This matches what the acoustic models expect and avoids server-side transcoding overhead. If your source audio arrives compressed, for example from a WebRTC call, decode it to PCM before streaming. Sending audio at an unexpected sample rate is one of the most common causes of degraded accuracy.
Keep the Streaming Connection Stable
Streaming sessions are sensitive to network conditions. Use gRPC keep-alive settings to prevent intermediate proxies from closing idle connections, and implement automatic reconnection with buffered audio so a brief network hiccup does not lose speech. On unstable mobile networks, consider sending slightly larger audio chunks to reduce round-trip overhead, at the cost of a small latency increase.
Manage the Streaming Lifecycle Explicitly
A streaming session has a defined lifecycle: open the stream, send audio, receive interim results, receive the final result, and close cleanly. Handle each stage deliberately. Interim results should be rendered as replaceable text, since the final result for an utterance may differ from the last interim result. Implement error recovery so that a failed stream resumes without dropping audio, and enforce the maximum stream duration by rotating sessions before Google closes them for you.
Secure Authentication Properly
Use a dedicated IAM service account with only the Speech-to-Text role attached. Generate short-lived access tokens on your backend and hand them to clients, rather than shipping service account keys in browser or mobile bundles. Rotate credentials on a schedule, and audit which services can mint tokens. Exposed long-lived keys are the most common security incident in Speech-to-Text deployments.
Reduce Latency and Improve Diarization
To reduce latency, keep audio chunks small and consistent, avoid client-side buffering before the first send, and co-locate your token server close to your users. To improve diarization, ensure each speaker's audio is captured on a separate channel where possible, since multi-channel audio with one speaker per channel produces far better diarization than a mixed mono signal.
Real-World Use Cases
Google real time speech to text powers several distinct product categories, each with different requirements.
Live captioning for webinars and virtual events. Organizers display captions in real time so attendees can follow along muted, in noisy environments, or in a second language. Interim results keep captions flowing naturally, and word timestamps let the caption UI scroll in sync with the speaker. Platforms like VideoSDK's interactive live streaming pair naturally with a streaming STT backend for exactly this scenario.
Voice assistants and smart home commands. Sub-second interim results let an assistant acknowledge a command before the user finishes speaking, which is what makes voice interaction feel responsive. Confidence scores gate command execution, so low-confidence utterances trigger a clarification prompt instead of a wrong action.
Call-center analytics and compliance transcription. Contact centers transcribe every call in real time for live agent assistance, sentiment detection, and post-call analytics. Speech adaptation handles product names and industry jargon, and diarization separates agent from customer for accurate analytics. Compliance regimes like HIPAA and GDPR are supported under Google Cloud's standard data-processing terms, though you remain responsible for configuring retention correctly.
Accessibility tools. Real-time captions for hearing-impaired users are one of the highest-impact applications of streaming STT. Word-level timestamps enable karaoke-style highlighting, and low latency is not optional here, since delayed captions break the connection between speech and text.
Meeting transcription and searchable archives. Teams transcribe meetings live, then index the transcripts for search. The final results, with speaker labels and timestamps, become the archive, while interim results serve the live view. For meetings built on video calling SDKs, VideoSDK's real-time transcription offers this pipeline pre-integrated, which removes the need to wire a separate STT backend to the audio streams.
Comparison with Major Competitors
Google competes with several strong streaming STT providers, and the right choice depends on your constraints.
| Provider | Latency | Language Coverage | Standout Feature | Best For |
|---|---|---|---|---|
| Google Speech-to-Text | Sub-second interim results | 85+ languages | Gemini 3.5 intelligent transcription, strong diarization | Multi-language products already on Google Cloud |
| Azure Speech | Sub-second | 100+ languages | Strong custom speech training | Microsoft-stack enterprises |
| AWS Transcribe | Low | Broad | Deep AWS analytics integration | AWS-native call centers |
| Deepgram | Very low | Focused set | Lowest-latency streaming, competitive pricing | Latency-critical voice agents |
| OpenAI Whisper | Higher for streaming | Very broad | Open model, strong noise robustness | Batch and offline workloads |
[LINKABLE ASSET — comparison table]
The most important row for most readers is latency. If you are building a voice agent where every 100 milliseconds of response time compounds through the pipeline, Deepgram's streaming latency is a serious contender. If you are building a multilingual webinar platform already running on Google Cloud, Google's language coverage, diarization quality, and the new Gemini 3.5 Transcribe capabilities make it the pragmatic choice.
A simple decision framework: choose Google when you need broad language support, intelligent transcription features, and you are already in the Google Cloud ecosystem. Choose Azure when your stack is Microsoft and you need deep custom acoustic model training. Choose AWS Transcribe when your analytics live in AWS. Choose Deepgram when raw streaming latency is the dominant requirement. Choose Whisper for offline and batch transcription where latency does not matter.
Future Trends: Gemini 3.5 Transcribe and Intelligent Transcription
Gemini 3.5 Transcribe represents a shift in what a speech API is for. Beyond converting speech to text, it performs filler-word removal, reformats spoken phrasing into readable prose, and supports function calling on transcribed content, meaning the transcription output can directly drive structured actions in your application.
This blurs the line between STT and LLM processing. Traditionally, a voice pipeline ran speech recognition, then fed the raw transcript into a separate language model for cleanup and intent extraction. Intelligent transcription collapses those stages, reducing end-to-end latency and removing a whole class of glue code.
For real-time applications, the impact is significant. A live captioning system can display clean, punctuated, filler-free text without a post-processing step. A voice agent can extract structured intent directly from the transcription stream. As these capabilities mature, expect the distinction between a transcription API and a conversational AI API to keep shrinking, and expect pricing models to evolve accordingly.
Definitions Glossary
Streaming recognition: The Speech-to-Text mode where audio is sent continuously in chunks and interim results are returned while speech is ongoing, enabling sub-second transcription for live applications.
Speaker diarization: The process of labeling which speaker produced each recognized word, allowing multi-speaker audio to be reconstructed into per-speaker transcripts.
Word error rate (WER): The standard accuracy metric for speech recognition, measuring the percentage of words substituted, deleted, or inserted relative to a reference transcript.
Speech adaptation: A Google Speech-to-Text feature that biases recognition toward custom phrases and vocabulary, improving accuracy on domain-specific terms like product names and jargon.
Interim results: Partial transcription results returned during streaming recognition that may be revised before the final result for an utterance is committed.
Real-time transcription in VideoSDK: Built-in transcription capability within VideoSDK's communication SDKs that converts live meeting and call audio into text without wiring a separate STT backend to the audio streams.
Key Takeaways
- Google real time speech to text delivers sub-second interim results through streaming gRPC or REST endpoints, making it suitable for live captioning, voice assistants, and call-center analytics.
- Enhanced models and speech adaptation substantially improve accuracy on noisy audio and domain vocabulary, at a higher per-minute cost than standard models.
- Diarization adds a per-minute surcharge that applies to all transcribed minutes, so budget for it explicitly in multi-speaker pipelines.
- Best results come from Linear PCM audio at 16 kHz, stable gRPC connections with keep-alive, explicit streaming lifecycle handling, and server-side token generation through IAM.
- Gemini 3.5 Transcribe is merging transcription with language understanding, enabling filler removal and function calling directly from the speech pipeline.
- For video and audio call applications, VideoSDK's real-time transcription offers this capability pre-integrated into its communication SDKs.
Conclusion
Google real time speech to text remains a strong default for developers who need low-latency transcription with broad language coverage, solid diarization, and a clear path toward intelligent transcription through Gemini 3.5 Transcribe. Start with the 60-minute free tier to validate accuracy on your real audio, then test an enhanced model with speech adaptation before committing to a pricing tier. If you are building transcription into live video calls or streaming experiences, explore VideoSDK's real-time transcription to get the pipeline pre-integrated, and sign up at app.videosdk.live/login to try it. What are you building with real-time speech recognition? Drop a comment, I'd love to hear what kind of transcription use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ