


Real time AI translation for voice and video calling is the process of converting a speaker's words into another language and delivering them as translated speech or subtitles while the call is still happening. It chains speech-to-text, an AI translation layer, and text-to-speech into a pipeline that typically completes in 0.5 to 3 seconds. VideoSDK's room-based architecture, custom tracks, and real-time transcription features give developers a practical foundation for hosting these translated streams in production.
Two people on a video call, one speaking Japanese and one speaking Spanish, and each hearing the other in their own language within about a second. That scenario is no longer a research demo. It is a shipping product category in 2026, driven by remote-first teams, cross-border telehealth, and global customer support.
Real time AI translation for voice and video calling is what makes it work. Developers building multilingual collaboration tools, telemedicine platforms, and international support centers are actively searching for how to wire speech recognition, machine translation, and neural voices into their calling infrastructure without wrecking call quality.
This guide walks the full path: how the pipeline works, the architecture, the hard technical challenges, a step-by-step implementation blueprint in plain language, and how to integrate the whole thing with an RTC SDK like VideoSDK. By the end, you will know exactly what to build and what to test before going live.
What Is Real Time AI Translation for Voice and Video Calling?
Real time AI translation for voice and video calling is defined as the live conversion of spoken language in a call into another language, delivered as translated audio, subtitles, or both, with low enough latency that conversation feels natural. It works by chaining three stages: a speech-to-text (STT) layer transcribes what each speaker says, an AI translation layer converts that text into the target language, and a text-to-speech (TTS) layer renders the translated text as natural-sounding voice.
The critical word is "real time." A subtitled movie is translation. A translated call is translation plus a latency budget. Most production systems land between 0.5 and 3 seconds end to end, and anything beyond roughly 3 seconds starts to break conversational rhythm, because speakers begin talking over each other's delayed responses.
There are two delivery modes. Full audio translation replaces the speaker's voice with a translated voice. Subtitle overlay keeps the original audio and adds translated captions, which is cheaper, faster, and often preferred in professional settings where tone matters.
The Speech-to-Text (STT) Layer
The STT layer is the foundation, and its quality caps the quality of everything downstream. Modern options include OpenAI's Whisper family, Deepgram's Nova models, Google Cloud STT, and ElevenLabs Scribe, each with different speed and accuracy profiles on conversational audio.
The core trade-off is on-device versus cloud. On-device STT keeps audio private and avoids network round trips, but mobile hardware limits model size and accuracy. Cloud STT delivers better accuracy, speaker diarization, and streaming recognition at the cost of latency and sending audio off the device. For calls, streaming STT matters more than batch accuracy: you want partial transcripts as words are spoken, not a full transcript after the sentence ends.
The AI Translation Layer
The translation layer converts transcribed text into the target language. In 2026 this is almost always an LLM or LLM-adjacent service: Google Gemini, OpenAI models served through fast inference providers like Groq or Cerebras, or Anthropic's Claude family. LLM-based translation beats older phrase-based systems because it handles context, idioms, and tone, not just word substitution.
Latency is the deciding factor here. A large model producing beautiful translations in 4 seconds is useless in a live call. Fast inference platforms that serve smaller, optimized models in a few hundred milliseconds are the practical choice. Real-time multimodal models such as OpenAI Realtime and Google Gemini Live are beginning to collapse STT, translation, and TTS into a single step, which removes an entire round trip from the pipeline.
The Text-to-Speech (TTS) Layer
The TTS layer renders translated text as speech. Neural voices from ElevenLabs, Cartesia, Azure Speech, and OpenAI TTS have reached the point where most listeners cannot reliably distinguish them from human recordings in short bursts.
Two decisions matter here. First, voice choice: a distinct voice per language helps listeners track who is speaking, and voice cloning can preserve a speaker's identity across languages, though it raises consent and ethics questions you should resolve before shipping. Second, streaming synthesis: sentence-level TTS adds a full sentence of delay, while chunked or streaming TTS starts speaking as soon as the first phrase is translated. For real time AI translation for voice and video calling, streaming TTS is non-negotiable if you are delivering audio rather than subtitles.
Architecture Overview: The Translation Pipeline End to End
The pipeline is a chain of services with audio flowing in one direction and latency accumulating at every hop. A speaker's microphone audio is captured, streamed to an STT service, converted to text, passed to a translation engine, synthesized by a TTS service, and then routed back into the call so the other participant hears the translated voice.
The last hop is the one most tutorials skip: getting translated audio back into the call. On desktop, virtual audio drivers such as BlackHole on macOS or VB-Cable on Windows act as a loopback device, so the TTS output appears as a microphone input to the calling app. On server-side architectures, the translation pipeline joins the call as a bot participant and publishes its audio as a regular stream, which is cleaner and works on mobile.
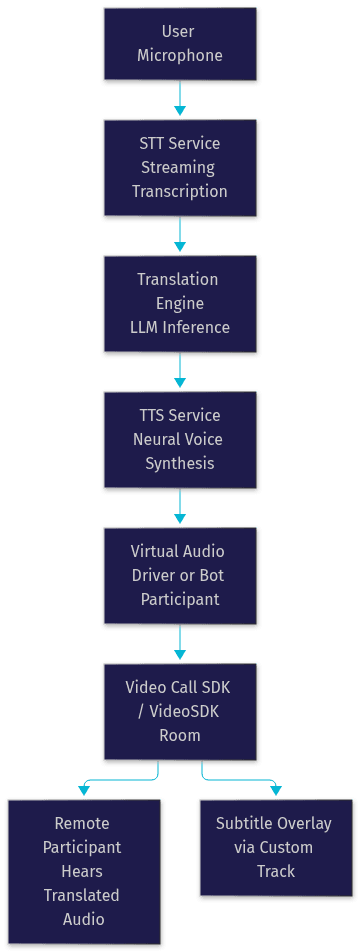
The diagram above shows the full data flow. Every arrow is a latency contributor, which is why the biggest architectural decision is how many of these stages you can collapse or run in parallel.
Key Technical Challenges in Real Time AI Translation
Latency Management
Sub-second latency is the difference between a conversation and a relay exercise. Humans tolerate roughly 200 milliseconds of round-trip delay in normal speech; translation adds unavoidable processing time on top, so the goal is to keep the total added delay under about 1.5 seconds so the exchange still feels live.
Three techniques help. First, use streaming at every stage: streaming STT, chunked translation, and streaming TTS, so work overlaps instead of queueing. Second, keep buffers small; large audio buffers smooth out network jitter but add fixed delay to every utterance. Third, run the pipeline asynchronously with respect to the call itself, so translation never blocks media transport. If the underlying RTC layer has network-adaptive streaming, like VideoSDK's automatic bitrate adjustment, the call stays stable even when the translation pipeline is working hard.
Accuracy and Context
Accuracy failures in real time AI translation for voice and video calling are usually context failures. Medical calls need drug names and anatomy handled correctly; sales calls need product terminology and numbers preserved. Feed the translation layer a domain glossary or system context so the LLM knows the vocabulary. Speaker diarization matters in multi-party calls, because attributing a sentence to the wrong speaker produces a confidently wrong translation. Always design a fallback: if translation confidence is low, deliver the original transcript as a subtitle rather than a possibly wrong spoken translation.
Privacy and Security
Call audio is sensitive data. On-device STT keeps raw audio private but limits accuracy. Cloud pipelines should encrypt audio in transit and at rest, avoid retaining transcripts after the call, and comply with regional rules like HIPAA for telehealth or GDPR for European users. Token-scoped access to rooms, as VideoSDK provides with server-generated meeting tokens, prevents unauthorized participants from ever reaching the audio in the first place.
Implementation Blueprint: Building Real Time AI Translation Step by Step
Here is the complete workflow in plain language, from empty repository to production call.
Step 1: Choose Your STT Provider
Pick a streaming STT service based on your latency budget and privacy model. Cloud services like Deepgram or Google Cloud STT give streaming partial transcripts with speaker labels. Evaluate each candidate on conversational audio in your target languages, not on clean studio recordings, because call audio is compressed, noisy, and overlapping. Confirm the service emits interim results, since waiting for finalized sentences adds hundreds of milliseconds.
Step 2: Set Up the Translation API
Configure an LLM-backed translation endpoint with a fast inference provider. Define the language pairs you will support at launch, and provide domain context as part of the request so technical vocabulary translates correctly. Measure the round-trip time for a typical sentence; if it exceeds a few hundred milliseconds, switch to a smaller model or a faster inference platform. Design the layer to translate phrase-level chunks rather than full turns.
Step 3: Deploy the TTS Service
Select a neural TTS provider and pick a distinct voice per language so listeners can distinguish speakers. Enable streaming synthesis so audio starts playing before the full sentence is translated. If you offer subtitle mode instead of audio mode, this step becomes text rendering, which is faster and cheaper. Decide upfront whether voice cloning is in scope, and if so, obtain explicit consent from users whose voices are cloned.
Step 4: Route Audio Through a Virtual Driver or Bot Participant
For desktop apps, install a virtual audio driver and configure the TTS output to play into it, so the calling app treats translated speech as microphone input. For server-side or mobile deployments, run the pipeline as a bot participant that joins the room and publishes translated audio as its own stream. The bot approach is more robust and works uniformly across platforms.
Step 5: Hook Into a WebRTC or VideoSDK Room
Connect the pipeline to your RTC layer. With VideoSDK, create a room server-side, generate a scoped meeting token, and have the translation bot join as a participant. Publish translated audio as a custom track, and use the SDK's data channels or custom tracks to deliver subtitle text to the other participants' UIs. The REST API reference lets you orchestrate room creation and participant management from your backend.
Step 6: Test with Latency Tools
Before launch, instrument the pipeline end to end. Timestamp each stage: audio capture, transcript arrival, translation completion, TTS start, and remote playback. Verify behavior on poor networks with 3G simulation. Run the VideoSDK quickstart alongside your pipeline to confirm the call layer itself is not your bottleneck.
Common Pitfalls
Three problems bite nearly every team. Token expiry mid-call drops the translation bot from the room, so refresh tokens before they lapse. Audio format mismatches between the STT service and the calling SDK produce silent failures where transcripts simply never arrive; validate sample rates and channel counts early. And HTTPS is mandatory in production browsers for microphone access, so a pipeline that works on localhost can fail entirely on a deployed domain.
Integrating Real Time AI Translation with VideoSDK
VideoSDK's room-based architecture maps naturally onto this pipeline. A room is the shared media space where participants, including your translation bot, publish and subscribe to streams. The bot joins like any other participant, receives the original speaker's audio, and publishes translated audio and subtitle data back into the same room.
Three VideoSDK capabilities matter specifically. First, custom video and audio tracks let you publish the translated stream and overlay subtitle text without hacking the default media flow. Second, the Prebuilt UI Kit gets a working call interface running in minutes, so your team can focus on the translation pipeline rather than call UI. Third, token-based authentication, generated server-side with your API key and secret, keeps room access controlled; never generate tokens on the client.
VideoSDK also offers real-time transcription natively, which can replace or supplement your external STT layer and remove one integration hop. And if you want the translation logic itself to be an AI agent rather than hand-wired services, the VideoSDK AI Agents framework supports STT, LLM, and TTS plugins in a managed pipeline.
Real-World Use Cases for Real Time AI Translation
Telehealth consultations across languages. A patient describes symptoms in Portuguese; the doctor hears and reads English. Subtitle mode is often preferred here because clinicians want the patient's original tone, and medical glossaries keep drug names and dosages accurate. Compliance requirements make on-device or encrypted-cloud processing essential.
International sales calls and negotiations. A seller speaks Mandarin; the buyer hears Korean with a distinct translated voice. Phrase-level latency keeps the deal conversation flowing, and number accuracy is critical, so the translation layer needs explicit instruction to preserve figures, currencies, and contract terms exactly.
Live-streamed webinars with multilingual audiences. A host presents in English while thousands of viewers in a VideoSDK interactive live streaming room receive subtitles in their own languages. Subtitle delivery scales far better than per-viewer translated audio, and the audience can react in real time through chat and polls.
Gaming voice chat with on-the-fly translation. Squadmates speaking different languages coordinate in real time. Here, on-device or edge STT reduces latency and keeps bandwidth low, and a slightly robotic translated voice is perfectly acceptable in exchange for cross-language teamwork.
Evaluation Metrics and Monitoring
Ship with measurable targets, not vibes. Four KPIs cover the pipeline. End-to-end latency, measured from speech onset to translated audio or subtitle display, should sit under 1.5 seconds for audio mode and under 1 second for subtitles. Word error rate on the STT layer, benchmarked per language on conversational audio, tells you whether recognition is your weak link. Translation quality, tracked with BLEU or COMET scores plus human spot checks, catches regressions when you swap models. User satisfaction, gathered with a simple post-call rating, is the metric that actually predicts retention.
Monitor continuously in production. VideoSDK's session analytics expose join failures, quality degradation, and participant-level issues on the call side. Pair that with your own pipeline instrumentation, timestamping each stage, so you can tell within seconds whether a latency spike came from STT, the LLM, or TTS. Alert on latency percentiles, not averages, because the worst 5 percent of utterances are what users remember.
Future Trends in Real Time AI Translation
Three shifts are coming fast. Speech-to-speech multimodal models, including OpenAI Realtime, Google Gemini Live, and AWS Nova Sonic, translate directly from audio in and audio out, collapsing the three-stage pipeline into one and cutting latency dramatically. Edge AI chips in phones and laptops are making on-device STT and TTS genuinely competitive with cloud, enabling fully private translated calls with no audio ever leaving the device. And AI agent frameworks, like VideoSDK's open-source Agent SDK, are turning translation from a bolted-on pipeline into a first-class room participant that can be configured, observed, and improved like any other agent. The teams that build on room-based, agent-capable infrastructure now will absorb these shifts as configuration changes rather than rewrites.
Definitions Glossary
Real Time AI Translation: Live conversion of spoken language during a call into another language, delivered as translated audio or subtitles with low enough latency to preserve conversational flow.
STT (Speech-to-Text): The process of converting spoken audio into text. In VideoSDK pipelines, streaming STT provides partial transcripts in real time rather than waiting for complete sentences.
TTS (Text-to-Speech): Neural synthesis of written text into natural-sounding speech, used to voice translated text. Streaming TTS starts speaking before a full sentence finishes translating.
Room: A VideoSDK meeting room that participants, including translation bots and AI agents, join to share audio and video streams, identified by a unique room ID.
Custom Track: A VideoSDK feature for publishing non-default media, such as translated audio or subtitle data, alongside standard camera and microphone streams.
Meeting Token: A JWT generated server-side with your API key and secret that authenticates a participant's access to a VideoSDK room.
Key Takeaways
- Real time AI translation for voice and video calling chains streaming STT, an LLM translation layer, and streaming TTS, and the total added latency must stay under roughly 1.5 seconds to keep conversation natural.
- The hardest engineering problem is not any single stage but routing translated audio back into the call, solved either with virtual audio drivers on desktop or a bot participant that joins the room and publishes translated streams.
- VideoSDK's room-based architecture, custom tracks, native real-time transcription, and token-based authentication provide a production-ready foundation for hosting translated streams across web and mobile.
- Subtitle overlay is often the better delivery mode than full audio translation: it is faster, cheaper, scales to thousands of viewers, and preserves the original speaker's tone.
- Ship with measurable KPIs, end-to-end latency, word error rate, translation quality, and user satisfaction, and monitor percentiles rather than averages.
Conclusion
Real time AI translation for voice and video calling has moved from demo to shippable product, and the developers winning here are the ones who treat it as a complete system: STT, translation, TTS, audio routing, and a call platform that stays stable under load. VideoSDK gives you the room architecture, custom tracks, native transcription, and AI agent tooling to assemble that system without building RTC infrastructure from scratch. Start with the VideoSDK quickstart, spin up a free account at app.videosdk.live, and wire your first translated call this week. What are you building with VideoSDK? Drop a comment, I'd love to hear which language pairs and use cases you are tackling.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ