


Live audio transcription is the process of converting spoken audio into written text in real time, typically within a few hundred milliseconds of the words being spoken. It powers live captions in video calls, real-time agent assistance in contact centers, and searchable archives for virtual events. VideoSDK provides built-in real-time transcription for its video and audio calling SDKs, so developers can add live captions to any app without wiring a separate speech-to-text pipeline.
Audio-first content has exploded. Virtual meetings, webinars, podcasts, live shopping events, and voice-based customer support now generate enormous volumes of spoken audio every day, and organizations increasingly expect that audio to be searchable, accessible, and analyzable the moment it happens. Post-call transcription is no longer enough for workflows that depend on immediate text: a contact center supervisor needs to see what a caller said seconds ago, a webinar host needs live captions for accessibility compliance, and a live shopping platform needs real-time moderation of spoken product claims.
That is where live audio transcription comes in. It converts speech to text as it is spoken, streaming partial and finalized results to your application with sub-second latency. In this guide, you will learn how real-time speech-to-text actually works under the hood, how to evaluate transcription engines on accuracy, latency, language support, and cost, and how to integrate live transcription into your product using SDKs and APIs, including VideoSDK's built-in transcription capabilities.
What is Live Audio Transcription?
Live audio transcription is defined as the real-time conversion of a continuous audio stream into text, delivered while the speaker is still talking. It differs from post-recording transcription, where a finished audio file is processed after the fact and results arrive minutes or hours later.
Three core concepts distinguish the live variant. First, streaming: audio is sent to the transcription engine in small chunks, often 100 milliseconds or less, rather than as a complete file. Second, latency: results must arrive fast enough to feel instantaneous, typically under a second for captioning use cases. Third, partial results: engines emit interim hypotheses that get refined as more context arrives, so the on-screen text may briefly change before a phrase is finalized. Real-time captioning is the most visible application, but the same pipeline feeds live agent assistance, real-time moderation, and instant analytics.
How Live Audio Transcription Works
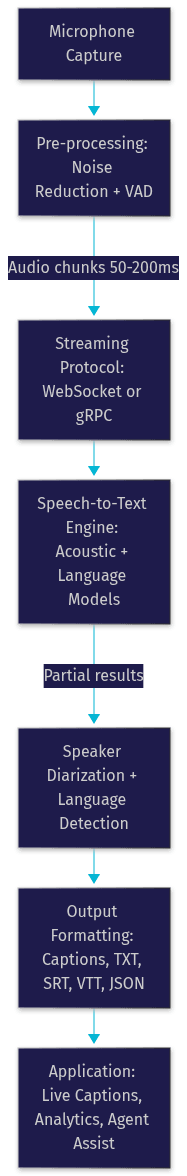
A live transcription pipeline is a chain of four stages: capturing and cleaning the audio, streaming it to an engine, running speech recognition, and formatting the output for display or downstream processing. Understanding each stage helps you diagnose whether poor transcription quality comes from your microphone setup, your network, or the engine itself.
Audio Capture and Pre-processing
Everything starts with the microphone. A high-quality condenser or headset microphone positioned close to the speaker produces a dramatically cleaner signal than a laptop's built-in mic picking up a conference room. Before audio reaches the transcription engine, most pipelines apply pre-processing: noise reduction suppresses background hum and keyboard clicks, and automatic gain control normalizes volume across speakers.
Voice activity detection, or VAD, is the gatekeeper of the pipeline. It distinguishes speech from silence and non-speech noise, so the engine only processes segments that actually contain words. Good VAD reduces cost, because you are not paying to transcribe silence, and improves accuracy, because the acoustic model is not confused by music or traffic. VideoSDK's AI agent pipeline, for example, includes built-in voice activity detection as a first-class component alongside turn detection.
Streaming Protocols (WebSocket, gRPC)
Once audio is captured, it must travel to the transcription engine continuously. Two protocols dominate. WebSocket streaming is the standard for browser and mobile clients: it provides a persistent, bidirectional connection over which the client pushes audio chunks and the server pushes back partial and final transcription results. gRPC streaming is favored for server-to-server pipelines, where a backend service forwards audio from a telephony system or media server to a transcription provider with lower overhead.
The key design decision is chunk size. Smaller chunks lower latency but increase per-request overhead; larger chunks batch more efficiently but delay results. Most production systems settle in the 50 to 200 millisecond range. The connection must also handle reconnects gracefully, because a dropped stream mid-meeting means lost transcript unless the client buffers and resumes.
Speech-to-Text Engines
Modern transcription engines are neural networks, not rule-based systems. An acoustic model maps raw audio features to phonetic probabilities, while a language model predicts which word sequences are likely given context. Today's leading engines combine both into end-to-end transformer-based models that consume audio directly and emit text, which is why accuracy has improved so sharply in recent years. According to Artificial Analysis's Speech Arena benchmarks, top-tier engines now achieve word error rates in the single digits on clean conversational audio.
Inference latency is the second dimension. Streaming engines emit partial results as partial hypotheses within a few hundred milliseconds, then finalize each segment once enough right-side context is available. Punctuation, capitalization, and inverse text normalization, converting spoken "five hundred dollars" into "$500", typically happen in a final formatting pass.
Speaker Diarization and Language Detection
Real conversations involve multiple people. Speaker diarization segments the transcript by who spoke, labeling each utterance as Speaker A, Speaker B, or a named participant when metadata is available. In a meeting context, the SDK can often supply speaker identity directly from the participant's stream, which is far more accurate than purely acoustic diarization. VideoSDK's architecture makes this natural: each participant's audio arrives as a distinct track, so per-speaker transcription is available without acoustic guessing.
Language detection handles multilingual streams. Engines either detect the dominant language at stream start or continuously, switching models mid-stream when a speaker changes language. For global webinars and support lines, continuous multilingual support matters more than headline accuracy on a single language.
The full pipeline looks like this:
Choosing the Right Live Audio Transcription Solution
No single engine wins on every dimension. The right choice depends on which trade-offs your use case can absorb, so evaluate solutions across four axes before committing.
Accuracy vs. Latency Trade-off
Accuracy and latency pull in opposite directions. An engine that waits for more audio context produces a more accurate final transcript but delays results; an engine that emits text immediately feels responsive but revises its output more often. For live captioning in a video call, prioritize latency under 500 milliseconds, because captions that lag a second behind the speaker frustrate viewers. For compliance recording or legal transcription, prioritize the lowest possible word error rate and accept a longer delay. Many engines let you tune this balance per stream.
Language Support and Custom Vocabulary
If your audience is global, check both the number of supported languages and how well each one performs, because engines rarely deliver equal accuracy across all languages. Custom vocabulary matters just as much: the ability to boost domain terms, product names, and acronyms can cut errors dramatically in specialized fields like medicine, law, or finance. Look for engines that accept custom word lists or allow model adaptation on your own audio.
Pricing Models (per minute, subscription, on-prem)
Most cloud transcription services charge per audio minute, with volume discounts at scale. Subscription plans suit products with predictable, steady usage. On-premise or self-hosted engines carry license or infrastructure costs but eliminate per-minute fees, which can be cheaper at very high volume. Free tiers are useful for prototyping: VideoSDK includes transcription with its free tier credit, so you can validate the full experience before committing to a paid plan.
Privacy and Security Considerations
Live transcription streams potentially sensitive conversations, so treat the transcript as protected data. Ask three questions of any provider: where is audio processed and stored, how long is it retained, and is it used to train the provider's models. For regulated industries, look for encryption in transit and at rest, regional data residency, GDPR-compliant processing agreements, and the option to run transcription on-premise. VideoSDK supports end-to-end encryption for calls and lets you control recording and transcription retention through its REST APIs.
Integration Options
Once you have chosen an engine, the integration surface determines how much work sits between you and a working feature. There are three main paths, plus one output consideration.
Browser-Based JavaScript SDKs
For web applications, browser-based SDKs are the fastest route to live captions. The SDK manages microphone access, audio chunking, the WebSocket connection to the engine, and rendering of partial results. Your application supplies the audio source, which can be the user's microphone or, more powerfully, the remote audio streams from other call participants. In a VideoSDK-based call, you can route each participant's audio track into the transcription pipeline and display captions per speaker, all from the client side, with the SDK handling reconnection and stream lifecycle. The VideoSDK JavaScript quickstart shows how to get a call running before layering transcription on top.
Server-Side APIs (REST, WebSocket)
For custom pipelines, server-side integration gives you full control. Your backend opens a WebSocket or gRPC stream to the transcription provider, forwards audio from your media server or telephony gateway, and receives transcript events that you can broadcast to clients, store in a database, or feed into analytics. This is the right pattern when transcription output must trigger server-side logic, such as real-time compliance alerts in a contact center or keyword detection in a live shopping stream. VideoSDK's REST APIs let you manage transcription sessions programmatically alongside room and participant management, and the Python SDK is designed for exactly these AI and ML pipeline integrations.
Edge and On-Device Solutions
Running transcription locally on the device eliminates network latency entirely and keeps audio private, since nothing leaves the hardware. Modern low-power neural chips in laptops and phones make on-device speech recognition viable for single-speaker use cases like voice assistants and offline note-taking. The trade-offs are model size, accuracy gaps compared to large cloud models, and limited multilingual support. Choose edge transcription when privacy is non-negotiable, connectivity is unreliable, or per-minute cloud costs at your volume become prohibitive.
Export Formats (TXT, SRT, VTT, JSON)
The transcript's destination shapes the format you need. Plain text suits notes and archives. SRT and VTT are subtitle formats with timestamps, required for adding captions to recorded video. JSON with word-level timestamps and speaker labels powers downstream processing: search indexing, sentiment analysis, highlight extraction, and compliance review. A good pipeline captures structured output from the start, because retrofitting timestamps onto a plain transcript later is painful.
Real-World Use Cases
Live audio transcription is not a niche feature. It is becoming table stakes across several product categories.
Virtual Meetings and Webinars
In virtual meetings, live captions serve two audiences: participants with hearing impairments, where captions are an accessibility requirement in many jurisdictions, and participants joining from noisy environments. Meeting platforms that embed transcription also unlock automated note-taking, since a timestamped, speaker-labeled transcript can be summarized into action items after the call. VideoSDK includes real-time transcription alongside post-call summaries in its calling SDKs, so a meeting app built on VideoSDK gets both without a separate vendor.
Live Events and Broadcasts
Broadcasts and streamed events need instant captions at scale, often across thousands of concurrent viewers. Here the pipeline typically runs server-side: audio from the broadcast feed is streamed to a transcription engine, and the resulting caption stream is delivered to viewers as an overlay, or exported via RTMP to platforms like YouTube alongside the video. Latency tolerance is slightly higher than in a two-way call, but accuracy expectations are not, because errors are visible to everyone simultaneously.
Podcasts and E-Learning
Podcasters use live transcription to generate show notes while recording, turning a spoken session into a searchable, SEO-friendly archive with zero extra production effort. In e-learning, real-time captions improve comprehension and retention for students, support non-native speakers, and create searchable transcripts of every lesson. Because educational content is evergreen, the structured JSON transcript becomes a durable asset: students can search a course library by any phrase a instructor ever said.
Customer Support Centers
Contact centers are the most demanding live transcription use case. Real-time transcripts feed agent-assist tools that surface relevant knowledge base articles mid-conversation, detect escalation signals, and monitor compliance phrases as they are spoken rather than in a post-call review. Per-speaker diarization is essential here, because agent and customer audio must be separated for analytics to be meaningful. Latency requirements are strict: an assist prompt that arrives after the call has moved on is worthless.
Best Practices for High-Quality Live Audio Transcription
Engine quality is only half the equation. The other half is what you feed the pipeline.
Start with microphone placement. A microphone within 30 centimeters of the speaker's mouth outperforms any amount of software cleanup applied to a distant room mic. Encourage headset use in meetings and position dedicated microphones for panels and events.
Next, control room acoustics. Hard surfaces cause echo and reverb that confuse acoustic models. Carpets, curtains, and acoustic panels measurably improve recognition, and echo cancellation in the calling SDK prevents the remote participant's audio from being re-transcribed through a local microphone.
Stabilize the network. Live transcription is a streaming workload, so jitter and packet loss cause gaps in the transcript. Prefer wired connections for hosts, and choose an SDK that buffers and resumes streams on reconnect rather than silently dropping audio.
Finally, plan for post-processing. Even the best engines make errors on names and jargon, so build a lightweight editing step into your workflow for published transcripts, and use custom vocabulary boosting for recurring domain terms. For recorded sessions, pair real-time captions with a post-call transcription pass, which can use a larger, more accurate model since latency no longer matters.
Future Trends
Three trends will reshape live transcription over the next few years. Multimodal models are merging speech recognition with vision, letting systems transcribe while also reading slides, whiteboards, and speaker expressions, which improves context and disambiguation. Real-time translation is converging with transcription, so a single pipeline will emit both a transcript in the original language and a live translation, collapsing today's two-step workflows into one. And low-power edge chips are closing the accuracy gap for on-device transcription, making private, offline, always-on transcription realistic on consumer hardware. For developers, the practical implication is to build pipelines that are engine-agnostic, because the best model for your use case will keep changing.
Definitions Glossary
Live audio transcription: The real-time conversion of a continuous audio stream into text, delivered while the speaker is still talking, typically with sub-second latency and partial results that refine over time.
Streaming transcription: A speech-to-text architecture in which audio is sent to the engine in small chunks over a persistent connection, such as a WebSocket, rather than as a complete recorded file.
Speaker diarization: The process of segmenting a transcript by who spoke, labeling each utterance with a speaker identity derived either acoustically or from per-participant audio tracks, as in VideoSDK rooms.
Voice activity detection (VAD): A pre-processing component that distinguishes speech from silence and background noise, so only segments containing speech are sent to the transcription engine.
Partial results: Interim transcription hypotheses emitted by a streaming engine before a phrase is finalized, which may be revised as more audio context arrives.
Key Takeaways
- Live audio transcription converts speech to text in real time through a pipeline of audio capture, pre-processing, streaming transport, and neural speech recognition, with results typically arriving in under a second.
- Accuracy and latency trade off against each other, so match the balance to your use case: prioritize latency for live captioning and accuracy for compliance and archival.
- Speaker diarization and language detection are essential for multi-speaker, multilingual streams, and per-participant audio tracks, as in VideoSDK rooms, make diarization far more reliable than acoustic guessing alone.
- Integration options span browser SDKs, server-side APIs, and on-device edge engines, and structured export formats like JSON with timestamps unlock downstream search and analytics.
- VideoSDK includes real-time transcription, post-call summaries, and per-participant audio tracks in its calling SDKs, so you can add live captions to a video or audio calling app without wiring a separate speech-to-text vendor.
Conclusion
Live audio transcription has moved from a nice-to-have to a core feature for meetings, events, education, and support products, and the technology behind it, streaming protocols, neural speech models, and speaker diarization, is now mature enough to build on confidently. Evaluate solutions against your specific constraints: latency budget, languages, privacy requirements, and cost per minute. If you are building a calling or streaming product, start with VideoSDK's built-in real-time transcription and quickstart guides, and explore the code samples for working examples. You can sign up free at app.videosdk.live/login and test transcription in your own app today. What are you building with live audio transcription? Drop a comment, I'd love to hear about your use case.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ