


Live audio to text transcription converts spoken audio into readable text in real time, typically within a few hundred milliseconds of it being spoken. Modern speech-to-text engines stream audio over WebRTC or WebSocket connections, apply acoustic and language models to produce interim and final transcripts, and often add speaker diarization and punctuation. VideoSDK brings this capability directly into its video and audio calling SDKs, so developers can add live captions to meetings without wiring a separate transcription pipeline.
Every second of spoken audio that goes uncaptioned is a second lost for someone who is deaf or hard of hearing, for a non-native speaker trying to follow a fast-moving meeting, and for any team that wants a searchable record of what was actually said. Live audio to text transcription has quietly become one of the most requested features in meeting apps, classroom tools, contact center platforms, and live streaming products.
The technology has matured fast. What used to require an on-premise speech stack and a phonetics lab now runs as a managed cloud service with sub-second latency and accuracy that rivals human transcriptionists on clean audio. But choosing and integrating a transcription solution still involves real trade-offs: latency versus accuracy, cloud convenience versus privacy, per-minute pricing versus flat-rate SDKs.
This guide covers how live audio to text transcription works under the hood, the performance factors that matter, a decision framework for picking a provider, and a complete implementation walkthrough in plain language. By the end, you will know exactly how to get from a microphone to live captions on screen.
What Is Live Audio to Text Transcription?
Live audio to text transcription is defined as the process of converting spoken audio into written text as the speech happens, rather than after the fact. Where traditional transcription works on a finished recording, live transcription operates on a continuous stream, producing interim results that refine themselves as more context arrives, followed by final, stable segments.
Live audio to text transcription works by capturing audio in small chunks, streaming those chunks to a speech recognition engine, and displaying the resulting text with minimal delay. In practice, developers encounter it as live captions in a video call, real-time subtitles on a live stream, or a rolling transcript panel in a meeting app. VideoSDK provides this through built-in real-time transcription available across its video and audio calling SDKs, alongside post-call transcription and summary features.
How Live Audio to Text Transcription Works
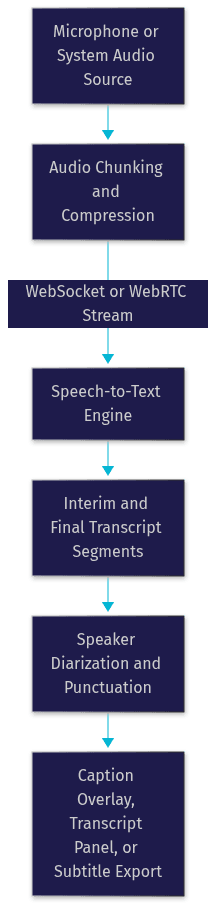
Every live transcription system, regardless of vendor, follows the same three-stage pipeline: capture the audio, recognize the speech, and polish the output. Understanding each stage helps you debug problems and make smarter integration choices.
Audio Capture and Streaming
The pipeline starts at the microphone or system audio source. The client application captures raw audio, typically at a 16 kHz sample rate optimized for speech, and compresses it into small chunks of a few hundred milliseconds each. Those chunks travel over a persistent connection, usually a WebSocket or a WebRTC media stream, to the recognition engine. A persistent, ordered connection matters because transcription depends on receiving audio chunks in sequence; dropped or reordered packets produce garbled text. This is one reason running transcription alongside an established real-time communication stack, like the one VideoSDK uses for its rooms, is more reliable than bolting a separate streaming layer onto an app.
Speech-to-Text Engine
Once audio chunks arrive, the speech-to-text engine does the heavy lifting. Cloud-based engines run large acoustic and language models on GPU infrastructure, which generally delivers the best accuracy and the broadest language coverage. Edge or on-device models run smaller compressed models directly on the phone or laptop, trading some accuracy for lower latency, offline capability, and stronger privacy. Most engines emit two kinds of results: interim hypotheses that appear within a few hundred milliseconds and may change, and final results that are stable once the engine has enough sentence context. Modern engines increasingly combine classic acoustic modeling with large language model post-processing, which noticeably improves punctuation, capitalization, and rare-word handling.
Post-Processing: Diarization, Punctuation, Formatting
Raw recognized words are not yet readable captions. Post-processing turns them into usable text. Punctuation and capitalization models insert sentence boundaries. Speaker diarization segments the stream by who is talking, labeling turns as Speaker One, Speaker Two, and so on. Formatting layers handle numbers, dates, and currency. Some pipelines also apply custom vocabulary boosting, so product names and industry jargon survive recognition. The finished segments are then pushed to the display layer, whether that is a caption overlay, a side panel, or a subtitle export.
Key Performance Factors in Live Audio to Text Transcription
Evaluating live transcription comes down to five measurable factors. Insisting on concrete numbers for each one, rather than vendor marketing language, is how you avoid a bad provider choice.
Latency
Latency is the delay between a word being spoken and it appearing on screen. For genuinely interactive captioning, you want end-to-end latency under one second, and the best streaming engines deliver final results in the 300 to 800 millisecond range. Anything above two seconds feels laggy in conversation and breaks the experience for live Q&A or interpreter-assisted settings. Interim results matter here: engines that show a fast rough hypothesis and refine it a beat later feel twice as responsive as their raw latency numbers suggest.
Accuracy
Accuracy is usually reported as word error rate, the percentage of words the engine gets wrong, substituted, or drops. On clean single-speaker audio, leading engines now achieve word error rates in the 5 to 10 percent range, which is comparable to professional human transcription. Accuracy degrades with background noise, distant microphones, overlapping speakers, and heavy accents. Microphone quality is the single biggest lever you control: a headset mic at close range can halve the error rate compared with a laptop mic across a conference table. Custom vocabulary support, where you supply domain terms and names, is another significant accuracy lever for specialized apps.
Language Support and Multilingual Capabilities
Provider language coverage varies from a handful of languages to over a hundred. Two capabilities matter beyond raw counts: automatic language detection, which identifies the spoken language on the fly, and code-switching support, which handles speakers who mix languages mid-sentence. If your product serves a global audience, test the specific languages your users actually speak, because headline language counts often include low-quality tiers.
Speaker Identification
Speaker diarization answers "who said what" by clustering audio segments by voice characteristics. It works well when speakers take clean turns and each has a few seconds of speech, but it struggles with rapid interruptions and crosstalk. In a meeting context, a smarter approach is to use the communication platform's own participant identity: because VideoSDK knows which participant's audio track is active at any moment, its transcription can attribute text to named participants rather than anonymous speaker clusters, which is far more reliable than audio-only diarization.
Privacy and Security
Transcription data is sensitive by definition: it can contain personal, medical, or financial information. Ask every provider where audio is processed, how long it is retained, and whether transcripts are used to train their models. For regulated industries, look for on-device or edge processing options, encryption in transit and at rest, data residency controls, and clear no-training guarantees. VideoSDK supports end-to-end encrypted calls, and its transcription features are documented so you can verify exactly how session data is handled before you commit.
Choosing the Right Live Transcription Solution
With the performance factors in hand, you can turn provider selection into a structured decision rather than a guess.
Decision-Tree Criteria
Start with your non-negotiables, then let the remaining criteria narrow the field. The six criteria that matter most are cost structure, latency requirements, accuracy on your actual audio, language coverage, privacy constraints, and integration flexibility.
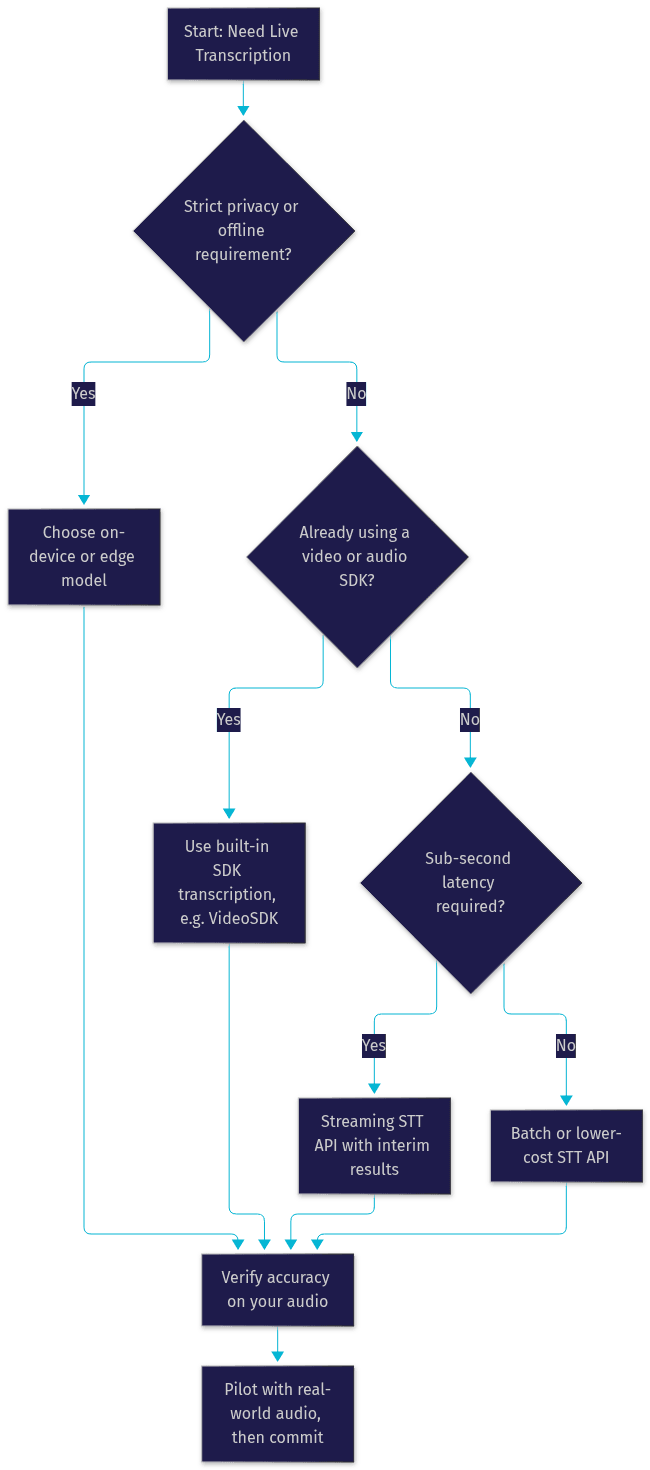
The most common mistake is choosing on price alone. A cheap per-minute API that produces inaccurate captions costs more in user trust than a pricier provider saves in fees. Always pilot with your own audio before committing.
Comparison of Leading Providers
A high-level scan of the market, focused on the criteria above:
- VideoSDK: best when transcription is part of a larger real-time app. Live transcription is built into the same SDK that powers video calls, audio rooms, and interactive live streaming, with participant-attributed transcripts, post-call summaries, and recording integration. Strong fit for meetings, classrooms, and live events.
- Deepgram: strong developer-focused streaming API with low latency and good accuracy, popular for custom pipelines. Best for teams building their own audio transport.
- AssemblyAI: broad feature set including diarization and summarization, with a clean API. Good for post-call processing as well as streaming.
- OpenAI Whisper-based services: excellent accuracy and wide language coverage, but the base model is batch-oriented; real-time variants trade some accuracy for speed.
- Google Cloud Speech-to-Text and Azure Speech: enterprise-grade coverage, hundreds of languages, and strong compliance tooling. Best for large organizations already in those clouds.
- Otter.ai and Rev: polished end-user products rather than developer APIs. Good for individuals and teams who want transcription without building anything.
If your product already includes live audio or video communication, the built-in route usually wins on integration speed and cost predictability. If you are building a standalone transcription tool, a dedicated speech API is the better fit.
Implementation Guide: From Concept to Live Captions
Here is the full path from an idea to working live captions, explained in plain language with no code required.
Step 1: Define the Use-Case
Start by naming the environment: a one-on-one meeting app, a webinar with thousands of viewers, a classroom, a contact center, or a live podcast. The use-case determines your latency budget, your speaker-attribution needs, and your display format. A webinar can tolerate captions arriving a second late; a live Q&A cannot. A contact center needs per-agent attribution; a lecture does not. Write these requirements down before looking at any provider.
Step 2: Select an Integration Method
There are three common routes. The first is transcription built into your real-time communication SDK: if your app uses VideoSDK rooms, you enable transcription on the session and receive caption events through the same SDK, with no separate audio pipeline to build. The second is a standalone streaming speech API over a WebSocket, where your app captures audio, streams it to the provider, and renders the returned text. The third is a REST-based flow, where audio is uploaded in near-real-time segments and transcripts come back in batches; this is simpler but laggier. For most product teams, the SDK route is fastest to ship and the WebSocket route offers the most control.
Step 3: Prepare Audio Input
Garbage in, garbled captions out. Ask speakers to use headsets or positioned microphones rather than laptop mics across a table. Reduce background noise at the source: HVAC hum, keyboard clatter, and side conversations all raise the word error rate. On the network side, a stable connection with low jitter matters more than raw bandwidth, because speech codecs adapt to low bandwidth but cannot recover from disordered packets. If you control the room, soft furnishings and echo reduction help noticeably.
Step 4: Configure the Service
Before going live, set the spoken language, or enable auto-detection if your audience is multilingual. Enable speaker diarization if you need who-said-what attribution, and prefer participant-based attribution when your platform provides it. Configure custom vocabulary with the product names, people, and jargon your users will say. Set your privacy options: retention period, whether transcripts feed model training, and data residency if you operate under regional rules. VideoSDK's transcription configuration is documented alongside its recording and transcription guides, so every setting can be verified before deployment.
Step 5: Display Captions
The display layer is where users judge the whole system. Common patterns include a bottom-of-screen overlay that shows the last one or two lines and scrolls upward, a persistent side panel with the full rolling transcript, and speaker-labeled chat-style transcripts for meetings. Show interim results in a lighter style and swap them for final text as it stabilizes, so the captions feel alive. For streaming products, captions can ride alongside interactive live streaming output, and many teams also export standard subtitle files for post-event playback.
Step 6: Post-Session Actions
A live transcript is most valuable after the session ends. Save the final transcript with speaker labels and timestamps, allow light human editing for the segments that matter, and export to the formats your workflow needs: plain text for archives, subtitle formats for video, and structured text for search. This is also where post-call summarization shines: VideoSDK can generate a post-call summary from the same session, turning an hour of transcript into a paragraph of decisions and action items without any extra pipeline.
Best Practices for High-Quality Live Transcription
A handful of habits separate crisp captions from frustrating ones. Use close-range microphones whenever you can influence the hardware. Encourage speakers to take turns rather than talk over each other, since overlapping speech is the hardest input for both recognition and diarization. Keep the audio path short: capture, compress, and send, without resampling the audio multiple times on the client.
On the engineering side, always handle the difference between interim and final results in your display logic, and expect occasional corrections as context arrives. Build reconnection handling into your streaming layer so a brief network blip does not silently kill captions for the rest of the call. Monitor transcription latency and error signals in production rather than discovering problems from user complaints. Finally, run a short pilot with real users and real accents before a public launch; lab audio and live audio are different worlds.
Real-World Use Cases for Live Audio to Text Transcription
Education: live lectures get real-time captions that help deaf students, non-native speakers, and anyone reviewing the material later; recorded transcripts become study notes automatically.
Accessibility: conferences, town halls, and religious services provide inclusive captions without hiring live stenographers for every event.
Customer support: contact center platforms transcribe calls in real time, surfacing the conversation to supervisors and feeding post-call analytics and compliance archives.
Content creation: live podcasts and streams generate transcripts that become show notes, subtitles, and searchable archives with no extra production step.
Multilingual webinars: auto-detected language plus live captions lets a global audience follow a session in the speaker's language, with some platforms layering live translation on top.
Future Trends in Live Audio to Text Transcription
Three shifts are reshaping the field. First, edge AI models are getting good enough that on-device transcription is becoming a realistic default for privacy-sensitive apps, with small distilled models running comfortably on modern phones and laptops. Second, real-time summarization is merging with transcription: instead of a raw transcript, users increasingly expect live meeting notes, action items, and topic highlights generated as the conversation unfolds, powered by large language models sitting directly behind the speech engine. Third, multimodal integration means transcription is becoming one input among several, combined with screen content, chat, and video context to produce richer understanding of a session. VideoSDK's pairing of real-time transcription with post-call summaries and its AI agent capabilities is an early example of where this convergence is heading.
Definitions Glossary
Live audio to text transcription: The process of converting spoken audio into written text in real time as the speech happens, producing interim and final transcript segments with minimal delay.
Word error rate (WER): The standard accuracy metric for speech recognition, measuring the percentage of words that are substituted, deleted, or inserted incorrectly relative to a reference transcript.
Speaker diarization: The process of segmenting an audio stream by speaker, labeling which portions of the transcript belong to which voice, typically without knowing the speakers' identities in advance.
Interim results: Early, provisional transcript hypotheses returned by a streaming speech engine that may be revised as more sentence context becomes available, displayed to keep captions responsive.
Real-time transcription SDK: A software development kit, such as VideoSDK's, that delivers live caption events through the same integration that powers real-time audio and video, with transcripts attributed to named participants.
Key Takeaways
- Live audio to text transcription converts speech to text within a few hundred milliseconds, and sub-second latency is the threshold that separates interactive captions from laggy ones.
- Accuracy depends more on microphone quality and speaker discipline than on engine choice; a close-range headset can halve the word error rate of a distant laptop mic.
- Choose a provider using six criteria: cost, latency, accuracy on your own audio, language coverage, privacy constraints, and integration flexibility, and always pilot before committing.
- If your app already uses a real-time communication SDK, built-in transcription, such as VideoSDK's, is usually faster to ship and attributes text to named participants instead of anonymous speaker clusters.
- The field is converging on transcription plus real-time summarization, with edge models and multimodal context making live captions smarter and more private.
Conclusion
Live audio to text transcription has moved from a nice-to-have accessibility feature to a core expectation across meetings, classrooms, support lines, and live streams. The technology is mature, the integration paths are clear, and the decision comes down to the criteria in this guide: latency, accuracy, languages, privacy, and how cleanly the solution fits your existing stack. If you are building a real-time app, the fastest way to evaluate is to try it yourself: create a free account at app.videosdk.live, enable transcription on a test session, and judge the captions against your own audio. What are you building with live transcription? Drop a comment, I'd love to hear what kind of live captioning use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ