


A voice to text LLM model is a unified neural architecture that converts spoken audio directly into text or structured responses by combining an acoustic encoder with a large language model backbone, eliminating the intermediate transcription step required by traditional ASR pipelines. VideoSDK extends this paradigm by letting developers pipe real-time audio streams from any device into AI agent pipelines powered by these models, enabling sub-second conversational voice experiences. To start building, explore the VideoSDK AI Agents documentation.
The surge in voice to text LLM models is reshaping how developers build conversational interfaces. Instead of chaining a speech-to-text engine, a text-based LLM, and a text-to-speech module in a fragile pipeline, teams are now adopting end-to-end models that process audio natively and generate text or speech responses with lower latency and richer context retention.
This shift matters because every hop in a traditional pipeline adds latency, loses paralinguistic information like emotion and emphasis, and increases integration complexity. For real-time applications such as AI voice agents, live transcription, and interactive voice response systems, those costs are unacceptable. By 2026, open-source voice to text LLM models have matured to the point where they rival or exceed classic ASR systems on accuracy while offering the semantic understanding of a full LLM.
By the end of this article, you will understand the architecture behind these models, the leading open-source options available today, how to evaluate their performance, and the deployment strategies that make them production-ready.
What Is a Voice to Text LLM Model?
A voice to text LLM model is defined as a neural network architecture that ingests raw or preprocessed audio and produces text output by fusing an acoustic encoder with a large language model decoder in a single end-to-end pipeline. Unlike traditional automatic speech recognition systems that treat transcription and language understanding as separate tasks, a voice to text LLM model handles both within a shared parameter space.
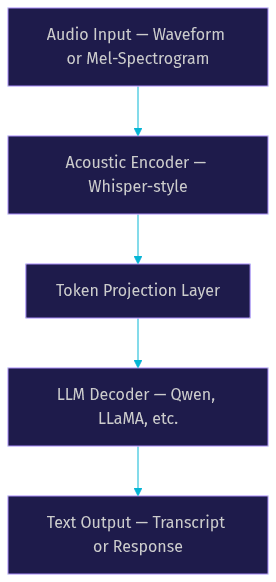
The model works by first passing audio through an acoustic encoder, typically derived from a Whisper-style architecture, which converts the waveform into a sequence of continuous or discrete acoustic tokens. These tokens are then projected into the embedding space of the LLM backbone, where the language model processes them alongside any text instructions or conversation history. The LLM decoder generates the final text output, whether that is a transcript, a summary, or a conversational response.
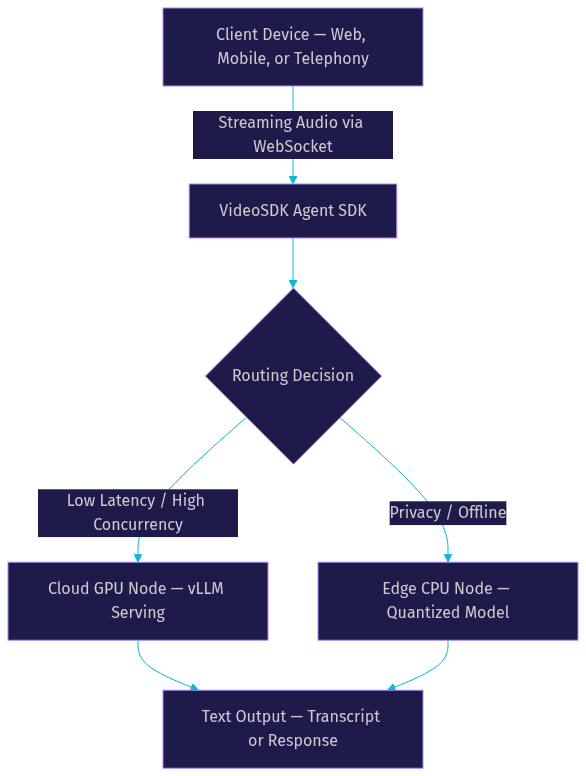
VideoSDK provides infrastructure that connects these models to real-time communication channels through its AI Voice Agent SDK, allowing developers to route live audio from web, mobile, or telephony endpoints directly into a voice to text LLM model pipeline.
How Voice to Text LLMs Differ From Traditional ASR
A voice to text LLM model eliminates the transcription hop that defines classic ASR pipelines, reducing end-to-end latency and preserving paralinguistic cues that traditional systems discard.
In a traditional pipeline, audio goes through an ASR model that outputs text, then that text is fed into an LLM for comprehension or response generation. Each stage operates independently, meaning the ASR model cannot leverage the LLM's language priors to improve transcription accuracy, and the LLM cannot access acoustic features like tone, pacing, or emphasis. This separation creates a compounding error problem where ASR mistakes propagate into the LLM's reasoning.
A voice to text LLM model collapses these stages. The acoustic encoder and LLM backbone are trained jointly or fine-tuned together, allowing the language model to use its semantic knowledge to guide transcription decisions. This joint training means the model can disambiguate homophones using conversational context, handle code-switching between languages more naturally, and produce outputs that reflect not just what was said but how it was said.
The latency gains are significant. By removing the intermediate text generation and re-encoding step, end-to-end models can achieve token-level latency that is measurably lower than cascaded pipelines, which is critical for conversational voice agents where users expect near-instant responses.
Core Architectural Components of a Voice to Text LLM Model
Every voice to text LLM model shares a common architectural blueprint consisting of an acoustic encoder, a projection layer, an LLM backbone, and an inference engine. Understanding these components is essential for evaluating model trade-offs and planning deployment.
Acoustic Encoder
The acoustic encoder is responsible for transforming raw audio waveforms into a structured representation that the LLM can consume. Most contemporary voice to text LLM models use a Whisper-style encoder as their acoustic front-end because it is pre-trained on hundreds of thousands of hours of multilingual speech data. The encoder processes mel-spectrogram features extracted from the audio and outputs a sequence of hidden states that capture phonetic and acoustic information at the frame level.
LLM Backbone
The LLM backbone is the language model that processes the acoustic tokens and generates text output. Popular backbones include Qwen, LLaMA, and Gemini-family models, chosen for their strong reasoning capabilities and open-weight availability. The backbone size directly influences both the model's understanding capacity and its hardware requirements. A 7-billion-parameter backbone provides a strong balance of quality and deployability, while smaller 1-billion to 3-billion parameter backbones are preferred for edge and CPU-based deployments.
Continuous Tokenizers
Between the acoustic encoder and the LLM backbone sits a tokenizer or projection layer that aligns the audio representation with the LLM's embedding space. Many modern architectures use continuous speech tokenizers that produce token streams at approximately 7.5 Hz, meaning one token represents roughly 133 milliseconds of audio. This rate balances granularity with computational efficiency, giving the LLM enough acoustic detail to transcribe accurately without overwhelming its context window.
Inference Engine (vLLM)
Serving a voice to text LLM model efficiently requires an inference engine that can handle concurrent audio streams with low memory overhead. vLLM has emerged as the dominant serving engine for these models because of its paged attention mechanism, which reduces GPU memory waste by managing the KV cache in non-contiguous blocks. vLLM also supports tensor parallelism for multi-GPU deployments and continuous batching, allowing multiple audio streams to be processed simultaneously without queuing delays.
Survey of Prominent Open-Source Voice to Text LLM Models
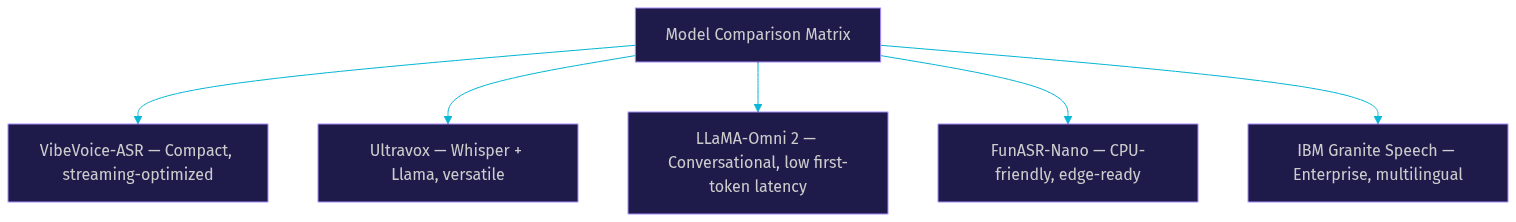
The open-source landscape for voice to text LLM models has expanded rapidly. Here are five models that represent the current state of the art, each with distinct architectural choices and deployment profiles.
VibeVoice-ASR
VibeVoice-ASR is an open-source voice to text LLM model designed for high-accuracy streaming transcription. It pairs a Whisper encoder with a compact LLM backbone and focuses on real-time factor optimization, making it suitable for live captioning and meeting transcription. Its architecture prioritizes low token-level latency, which makes it a strong candidate for conversational applications where responsiveness matters more than peak throughput.
Ultravox
Ultravox is a multimodal speech-LLM that connects a Whisper encoder to a Llama backbone through a learned projection layer. It supports both transcription and conversational response generation, making it versatile for voice agent use cases. Ultravox is notable for its efficient training methodology, which requires relatively small amounts of paired audio-text data to achieve strong performance, and it has gained traction in the open-source community for its clean architecture and reproducible training pipeline.
LLaMA-Omni 2
LLaMA-Omni 2 extends the original LLaMA-Omni architecture with improved streaming capabilities and support for both text and speech output. It is designed specifically for real-time conversational voice agents, with an architecture that minimizes the gap between audio input and first token output. The model supports instruction-following, meaning developers can prompt it with task descriptions that shape its transcription or response behavior.
FunASR-Nano
FunASR-Nano, part of the FunASR family developed by Alibaba, is optimized for resource-constrained environments. It uses a smaller backbone and aggressive quantization to run on CPU-only hardware while maintaining competitive word error rates. This makes it attractive for edge deployment scenarios where GPU access is limited or where privacy requirements demand on-device processing.
IBM Granite Speech
IBM Granite Speech is part of the Granite model family and brings enterprise-grade speech understanding with a focus on multilingual coverage and compliance. It supports multiple languages out of the box and is designed to integrate into enterprise workflows where transcription accuracy, data governance, and auditability are non-negotiable. Its architecture follows the encoder-projection-LLM pattern but includes additional fine-tuning for business and technical vocabulary.
Performance Considerations for Voice to Text LLM Models
Evaluating a voice to text LLM model requires looking beyond raw accuracy. Latency, multilingual coverage, and hardware efficiency all determine whether a model is viable for your specific application.
Latency and Real-Time Factor
Latency in voice to text LLM models is measured in two ways: token-level latency, which is the time from audio input to first output token, and real-time factor (RTF), which is the ratio of processing time to audio duration. An RTF below 1.0 means the model processes audio faster than it arrives, enabling true streaming. For conversational voice agents, token-level latency under 300 milliseconds is the threshold where users perceive the interaction as natural. Models served through vLLM with continuous batching can sustain sub-1.0 RTF across multiple concurrent streams, but this depends heavily on the backbone size and available GPU memory.
Accuracy (WER and BLEU)
Word error rate (WER) remains the primary accuracy metric for transcription tasks. Leading open-source voice to text LLM models achieve WER scores in the range of 7 to 12 percent on standard English benchmarks like LibriSpeech and CommonVoice, with some models approaching parity with commercial offerings. For translation or summarization tasks, BLEU and ROUGE scores provide additional signal. It is important to evaluate models on domain-specific audio, as benchmarks recorded in clean studio conditions often overstate real-world performance where background noise, accents, and overlapping speech are present.
Multilingual Coverage
Multilingual ASR capability varies significantly across models. IBM Granite Speech and FunASR-Nano offer broad language coverage out of the box, while models like Ultravox and LLaMA-Omni 2 are primarily English-focused with limited multilingual fine-tuning. If your application serves a global audience, prioritize models that publish per-language WER benchmarks and support code-switching, where speakers alternate between languages within a single utterance.
Hardware and Quantization Trade-offs
The backbone size of a voice to text LLM model directly determines its hardware footprint. A 7-billion-parameter model typically requires 14 to 16 GB of GPU memory in half-precision, while 4-bit quantization can reduce this to roughly 5 to 6 GB, making it feasible on consumer-grade GPUs. CPU inference is possible with aggressive quantization and smaller backbones, but RTF will generally exceed 1.0 unless the model is heavily optimized for CPU instruction sets like AVX-512.
Deployment Strategies for Voice to Text LLM Models
Choosing the right deployment strategy depends on your latency requirements, hardware budget, and whether you need streaming or batch processing.
CPU-Optimized Quantized Inference
For applications where GPU hardware is unavailable or cost-prohibitive, CPU-optimized inference with quantized models is a viable path. Models like FunASR-Nano are specifically designed for this scenario, using INT8 or INT4 quantization to reduce memory footprint and leverage CPU vector instructions. While CPU inference cannot match GPU throughput, it is sufficient for low-concurrency workloads such as on-device transcription or batch processing of recorded audio. The key trade-off is that RTF will typically be higher, and concurrent stream capacity will be limited to one or two simultaneous audio streams per CPU core.
GPU-Accelerated vLLM Serving
For production workloads with multiple concurrent users, GPU-accelerated serving through vLLM is the recommended approach. vLLM's paged attention and continuous batching allow a single GPU to handle dozens of simultaneous audio streams by efficiently sharing the KV cache across requests. Tensor parallelism enables multi-GPU configurations for larger backbone sizes, and vLLM's OpenAI-compatible API simplifies integration with existing application infrastructure. This is the deployment pattern that VideoSDK's AI Agent Cloud uses to serve voice agent pipelines at scale.
Streaming via WebSocket or SDK
Real-time applications require streaming audio input and streaming text output, which means the deployment must support WebSocket connections or SDK-based audio streaming. The client sends audio chunks as they are captured, and the server returns partial transcripts or response tokens as they are generated. VideoSDK's agent SDK handles this streaming pipeline natively, managing audio chunking, turn detection, and voice activity detection so that the voice to text LLM model receives clean audio segments without silence padding or truncated speech.
Edge-Device Scenarios
Edge deployment is emerging as a viable option for privacy-sensitive applications. With quantized models under 3 billion parameters, it is possible to run a voice to text LLM model on devices like Raspberry Pi 5 or industrial edge gateways. This eliminates network latency entirely and keeps audio data on-device, which is critical for healthcare, legal, and defense applications where data residency requirements prohibit cloud processing.
Emerging Trends and Research Directions in Voice to Text LLM Models
The field is moving quickly, and several research directions are shaping the next generation of voice to text LLM models.
Continuous Speech Tokenizers
Continuous speech tokenizers are replacing discrete token approaches because they preserve more acoustic information without increasing the token sequence length. By projecting the encoder's hidden states directly into the LLM's embedding space as continuous vectors, models achieve better WER scores and lower latency. Research is ongoing into adaptive tokenization rates that dynamically adjust the number of tokens per second based on speech density, which could further reduce computational cost during silence or pauses.
Instruction-Tuned Voice Agents
Instruction tuning for voice to text LLM models is expanding beyond simple transcription. Models are being fine-tuned to follow complex voice instructions, such as summarizing a meeting in a specific format, extracting action items, or responding in a particular persona. This trend is driven by the convergence of voice agent platforms and transcription services into unified voice AI systems. VideoSDK's Conversational Graph complements this by providing a deterministic flow layer that sits on top of instruction-tuned models, ensuring business rules govern conversation branching rather than LLM judgment.
Privacy-Preserving On-Device Models
As quantization techniques improve and edge hardware becomes more capable, on-device voice to text LLM models are becoming practical. Federated learning and differential privacy techniques are being explored to fine-tune these models on user data without transmitting audio to central servers. This direction is particularly relevant for enterprise deployments where GDPR, HIPAA, or similar regulations restrict audio data transmission.
Hybrid ASR-LLM Pipelines
While end-to-end voice to text LLM models are the frontier, hybrid pipelines that combine a specialized ASR model with an LLM for post-processing remain relevant for certain use cases. These pipelines can leverage the superior WER of dedicated ASR models on accented or noisy speech while still benefiting from the LLM's semantic capabilities for error correction, punctuation restoration, and context-aware formatting. The choice between end-to-end and hybrid depends on whether your priority is minimum latency or maximum transcription accuracy in adverse conditions.
Definitions Glossary
Voice to Text LLM Model: A neural architecture that combines an acoustic encoder with a large language model backbone to convert spoken audio into text or structured responses in a single end-to-end pipeline.
Acoustic Encoder: The component of a voice to text LLM model that transforms raw audio into a sequence of hidden states or tokens, typically derived from a Whisper-style architecture.
Real-Time Factor (RTF): The ratio of processing time to audio duration, where a value below 1.0 indicates the model processes audio faster than it arrives, enabling true streaming transcription.
Continuous Speech Tokenizer: A projection layer that converts acoustic encoder outputs into continuous vectors in the LLM's embedding space, typically operating at a rate of 7.5 tokens per second.
vLLM: A high-throughput inference engine that uses paged attention and continuous batching to serve large language models efficiently, widely adopted for serving voice to text LLM models in production.
Key Takeaways
- A voice to text LLM model unifies acoustic encoding and language understanding into a single architecture, eliminating the intermediate transcription step that adds latency and loses paralinguistic information in traditional ASR pipelines.
- Open-source models like Ultravox, LLaMA-Omni 2, and FunASR-Nano cover a spectrum of use cases from high-accuracy cloud transcription to privacy-preserving edge deployment.
- Performance evaluation should consider token-level latency, real-time factor, word error rate, and multilingual coverage rather than focusing on any single metric.
- Deployment strategy depends on hardware availability and latency requirements, with vLLM serving on GPUs for high-concurrency workloads and quantized inference on CPUs for edge or budget-constrained scenarios.
- VideoSDK's AI Voice Agent SDK and Conversational Graph provide the infrastructure layer that connects these models to real-time audio streams from web, mobile, and telephony endpoints, handling streaming, turn detection, and conversation orchestration.
Conclusion
Voice to text LLM models represent a fundamental shift from cascaded ASR pipelines to unified architectures that process speech with the full semantic power of large language models. Whether you are building a conversational voice agent, a real-time transcription service, or a privacy-preserving on-device assistant, the open-source landscape in 2026 offers models that are production-ready and deployable across GPU and CPU environments. The key is matching the model's backbone size, tokenizer design, and serving infrastructure to your specific latency, accuracy, and hardware constraints. To start integrating these models into a real-time voice pipeline, explore the VideoSDK AI Agents documentation or join the VideoSDK Discord community to connect with other developers building voice AI applications. What are you building with voice to text LLM models? Drop a comment, I would love to hear what kind of voice AI use case you are working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ