


Text to speech (TTS) is the process of converting written text into synthesized spoken audio using a speech synthesis API or SDK. Modern neural TTS services such as Google Cloud Text-to-Speech, OpenAI's Audio API, and Azure Speech Service let developers generate natural-sounding voices in dozens of languages within seconds. This guide walks through the full workflow, from choosing a service and preparing your text to optimizing voice quality and shipping real-time or batch synthesis in production.
Voice is becoming the default interface. Voice assistants, audiobook platforms, accessibility tools, and interactive voice response systems all depend on one core capability: turning text into natural-sounding speech. If you are building any of these, you need a reliable way to do text to speech at scale.
The good news is that you no longer need to train acoustic models yourself. Cloud text-to-speech APIs handle the machine learning heavy lifting, and you focus on text preparation, voice selection, and integration. The bad news is that the details matter. A poorly prepared input, a mismatched voice, or a naive latency assumption can make an otherwise solid product feel robotic and broken.
By the end of this article, you will understand the full TTS pipeline, know how to choose between the leading providers, and be able to run both simple synthesis and production-grade streaming workflows.
What Is Text to Speech?
Text to speech is defined as speech synthesis: the automatic conversion of written language into spoken audio. A TTS system takes a string of text as input and returns an audio file or audio stream as output, typically encoded as MP3, WAV, or OGG.
A modern TTS system works by running your text through a multi-stage pipeline. First, linguistic analysis normalizes the text, expanding numbers, dates, and abbreviations into speakable words. Second, an acoustic model, almost always a neural network in 2026, converts the normalized text into a spectrogram or raw audio waveform. Third, a vocoder shapes that output into the final audio encoding you requested.
Neural voices have largely replaced older concatenative approaches, which stitched together recorded speech fragments. Neural models generate speech directly, which produces far more natural prosody, the rhythm, stress, and intonation of human speech.
Here is what the synthesis flow looks like end to end:
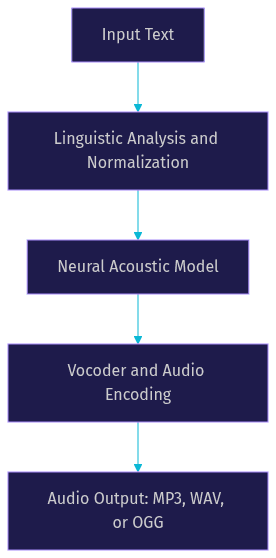
For developers, the practical takeaway is simple: you send text, the cloud service runs this pipeline, and you receive base64-encoded audio you can play or store. Everything between those two points is the provider's problem, but your input quality determines your output quality.
Core Components of a TTS System
Every TTS integration touches three components, and understanding each one prevents most integration mistakes.
Voice Models
A voice model is the trained neural network that defines how your audio sounds. Neural voices now dominate the market, offering natural prosody and consistent quality across long passages. When evaluating voices, check language and accent coverage: Google Cloud Text-to-Speech offers more than 100 voices across dozens of languages, and Azure Speech Service offers an even broader multilingual catalog with regional accent variants. Voice count matters less than fit, though. A single well-matched voice beats a catalog of voices that do not match your product's tone.
Input Formats
Your input can be plain text or SSML, the Speech Synthesis Markup Language. Plain text is fine for simple use cases. SSML gives you explicit control over pauses, emphasis, pronunciation, pitch, and speaking rate through inline tags. The trade-off is verbosity and a stricter syntax that the API will reject if malformed. Most production systems use SSML for user-facing audio and plain text for internal or bulk generation.
Output Formats
The audio encoding you choose affects quality, file size, and compatibility. MP3 is the safe default for web playback and storage. WAV and LINEAR16 deliver uncompressed audio for telephony integrations and further processing, at the cost of much larger files. OGG Opus offers excellent compression for mobile apps. Also consider sample rate: 24 kHz is typical for neural voices, while telephony systems often need 8 kHz. Mismatched sample rates cause audio that plays too fast, too slow, or not at all.
Choosing a TTS Service
The three leading cloud providers in 2026 are Google Cloud Text-to-Speech, OpenAI's Audio API, and Azure Speech Service. Each has distinct strengths, and the right choice depends on your use case, budget, and latency requirements.
Google Cloud Text-to-Speech offers the broadest voice catalog with strong multilingual support and mature SSML handling. It suits content platforms, e-learning, and any application generating audio in many languages. Pricing is usage-based per character of input text.
OpenAI's Audio API delivers some of the most natural conversational voices available, which makes it a strong fit for voice assistants and dialogue-heavy applications. Its voice count is smaller than Google's or Azure's, but the quality per voice is exceptional for expressive, human-like delivery.
Azure Speech Service stands out for enterprise features: custom voice creation, extensive regional accent coverage, and tight integration with telephony and interactive voice response scenarios. If you need a branded custom voice or deep PBX integration, Azure is often the pragmatic choice.
A quick comparison:
| Dimension | Google Cloud TTS | OpenAI Audio API | Azure Speech Service |
|---|---|---|---|
| Voice catalog | 100+ voices, many languages | Smaller set, highly expressive | Very broad, strong accent variants |
| Best for | Multilingual content at scale | Conversational assistants | Enterprise and telephony |
| Custom voice | Limited | Not a core offering | Yes, with approval process |
| Real-time streaming | Yes | Yes | Yes, strong telephony support |
| Pricing model | Per input character | Per input character | Per input character |
In practice, teams building voice assistants on real-time communication platforms often pair a TTS provider with a full RTC stack. VideoSDK's AI agent pipeline, for example, connects STT, LLM, and TTS providers into a live voice session, so the synthesized speech streams directly into a room alongside human participants. You can explore that architecture in the VideoSDK AI Agents documentation.
Preparing Text for Synthesis
Garbage in, robotic audio out. Text preparation is the highest-leverage step in the entire TTS workflow, and it is the step most teams skip.
Start with normalization. Raw text contains elements a TTS engine may mispronounce: numbers, dates, currency amounts, acronyms, and abbreviations. Most engines handle common cases, but ambiguous ones fail silently. "Dr. Smith lives on 2nd St." can be spoken several ways, and the engine will pick one, possibly the wrong one. SSML lets you resolve ambiguity explicitly with say-as tags that tell the engine how to interpret dates, ordinals, and telephone numbers.
Next, control pacing. SSML break tags insert explicit pauses at natural boundaries, such as between list items or after a question. Without them, long passages sound rushed and breathless.
For emphasis, prosody tags adjust pitch, rate, and volume on specific phrases. Use them sparingly. Over-tagged SSML sounds artificial, and in practice, less markup with a good neural voice often beats heavy markup with a mediocre one.
For multilingual content, keep each synthesis request in a single language where possible. Mixing languages in one request forces the engine to guess pronunciation rules, and the results degrade. Generate per-language segments and stitch the audio, or use a voice that explicitly supports multilingual synthesis.
Step-by-Step: How to Do Text to Speech End to End
This section walks through the complete workflow, from an empty cloud project to playable audio. No single step is hard, but the order matters, and skipping authentication planning is the most common failure point.
Step 1: Set Up a Cloud Project and Enable the TTS API
Create a project in your chosen provider's console and enable the text-to-speech API for that project. This activates billing against the project and gives you a place to manage credentials, quotas, and usage monitoring. Expect the API to appear in your enabled services list within seconds.
Step 2: Authenticate Securely
Never embed long-lived credentials in a client application. Generate a service account or API key, store it in your server's secret manager or environment configuration, and route all synthesis requests through your own backend. Your backend calls the TTS provider, then returns audio to your frontend. This pattern protects your credentials and lets you add caching and rate limiting later. For a deeper treatment of token-based authentication patterns in real-time applications, see how VideoSDK handles authentication and tokens.
Step 3: Choose a Voice and Language
Select a voice that matches your content's tone and your audience's locale. Test the same passage with three or four candidate voices before committing. Voice choice is subjective, and stakeholders will have opinions, so make the decision early with short samples rather than late with a full production batch.
Step 4: Craft the Input
Decide between plain text and SSML. For anything user-facing, use SSML to control pauses, number pronunciation, and emphasis. Validate your SSML structure before sending it, because malformed markup returns an error rather than a best-effort reading.
Step 5: Call the Synthesis Endpoint
Send an HTTP request to the provider's synthesis endpoint containing your text or SSML, the voice identifier, the language code, and the desired audio encoding. The request is a standard authenticated POST call, and the provider's documentation describes the exact request structure for each service.
Step 6: Receive and Decode the Audio
The response arrives as base64-encoded audio. Decode it into binary audio data on your server before storage or playback. Base64 inflates payload size by roughly a third, so decode early if you are streaming to clients over constrained networks.
Step 7: Play or Store the Audio
Either stream the decoded audio directly to the client for immediate playback or write it to object storage for later use. For audiobooks and other long-form content, store it. For voice assistants, stream it.
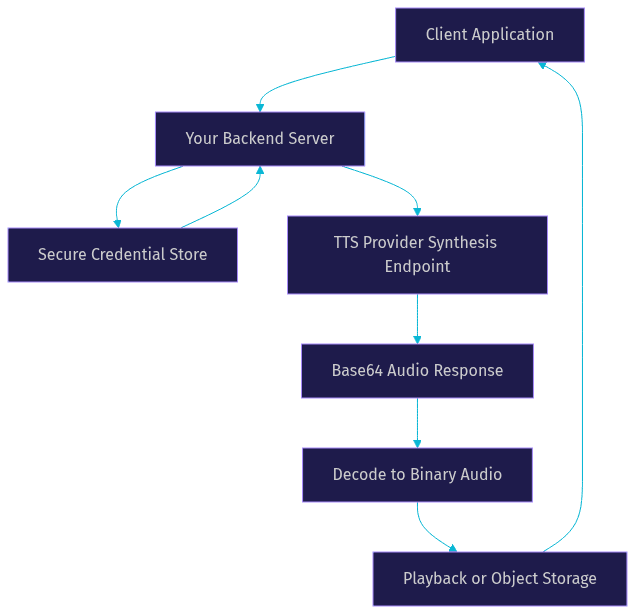
The loop above is the entire architecture. Your backend sits between the client and the provider, holding credentials, decoding audio, and controlling caching. Teams that skip the backend layer and call TTS providers directly from browsers expose credentials and lose all caching control.
Optimizing Speech Quality
Voice quality is a tuning problem, not a binary choice. Small parameter adjustments produce large perceptual differences.
Start with voice selection, which matters more than any other setting. Then tune the three core prosody parameters: pitch, speaking rate, and volume gain. Speaking rate is the most impactful. A rate even ten percent too fast makes technical content hard to follow, while ten percent too slow sounds condescending. Pitch adjustments of a few semitones can make a voice feel warmer or more authoritative.
Some providers also support emotion or style tags that switch a voice between delivery modes, such as cheerful, empathetic, or neutral. These work well for customer-facing scripts but test them carefully, because style shifts can sound jarring mid-paragraph.
The practical workflow is iterative: generate a short representative sample, adjust one parameter, regenerate, and compare. Keep the sample under thirty seconds so each iteration costs almost nothing and comparison stays fast. Once you lock in settings, save them as named configuration so your whole team generates consistent audio.
One caution from practice: do not chase perfection on day one. A good neural voice with sensible defaults outperforms weeks of micro-tuning a mediocre voice. Get the defaults right, then optimize the passages users hear most, such as greetings and error messages.
Advanced Scenarios
Once basic synthesis works, three advanced patterns unlock the serious use cases.
Real-Time Streaming for Voice Assistants
Voice assistants cannot wait for a full sentence of audio before responding. Low-latency TTS streams audio in chunks as it is generated, so playback begins before synthesis finishes. Target end-to-end response times under a second for conversational products. This requires a streaming-capable TTS endpoint, a client that plays audio incrementally, and careful buffering to avoid gaps. Platforms like VideoSDK's agent pipeline are built around exactly this constraint, streaming TTS output directly into live sessions with sub-second response targets. The VideoSDK AI Agents docs cover the full STT-to-TTS streaming architecture.
Batch Synthesis for Long-Form Audio
Audiobooks, course narration, and article audio feeds need batch synthesis: generating hours of audio from large text corpora. The key disciplines are chunking text at natural sentence boundaries, generating in parallel within your quota limits, concatenating with consistent encoding settings, and storing results in object storage. Batch work also benefits from caching, since popular content gets re-requested and regeneration is pure waste.
Custom Voice Creation
Custom voice creation, often called voice cloning, trains a voice model on recorded speech from a specific person. Data requirements vary by provider but typically involve thirty minutes to several hours of clean, consented recordings. Azure's custom voice program requires an explicit approval process precisely because of misuse potential. Treat custom voices as a serious commitment, not a weekend experiment.
Common Pitfalls and Troubleshooting
Most TTS failures fall into five predictable categories, and each has a quick check.
Token and credential expiration. Service account tokens expire, and expired credentials return authentication errors that look like API outages. Check token validity first whenever synthesis suddenly stops working across your whole application.
Language-voice mismatches. Requesting English text with a French voice identifier produces mangled pronunciation or an outright error. Always verify that your voice identifier supports your language code, especially after adding a new locale.
SSML syntax errors. A single unclosed tag rejects the entire request. Validate SSML structure before sending, and keep a minimal known-good template that you extend incrementally rather than building complex markup from scratch each time.
Audio clipping and encoding mismatches. Audio that plays at the wrong speed or sounds distorted usually means a sample-rate or encoding mismatch between what you requested and what your playback path expects. Confirm the requested encoding matches your player's supported formats.
Latency spikes. Sudden latency increases often trace to network routing, quota throttling, or oversized input text. Check your request sizes, monitor provider status pages, and cache aggressively for repeated content.
Ethical and Legal Considerations
Synthesized speech carries real legal and ethical weight, and responsible handling is now a compliance requirement, not a courtesy.
Disclosure comes first. Several jurisdictions and platform policies require that users be informed when they are hearing synthetic speech, particularly in customer service and outbound calling contexts. Many providers automatically watermark generated audio or embed metadata identifying it as synthetic.
Voice cloning deserves special care. Cloning a voice without the speaker's documented consent creates deep-fake risk and potential legal liability. Use provider programs that require recorded consent statements, and keep that consent documentation on file.
Copyright also applies. Generated speech itself is generally usable, but the underlying text you synthesize may be copyrighted, and cloned voices may carry usage restrictions set by the provider or the voice owner. Review your provider's acceptable use policy before shipping a commercial product.
Definitions Glossary
Text to Speech (TTS): The automatic conversion of written text into synthesized spoken audio, typically delivered through a cloud API that returns an encoded audio file or stream.
SSML (Speech Synthesis Markup Language): An XML-based markup language that gives developers explicit control over pauses, emphasis, pronunciation, pitch, and speaking rate in synthesized speech.
Neural Voice: A voice generated by a neural network acoustic model, producing natural prosody and intonation compared to older concatenative techniques that stitched recorded fragments together.
Real-Time TTS: Streaming speech synthesis that begins returning audio before the full input is processed, enabling sub-second response times for voice assistants and live agents.
Batch Synthesis: Generating large volumes of audio from long text corpora in parallel, used for audiobooks, course narration, and archived content feeds.
Voice Cloning: Training a custom voice model on recorded speech from a specific person, requiring consented audio data and, with most providers, an approval process.
Key Takeaways
- Text to speech converts text into audio through a three-stage pipeline: linguistic normalization, neural acoustic modeling, and audio encoding, all handled by the cloud provider.
- Google Cloud TTS, OpenAI's Audio API, and Azure Speech Service each win different scenarios: multilingual breadth, conversational naturalness, and enterprise telephony respectively.
- Text preparation with SSML is the highest-leverage step, controlling pauses, number pronunciation, and emphasis before any audio is generated.
- Always route synthesis through your own backend so credentials stay server-side and you retain caching and rate-limiting control.
- Real-time streaming and batch synthesis are the two production patterns, and choosing the wrong one for your use case causes either latency pain or wasted regeneration cost.
Conclusion
Learning how to do text to speech is less about machine learning and more about disciplined integration: pick the right provider for your use case, prepare text carefully with SSML, authenticate through a backend, and tune prosody with short iterative samples. The advanced patterns, real-time streaming for assistants and batch synthesis for long-form audio, then become straightforward extensions of the same workflow. If you are building a live voice product, VideoSDK's AI agent pipeline connects your TTS provider directly into real-time sessions, and you can start experimenting with the VideoSDK AI Agents guide or grab code samples from the VideoSDK code sample library. What are you building with synthesized speech? Drop a comment, I'd love to hear what kind of voice experience you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ