


Whisper speech to text is OpenAI's open-source, end-to-end speech recognition system that converts spoken audio into written text using a transformer-based encoder-decoder architecture. It supports multilingual transcription, language identification, and translation across model sizes ranging from tiny to large, giving developers flexibility between speed and accuracy. You can use it through the OpenAI API, run it locally with Whisper.cpp, or integrate it into real-time pipelines using VideoSDK's AI agent infrastructure for live transcription workflows.
If you have ever tried to build a transcription feature from scratch, you know the pain of stitching together acoustic models, language models, and post-processing pipelines. Whisper speech to text collapses all of that into a single neural network trained on 680,000 hours of multilingual audio data. That scale is what makes it remarkably robust across accents, background noise, and languages without requiring per-domain fine-tuning.
For developers building applications that need audio transcription, whether that is a meeting recorder, a podcast indexing tool, or a real-time voice agent, Whisper has become the default starting point. This guide walks through how it works, how to optimize it, and how to deploy it in production without burning through your compute budget.
Understanding Whisper Speech-to-Text Technology
Whisper speech to text stands out because it treats transcription, language identification, and translation as related tasks within a single model rather than separate systems glued together. OpenAI trained it on a massive and diverse audio dataset scraped from the internet, which gives it a level of generalization that narrower models trained on clean audiobook data simply cannot match. Developers choose Whisper because it works acceptably on messy, real-world audio out of the box, and because the open-source release means you can run it on your own hardware without per-minute API fees.
The model handles 99 languages for transcription and can translate non-English speech into English text. It also includes built-in timestamp prediction and special token handling for events like silence, music, and background noise. This multitask design means a single model deployment can serve multiple product features, which simplifies your infrastructure considerably.
How Whisper Works Under the Hood
Whisper processes audio by first converting the raw waveform into a log-mel spectrogram, which represents audio as a visual time-frequency grid. This spectrogram is then passed through a transformer encoder that extracts meaningful acoustic features. A transformer decoder generates text tokens autoregressively, meaning it predicts each token based on the spectrogram and all previously generated tokens.
The decoder uses special tokens to structure its output, including tokens for language identification, task selection (transcribe versus translate), and timestamp markers. This token-based design is what allows a single model to handle multiple languages and tasks without separate fine-tuning heads. The architecture is conceptually similar to a sequence-to-sequence translation model, except the source sequence is an audio spectrogram instead of text in a foreign language.
Model Sizes and Trade-offs
Whisper ships in five primary model sizes: tiny, base, small, medium, and large. Each size roughly doubles the parameter count of the previous one, which creates a direct trade-off between transcription accuracy and inference speed. The tiny model runs at around 39 million parameters and can transcribe faster than real-time on a modern CPU, while the large model exceeds 1.5 billion parameters and typically requires GPU acceleration for practical use.
For English-only transcription, the small model (244 million parameters) hits a sweet spot where accuracy is strong and resource requirements remain manageable on modest hardware. For multilingual workloads, the medium and large models perform significantly better because they have enough capacity to represent the acoustic and lexical patterns of diverse languages. Developers should benchmark their specific audio domain against multiple model sizes rather than defaulting to the largest option, since the accuracy gap between small and large is often smaller than the cost gap.
Setting Up Whisper for Accurate Transcription
Getting good results from Whisper speech to text requires preparation before you ever pass audio through the model. The quality of your input audio has a disproportionate impact on transcription accuracy, and choosing the wrong model size for your hardware can turn a fast pipeline into a painfully slow one. The setup phase is where most developers either set themselves up for smooth production operation or create problems that surface later under load.
Preparing Audio Input
Whisper expects audio at a 16,000 Hz sample rate in mono channel format. If your input audio does not match this specification, you need to resample and downmix it before inference. The standard approach is to use ffmpeg as a preprocessing step, converting any incoming audio format to the correct sample rate and channel configuration. This normalization step matters more than most developers expect because resampling artifacts can introduce errors that the model interprets as speech.
Stereo audio should be downmixed to mono by averaging channels rather than dropping one channel entirely, since both channels may contain unique speech content in scenarios like phone calls. You should also trim leading and trailing silence to reduce unnecessary processing time, especially for batch transcription of many short clips. Consistent audio preprocessing ensures that the model receives clean, predictable input regardless of the source format.
Choosing the Right Model for Your Use-Case
Model selection should be driven by three factors: your target languages, your available hardware, and your latency requirements. If you are transcribing English audio on a server with a modern GPU, the medium model offers excellent accuracy with sub-real-time latency. If you are running on CPU-only infrastructure, the tiny or base models will keep your pipeline responsive, though you will sacrifice some accuracy on accented speech and noisy audio.
For real-time transcription use cases, such as live captioning in a video calling application built with VideoSDK's React SDK, the tiny or base models are typically the only viable options on CPU. If you need higher accuracy in a streaming context, consider running the small model on a GPU instance and sending audio chunks over a network connection. The key is to match your model size to your actual latency budget, not to your desired accuracy in the abstract.
Optimizing Performance and Cost
Running Whisper speech to text at scale introduces real cost considerations, especially if you are processing hundreds of hours of audio per day. The difference between an optimized pipeline and a naive one can be an order of magnitude in compute costs. Optimization involves choosing the right hardware, batching requests intelligently, and deciding whether your use case truly requires real-time processing or can tolerate batch processing with better throughput.
GPU vs CPU Inference
GPU inference is the clear choice for the medium and large Whisper models, where the parallel computation capabilities of modern GPUs dramatically reduce per-audio-minute processing time. A single mid-range GPU like an NVIDIA A10G can transcribe audio with the large model at 10 to 30 times real-time speed, meaning one hour of audio processes in two to six minutes. CPU inference is viable for the tiny and base models, which can run at or near real-time on modern multi-core processors.
Batching multiple audio segments together on a GPU can further improve throughput by keeping the GPU saturated. However, batching introduces complexity in your pipeline because segments of different lengths need padding or truncation to form uniform batches. For production systems, a common pattern is to maintain a queue of audio chunks and process them in batches of 8 to 16 on a GPU worker, which balances throughput with latency for most workloads.
Real-time vs Batch Transcription
Real-time transcription processes audio in small chunks as it arrives, producing text with minimal delay. This is essential for live captioning, voice agents, and interactive applications where users need immediate feedback. The challenge with real-time Whisper is that the model was designed for complete utterances, so chunking audio too aggressively can degrade accuracy at chunk boundaries. A practical approach is to use a sliding window of 20 to 30 seconds with overlap, then merge overlapping transcriptions.
Batch transcription processes complete audio files after recording finishes, which allows the model to use full context for maximum accuracy. This is ideal for podcast transcription, meeting recording post-processing, and any scenario where a few minutes of processing delay is acceptable. Batch processing is significantly cheaper per audio hour because you can use spot instances, maximize batching, and avoid the overhead of streaming infrastructure. For applications that need both, a hybrid approach can batch process for accuracy while running a smaller model in parallel for live preview.
Common Pitfalls and How to Avoid Them
Even with a solid setup, Whisper speech to text has known failure modes that trip up developers in production. Understanding these pitfalls before deployment saves debugging time and prevents user-facing quality issues. The most common problems relate to audio quality, memory management, and the model's tendency to hallucinate text during silence.
Handling Background Noise and Overlapping Speech
Whisper is more robust to background noise than many older speech recognition systems, but it still struggles with overlapping speakers and loud non-speech sounds. In noisy environments, the model may transcribe phantom words during silent periods, a phenomenon known as hallucination. Applying a noise gate or voice activity detection (VAD) filter before Whisper inference can significantly reduce these hallucinations by ensuring the model only processes segments that actually contain speech.
For overlapping speech, Whisper does not perform speaker diarization natively. If your application needs to identify who said what, you will need to pair Whisper with a separate diarization system. A common architecture runs VAD to split audio into speech segments, applies a clustering model to assign speaker labels, and then transcribes each segment with Whisper. This adds complexity but is necessary for meeting transcription and interview processing use cases.
Managing Long Recordings and Memory
Long audio files can cause out-of-memory errors because Whisper processes the entire spectrogram in a single forward pass. The standard solution is to chunk long recordings into 30-second segments, which matches Whisper's training window size, and process each chunk independently. You then stitch the resulting text segments together, using timestamp tokens to align overlapping chunks.
Checkpointing is important for batch processing of many long files. If your pipeline crashes after processing 50 of 100 files, you want to resume from file 51 rather than starting over. Store intermediate results and processing state after each file completes. For streaming pipelines, implement backpressure handling so that if the transcription worker falls behind, the audio buffer does not grow unbounded and cause memory pressure on your application server.
Integrating Whisper Speech-to-Text into Applications
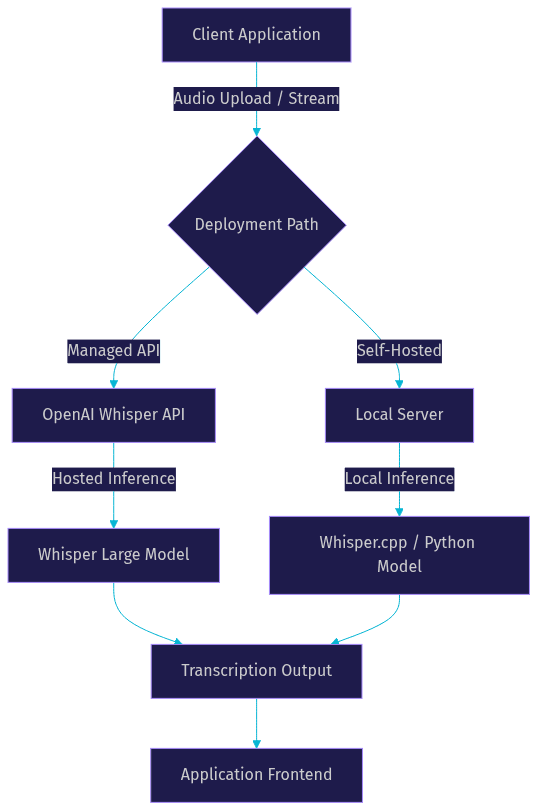
Integrating Whisper into a production application involves choosing between the managed OpenAI API and self-hosted deployment. Each path has distinct trade-offs in cost, latency, control, and operational complexity. Your choice depends on your audio volume, latency requirements, budget, and whether you need to keep audio data within your own infrastructure for compliance reasons.
Using the OpenAI API
The OpenAI API provides Whisper speech to text as a hosted service through two endpoints: a standard transcription endpoint and a translation endpoint. Authentication uses your OpenAI API key, and you send audio files as multipart form data along with optional parameters for language, response format, and timestamp granularity. The API supports responses in plain text, JSON, verbose JSON with timestamps, and subtitle formats (SRT and VTT).
Rate limits on the API are based on tokens per minute and requests per minute, which means very long audio files can hit token limits before request limits. For high-volume workloads, the API cost is billed per minute of audio processed, which is straightforward but can become expensive at scale. The API is the fastest path to production for teams that want transcription without managing GPU infrastructure, and it guarantees you always run the latest model version without maintenance overhead.
Running Whisper Locally with Whisper.cpp
Whisper.cpp is a C++ port of the Whisper model that enables high-performance inference on CPU and Apple Silicon without requiring Python or PyTorch. It is particularly valuable for edge deployment, on-device transcription, and scenarios where you cannot send audio to a third-party API. The compilation process involves cloning the repository, downloading your chosen model in GGML format, and building the project with your platform's native compiler.
Once compiled, Whisper.cpp can serve as a backend for a lightweight HTTP transcription endpoint. You would typically wrap it in a small web server that accepts audio uploads, writes them to a temporary file, invokes the Whisper.cpp binary, and returns the transcription result. This approach gives you full control over data privacy and eliminates per-minute API costs, though you bear the responsibility for infrastructure maintenance and scaling. For real-time applications, you can also explore VideoSDK's real-time transcription capabilities which integrate transcription directly into video calling sessions.
The following diagram illustrates a typical Whisper deployment architecture showing both API and local deployment paths:
Comparing Whisper Speech-to-Text with Other STT Solutions
Whisper is not the only speech-to-text option available, and choosing it blindly over alternatives like Deepgram, Google Cloud Speech-to-Text, or Azure Speech can lead to suboptimal results for specific use cases. An objective comparison requires looking at accuracy benchmarks, latency characteristics, resource requirements, and cost structures across providers. Each solution has strengths that make it better suited to particular workloads.
Accuracy Benchmarks
On the LibriSpeech benchmark, which tests clean read speech, Whisper large achieves a word error rate (WER) of approximately 3 to 5 percent, which is competitive with but not always better than specialized models from Deepgram and Google. Where Whisper excels is on noisy, real-world audio and multilingual content, where its broad training data gives it an edge over models trained primarily on clean English audiobook data. According to independent benchmarks from Artificial Analysis's Speech Arena, Deepgram's Nova models often achieve lower WER on conversational audio, while Whisper maintains stronger performance on accented and non-English speech.
It is important to note that benchmark numbers vary significantly based on audio domain, language, and preprocessing quality. A model that wins on LibriSpeech may underperform on phone call audio with codec compression artifacts. Developers should always benchmark candidate models on their own representative audio samples rather than relying solely on published numbers.
Latency and Resource Requirements
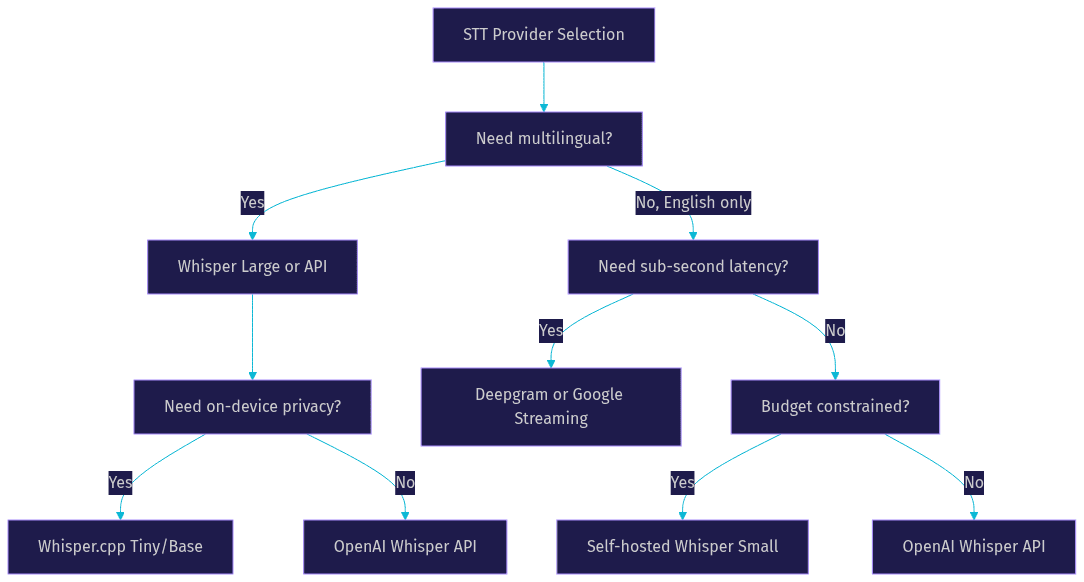
Whisper's latency depends heavily on model size and hardware. The large model on a GPU achieves transcription throughput of 10 to 30 times real-time, while the tiny model on CPU can process audio at 2 to 5 times real-time. In contrast, streaming-optimized models like Deepgram are designed for sub-second latency on live audio and do not require chunking workarounds. Google Cloud Speech-to-Text and Azure Speech both offer streaming endpoints with latency under 500 milliseconds for their standard models.
Cost per hour of audio also varies dramatically. The OpenAI Whisper API charges per minute of audio processed, while self-hosted Whisper costs only the compute infrastructure. Deepgram and Google charge per minute but offer volume discounts. For high-volume workloads exceeding 1,000 hours per month, self-hosted Whisper on GPU instances is often the most cost-effective option, though it requires engineering investment in infrastructure and monitoring.
The decision matrix below visualizes when to choose Whisper versus alternative STT providers based on common developer scenarios:
Future Directions and Community Resources
The Whisper speech to text ecosystem continues to evolve rapidly in 2026, with active development on model efficiency, real-time streaming support, and hardware acceleration. OpenAI has not released a Whisper v2 as a standalone model, but the community has produced numerous optimized variants, quantized versions, and fine-tuned derivatives that extend the original model's capabilities for specific domains and languages.
Model Updates and Open-Source Contributions
The official OpenAI Whisper GitHub repository remains the canonical source for model weights and reference implementations. Community contributions have produced faster inference engines like Whisper.cpp, faster-whisper (which uses CTranslate2 for optimized inference), and whisper-jax (which leverages JAX for GPU acceleration). These projects demonstrate the strength of the open-source ecosystem around Whisper and give developers multiple deployment options beyond the original Python implementation.
Developers can contribute by reporting issues, improving documentation, and sharing benchmark results for specific audio domains. The release cadence of community forks is typically faster than the official repository, so monitoring the broader ecosystem is important for staying current with performance improvements.
Where to Find Help and Sample Projects
Official documentation on OpenAI's platform provides API reference material and integration guides. For self-hosted deployments, the Whisper.cpp and faster-whisper GitHub repositories include detailed README files and issue trackers where developers share solutions. The VideoSDK Discord community includes developers building real-time transcription pipelines who can share practical integration advice.
Notable open-source projects include WhisperX (which adds speaker diarization and word-level alignment), whisper.cpp bindings for WebAssembly (enabling in-browser transcription), and VideoSDK's code samples which include transcription integration examples for video calling applications. These resources provide starting points for common integration patterns and reduce the time needed to build a production transcription feature.
Definitions Glossary
Whisper: OpenAI's open-source speech recognition model that performs transcription, language identification, and translation using a transformer encoder-decoder architecture trained on 680,000 hours of multilingual audio.
Log-Mel Spectrogram: A time-frequency representation of audio that Whisper uses as input, converting raw waveforms into a visual grid of acoustic energy across frequency bands.
Word Error Rate (WER): The standard metric for speech recognition accuracy, calculated as the percentage of words that are substituted, deleted, or inserted relative to the reference transcription.
Voice Activity Detection (VAD): A preprocessing technique that identifies which portions of an audio stream contain speech, used to reduce Whisper hallucinations during silent segments and to enable efficient chunking.
Speaker Diarization: The process of partitioning an audio stream into segments based on speaker identity, which Whisper does not perform natively and must be handled by a separate system.
Whisper.cpp: A high-performance C++ port of the Whisper model that enables CPU and Apple Silicon inference without Python dependencies, suitable for edge deployment and self-hosted transcription services.
Key Takeaways
- Whisper speech to text offers strong out-of-the-box accuracy on noisy, multilingual audio without requiring domain-specific fine-tuning, making it an excellent default choice for new transcription projects.
- Model size selection should be driven by your hardware, latency budget, and target languages, not by a blanket assumption that larger is always better.
- Audio preprocessing to 16 kHz mono format is non-negotiable for reliable results, and applying VAD before inference significantly reduces hallucination errors during silence.
- The OpenAI API is the fastest path to production for low-volume workloads, while self-hosted Whisper on GPU instances becomes more cost-effective above approximately 1,000 audio hours per month.
- For real-time transcription in video calling applications, pairing Whisper with VideoSDK's real-time communication SDKs provides a complete pipeline from audio capture to text output.
Conclusion
Whisper speech to text has fundamentally changed how developers approach audio transcription by combining strong multilingual accuracy with open-source flexibility. Whether you use the managed OpenAI API for speed-to-production or self-host with Whisper.cpp for cost control and data privacy, the key to success lies in thoughtful audio preprocessing, appropriate model selection, and honest benchmarking against alternatives like Deepgram and Google Cloud Speech. For developers building real-time voice applications, integrating Whisper with VideoSDK's AI agent infrastructure gives you a production-ready pipeline that handles audio capture, transcription, and response generation in one cohesive system. You can start building today by signing up at app.videosdk.live/login and exploring the free tier. What are you building with Whisper speech to text? Drop a comment below, I would love to hear what kind of transcription use case you are working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ