


Speech recognition in Python is the process of converting spoken audio into text using libraries such as OpenAI Whisper, Vosk, SpeechRecognition, and NVIDIA NeMo. Python is the dominant language for this work because every major ASR framework ships first-class Python APIs. For real-time, production-grade voice applications, VideoSDK's Python SDK and AI agent infrastructure let you pipe live audio from a room directly into your speech recognition pipeline.
Speech interfaces have moved from novelty to expectation. Voice assistants, meeting transcription, podcast indexing, call center analytics, and AI voice agents all depend on one core capability: converting audio into accurate text, fast. Python has become the default language for this work because the entire machine learning ecosystem, from data preprocessing to model serving, is built around it.
The tooling landscape has also matured dramatically. OpenAI's Whisper models pushed open-source transcription accuracy to levels that were exclusive to cloud giants a few years ago, while lightweight engines like Vosk made offline, real-time recognition practical on a laptop. Meanwhile, real-time communication platforms like VideoSDK now expose live audio streams to Python backends, which means you can transcribe an ongoing video call, not just a recorded file.
This guide walks through the full journey: understanding how speech recognition actually works, choosing the right library, building a complete pipeline, improving accuracy, and deploying to production. By the end, you will know how to assemble a speech-to-text system in Python that fits your latency, privacy, and hardware constraints.
Understanding Speech Recognition Basics
Every speech recognition system, regardless of library, follows the same fundamental architecture. Audio is captured, converted into numerical features, and decoded into text using models that map acoustic patterns to linguistic meaning.
Three components do the heavy lifting. The acoustic model learns the relationship between audio signals and phonetic units, effectively recognizing which sounds are being produced. The language model scores candidate word sequences, helping the decoder pick "recognize speech" over the phonetically similar "wreck a nice beach." The decoder combines both models to search for the most probable transcription.
Modern end-to-end systems, like Whisper, collapse these components into a single neural network trained on hundreds of thousands of hours of audio, which is why they generalize so well across accents and noise conditions.
To evaluate any system, you need metrics. Word Error Rate (WER) is the standard: it counts substitutions, deletions, and insertions as a percentage of total words. A WER below 10 percent is considered production-grade for conversational audio, and benchmarks from Artificial Analysis's Speech Arena show top models now achieving mid-single-digit WER on clean speech.
Choosing the Right Python Library
The library you choose shapes everything downstream: latency, accuracy, cost, and deployment complexity. There is no single best option, only the best fit for your constraints.
Overview of Popular Libraries
OpenAI Whisper is the accuracy leader among open-source options. It supports roughly 100 languages, handles noisy audio remarkably well, and includes built-in translation. The trade-off is resource consumption: larger Whisper variants need a GPU for acceptable speed, and it is fundamentally a batch tool unless you adapt it for streaming.
Vosk is the go-to for lightweight, offline, real-time recognition. It runs on devices as small as a Raspberry Pi, supports more than 20 languages, and streams partial results with latency measured in hundreds of milliseconds. Accuracy trails Whisper on difficult audio, but for embedded and edge scenarios it is hard to beat.
SpeechRecognition is best understood as a unified front-end. It provides a consistent interface over multiple engines, including Google Cloud Speech, Whisper, and Vosk, which makes it ideal for prototyping and switching backends without rewriting your logic.
NVIDIA NeMo targets teams building custom ASR systems. It offers production-grade models like Parakeet and Canary, speaker diarization, and full training pipelines for fine-tuning on domain-specific audio. It demands more expertise and GPU infrastructure but delivers the most control.
Coqui DeepSpeech deserves a mention historically, but the original project has been discontinued, so treat it as legacy unless you maintain an existing deployment.
Selecting Based on Project Needs
Choose based on four questions. First, what latency do you need? Sub-second response times point to Vosk or streaming cloud APIs; batch transcription of recorded files can use full-size Whisper. Second, what hardware do you have? CPU-only deployments favor Vosk's small models; GPU availability unlocks Whisper and NeMo. Third, what are your privacy requirements? Healthcare and legal workloads often mandate offline processing, eliminating cloud APIs entirely. Fourth, what licensing fits your product? Vosk and Whisper use permissive licenses suitable for commercial products, while some cloud services restrict storage and retraining of audio.
For a concrete decision rule: use Whisper for accuracy-critical batch transcription, Vosk for offline real-time on constrained hardware, NeMo when you need to train or fine-tune custom models, and SpeechRecognition when you want backend flexibility during prototyping.
Setting Up the Development Environment
A clean environment prevents the most frustrating class of speech recognition bugs, which are almost always audio-format mismatches rather than model failures.
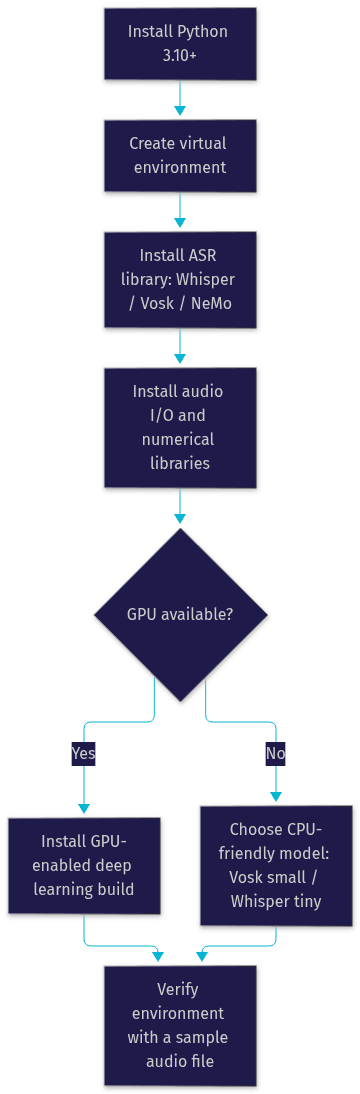
Start with a recent Python release, version 3.10 or newer, since current ASR library versions require it. Create an isolated virtual environment for the project so that audio-processing dependencies do not conflict with other machine learning work on your machine.
Your core dependency groups are: the ASR library itself, an audio I/O library for reading files and capturing microphone input, and numerical libraries for preprocessing. If you plan GPU inference with Whisper or NeMo, install the GPU-enabled builds of the deep learning framework, and verify that your system actually detects the GPU before training or inference, since silently falling back to CPU is a common and painful surprise.
One practical tip from production deployments: pin your library versions explicitly. Speech recognition libraries update frequently, and a minor version bump can change default models or audio handling behavior.
Offline vs Cloud-Based Solutions
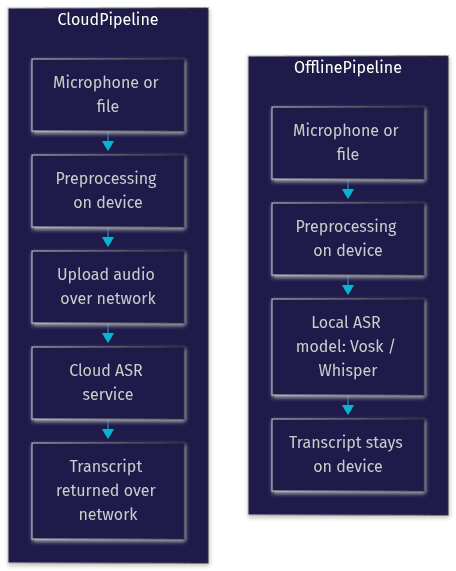
The offline versus cloud decision is architectural, not just a pricing question, because it determines where your audio data lives and how your latency budget is spent.
Offline solutions process audio entirely on your hardware. Privacy is the headline benefit: no audio leaves the device, which matters enormously for healthcare, legal, and enterprise deployments. There are no per-minute API costs and no rate limits. The costs are upfront: you supply the compute, and you are responsible for model updates and accuracy improvements.
Cloud services, including Google Cloud Speech-to-Text, AssemblyAI, and Deepgram, offer state-of-the-art accuracy with zero infrastructure management, plus extras like speaker diarization and entity extraction built in. You pay per minute of audio, typically fractions of a cent, and you accept network latency and data residency considerations.
A hybrid pattern is increasingly common: run a small offline model for real-time interaction, and send the same audio to a larger cloud model for high-accuracy archival transcription.
Building a Simple Speech-to-Text Pipeline
A speech recognition pipeline is a sequence of well-defined stages, and understanding each stage independently makes debugging dramatically easier.
Capturing Audio Input
Your audio arrives from either a microphone or a file. Microphone capture requires selecting the correct input device and requesting operating-system permission, which desktop and mobile platforms enforce differently. File sources are simpler but introduce format questions: sample rate, channel count, and encoding must be known before inference. Most ASR models expect single-channel audio at 16 kHz, so stereo or higher-rate sources need conversion first.
Preprocessing Audio
Preprocessing exists to make the model's job easier. Resampling converts audio to the sample rate the model expects, typically 16 kHz. Normalization scales amplitude to a consistent range so quiet recordings are not penalized. Noise reduction removes steady background sounds like fans and hum; spectral gating techniques work well here and are available through standard Python audio libraries. Trimming leading and trailing silence also reduces wasted inference time.
Model Inference
Inference means feeding the processed audio into your chosen model and collecting the transcript. With Whisper, you load a model size matched to your hardware, pass the audio, and receive text plus language detection and segment timestamps. With Vosk, you create a recognizer bound to your model, then feed audio in small chunks, receiving partial hypotheses as speech continues, which is what enables real-time display. With cloud APIs, you upload audio or stream it and receive a JSON response containing the transcript and confidence metadata.
For live conversations, VideoSDK's Python SDK can serve as your audio source: it connects to a VideoSDK room, receives each participant's audio stream, and hands the raw audio to your recognition pipeline for real-time transcription during calls and meetings.
Post-Processing
Raw transcripts often lack punctuation and capitalization, especially from streaming models like Vosk. Punctuation restoration models, including lightweight transformer models available through Python libraries, convert lowercase word streams into readable sentences. Additional formatting steps include converting spoken numbers to digits, removing filler words, and normalizing timestamps for subtitle generation.
Improving Accuracy and Performance
Getting a working pipeline is the easy part. Getting a pipeline that survives real-world audio is where projects succeed or fail.
Noise Reduction Strategies
Noise is the number one accuracy killer. Beyond preprocessing, consider voice activity detection (VAD), which identifies speech segments and lets you skip inference on silence entirely. This both improves accuracy, since the model never sees pure noise, and cuts compute costs significantly. Energy-based VAD works for simple cases; neural VAD models handle music, crosstalk, and background conversation far better.
Leveraging Language Models and Custom Vocabulary
Domain-specific vocabulary is where generic models stumble. Product names, medical terminology, and acronyms routinely get mangled. Two fixes exist: shallow fusion, where an external language model rescores the ASR output to favor domain terms, and fine-tuning, where you retrain the acoustic model on labeled domain audio using a framework like NeMo. Fine-tuning delivers larger gains but requires hundreds of hours of transcribed domain audio. For cloud services, custom vocabulary and phrase hint features achieve similar boosts with far less effort.
Real-Time Streaming Optimizations
For streaming scenarios, three optimizations matter most. Use smaller, quantized models: converting model weights to lower precision roughly halves memory and speeds inference with minimal accuracy loss. Process audio in overlapping chunks so no words are cut at boundaries. And cache your model in memory between requests rather than reloading it, which is the single most common performance mistake in web-deployed speech services. If you are building interactive voice applications, VideoSDK's AI agent infrastructure handles this streaming architecture natively, with built-in turn detection and voice activity detection.
Deploying Speech Recognition in Applications
Deployment context changes your constraints more than any model choice does.
Desktop and CLI Tools
Desktop and command-line tools are the simplest deployment target. Package your pipeline with a task runner or GUI framework, bundle the model file with the application, and everything runs locally with zero network dependency. This is ideal for internal transcription tools, journalist interview processing, and accessibility utilities.
Web Integration with Flask and FastAPI
For web deployment, wrap your pipeline in a service using FastAPI or Flask. The critical architectural decision is how audio reaches your server: short clips can be uploaded as complete files, while live transcription requires WebSocket connections that stream audio chunks for incremental processing. Keep the model loaded in a worker process at startup, queue incoming requests, and scale by running multiple worker processes, each holding its own model instance. Monitor GPU memory carefully, since each loaded model consumes it.
Mobile and Edge Devices
Edge deployment inverts your priorities: model size and battery consumption dominate. Vosk's small models, roughly 50 megabytes, run comfortably on Android and iOS devices and on single-board computers like the Raspberry Pi. Quantized Whisper variants extend on-device transcription to mid-range phones. The payoff is complete offline operation, instant response, and zero recurring cost, which is why voice features in consumer apps increasingly run entirely on-device.
Common Pitfalls and Troubleshooting
Most speech recognition failures trace back to a handful of recurring issues.
Mismatched sample rates are the classic silent failure: audio recorded at 44.1 kHz fed to a model expecting 16 kHz produces garbage transcripts with no error message. Always verify the sample rate before inference.
Audio clipping occurs when input volume exceeds the maximum representable amplitude, flattening the waveform's peaks. Clipped audio cannot be repaired after capture, so fix gain levels at the source.
GPU memory errors appear when a model exceeds available VRAM, common when running large Whisper variants alongside other workloads. The fix is a smaller model variant or explicit memory management between inference runs.
API rate limits bite cloud deployments during batch processing. Throttle your request rate, implement exponential backoff on failures, and monitor your quota dashboard rather than discovering limits through errors.
Finally, stereo versus mono confusion: models trained on single-channel audio can behave unpredictably with two-channel input. Downmix to mono explicitly.
Future Trends in Python Speech Recognition
Three trends are reshaping the field right now.
First, real-time multimodal models, including OpenAI's Realtime API, Google's Gemini Live, and AWS Nova Sonic, process speech and generate responses in a single model, collapsing the traditional STT-to-LLM-to-TTS pipeline. This is precisely the architecture VideoSDK's AI voice agent SDK is built around, connecting these models to live rooms with sub-second interaction.
Second, on-device inference keeps improving. Distillation and quantization techniques are shrinking capable models to sizes that run on phones, making private, offline voice features standard rather than exceptional.
Third, speaker diarization and custom vocabulary tooling is becoming accessible. What once required research-level expertise is now available through mainstream Python libraries and cloud APIs, letting small teams build meeting intelligence products that were enterprise-only a few years ago.
Definitions Glossary
Word Error Rate (WER): The standard accuracy metric for speech recognition, calculated as the percentage of words that are substituted, deleted, or inserted relative to a correct transcript. Lower WER indicates a more accurate model.
Voice Activity Detection (VAD): A technique that identifies which segments of an audio signal contain actual speech. Using VAD before recognition improves accuracy and reduces compute by skipping silence and noise.
Speaker Diarization: The task of separating a multi-speaker recording into segments attributed to individual speakers. It answers "who spoke when" and is essential for meeting transcription.
Quantization: Reducing the numerical precision of a model's weights, for example from 32-bit to 8-bit values. It shrinks model size and speeds inference with minimal accuracy loss, enabling edge deployment.
Agent Worker: The Python process in VideoSDK's AI agent architecture that manages a voice agent's session lifecycle, running the speech recognition, language model, and text-to-speech pipeline inside a VideoSDK room.
Key Takeaways
- Speech recognition in Python is a pipeline problem: capture, preprocess, run inference, and post-process, and debugging each stage independently makes failures tractable.
- Choose your library by constraint: Whisper for accuracy-critical batch work, Vosk for offline real-time on constrained hardware, NeMo for custom model training, and SpeechRecognition for backend-flexible prototyping.
- The offline versus cloud decision is architectural, driven by privacy, latency, and cost, and hybrid patterns combining both are increasingly common.
- Preprocessing and voice activity detection deliver larger accuracy gains than model upgrades in most real-world projects.
- For live conversations and AI voice agents, VideoSDK's Python SDK and agent infrastructure provide the real-time audio transport layer that turns a speech recognition pipeline into an interactive product.
Conclusion
Speech recognition in Python has never been more accessible, with open-source models matching cloud accuracy and lightweight engines running on devices the size of a credit card. The winners in this space are developers who treat speech recognition as a full pipeline, from audio capture through post-processing, rather than a single library call. Start with a small end-to-end pipeline, measure word error rate on your actual audio, and iterate on preprocessing before reaching for bigger models. When you are ready to make your speech recognition pipeline conversational, explore the VideoSDK AI agents documentation and the Python SDK architecture guide to connect live audio rooms to your models. You can start free at app.videosdk.live. What are you building with speech recognition in Python? Drop a comment, I would love to hear about your use case.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ