


Speech recognition and synthesis from Google refers to two complementary cloud AI services: Google Speech-to-Text converts spoken audio into written text, and Google Cloud Text-to-Speech generates natural-sounding audio from written text. Together they form a complete voice pipeline that developers can embed into applications using REST APIs, gRPC, or client libraries. VideoSDK integrates with these Google services to power real-time transcription and voice responses inside live video and audio rooms.
Building a voice-powered application used to mean stitching together half a dozen libraries, each with its own quirks. Today, Google's cloud speech stack handles both ends of the conversation: listening and speaking. Whether you are building a transcription tool, a voice assistant, or an interactive telephony agent, understanding how these services work individually and together is essential for shipping a reliable product.
This guide walks through the capabilities, models, pricing, and integration patterns for speech recognition and synthesis from Google, with practical guidance on combining them in a unified pipeline.
Understanding Speech Recognition and Synthesis from Google
Google offers two primary AI services that cover the full voice interaction loop. Speech-to-Text takes raw audio and returns structured, timestamped text. Text-to-Speech takes written text and returns audio that sounds increasingly indistinguishable from human speech. Both services share the same Google Cloud foundation, meaning they use consistent authentication, regional routing, and billing infrastructure.
Developers choose Google's speech stack for three reasons: model quality, language breadth, and ecosystem integration. Google has trained its speech models on massive multilingual datasets, and the latest Chirp 3 model family pushes accuracy and naturalness further than previous generations. The services also integrate naturally with other Google Cloud AI products, including Gemini models for text reasoning and translation.
For developers building real-time communication apps, these services pair well with platforms like VideoSDK, which provides the live audio transport layer. VideoSDK handles the room, participant management, and media streaming, while Google's services handle the intelligence layer on top.
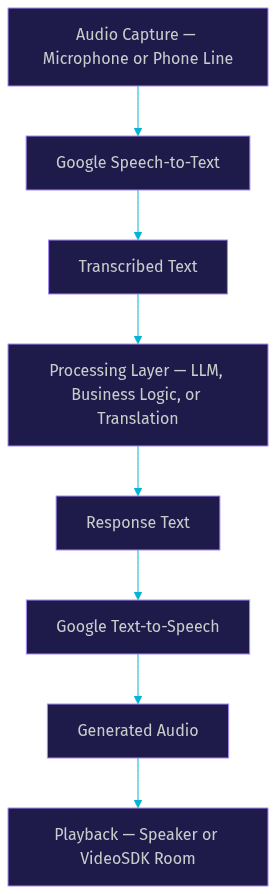
Here is a high-level view of how audio flows through a unified Google speech pipeline:
Google Speech-to-Text: From Audio to Text
Google Speech-to-Text is the transcription engine that converts spoken language into structured text. It supports over 125 languages and variants, and it handles everything from short voice commands to multi-hour recorded meetings.
Core Capabilities and Model Families
Google offers several model families, each tuned for different use cases. The Chirp 3 model represents the latest generation, delivering improved accuracy on conversational audio, accented speech, and noisy recordings. It builds on Google's earlier Chirp model with better multilingual handling and lower word-error rates on difficult audio.
Beyond Chirp 3, Google maintains specialized models. The long-running model handles extended audio files in batch mode. The short model is optimized for brief utterances like voice commands. The phone call model is tuned for the narrowband audio typical of telephony. The chirp_2 model remains available for developers who need stability while migrating to newer versions.
Developers select a model based on audio characteristics and latency requirements. Batch transcription processes recorded files asynchronously and is ideal for post-meeting summaries. Streaming recognition processes live audio in real time and is necessary for voice assistants and live captioning.
Real-Time Streaming Transcription
Streaming speech recognition is where Google's service shines for interactive applications. Audio is sent in chunks as the user speaks, and partial transcripts arrive within hundreds of milliseconds. This low-latency feedback loop is what makes live captioning and voice command systems feel responsive.
Speaker diarization is a critical feature for multi-participant scenarios. It labels each segment of transcript with a speaker identifier, so you know who said what. This is especially useful for meeting transcription, medical dictation, and customer service call analysis.
Multichannel recognition takes this further by processing each audio channel independently. If your audio source has separate channels for each speaker, Google can transcribe them in parallel and produce a cleaner, more accurate result than trying to separate a mixed mono stream.
For developers using VideoSDK, real-time transcription can be layered directly onto a live room. VideoSDK's real-time transcription feature captures participant audio and routes it through a transcription backend, which can use Google Speech-to-Text as the recognition engine.
Customization and Domain Adaptation
Out-of-the-box models are strong, but production applications often deal with domain-specific vocabulary. Medical terms, product names, and industry jargon can trip up even the best general-purpose model.
Google addresses this through model adaptation. You can provide phrase hints, which are words or phrases the model should prioritize during recognition. The boost parameter controls how strongly the model favors these hints. A high boost value makes the model more likely to output a hinted phrase even if the audio is ambiguous.
Custom vocabularies go further by letting you upload lists of domain-specific terms that the model should learn. This is particularly valuable for healthcare applications, legal transcription, and any vertical where accuracy on specialized terminology directly impacts business outcomes.
Noise robustness is another area where Google has invested heavily. The Chirp 3 model handles background noise, reverberation, and varying microphone quality better than its predecessors. For extremely noisy environments, combining Google's noise robustness with VideoSDK's built-in noise suppression produces the cleanest input signal for transcription.
Deployment Options and Security
Google Speech-to-Text is primarily a cloud service, but Google also offers an on-premise speech recognition solution for organizations with strict data residency or regulatory requirements. The on-premise option lets you run recognition models inside your own infrastructure, keeping audio data within your network perimeter.
For cloud deployments, Google provides regional endpoints across multiple continents. Choosing a region close to your users reduces latency, which matters for real-time applications. All data in transit is encrypted, and Google offers customer-managed encryption keys for organizations that need additional control.
Compliance certifications include HIPAA, SOC 2, and ISO 27001. For healthcare and financial applications, these certifications are often a prerequisite for using any cloud AI service.
Google Text-to-Speech: From Text to Natural Audio
Google Cloud Text-to-Speech is the synthesis engine that converts written text into spoken audio. It powers voice assistants, accessibility tools, audiobook narration, and automated phone systems.
Voice Tiers and the Chirp 3 HD Lineup
Google organizes its voices into tiers based on quality and generation method. The Chirp 3 HD voices represent the highest quality tier, producing audio that approaches human narration. These voices handle intonation, emphasis, and pacing with a level of naturalness that earlier tiers could not achieve.
Neural2 voices offer strong quality at a lower price point than HD voices. They use a different generation architecture and are suitable for applications where quality matters but budget is a concern. WaveNet voices, an older generation, remain available for backward compatibility. Standard voices use concatenative synthesis and are the most affordable option, though they sound noticeably robotic compared to neural voices.
Language coverage is broad. Google offers voices in over 40 languages and variants, with multiple voice options per language. This lets developers pick a voice that matches the gender, accent, and tone appropriate for their application and audience.
SSML and Fine-Grained Control
Speech Synthesis Markup Language (SSML) gives developers control over how text is spoken. Without SSML, the model decides pacing, emphasis, and pronunciation on its own. With SSML, you can insert pauses, adjust speaking rate, change pitch, and specify exact pronunciations for difficult words.
For example, you can use SSML to make a voice assistant speak more slowly when reading out a phone number, then return to normal speed for conversational text. You can emphasize specific words in a product announcement. You can also use phoneme tags to force correct pronunciation of names or technical terms that the model might misread.
SSML support varies by voice tier. The HD and Neural2 voices support the full SSML tag set, while Standard voices support a reduced subset. Developers building production voice applications should verify SSML compatibility for their chosen voice before committing to a tier.
Streaming Synthesis and Low-Latency Use Cases
Like Speech-to-Text, Text-to-Speech supports streaming synthesis. Instead of waiting for the entire text to be processed before returning any audio, streaming synthesis returns audio chunks as they are generated. This reduces time-to-first-audio, which is the metric that matters most for interactive voice applications.
For a voice assistant, the user experience depends on how quickly the system responds after the user stops speaking. If the assistant takes two seconds to start talking, the interaction feels sluggish. Streaming synthesis can cut that to under 500 milliseconds for short responses, making the conversation feel natural.
This is where pairing Google's TTS with a real-time transport layer like VideoSDK becomes powerful. VideoSDK's AI Voice Agent architecture connects STT, LLM, and TTS providers into a single pipeline, and Google's streaming TTS can serve as the speech generation component.
Custom Voice Creation and Regional Considerations
Google offers a Custom Voice feature that lets organizations train a unique voice on their own audio data. This is valuable for brands that want a consistent, recognizable voice across all customer touchpoints. The training process requires high-quality recordings of a single speaker reading a provided script.
Custom Voice has regulatory implications. Google requires proof that you have the right to use the speaker's voice, and the feature is not available in all regions. Developers should check regional availability and compliance requirements before committing to a custom voice project.
Regional endpoints for Text-to-Speech mirror those for Speech-to-Text. Selecting a nearby region reduces latency for streaming synthesis, which is critical for real-time applications.
Choosing the Right Service for Your Application
Most voice-powered applications need both recognition and synthesis, but the emphasis varies. A transcription-only tool needs Speech-to-Text but not Text-to-Speech. An audiobook generator needs Text-to-Speech but not Speech-to-Text. A voice assistant or AI phone agent needs both.
Decision Matrix: Transcription vs Synthesis Needs
If your application captures human speech and converts it to text for storage, search, or analysis, Google Speech-to-Text is your primary service. If your application generates spoken audio from text for playback, Google Text-to-Speech is your primary service. If your application does both, which is the case for conversational AI, you need both services working in a pipeline.
The decision also depends on latency requirements. Batch processing can tolerate seconds of delay. Real-time applications need sub-second response, which means streaming APIs for both services and careful pipeline design.
Cost Considerations and Free-Tier Limits
Google Cloud provides a free tier for both services . Speech-to-Text offers a limited number of free transcription minutes per month. Text-to-Speech offers a limited number of free characters per month. These free tiers are sufficient for development and testing but will not cover production traffic.
Pricing scales with usage. Speech-to-Text charges per minute of audio processed, with different rates for standard and enhanced models. Text-to-Speech charges per character of text synthesized, with different rates for Standard, WaveNet, Neural2, and HD voices. The HD voices are the most expensive, and costs add up quickly for high-volume applications like call center automation.
Budgeting tip: use the cheapest voice tier that meets your quality bar. For internal tools, Standard or WaveNet voices may be sufficient. For customer-facing applications, Neural2 or HD voices deliver the quality users expect.
Performance and Latency Benchmarks
Google publishes latency figures for its speech models, and independent benchmarks from sources like Artificial Analysis provide additional context. According to Google's published documentation, streaming Speech-to-Text returns partial results in under a second for most configurations. Streaming Text-to-Speech achieves time-to-first-audio in the 200 to 400 millisecond range for short inputs .
For comparison, other major STT providers like Deepgram and AssemblyAI publish their own latency numbers, and the differences are often within 100 to 200 milliseconds for similar model tiers. The choice between providers frequently comes down to accuracy on your specific audio domain, pricing, and ecosystem fit rather than raw latency alone.
Integrating Both Services in a Unified Workflow
Building a complete voice pipeline means connecting Speech-to-Text, a processing layer, and Text-to-Speech into a single flow that handles errors gracefully and scales under load.
End-to-End Pipeline Description
A typical pipeline starts with audio capture. In a VideoSDK room, this means accessing a participant's microphone stream. The audio is chunked and sent to Google Speech-to-Text via its streaming API. As partial transcripts arrive, they are passed to a processing layer, which might be an LLM for conversational responses, a translation service for multilingual scenarios, or business logic for command processing.
The processing layer produces response text, which is sent to Google Text-to-Speech via its streaming API. The returned audio chunks are played back to the user through the VideoSDK room or directly through the device speaker.
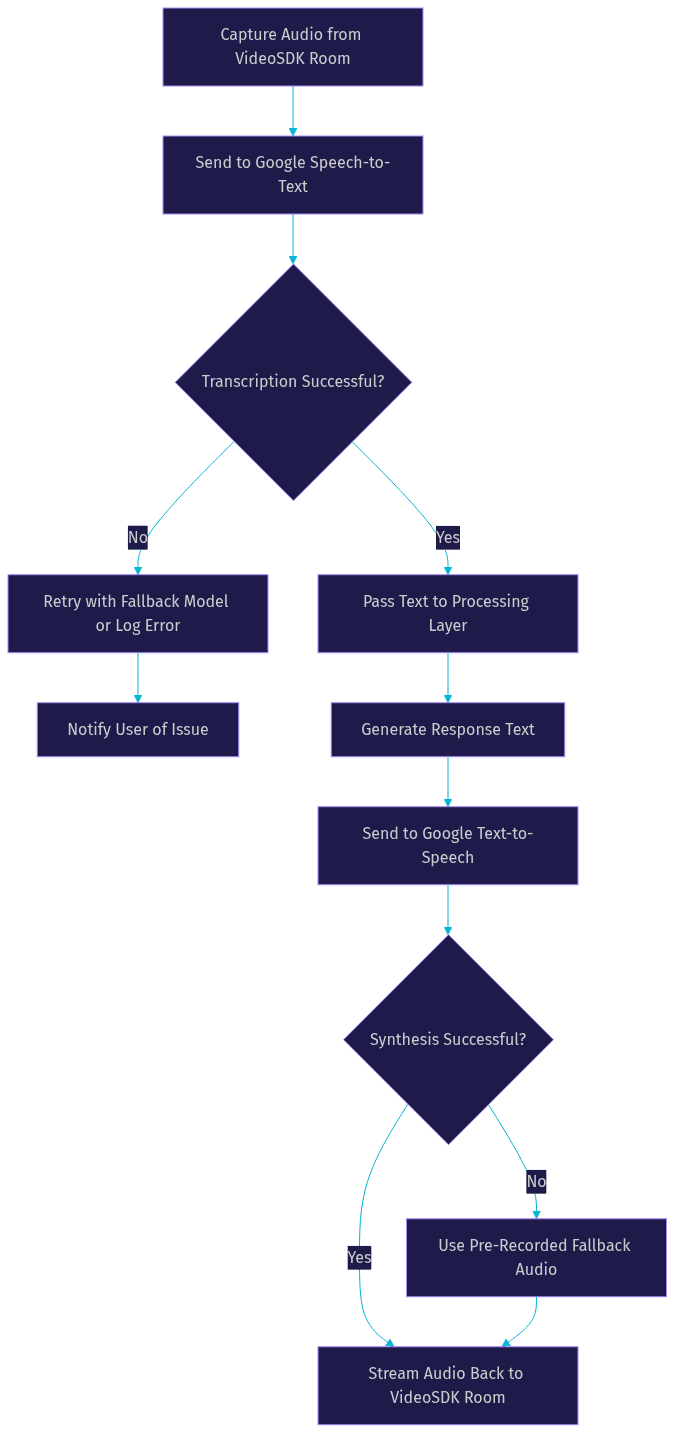
Here is the pipeline with error handling decision points:
Error Handling and Fallback Strategies
Transcription errors happen. Background noise, heavy accents, and overlapping speech can produce garbled text. Your pipeline should detect low-confidence transcripts and decide whether to proceed, ask the user to repeat, or fall back to a different model.
Google Speech-to-Text returns confidence scores for each transcription segment. A common pattern is to threshold on confidence: if the score is below a certain level, trigger a clarification request rather than acting on potentially incorrect input.
Synthesis errors are less common but still possible. Network interruptions, rate limiting, or temporary service unavailability can cause TTS calls to fail. A robust pipeline keeps pre-recorded fallback audio for critical phrases like error messages and greetings, so the user always hears something even if the TTS service is temporarily unavailable.
Production Best Practices
In production, several details separate a working prototype from a reliable system. Always use HTTPS for API calls. Manage authentication tokens properly by refreshing them before expiry and never hardcoding secrets in client-side code. Route requests to the regional endpoint closest to your users to minimize latency.
Implement monitoring for both services. Track transcription latency, confidence scores, and error rates. Track TTS time-to-first-audio and synthesis failures. Set up alerts for error rate spikes, which often indicate regional outages or quota exhaustion.
For scaling, Google Cloud handles horizontal scaling automatically, but you should request quota increases before you need them. A sudden traffic spike that exceeds your default quota will cause request failures, and quota increases can take time to process.
If you are building this pipeline inside a VideoSDK room, VideoSDK's Python SDK provides the backend integration layer for connecting your speech pipeline to live media streams. The REST API handles room management and session orchestration server-side.
Future Trends in Speech Recognition and Synthesis from Google
Google's speech roadmap is converging with its broader Gemini AI strategy. The Gemini Audio capabilities announced in 2025 and expanding through 2026 point toward unified multimodal models that handle speech input and output natively, without separate STT and TTS services. This could simplify pipelines significantly, though it also raises questions about latency, cost, and control compared to the current modular approach.
Expanded language support is a consistent theme. Google continues to add languages and improve accuracy on low-resource languages, which matters for developers building products for global markets. Real-time translation, where speech in one language is transcribed, translated, and synthesized in another language with minimal delay, is another active development area.
For developers building AI voice agents, VideoSDK's Conversational Graph offers a way to structure these conversations deterministically, regardless of which STT and TTS providers power the pipeline. As Google's models evolve, the orchestration layer remains stable.
Quick Recap
- Google Speech-to-Text converts audio to text using models like Chirp 3, with streaming, batch, and customization options for over 125 languages.
- Google Cloud Text-to-Speech generates natural audio from text across multiple voice tiers, with SSML for fine-grained control and streaming for low-latency playback.
- Most conversational AI applications need both services in a unified pipeline, connected through a processing layer like an LLM or business logic engine.
- Cost management depends on selecting the right model and voice tier for your quality requirements and monitoring usage against free-tier limits.
- Production systems require error handling, fallback audio, regional routing, token management, and proactive quota planning.
- VideoSDK provides the real-time transport layer that connects Google's speech services to live video and audio rooms.
Definitions Glossary
Speech-to-Text (STT): The process of converting spoken audio into written text. Google Cloud Speech-to-Text provides this through REST and streaming APIs with models like Chirp 3 for high-accuracy transcription.
Text-to-Speech (TTS): The process of converting written text into spoken audio. Google Cloud Text-to-Speech offers multiple voice tiers including HD, Neural2, WaveNet, and Standard voices with varying quality and pricing.
Chirp 3: Google's latest generation speech model family, used for both recognition and synthesis. It delivers improved accuracy on conversational audio and more natural-sounding synthesis compared to previous generations.
SSML (Speech Synthesis Markup Language): An XML-based markup language that controls how text-to-speech engines pronounce text. It supports pauses, emphasis, rate changes, pitch adjustments, and phoneme-level pronunciation control.
Speaker Diarization: A speech recognition feature that identifies and labels different speakers in an audio stream. It produces transcripts where each segment is attributed to a specific speaker.
Streaming Recognition: A mode of speech-to-text where audio is sent and transcribed in real-time chunks, producing partial results as the user speaks. This is essential for voice assistants and live captioning.
Key Takeaways
- Speech recognition and synthesis from Google form a complete voice pipeline, with Speech-to-Text handling transcription and Text-to-Speech handling generation across 125+ languages.
- The Chirp 3 model family represents Google's current state of the art for both recognition accuracy and synthesis naturalness, though developers should verify availability and pricing before committing.
- Streaming APIs for both services enable sub-second response times, which is critical for conversational AI, live captioning, and interactive voice applications.
- Production deployments require careful attention to error handling, fallback strategies, regional routing, and quota management to maintain reliability under load.
- VideoSDK's real-time communication platform provides the transport layer that connects Google's speech services to live audio and video rooms, with built-in transcription support and AI agent orchestration.
Conclusion
Google's speech recognition and synthesis services give developers a powerful, well-documented foundation for building voice-enabled applications. The Chirp 3 model family, streaming APIs, and broad language coverage make this stack suitable for everything from meeting transcription to conversational AI agents. The key to success is treating STT and TTS not as isolated APIs but as components in a carefully designed pipeline with proper error handling, fallback strategies, and production monitoring.
If you are building a real-time voice application, VideoSDK provides the live audio transport, room management, and AI agent orchestration layer that connects Google's speech services to your users. You can start with the VideoSDK quickstart guide or explore the AI Voice Agent documentation to see how Google STT and TTS fit into a complete agent pipeline. Sign up at app.videosdk.live/login to get started with free credits.
What are you building with Google's speech services? Drop a comment and let me know what kind of voice application you are working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ