


Speech recognition and synthesis are the two halves of a voice interface: automatic speech recognition (ASR) converts spoken audio into text, and text-to-speech (TTS) converts text back into natural spoken audio. Modern neural models have pushed both tasks to production-grade accuracy and naturalness, and pipelines that chain them with a language model now power real-time speech AI agents. This guide walks through the models, toolkits, evaluation metrics, and architecture decisions you need to build one yourself, including how platforms like VideoSDK connect these pipelines to live rooms and calls.
Introduction
Every time you dictate a message, hear a navigation app speak a direction, or talk to a voice assistant, two AI systems are working back to back. One listens, the other speaks. Speech recognition and synthesis have moved from research curiosities to the backbone of accessibility tools, customer support automation, podcast production, and real-time AI agents that hold actual phone conversations.
What changed is scale and latency. Modern neural speech models transcribe conversational audio with word error rates in the single digits and generate speech nearly indistinguishable from human voices, all fast enough to hold a live conversation. That combination unlocked a wave of products: AI receptionists, live translation, voice-controlled interfaces, and agents that join video calls as participants.
If you are building anything with a voice, you need to understand both halves of the pipeline, how they fit together, and where the real trade-offs live. That is exactly what this guide covers.
Understanding Speech Recognition and Synthesis
Speech recognition and synthesis are inverse problems sharing one medium: audio. Recognition maps an audio signal to its linguistic content. Synthesis maps linguistic content back to an audio waveform. Both were historically treated as separate disciplines with separate tooling, but modern architectures increasingly share components, training data, and even model backbones.
What is Speech Recognition?
Automatic speech recognition is defined as the task of converting a spoken audio stream into a sequence of words. ASR works by combining an acoustic model, which maps raw audio features to phonetic or subword units, with a language model, which scores plausible word sequences. Modern end-to-end neural models fold both roles into a single transformer trained on paired audio-text data, producing token-by-token output directly from the waveform. Typical output is a transcript, often with word-level timestamps and confidence scores that downstream systems can use for correction or alignment.
What is Speech Synthesis?
Text-to-speech is defined as the task of generating a spoken audio waveform from input text. TTS works by first converting text into linguistic features such as phonemes, stress, and prosody, then generating an audio waveform conditioned on those features. Older parametric and concatenative systems stitched together recorded speech fragments, which sounded robotic. Modern neural approaches use sequence-to-sequence models with vocoders that synthesize waveforms directly, producing natural intonation, and in some systems, voice cloning from seconds of reference audio.
Core Technologies and Models
The gap between traditional and neural approaches explains most of the quality jump you hear in modern systems.
Traditional vs Neural Approaches
Traditional pipelines were modular and rule-heavy: hand-engineered audio features fed hidden Markov models, and synthesis relied on unit selection from recorded speech databases. They were interpretable and lightweight, but brittle with accents, noise, and expressive speech. Deep-learning models replaced the entire stack with end-to-end training on thousands of hours of audio. The result is dramatically better robustness: a single neural ASR model handles multiple accents and noisy conditions without per-domain tuning, and neural TTS produces prosody that follows punctuation and context rather than flat, monotone output. The cost is compute: neural models need GPUs for training and, for the largest ones, for inference too.
State-of-the-Art Models
As of 2026, a few model families dominate. OpenAI's Whisper remains the reference open-weight ASR model, strong across dozens of languages and robust to noise. NVIDIA's NeMo and Baidu's PaddleSpeech provide full training and fine-tuning frameworks for both ASR and TTS. On the synthesis side, ElevenLabs leads commercial voice naturalness and cloning, while Microsoft's VALL-E line and Google's Gemini-based TTS pushed zero-shot cloning and expressive control forward. Emerging unified audio-language models, including OpenAI's Realtime API and Google's Gemini Live, process speech in and speech out natively, collapsing the STT-LLM-TTS chain into a single model. Independent leaderboards such as Artificial Analysis's Speech Arena and Hugging Face's Open ASR Leaderboard are the best places to compare current versions, since model rankings shift every few months.
Building an End-to-End Speech Recognition and Synthesis Pipeline
A production speech pipeline is a chain of stages, each with its own latency budget and failure modes. Getting the order right matters as much as picking the models.
Voice Activity Detection (VAD)
VAD is the first gate in any real-time speech pipeline. It decides, on short audio windows, whether a segment contains speech or silence, so you only send meaningful audio downstream. Without VAD, you burn compute transcribing background noise and your agent responds to coughs and keyboard clicks. Common open-source options include WebRTC's built-in VAD, Silero VAD, and NVIDIA NeMo's VAD models, which trade off latency, accuracy, and CPU footprint. Good VAD also drives turn detection: the pause length that signals a speaker has finished talking.
Speech-to-Text (STT)
Model selection for STT is a trade-off between accuracy, latency, and cost. Batch models like Whisper maximize accuracy but process whole utterances, adding seconds of delay. Streaming models, such as Deepgram's Nova series, AssemblyAI's Universal model, and Google's streaming recognizers, emit partial hypotheses as audio arrives, enabling sub-second first-token latency. Match the choice to your use case: voicemail transcription can be batch, live agents cannot. Also decide whether you need word timestamps, diarization, or multilingual output, since not every model offers all three.
Language Understanding / LLM (optional)
A language model between STT and TTS adds value whenever the response must be generated rather than looked up. For a read-aloud feature, skip it: pipe the transcript straight to TTS. For a conversational agent, the LLM turns a raw transcript into a coherent reply, handles context across turns, and can call external tools. This is the architecture behind modern speech AI agents, where the LLM is the brain and STT and TTS are its ears and mouth.
Text-to-Speech (TTS)
TTS selection revolves around voice selection, prosody control, and streaming. Streaming TTS emits audio in chunks as text arrives, which is essential for conversational latency: waiting for a full sentence before speaking adds a perceptible lag. Voice selection ranges from prebuilt voices to custom voices and cloning, where a short reference sample defines the timbre. Prosody control lets you shape emphasis, pace, and emotion, which matters for brand consistency and expressive agents. Most cloud TTS APIs expose these as parameters rather than code-level configuration.
The full pipeline looks like this:
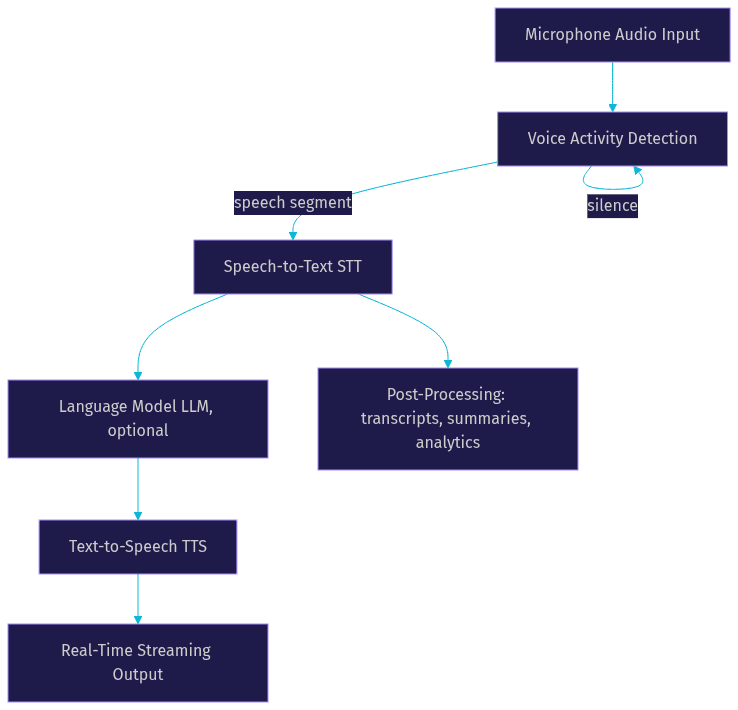
If you are building this pipeline into a live product, VideoSDK's AI Agents documentation describes how an agent worker connects this STT-LLM-TTS chain directly into a real-time room, so users on web, mobile, or phone can talk to it with sub-second interaction. The same platform provides real-time transcription for live calls, which pairs recognition and synthesis into one workflow.
Cloud Services vs Open-Source Solutions
The biggest architectural decision is whether to consume speech AI as a managed API or run open models yourself. Both paths are viable in 2026; they optimize for different constraints.
Overview of Major Cloud APIs
The major cloud speech APIs each have distinct strengths. Google Cloud TTS offers broad language coverage and solid quality with WaveNet-derived voices. Azure Speech provides strong customization, custom neural voices, and tight enterprise integration. AWS Polly is the workhorse option: reliable, cheap, and available in many regions. ElevenLabs leads on naturalness and voice cloning, at a premium price per character. OpenAI's Realtime TTS, part of its Realtime API, targets conversational agents with low-latency speech in and speech out. Cloud APIs win on time-to-market: you get production-grade quality, scaling, and SLAs without touching a GPU. You pay per usage, and your audio transits a third party, which matters for healthcare, legal, and finance workloads.
Open-Source Toolkits
Open-source toolkits give you ownership of the full stack. NVIDIA NeMo is the most complete framework for training and fine-tuning ASR and TTS models, best suited to teams with GPU infrastructure. PaddleSpeech offers a broad model zoo with lighter deployment requirements. Silero provides compact, fast VAD and STT models that run on CPU, ideal for edge deployment. Newer projects like VibeVoice and community speech agent frameworks focus on streaming synthesis and agent orchestration. Licensing is generally permissive (MIT or Apache style), but verify each model's license before commercial use, since some weights carry non-commercial restrictions. Open-source wins on cost at scale, data privacy, and customization; it loses on operational burden: you own inference serving, scaling, and monitoring.
Choosing the Right Solution for Your Project
Criteria: latency, language support, customization, cost, deployment
Use five criteria to decide. Latency: conversational products need streaming STT and TTS with sub-second response; batch products do not. Language support: check actual measured quality for your target languages, not just the supported list, since coverage varies widely for low-resource languages. Customization: decide early whether you need custom vocabulary, domain fine-tuning, or a cloned voice, because these eliminate some providers immediately. Cost: model total cost at your expected volume, including per-minute STT, per-character TTS, and GPU hosting if self-hosting. Deployment: determine whether audio can leave your infrastructure, whether you need on-prem or edge inference, and whether your target platform supports the runtime you choose.
Decision Matrix
This matrix summarizes the trade-off:
| Criterion | Cloud APIs | Open-Source Toolkits |
|---|---|---|
| Latency | Low, streaming available | Low with streaming models, more tuning needed |
| Language support | Broad, verified quality | Broad for ASR, thinner for TTS in low-resource languages |
| Customization | Limited to vendor options | Full fine-tuning and voice training |
| Cost | Predictable per-use, scales linearly | High fixed cost, low marginal cost |
| Deployment | Vendor cloud only | On-prem, edge, air-gapped |
| Best for | Fast time-to-market, variable volume | High volume, privacy-sensitive, custom needs |
The most important row is deployment: if your audio cannot leave your infrastructure, the cloud column is off the table entirely, and the decision is made for you.
Evaluation Metrics and Benchmarking
You cannot choose models by vendor marketing pages. Measure them yourself, on your data, with standard metrics. Word error rate (WER) measures ASR accuracy as the share of substituted, inserted, and deleted words. Mean opinion score (MOS) measures TTS naturalness through human ratings on a 1-to-5 scale; neural TTS systems now routinely score above 4. Latency is measured end-to-end: time from speech onset to first audible response. Real-time factor (RTF) measures processing speed, where a value below 1 means the system transcribes faster than real time.
For reproducible benchmarks, use open datasets such as LibriSpeech for clean English ASR, Common Voice for multilingual coverage, and EARS-Wisdom or AMI for noisy, conversational audio. Run every model on identical audio slices, report WER with confidence intervals, and record model versions and hardware. Community leaderboards like the Hugging Face Open ASR Leaderboard and Artificial Analysis's Speech Arena provide useful baselines, but your domain audio will behave differently than clean benchmark sets.
Practical Implementation Tips
Data Preparation and Quality
Garbage in, garbage out applies doubly to speech. Clean your training and evaluation audio: normalize sample rates, remove clipping, and trim leading and trailing silence. For fine-tuning, accurate transcript labels matter more than volume; a thousand well-aligned hours beat ten thousand noisy ones. Data augmentation, adding background noise, speed perturbation, and room reverb, dramatically improves robustness to real-world conditions without collecting new audio.
Handling Accents and Noisy Environments
Accents and noise are where naive deployments fail. Apply noise suppression before STT, either with a DSP-based filter or a neural denoiser; most modern speech SDKs, including VideoSDK's, ship built-in noise suppression you can enable per track. Multi-microphone arrays with beamforming help on hardware products. For accents, prefer models trained on diverse data (Whisper-class models are strong here) and fine-tune on your actual user population's speech rather than assuming benchmark performance transfers.
Real-time Streaming Considerations
Streaming is where architecture matters most. Buffer audio in short windows, roughly 20 to 40 milliseconds, and send them to VAD and streaming STT as they arrive rather than accumulating whole utterances. WebRTC is the right transport for live voice because it handles jitter, packet loss, and adaptive bitrate natively; plain WebSockets work for controlled networks but degrade on poor connections. For the lowest latency, run VAD and sometimes the full pipeline on-device or at the edge, sending only recognized text or compressed audio upstream. VideoSDK's real-time communication SDKs handle the WebRTC layer for you, which is why speech AI agents built on it join live rooms as first-class participants rather than bolted-on HTTP services.
Future Trends and Emerging Research
Three trends will reshape speech AI through the rest of the decade. First, unified audio-language models: instead of chaining STT, LLM, and TTS, single models process and generate speech natively, cutting latency and preserving tone and emotion that text transcription destroys. Second, multimodal LLMs that combine speech with vision, enabling agents that can see a shared screen while discussing it. Third, low-resource language synthesis: research on few-shot voice generation is bringing usable TTS to languages that commercial providers have long ignored, a meaningful accessibility win.
Alongside these, speech AI ethics is moving from afterthought to requirement. Voice cloning raises consent and impersonation concerns, and regulators are increasingly requiring disclosure when a voice is synthetic. If you are building voice products, build consent capture and synthetic-voice disclosure in from the start, not after launch.
Definitions Glossary
Automatic Speech Recognition (ASR): The task of converting spoken audio into text. Modern ASR models like Whisper produce transcripts with word-level timestamps and confidence scores.
Text-to-Speech (TTS): The task of generating a spoken audio waveform from input text. Neural TTS produces natural prosody and, with cloning, can replicate a specific voice from a short reference sample.
Voice Activity Detection (VAD): A lightweight gate that classifies short audio windows as speech or silence. VAD prevents wasted compute on noise and drives turn detection in conversational agents.
Word Error Rate (WER): The standard ASR accuracy metric, counting substituted, inserted, and deleted words as a share of the total. Lower is better; production systems target single digits on clean audio.
Real-Time Factor (RTF): A processing speed metric where values below 1 mean the system processes audio faster than it arrives. Essential for streaming deployment feasibility.
Speech AI Agent: A pipeline combining STT, an LLM, and TTS so users can hold live voice conversations with an AI. VideoSDK's Agent SDK connects these pipelines directly into real-time rooms and phone calls.
Key Takeaways
- Speech recognition and synthesis are inverse tasks that, chained with a language model, form the complete voice interface behind modern speech AI agents.
- Streaming is the deciding architecture: conversational products need VAD, streaming STT, and streaming TTS to hit sub-second response times.
- Cloud APIs win on time-to-market; open-source toolkits like NeMo and PaddleSpeech win on cost at scale, privacy, and customization.
- Evaluate models yourself with WER, MOS, latency, and RTF on open datasets and your own domain audio, rather than trusting vendor benchmarks.
- Platforms like VideoSDK handle the real-time transport layer, letting speech pipelines join live video and audio rooms as participants with built-in noise suppression and transcription.
Conclusion
Speech recognition and synthesis have crossed the threshold where voice is a first-class interface, not a novelty. The pipeline is well understood: VAD gates the audio, STT transcribes it, an optional LLM reasons over it, and TTS speaks the response. Your job is matching models and deployment choices to your latency, language, cost, and privacy constraints, then measuring results on real data rather than marketing claims.
The fastest way to learn is to prototype. Pick one cloud API or one open toolkit, wire the four stages together, and talk to it. If you want your agent to live inside real calls and video rooms, start with the VideoSDK AI Agents quickstart and the code samples library, or grab a free API key at app.videosdk.live and join the VideoSDK Discord community to compare notes with other builders.
What are you building with speech recognition and synthesis? Drop a comment, I'd love to hear what kind of voice use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ