


Open source speech recognition refers to automatic speech recognition (ASR) models and toolkits whose source code and model weights are publicly available under permissive licenses, letting developers transcribe speech without paying per-minute API fees or sending audio to third-party clouds. Leading projects in 2026 include Whisper, FunASR, PaddleSpeech, Moonshine, and Qwen3-ASR. If you need real-time transcription inside a live application, you can pair any of these engines with VideoSDK's real-time transcription features.
Every product team eventually hits the same wall with cloud speech APIs: the per-minute billing grows with your user base, the audio you transcribe leaves your infrastructure, and the vendor can change pricing or deprecate a model with little notice. For healthcare, legal, and enterprise collaboration products, that last point is not a hypothetical risk, it is a compliance blocker.
Open source speech recognition has matured dramatically. In 2026, community-driven ASR models routinely match or exceed proprietary APIs on standard benchmarks, and several run comfortably on a laptop CPU. This guide walks through what open source speech recognition actually is, the leading projects worth your time, a decision framework for choosing between them, and how to assemble a production-ready pipeline.
What Is Open Source Speech Recognition?
Open source speech recognition is defined as automatic speech recognition technology where the acoustic model, inference code, and often the training data pipeline are published under licenses that permit free use, modification, and redistribution. Open source speech recognition works by converting an audio waveform into text through three cooperating components: an acoustic model that maps audio features to phonetic probabilities, a language model that scores plausible word sequences, and a decoder that searches for the most likely transcription.
The difference from proprietary APIs is structural, not just financial. With a closed API, you send audio over the network and receive text back, with no visibility into how it was produced. With an open source ASR model, you control where inference runs, which model version you use, and how the output is post-processed. That control is what makes offline speech recognition and privacy-focused speech recognition practical at all.
Benefits of Using Open Source Speech Recognition
Open source speech recognition removes the two biggest constraints of cloud APIs: recurring cost and data exposure. The practical advantages compound quickly for teams building speech features into real products.
- Cost predictability. There are no per-minute charges. A self-hosted model transcribing ten thousand hours per month costs the same as one transcribing ten, apart from compute.
- Data privacy. Audio never leaves your infrastructure, which matters for telehealth consultations, legal depositions, and internal meetings. Privacy-focused speech recognition is now a procurement requirement in several regulated industries.
- Customizability. You can fine-tune open source ASR models on domain vocabulary, accents, or languages the original training set underrepresents.
- Offline capability. Edge speech recognition runs on devices with no network connectivity, enabling on-device transcription for mobile apps and IoT hardware.
- Community support. Active projects ship fixes, new model checkpoints, and benchmark results continuously, and community-driven speech models improve faster than any single vendor's release cycle.
Leading Open Source Speech Recognition Projects
The open source speech recognition landscape in 2026 is deep, but six projects stand out for production readiness, documentation quality, and community momentum. Each occupies a different point on the latency, accuracy, and hardware trade-off curve.
Qwen3-ASR
Qwen3-ASR is a multilingual speech recognition model family from the Qwen project, released in multiple parameter sizes so developers can trade accuracy against inference cost. Its language coverage spans major global languages, and a standout feature is built-in forced alignment, which maps each word in the transcript to a precise timestamp in the source audio. That makes it a strong fit for subtitle generation and searchable transcript indexes.
Whisper (OpenAI)
Whisper remains the most widely adopted open source ASR model in the world. Trained on roughly 680,000 hours of multilingual audio, it handles dozens of languages plus robust translation, and it ships in sizes ranging from a tiny model that runs on a laptop to a large model that competes with commercial APIs on accuracy. Its community adoption is its superpower: nearly every speech toolkit, transcription app, and subtitle tool built since its release integrates Whisper somewhere. For a general-purpose, well-understood baseline, it is still the default choice.
PaddleSpeech
PaddleSpeech, maintained by Baidu's PaddlePaddle team, is a full open source speech recognition toolkit rather than a single model. Beyond batch transcription, it offers streaming ASR suitable for real-time transcription, automatic punctuation restoration, text normalization, and speaker verification components. Its strength is breadth: one toolkit covers speech-to-text, text-to-speech, and speaker tasks with consistent APIs. Teams building conversational products in Chinese and English particularly benefit from its punctuation restoration, which turns raw decoder output into readable, well-formed transcripts without a separate post-processing service.
Moonshine Voice
Moonshine Voice targets on-device, low-latency speech recognition. Its models are deliberately small and fast enough to run real-time transcription on consumer hardware, including laptops and single-board computers, without a GPU. Multi-platform support across desktop and embedded environments makes it a natural fit for edge speech recognition scenarios: voice assistants, offline dictation, and hardware products where round-tripping to a cloud API would add unacceptable delay. Its small footprint also means cold-start latency is minimal, which matters for wake-word-style interactions.
FunASR
FunASR, from Alibaba's speech team, is an industrial-grade open source speech recognition toolkit designed for production workloads. It bundles voice activity detection, speaker diarization, punctuation, and timestamping alongside the core ASR models, so a single deployment can produce a fully formatted, speaker-attributed transcript. Its edge deployment variants bring the same pipeline to on-device scenarios. For meeting transcription and call-center analytics, where knowing who said what and when is as important as the words themselves, FunASR's integrated diarization is a genuine differentiator.
OpenASR
OpenASR takes a local-first approach: a command-line oriented tool with a curated model catalog, designed so transcription happens entirely on your machine with no network calls. Its privacy focus makes it a good entry point for developers evaluating offline speech recognition before committing to a full pipeline, and its model catalog lets you swap engines without rewriting your integration.
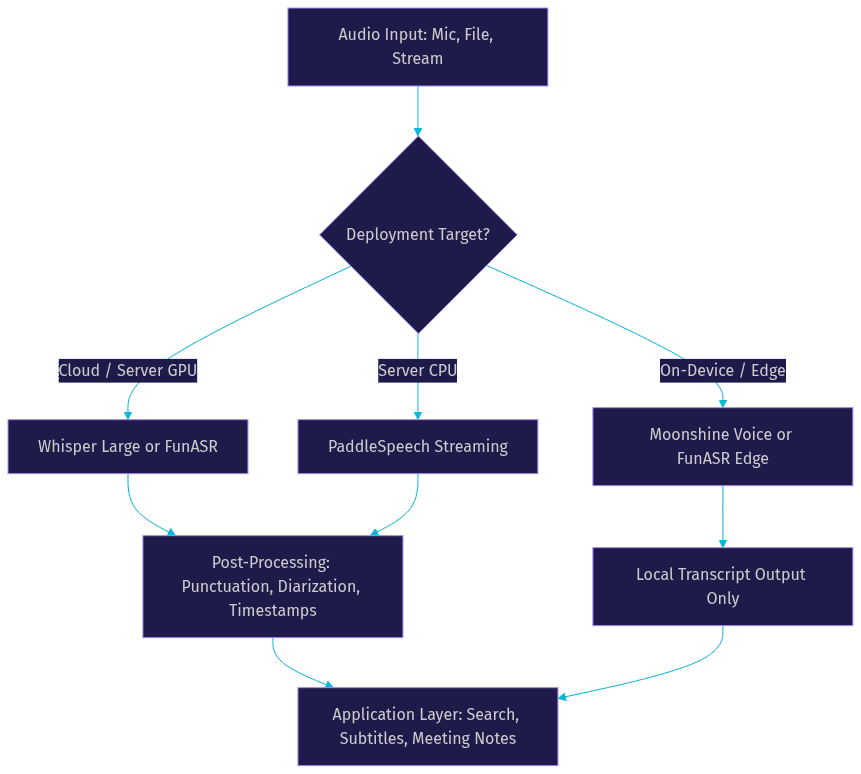
The diagram below shows how these projects map onto a common architecture and where each typically deploys:
How to Choose the Right Open Source Speech Recognition Solution
Choosing an open source speech recognition engine is a matching exercise between your constraints and each project's design center. Work through these six dimensions in order.
- Language support. Whisper and Qwen3-ASR cover the widest language range. PaddleSpeech and FunASR are strongest in Chinese and English. If you need a long-tail language, check each project's published benchmark results for that language specifically.
- Latency requirements. Batch transcription of recorded files tolerates seconds of delay; live captioning does not. For real-time transcription, prioritize streaming-capable engines like PaddleSpeech or the low-latency Moonshine models rather than batch-oriented large models.
- Hardware constraints. GPU-accelerated ASR unlocks the large Whisper and FunASR models; CPU-only speech transcription is entirely viable with smaller models. Decide your hardware budget before falling in love with a model.
- Licensing. Speech recognition licensing varies from fully permissive to restrictions on commercial use or model weights. Read the actual license of both the code and the model weights, which are sometimes licensed separately.
- Community activity. A project with recent commits, answered issues, and fresh model releases will still be maintainable in two years. Check the repository's release history before committing.
- Integration ease. Some projects are model checkpoints with minimal tooling; others are complete toolkits. Match the level of support to your team's speech expertise.
Setting Up an Open Source Speech Recognition Pipeline
A production open source speech recognition pipeline follows five stages, and the choices you make at each stage determine whether the result is a demo or a dependable system.
Select a model. Start from your latency and hardware constraints, not from leaderboard positions. A smaller model that meets your accuracy bar on your audio beats a larger model that is marginally more accurate but too slow or too expensive to run. Validate candidates on a sample of real audio from your actual users, including noisy segments, before committing.
Install dependencies. Every project publishes its runtime requirements, and version mismatches are the most common source of setup failures. Pin your dependency versions and prefer containerized deployment so the environment is reproducible across machines. A container image that bundles the model, runtime, and dependencies eliminates the classic "works on my machine" failure mode entirely.
Prepare audio. ASR models are trained on specific sample rates and channel configurations, so resampling and channel conversion happen before inference. Trim leading silence, normalize loudness where the toolkit expects it, and split very long recordings into segments that fit the model's context window. Voice activity detection, built into FunASR and available separately, prevents wasting compute on silent stretches.
Run inference. On GPU, batch multiple audio segments together to maximize utilization; on CPU, prefer smaller models and expect real-time-factor performance well above one for batch workloads. For streaming use cases, establish a persistent inference service rather than launching the model per request, since model loading dominates cold-start cost.
Handle output. Raw decoder output is rarely the finished product. Apply punctuation restoration, attach word-level timestamps, run speaker diarization where needed, and structure the transcript for downstream consumption. If your transcripts feed a live application, such as a video calling or streaming platform, consider how they surface in real time. VideoSDK's real-time transcription capabilities handle this integration layer natively for live sessions, so you can combine an open source engine for batch work with a managed pipeline for live calls. See the VideoSDK transcription documentation for details.
Real-World Use Cases for Open Source Speech Recognition
Open source speech recognition already powers production features across nearly every software category.
- Meeting transcription. FunASR's diarization and punctuation pipeline turns raw call recordings into attributed, readable meeting notes, deployed entirely on internal infrastructure.
- Voice assistants. Moonshine's on-device models enable wake-word and command recognition with sub-second response, no network required.
- Live stream captioning. Streaming ASR engines paired with a low-latency video platform produce captions close enough to real time to be readable, a combination used widely in edtech and virtual events.
- Multilingual subtitles. Whisper's translation capability plus Qwen3-ASR's forced alignment generates accurately timed subtitles across dozens of languages from a single source video.
- On-device applications. Edge speech recognition brings dictation and voice control to mobile apps and IoT devices where connectivity is unreliable or privacy demands local processing.
Common Challenges in Open Source Speech Recognition and How to Overcome Them
Every open source speech recognition deployment hits friction. Knowing the failure modes in advance shortens the path to production.
Noisy audio accuracy. Models benchmarked on clean speech degrade sharply on real-world recordings. The fix is validation on representative audio, plus preprocessing like noise suppression before inference. Fine-tuning on a few hours of your actual audio typically recovers most of the lost accuracy.
Dialects and accents. Community-driven speech models cover standard pronunciations well but underperform on strong regional accents. Fine-tuning with open source speech datasets containing those accents, or choosing a model family with broader training data, closes the gap.
Scaling inference. A single GPU serving one request at a time wastes capacity. Batch inference, queue-based request handling, and horizontal scaling of inference workers turn a laptop experiment into a service that absorbs traffic spikes.
Model updates. New checkpoints arrive constantly, and upgrading can shift output formatting or accuracy. Pin model versions in production, evaluate new releases against a fixed test set, and roll out changes deliberately rather than tracking the latest release.
Licensing constraints. Some model weights carry non-commercial or attribution requirements even when the code is permissive. Audit both licenses before shipping a commercial product, and document the versions you rely on.
Future Trends in Open Source Speech Recognition
Three trends are reshaping open source speech recognition right now. First, low-resource language models are shrinking the data requirement for adding new languages, with community efforts producing usable ASR for languages that had no practical option two years ago. Second, integration with large language models is turning raw transcripts into structured output: summaries, action items, and structured data extraction, all built on the same open source stack. Third, on-device quantization is pushing larger model quality onto phone and edge hardware, expanding what offline speech recognition can do without a server. Finally, community-driven benchmark initiatives are making speech recognition model comparison more trustworthy, giving developers shared evaluation sets rather than vendor-curated results.
Definitions Glossary
Open source speech recognition: Automatic speech recognition technology whose models and code are published under licenses permitting free use and modification, enabling self-hosted and offline transcription.
ASR (Automatic Speech Recognition): The general field of converting spoken audio into text, encompassing both proprietary APIs and open source models.
Speaker diarization: The process of segmenting a transcript by who spoke, labeling each segment with a speaker identity, essential for meeting and call transcription.
Forced alignment: Mapping each word in a transcript to its precise timestamp in the source audio, used for subtitles and searchable media.
Voice activity detection (VAD): Detecting which portions of an audio stream contain speech, so inference compute is spent only on relevant segments.
Real-time transcription: Converting speech to text with low enough latency that output appears while the speaker is still talking, as in live captioning.
Key Takeaways
- Open source speech recognition eliminates per-minute API costs and keeps audio on your own infrastructure, which is decisive for privacy-sensitive and high-volume products.
- Whisper, FunASR, PaddleSpeech, Moonshine, Qwen3-ASR, and OpenASR each target a different point on the latency, accuracy, and hardware trade-off curve, so match the engine to your constraints rather than to a leaderboard.
- Streaming and on-device engines like PaddleSpeech and Moonshine enable real-time transcription and edge deployment, while larger batch models maximize accuracy on recorded audio.
- A production pipeline needs more than a model: audio preparation, punctuation, timestamps, diarization, and reproducible containerized deployment determine whether the system is dependable.
- For live sessions inside video or streaming applications, pairing an open source engine with VideoSDK's real-time transcription capabilities covers the integration layer that batch toolkits leave to you.
Conclusion
Open source speech recognition has crossed the threshold from interesting experiment to production-grade infrastructure. The six projects covered here cover the full spectrum from GPU-heavy batch accuracy to sub-second on-device inference, and the decision framework in this guide should narrow your shortlist quickly. Start by validating one or two candidates on your own audio, containerize the winner, and build from there. If your transcripts need to surface live inside a calling or streaming product, explore VideoSDK's real-time transcription features alongside your self-hosted engine, and grab a free tier at app.videosdk.live/login to test it. What are you building with open source speech recognition? Drop a comment, I'd love to hear which engine you chose and why.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ