


Google Speech to Text is Google Cloud's speech recognition API that converts audio into text using machine learning models, supporting more than 85 languages across streaming, batch, and channel-based transcription modes. It offers specialized models for phone audio, video, and general speech, plus speech adaptation for boosting domain-specific vocabulary. Developers can start with the free tier and scale to production workloads with per-minute pricing, and the official documentation covers every integration path from mobile apps to call-center pipelines.
Accurate transcription is now a feature, not a nice-to-have. Call centers mine conversations for sentiment, video platforms generate captions automatically, and voice assistants depend on low-latency recognition to feel responsive. Get transcription wrong and the downstream product breaks: search returns garbage, captions mislead, and agents misunderstand users.
Google Speech to Text, part of Google Cloud's speech recognition API family, is one of the most widely deployed cloud STT services in 2026. It powers everything from real-time meeting transcription to batch processing of archived call recordings. This guide covers how it works, how to choose the right model, what it costs, and how to get production-grade accuracy, without the marketing fluff.
What Is Google Speech to Text?
Google Speech to Text is defined as a cloud-based speech recognition API that converts audio input into machine-readable text using neural network models trained on large multilingual corpora. It works by accepting audio through either a synchronous request (short audio, one response), an asynchronous batch job (long recordings), or a bidirectional streaming channel (live audio, incremental results).
The service exposes three core capabilities. First, broad language coverage: more than 85 languages and regional variants, from Brazilian Portuguese to Indian English. Second, flexible delivery modes: you can transcribe a 10-second voice clip, a 3-hour webinar recording, or a live microphone feed with word-level timestamps. Third, customization: speech adaptation lets you bias the recognizer toward domain vocabulary, like product names or medical terminology.
For developers building real-time communication apps, Google Speech to Text can also be paired with RTC platforms. VideoSDK, for example, supports real-time transcription inside its video calling SDK, and its Python SDK is designed for connecting custom STT and AI pipelines directly to live media streams, so Google's recognizer can be slotted into an in-call transcription flow.
Key Features Overview
Google Speech to Text's feature set centers on four pillars: language breadth, model specialization, vocabulary customization, and real-time delivery. Each pillar maps to a concrete engineering decision you'll make during integration.
Language and Dialect Coverage
The service supports more than 85 languages and variants, with regional models that distinguish, for example, US English from UK or Australian English. This matters because accent and dialect significantly affect word error rate. A recognizer tuned for one variant can mis transcribe another at rates that break downstream NLP. For multilingual products, Google also supports automatic language detection in some configurations, letting a single pipeline serve a global user base without per-user language selection.
Model Types: Standard, Enhanced, Phone Call, and Video
Google Speech to Text offers several recognizer models, and choosing the right one is the single highest-impact accuracy decision you'll make. The default model handles general audio reasonably well. The phone call model is optimized for 8kHz narrowband telephony audio, where standard models degrade badly. The video model is tuned for recordings with background music, multiple speakers, and studio-quality source audio. Enhanced versions of several models use a more advanced neural architecture and deliver measurably lower word error rates, at a higher price per minute.
In practice, teams integrating telephony workloads consistently find that switching from the default model to the phone call model cuts error rates dramatically on call-center audio, because the model was trained on exactly that acoustic profile.
Speech Adaptation and Custom Vocabulary
Speech adaptation lets you supply phrase hints and custom classes that bias recognition toward terms the base model doesn't know well. If your app transcribes medical consultations, boosting drug names and clinical terminology prevents the recognizer from substituting phonetically similar common words. Adaptation supports single phrases, multi-word phrases, and class tokens (like dollar amounts or addresses), and it works across both streaming and batch modes. This is the feature that separates a demo from a production system in specialized domains.
Real-Time Streaming and Word-Level Timestamps
Streaming recognition delivers interim results while the user is still speaking, which is what makes live captioning and voice assistants feel instant. Word-level timestamps attach a start and end time to every recognized word, enabling karaoke-style captions, in-video search, and precise subtitle alignment. Combined with automatic punctuation, these capabilities make Google Speech to Text a strong fit for live transcription inside communication apps, a pattern VideoSDK users implement with the real-time transcription features available across its SDKs.
How It Works: Architecture
Google Speech to Text works by sending audio from your application through a client library to Google's recognition service, which returns text results either once (batch) or incrementally (streaming). The streaming path uses a gRPC bidirectional channel: your client pushes audio chunks while simultaneously receiving partial and final transcription results over the same connection.
The end-to-end flow looks like this: audio is captured from a microphone or loaded from a file, optionally preprocessed (resampled, denoised, converted to a supported encoding), then sent to the API with a configuration object specifying language, model, and adaptation settings. The service runs the audio through its neural recognizer and returns a transcript with confidence scores and timestamps.
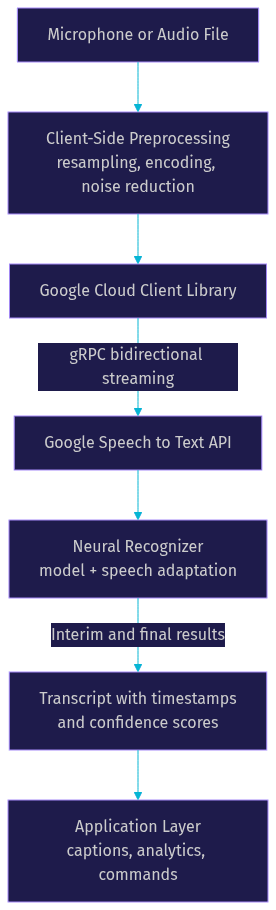
Two architectural details matter for production. First, streaming sessions have a duration limit, so long-running live audio requires session rotation logic in your client. Second, authentication flows through Google Cloud IAM, meaning your application authenticates with service-account credentials rather than API keys alone, which affects how you deploy and secure backend services.
Choosing the Right Model
Model selection is a decision matrix driven by your audio source, not by gut feel. Phone audio (8kHz, single channel, compressed) belongs on the phone call model. Studio or recorded video with multiple speakers belongs on the video model. Clean, general-purpose audio works on the default model, and enhanced variants raise accuracy where the extra cost per minute is justified.
The trade-off is always accuracy versus cost. Enhanced models and specialized models cost more per minute than the default, but the accuracy gain often reduces downstream correction effort, human review time, or user frustration enough to pay for itself. A practical rule from deployed systems: run a representative sample of your real audio through two candidate models, measure word error rate against a human-labeled baseline, and let the data pick the model. Vendor benchmarks, including Google's own published accuracy figures, are useful starting points but never substitute for testing on your actual audio distribution.
Pricing and Cost Management
Google Speech to Text prices transcription in 15-second increments, with different rates for the default model, enhanced models, and the video model, and separate rates for streaming versus batch recognition. Batch processing of long recordings is generally cheaper per minute than streaming, which reflects the resource cost of holding a live channel open.
To estimate monthly spend, use the Google Cloud pricing calculator with your expected audio minutes, split by model type and delivery mode. A call center transcribing 50,000 minutes per month of phone audio on the phone call model has a very different bill than a video platform streaming 10,000 minutes on the video model. Two cost-control levers matter: first, only stream when you actually need live results, and use batch for archived audio; second, trim silence and non-speech segments before sending audio, since you're billed on submitted duration, not on speech duration.
Implementation Best Practices
Getting production-grade results from Google Speech to Text is mostly about disciplined audio handling and request configuration. The service is forgiving of imperfect audio, but every preprocessing mistake shows up as transcription errors.
Preparing Audio
Use a sample rate of at least 16,000 Hz for general and video audio, and match the native rate of your source (8,000 Hz for telephony) rather than upsampling, since upsampling adds no information. Prefer lossless or lightly compressed encodings where possible, and send mono audio unless speaker separation genuinely requires stereo, since stereo doubles payload size without improving recognition for most models. Removing background noise and normalizing volume before submission consistently improves accuracy on real-world recordings.
Configuring Requests
Every recognition request carries a configuration that specifies the language code, the model, and optional features like automatic punctuation and the enhanced-model flag. Always set the language code explicitly rather than relying on defaults, and enable automatic punctuation for any output that humans will read, since unpunctuated transcripts degrade readability and downstream NLP performance. When you use speech adaptation, keep phrase lists focused: hundreds of tightly relevant phrases outperform thousands of loosely related ones.
Handling Long Audio
Audio longer than roughly a minute cannot go through the synchronous interface and must use the batch path. For very long files, split audio into chunks at natural boundaries, ideally silence-detected pauses, and transcribe chunks as separate batch jobs. Overlap chunks by a second or two and deduplicate the boundary region so words spanning a cut aren't lost or doubled. This chunking strategy is also how you parallelize transcription of large archives.
Managing Asynchronous Jobs
Batch jobs are submitted, then polled for completion. The recommended pattern is exponential backoff polling: check job status at increasing intervals rather than tight loops, and retrieve results only once the job reports completion. For pipelines processing many files, maintain a job queue with per-job state tracking so a single failed job doesn't stall the batch, and persist raw API responses before post-processing so you can re-parse without re-paying for transcription.
Error Handling and Retries
The most frequent errors are permission failures from misconfigured IAM roles, invalid audio encoding mismatches (declaring an encoding that doesn't match the actual bytes), and quota exhaustion on streaming concurrent channels. Mitigation is straightforward: validate encoding parameters against your actual audio before submission, implement retries with exponential backoff for transient errors, and monitor quota dashboards so you request limit increases before traffic spikes rather than after. Session timeouts on long streams require client-side reconnection logic that re-establishes the streaming channel transparently.
Common Use Cases
Google Speech to Text fits five recurring production patterns, each leveraging a different capability of the service.
Call-center analytics uses the phone call model on archived recordings to extract transcripts for sentiment analysis, compliance review, and agent coaching. The narrowband-optimized model is the differentiator here.
Video captioning uses the video model with word-level timestamps to generate aligned subtitles for recorded content, where timestamp accuracy determines whether captions sync with speech.
Voice-controlled IoT uses streaming recognition to turn spoken commands into device actions, where low latency matters more than perfect accuracy, since command grammars are small and adaptation-boosted.
Accessibility subtitles use live streaming transcription to caption conversations and events in real time, a pattern that pairs naturally with RTC platforms; VideoSDK's interactive live streaming and video calling SDKs support in-session transcription for exactly this scenario.
Meeting transcription combines streaming recognition with speaker attribution, producing searchable meeting records. Teams building this on VideoSDK often connect Google's recognizer through the Python SDK to process live room audio.
Performance Tips and Optimization
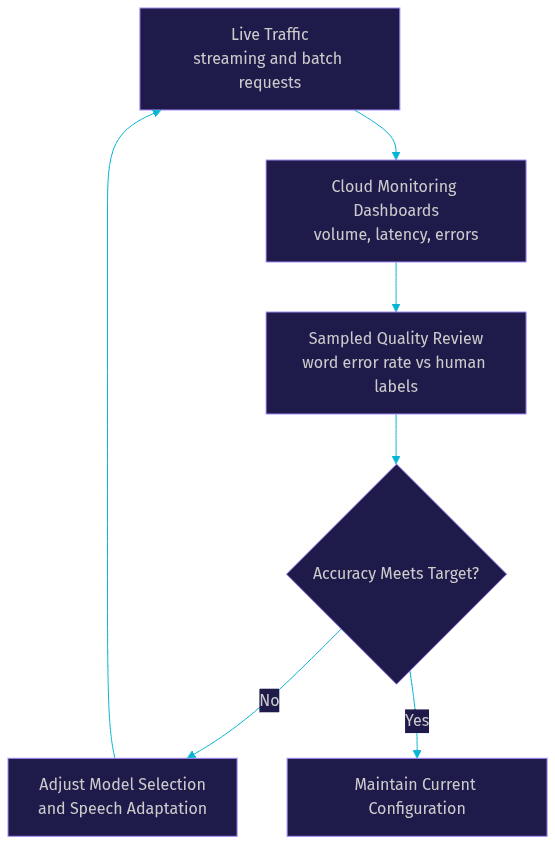
Optimization splits into latency work for streaming and accuracy work for everything. Both benefit from a monitoring feedback loop.
Reducing Latency for Streaming
Streaming latency is dominated by how much audio you buffer before sending. Send small chunks as they're captured rather than accumulating seconds of audio client-side, keep the gRPC channel warm rather than reconnecting per utterance, and colocate your backend close to Google's regional endpoints to cut network round-trip time. Interim results give users perceived responsiveness even before final results land, so surface them in your UI immediately.
Improving Accuracy in Noisy Environments
Noise is the top accuracy killer in field deployments. Apply audio preprocessing before submission: noise suppression, volume normalization, and silence trimming. Then use speech adaptation to boost the vocabulary that matters in your domain, since adaptation partially compensates for acoustic degradation. Finally, select the model matched to the acoustic conditions rather than forcing the default model onto phone or noisy field audio. For live communication apps, VideoSDK's SDKs include built-in noise suppression on captured audio, which cleans the signal before it ever reaches an STT pipeline.
Monitoring Usage and Quality
Google Cloud's monitoring dashboards expose request volume, error rates, and latency percentiles for the Speech to Text API. Track word error rate on a sampled, human-labeled subset of your traffic as your real quality metric, and feed that back into model selection and adaptation tuning.
Security and Compliance
Google Speech to Text encrypts data in transit and at rest, and access is governed by Google Cloud IAM, where you grant the speech recognition role to specific service accounts rather than sharing broad credentials. Data residency is handled through Google Cloud's regional infrastructure: you can process audio in specific regions to satisfy localization requirements, an important consideration for healthcare and financial workloads. Google Cloud maintains ISO certifications and supports GDPR compliance obligations, though the controller-processor split means your organization still owns the compliance posture for the audio you submit. For highly sensitive workloads, evaluate retention settings and avoid persisting raw audio longer than your use case requires.
Future Trends and Alternatives
The STT landscape in 2026 is shifting toward real-time multimodal models, like OpenAI's Realtime API and Google's own Gemini Live capabilities, which fuse speech understanding and generation in a single streaming model rather than chaining STT to an LLM. On-premise and self-hosted recognition is also growing for organizations that can't send audio to a public cloud.
How does Google Speech to Text compare? Azure Speech Services offers comparable language coverage and strong customization, with tight Microsoft-ecosystem integration. Amazon Transcribe is often the pragmatic choice inside AWS deployments, with solid call analytics features. Deepgram's newer models, including its Nova generation, compete aggressively on speed and price for streaming workloads, and independent benchmarks on Artificial Analysis are worth checking before committing. Google Speech to Text remains the strongest default when you need broad language coverage, mature batch tooling, and tight Google Cloud integration. For AI voice agent builders, VideoSDK's AI agents documentation covers how multiple STT providers, including Google's, plug into a real-time agent pipeline.
Definitions Glossary
Speech recognition API: A cloud service that converts spoken audio into text using machine learning models, exposed to developers through request-based interfaces. Google Speech to Text is one example, offered through Google Cloud.
Streaming transcription: A recognition mode where audio is sent incrementally over a bidirectional channel and results are returned while the user is still speaking, enabling live captions and voice interfaces.
Speech adaptation: A Google Speech to Text feature that biases recognition toward supplied phrases and custom classes, improving accuracy on domain-specific vocabulary like product names or medical terms.
Word-level timestamp: A per-word start and end time attached to transcription results, used for caption alignment, in-video search, and precise subtitle timing.
Word error rate (WER): The standard accuracy metric for STT systems, calculated from substitutions, deletions, and insertions relative to a human-labeled reference transcript.
Key Takeaways
- Google Speech to Text supports more than 85 languages across streaming, batch, and synchronous modes, with specialized models for phone, video, and general audio.
- Model selection is the highest-impact accuracy decision: match the recognizer model to your audio source and validate with word error rate measured on your real traffic.
- Speech adaptation is what turns a generic recognizer into a domain-accurate one, especially for medical, legal, and product-specific vocabulary.
- Cost is billed per 15-second increment and differs by model and mode, so use batch for archived audio and stream only when live results are required.
- For real-time apps, pairing Google Speech to Text with an RTC platform like VideoSDK's video calling SDK and Python SDK lets you transcribe live room audio with built-in noise suppression cleaning the signal first.
Conclusion
Google Speech to Text remains a solid default for cloud transcription in 2026 because it combines broad language coverage, purpose-built models, and mature streaming and batch tooling under one API. The engineering work is in the details: correct model selection, disciplined audio preprocessing, and adaptation tuned to your domain. Start with the free tier, run your own audio through two candidate models, and let measured word error rate drive your configuration. If you're building live transcription into a communication app, explore how VideoSDK's SDKs connect STT pipelines to real-time rooms, and join the VideoSDK Discord community to compare notes. What are you building with speech recognition? Drop a comment, I'd love to hear what kind of transcription use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ