


The Google Speech Recognition API (part of Google Cloud's Speech-to-Text service) converts audio into text using three recognition modes: synchronous for short clips, asynchronous batch for long files, and streaming for real-time transcription. It supports over 100 languages and variants, domain-specific models like Chirp 3, and custom vocabulary adaptation. Developers evaluating real-time transcription for production apps should also compare it with integrated solutions like VideoSDK's real-time transcription, which bundles transcription directly into live video and audio rooms.
Voice is becoming the default interface for everything from customer support calls to in-app voice commands, and every one of those experiences depends on one foundational capability: converting speech to text accurately, quickly, and at scale. The Google Speech Recognition API has become one of the most widely adopted speech-to-text services for exactly this reason. It offers mature language coverage, flexible recognition modes, and tight integration with the broader Google Cloud ecosystem.
But adopting any cloud speech service involves real decisions. Which recognition mode fits your latency budget? How do you push accuracy above 90% on noisy audio? What will transcription actually cost at production volume? This guide walks through the Google Speech Recognition API end to end, so you can answer those questions before you write a single integration.
What Is the Google Speech Recognition API?
The Google Speech Recognition API is defined as the speech-to-text service within Google Cloud that converts audio input into machine-readable text using neural network models trained on large multilingual corpora. It works by accepting an audio payload (or a live audio stream) alongside a recognition configuration, routing that request to a recognizer, and returning transcribed text with confidence scores and timing metadata.
The service sits inside Google Cloud's AI product family and is accessible through the Google Cloud SDK, REST interfaces, and gRPC clients. It exposes three primary recognition patterns: synchronous recognition for audio under roughly a minute, asynchronous batch recognition for files up to several hours, and streaming recognition for live audio from microphones or call streams.
Google Speech Recognition API provides speech-to-text through recognizers, which are configurable resources that hold your language, model, and adaptation settings. This resource-oriented design means you configure recognition behavior once and reuse it across requests, rather than passing a full configuration with every call.
Core Features and Capabilities of Google Speech Recognition API
Google Speech Recognition API's feature set centers on language breadth, model quality, and configurability. Language coverage spans more than 100 languages and regional variants, with stronger accuracy in widely spoken languages and continuous expansion in others.
Model selection matters most for accuracy. Google's Chirp 3 model family represents the current generation of multilingual speech models, designed for improved accuracy across accents and acoustic conditions, while Conformer-based models remain available for use cases that need specific behaviors like word-level timestamps or optimized telephony performance.
Beyond raw models, the API supports multichannel audio, so a two-person call recorded on separate channels can be transcribed with per-channel results, which dramatically simplifies speaker separation. Noise robustness is built into the newer models, though pre-processing noisy audio still improves results. Speech adaptation lets you bias recognition toward domain vocabulary, and profanity filtering, word timestamps, and speaker diarization add production-grade controls. Security features include encryption at rest and in transit, plus customer-managed encryption keys for regulated workloads.
How the Google Speech Recognition API Works: Architecture
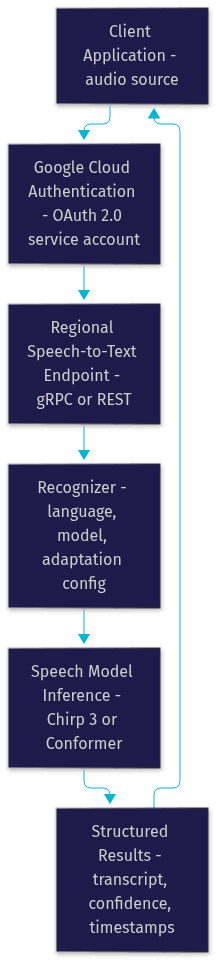
The Google Speech Recognition API works by authenticating your client, routing your audio and configuration to a regional recognizer, processing the audio through the selected model, and returning structured results. Understanding this flow helps you debug latency issues and design a reliable client-side pipeline.
At a high level, your application authenticates against Google Cloud using OAuth 2.0 credentials derived from a service account. The audio request, either a full payload or a stream of chunks, travels over gRPC or REST to a regional Speech-to-Text endpoint. The recognizer applies your configuration, runs inference, and returns results. In streaming mode, interim results arrive continuously while final results land once the stream closes or a natural pause is detected.
For teams building live voice or video applications, this flow typically sits downstream of a real-time communication layer. For example, a telehealth platform using VideoSDK's video calling SDKs can pipe participant audio into a speech recognition pipeline to produce live captions, with the RTC layer handling media transport and the recognition service handling transcription.
Authentication and Project Setup
Getting started with the Google Speech Recognition API requires a Google Cloud project with billing enabled, the Speech-to-Text API activated, and a service account with the correct credentials. Authentication uses OAuth 2.0 scopes, and Google strongly recommends service-account key files or workload identity federation rather than user credentials for server-side applications.
The setup sequence is straightforward: create a project in the Google Cloud console, enable the Speech-to-Text API, create a service account, grant it the appropriate role, and generate a key or attach the account to your compute environment. Client libraries automatically locate credentials from the environment, which avoids hardcoding secrets.
Billing considerations come next. The API requires an active billing account, though Google provides a free monthly allotment for speech-to-text usage. Keep in mind that streaming and batch recognition are billed differently, so your mode choice directly affects cost.
Request and Response Structure Explained
Every request to the Google Speech Recognition API follows a consistent logical shape: a configuration object describing how audio should be processed, and an audio object containing the data itself or a reference to it.
The configuration covers the language code, the model, audio encoding, sample rate, channel count, and optional features like profanity filtering or word timestamps. In the resource-based API, a recognizer holds these settings persistently, and a config mask tells the service which fields you want to override per request. The audio side either embeds raw bytes (practical for short clips) or references a file in Cloud Storage (required for long batch jobs).
Responses arrive as a list of recognition results, each containing one or more alternatives. Every alternative carries a transcript, a confidence score, and, when enabled, word-level timing information. Speech recognition metadata reports which model processed the request and the total audio duration billed. In streaming mode, you receive interim results as speech continues, followed by a final result with stable timing data, which is what live captioning interfaces typically render.
Choosing the Right Mode: Sync, Async, or Streaming
Mode selection is the single most consequential design decision with the Google Speech Recognition API, because it determines latency, file size limits, and cost structure.
Synchronous recognition suits short audio clips, roughly a minute or less, where you need the complete result in one response. It is the simplest mode but blocks until processing finishes.
Asynchronous batch recognition handles long recordings, up to several hours of audio, by submitting a job and polling or waiting for completion. Latency is measured in minutes, not milliseconds, which makes it ideal for transcribing archives, meeting recordings, or media libraries.
Streaming recognition delivers real-time transcription over a bidirectional connection, returning interim results in hundreds of milliseconds. It is the only mode suitable for live captioning, voice agents, and interactive voice commands. Streaming connections have duration limits, so long sessions require reconnect logic. For live apps, pairing streaming recognition with a real-time communication layer like VideoSDK's audio calling keeps media delivery and transcription synchronized.
Model Adaptation and Custom Vocabulary
Speech adaptation is the Google Speech Recognition API's mechanism for biasing recognition toward your domain's vocabulary. It works by supplying phrase sets and custom classes alongside your recognizer configuration, and the model weights those terms more heavily during decoding.
Phrase sets contain terms you expect to hear, each with an optional boost value that controls how strongly the model prefers them. A medical transcription app might boost drug names and clinical terminology; a support analytics pipeline might boost product names. Custom classes go further by grouping interchangeable values, such as a list of station names or account types, so one adaptation covers many possible utterances.
Adaptation is most effective for proper nouns, jargon, and alphanumeric identifiers that generic models routinely miss. It is not a fix for poor audio quality. In practice, teams see the biggest accuracy gains by combining a well-matched model, a curated phrase set, and clean audio, rather than relying on adaptation alone to rescue noisy input.
Best Practices for High Speech Recognition Accuracy
Accuracy with the Google Speech Recognition API is mostly determined before the request is ever sent. Audio quality is the dominant factor: capture at 16 kHz or higher for telephony-adjacent use cases, use lossless encodings where possible, and avoid resampling audio multiple times.
Match your configuration to the audio. Declaring the correct channel count enables per-channel transcription for multichannel recordings, and specifying the right encoding prevents the service from guessing. Apply noise reduction upstream when environments are loud, since even robust models degrade on heavily corrupted audio.
For speaker separation, prefer multichannel recording over diarization when you control the capture pipeline, because physical channel separation is more reliable than algorithmic diarization. When diarization is necessary, enable it selectively, since it adds processing overhead. Finally, measure accuracy on a labeled sample of your real audio before scaling, and iterate on phrase sets based on actual errors rather than assumptions.
Pricing, Cost Management, and Quotas
The Google Speech Recognition API bills by audio duration processed, with different rates for standard and enhanced models, and separate pricing for batch versus streaming recognition. Google includes a free monthly allotment per billing account, after which per-minute rates apply.
Cost control starts with mode discipline. Batch recognition is typically cheaper than streaming, so reserve streaming for genuinely interactive use cases. Trim silence from stored audio before batch processing, since billed time includes silence. Cache and reuse transcripts rather than reprocessing identical audio.
Quotas are the other operational concern. Streaming recognition has concurrent-request and payload limits per project, and exceeding them produces errors rather than graceful degradation. Request quota increases in advance for predictable traffic spikes, such as product launches or event-driven call volume, and implement exponential backoff on quota errors so your pipeline recovers automatically.
Security, Compliance, and Data Residency
The Google Speech Recognition API encrypts data in transit and at rest by default, and supports customer-managed encryption keys through Cloud KMS for workloads where you must control key access directly. Audio sent for recognition is not used to train Google models, which matters for regulated industries.
Data residency is handled through regional endpoints. You can process audio in specific regions to keep data within jurisdictional boundaries, an essential requirement for healthcare, legal, and financial deployments. Regional processing also reduces latency when your compute and your endpoint are co-located.
Google Cloud maintains a broad compliance portfolio, including SOC 2, ISO 27001, and HIPAA-eligible configurations, though eligibility depends on your overall architecture, not the API alone. For voice workloads with strict residency needs, some teams also evaluate on-premises or self-hosted speech recognition, trading operational burden for full physical control.
Real-World Use Cases for Google Speech Recognition API
Call-center transcription is the most common production use case: batch transcription of recorded calls feeds analytics pipelines that surface sentiment, compliance flags, and topic trends, while streaming transcription powers live agent-assist prompts.
Live captioning covers virtual events, classrooms, and broadcast workflows, where streaming recognition converts speech into on-screen text with sub-second latency. Media indexing applies batch recognition at scale to make video archives searchable by spoken content, enabling keyword-level retrieval across thousands of hours.
IoT and voice-command interfaces use streaming recognition to drive hands-free interactions in smart devices and vehicles. A growing pattern is AI voice agents, where speech recognition is the first stage of a pipeline that feeds an LLM and a text-to-speech engine. Developers building these agents often use orchestration layers like VideoSDK's AI voice agent framework, which manages the full speech-to-LLM-to-speech loop inside real-time rooms.
Common Pitfalls and Troubleshooting
The most frequent errors with the Google Speech Recognition API are self-inflicted configuration mistakes. Mismatched audio encoding or sample rate declarations produce garbled transcripts or outright failures, so always verify that your declared configuration matches the actual audio properties.
Quota-exceeded errors appear when streaming concurrency or request volume outgrows your project limits. The remedy is proactive quota planning plus client-side backoff, not retry storms, which make quota pressure worse. Latency spikes in streaming mode usually trace to network conditions or oversized audio chunks; sending smaller chunks more consistently keeps interim results flowing.
Long streaming sessions hitting connection duration limits cause dropped transcripts, so implement reconnection with buffered audio. Finally, poor accuracy on domain vocabulary is almost always an adaptation gap rather than a model failure, and a well-tuned phrase set resolves most of these cases without changing models.
Definitions Glossary
Synchronous recognition: A Google Speech Recognition API mode that processes short audio clips, roughly one minute or less, and returns the complete result in a single response.
Streaming recognition: A bidirectional mode that transcribes live audio in real time, returning interim results continuously and a final result when speech ends or the stream closes.
Recognizer: A configurable Google Speech Recognition API resource that stores your language, model, and adaptation settings so they can be reused across requests.
Speech adaptation: The mechanism for biasing recognition toward domain-specific vocabulary using phrase sets and custom classes with adjustable boost values.
Speaker diarization: The process of separating a single-channel audio stream into distinct speaker segments, attributing transcribed words to individual speakers.
Real-time transcription: Live conversion of speech to text as it is spoken, typically delivered with sub-second latency for captioning and agent-assist interfaces.
Key Takeaways
- The Google Speech Recognition API offers three modes, synchronous, asynchronous batch, and streaming, and choosing the right one determines your latency, file limits, and cost structure.
- Accuracy depends more on audio quality and correct configuration than on model choice, and speech adaptation with phrase sets fixes most domain-vocabulary errors.
- Streaming recognition is the only mode suitable for live captioning and voice agents, and it requires reconnect logic for long sessions.
- Cost control comes from reserving streaming for interactive use cases, trimming silence before batch processing, and planning quotas ahead of traffic spikes.
- For live video and voice applications, pairing the API with a real-time communication layer like VideoSDK keeps media transport and transcription synchronized end to end.
Conclusion
The Google Speech Recognition API remains one of the strongest speech-to-text choices for developers in 2026, combining broad language coverage, flexible recognition modes, and production-grade security controls. Success with it comes down to three things: picking the right mode for your latency budget, tuning adaptation for your vocabulary, and managing quotas and costs before they manage you.
If you are building live voice or video experiences, explore how VideoSDK's real-time transcription and AI voice agents integrate speech recognition directly into real-time rooms, and grab the free tier at app.videosdk.live to start experimenting. What are you building with speech recognition? Drop a comment, I'd love to hear what kind of transcription use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ