


Dify speech to text is a built-in audio transcription capability that converts voice inputs into text within Dify AI workflows. It allows developers to integrate speech recognition into chatbots and agents using models like OpenAI Whisper. You can enable it through the Application Toolbox in Dify Cloud or configure it manually in a self-hosted environment.
Developers building AI applications increasingly need voice interfaces. Users expect to speak to applications rather than type, especially on mobile devices and in hands-free environments. Dify provides a unified LLM workflow platform, and its speech-to-text feature bridges the gap between audio input and text-based language models. By leveraging Dify speech to text, developers can process audio uploads, transcribe microphone captures, and feed the resulting text into complex AI agents. This capability simplifies building voice-driven applications without managing separate transcription services. In this guide, we will explore how Dify handles audio transcription, compare cloud and self-hosted setups, and troubleshoot common issues.
What Is Dify Speech to Text?
Dify speech to text is defined as the audio processing capability within the Dify platform that converts spoken language into written text. It works by accepting audio file uploads or direct microphone captures, routing them through a configured speech-to-text model, and returning transcribed text to the workflow. This text then becomes the input for downstream LLMs, chatbots, or autonomous agents. Dify integrates this feature directly into its workflow builder, allowing developers to treat audio inputs like any other data source.
The platform supports multiple speech-to-text model providers, giving developers flexibility in choosing the right engine for their accuracy and latency requirements. Whether you need to transcribe a short voice command or a long podcast recording, Dify provides the infrastructure to connect the audio to the appropriate model. VideoSDK also provides real-time transcription capabilities for live audio and video calls, which can complement Dify workflows when live voice data is involved.
Core Components
The Dify speech to text architecture consists of three primary elements. First, the audio endpoint receives the uploaded file or live capture from the frontend UI component. Second, the default speech-to-text model, often OpenAI Whisper or a similar provider, processes the audio payload. Third, the integration layer passes the transcribed text into the active Dify chatbot or agent workflow. This pipeline ensures that voice data seamlessly triggers the same logic as typed text.
How the Feature Works Under the Hood
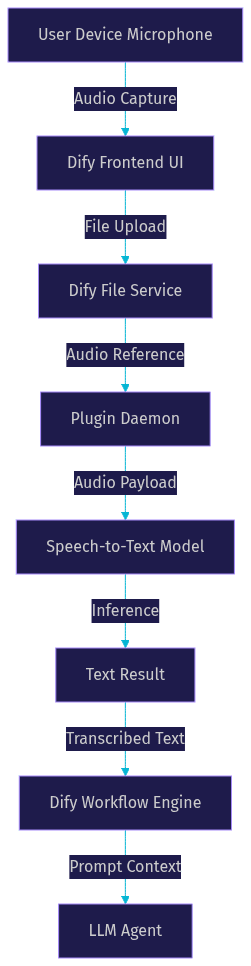
Understanding the Dify speech to text pipeline requires looking at the data flow from capture to transcription. When a user speaks into a Dify-powered application, the frontend UI component captures the audio stream from the microphone. The browser packages this audio into a standard file format, typically WAV or MP3, and sends it to the Dify file service. The file service stores the audio temporarily and generates a reference URL.
Next, the Dify plugin daemon takes over. The daemon reads the audio file reference and forwards the payload to the configured speech-to-text model provider. The model provider, such as OpenAI or a self-hosted Whisper instance, runs inference on the audio data. Once the model completes the transcription, the text result travels back through the plugin daemon to the Dify workflow engine. The engine injects this text into the prompt context, allowing the LLM to generate a response based on what the user said.
Enabling Speech-to-Text in Dify Cloud vs. Self-Hosted
Developers can deploy Dify speech to text in two main ways: through the managed Dify Cloud or via a self-hosted instance. Each path has distinct configuration requirements and trade-offs. Dify Cloud offers the fastest path to a working voice interface. The managed environment handles infrastructure scaling, file storage, and plugin daemon maintenance. Self-hosting provides maximum control over data privacy and model selection, but requires manual configuration of environment variables and Docker containers.
Cloud Activation
Activating Dify speech to text on the cloud platform takes only a few steps. First, navigate to your application dashboard and open the Application Toolbox. Inside the toolbox, locate the Speech-to-Text configuration panel. Toggle the feature on to enable voice input for your application. Next, select a model provider from the dropdown list. Dify Cloud typically offers OpenAI Whisper as the default option. Once you select a provider, the platform provisions the necessary API connections automatically. You can then test the microphone capture directly in the preview pane before publishing your app.
Self-Hosted Configuration
Configuring Dify speech to text on a self-hosted instance requires more manual setup. You need to modify your container orchestration configuration to ensure the file service can communicate with the plugin daemon. Specifically, you must define the public-facing address of your Dify instance so that the plugin daemon can fetch audio files from the file service. This is done by updating the relevant environment configuration entry that specifies the file service URL. After updating the configuration, restart your container services so the changes take effect.
Next, navigate to the Settings page in your Dify dashboard. Under the Model Provider section, add your preferred speech-to-text provider. You will need to enter your API keys for services like OpenAI or configure a local Whisper endpoint. Verify that the provider status shows as active before testing the audio upload feature. If the plugin daemon cannot reach the model endpoint, transcription will fail silently.
Common Pitfalls and Troubleshooting
Even with a solid setup, developers often encounter issues when implementing Dify speech to text. Most problems stem from misconfigured file uploads, preview mode limitations, or unregistered model providers. Checking GitHub issues and community forums reveals several recurring themes. Addressing these common pitfalls early saves significant debugging time.
Missing File Field Error
One frequent error occurs when the API request lacks the required file field. The Dify backend expects a multipart form data payload containing the audio file. If the frontend UI component does not properly attach the recorded audio to the request, the plugin daemon rejects it. Ensure your UI component packages the microphone capture into a valid file object before sending it to the Dify endpoint. Verify that the form field name matches what the backend expects.
Disabled UI in Preview Mode
Developers often notice that the speech-to-text button appears disabled or non-functional in the application preview mode. This is a known limitation. Dify restricts certain hardware access features, like microphone capture, to published applications. To test the voice input functionality, you must publish your application first. Once published, open the live application URL to verify that the microphone button activates and captures audio correctly.
Model Provider Misconfiguration
If the transcription fails silently or returns an error about an unregistered provider, the model configuration is likely at fault. Symptoms include API key rejection or missing model endpoints. To resolve this, go to the Settings page and verify your speech-to-text provider credentials. Ensure the API key has the necessary permissions for audio transcription. If you are using a self-hosted Whisper model, confirm that the endpoint URL is reachable from the Dify plugin daemon container.
Best Practices for High-Quality Transcription
Achieving high accuracy with Dify speech to text requires attention to audio quality and model selection. Always use a high sampling rate, such as 16 kHz or higher, to capture sufficient audio detail. Compress audio files to a manageable size, but avoid aggressive compression that destroys speech frequencies. Background noise suppression is critical. Encourage users to speak in quiet environments or apply a noise gate filter on the client side before uploading.
When choosing a model, consider the trade-offs. Whisper-large offers excellent accuracy for multi-language transcription but introduces higher latency. For real-time or near-real-time applications, consider faster models or streaming transcription APIs. Match the model to your specific use case, whether that is short voice commands or long-form podcast transcription. Always validate the audio file format support for your chosen provider to avoid unnecessary encoding conversions.
Real-World Use Cases
Dify speech to text unlocks several practical applications for developers building AI tools.
- Customer-support ticket summarization. Support teams can upload recorded calls into a Dify workflow. The speech-to-text feature transcribes the audio, and a downstream LLM summarizes the issue, categorizes the ticket, and suggests a resolution.
- Internal knowledge-base Q&A via voice. Employees can speak questions into an internal company bot. Dify transcribes the query, searches the company knowledge base, and returns a spoken or written answer. This hands-free interaction improves productivity in warehouse or field environments.
- Podcast-style content generation with Dify agents. Content creators can upload raw audio recordings. Dify transcribes the speech, and an agent workflow cleans up the text, generates show notes, and creates social media posts based on the transcript.
Future Roadmap and Community Resources
The Dify development team continues to expand the speech-to-text capabilities. Upcoming features on the 2026 roadmap include enhanced multi-language support with automatic language detection and streaming transcription for real-time agent interactions. Developers looking to stay updated should monitor the official Dify release notes. For troubleshooting and community support, join the Dify Discord server or participate in GitHub discussions. The community actively shares configuration tips, custom model integrations, and workflow templates. Checking the official roadmap provides visibility into upcoming platform enhancements.
Definitions Glossary
Dify Speech to Text: The built-in audio transcription capability in the Dify platform that converts voice inputs into text for LLM workflows.
Plugin Daemon: The background service in Dify that handles communication between the file service and external model providers.
FILES_URL: An environment variable required in self-hosted Dify setups that defines the public-facing URL for the file service.
Speech-to-Text Model: An AI model, such as OpenAI Whisper, that processes audio data and outputs transcribed text.
Application Toolbox: The section in the Dify dashboard where developers configure application-level features like speech-to-text and text-to-speech.
Key Takeaways
- Dify speech to text enables voice inputs for chatbots and agents by transcribing audio into text for LLM processing.
- The data flow involves microphone capture, file upload, plugin daemon routing, and model inference.
- Dify Cloud offers one-click activation, while self-hosted setups require Docker and environment variable configuration.
- Common issues include missing file fields, disabled preview mode UI, and unregistered model providers.
- High-quality transcription depends on audio sampling rates, noise suppression, and selecting the right model for the latency-accuracy trade-off.
Conclusion
Dify speech to text provides a powerful way to integrate voice interfaces into AI applications without managing separate transcription services. Whether you use the managed Dify Cloud or a self-hosted deployment, the platform streamlines the path from audio capture to LLM inference. By following best practices for audio quality and troubleshooting common pitfalls, developers can build robust voice-driven workflows. Try the Dify cloud demo to see the feature in action, and share your feedback on the community Discord or GitHub discussions. What are you building with Dify speech to text? Drop a comment to share your use case.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ