


Converting speech to text is the process of using automatic speech recognition (ASR) to transform spoken audio into written text. Modern AI-powered speech recognition services such as VideoSDK's real-time transcription, OpenAI Whisper, and Deepgram STT can transcribe audio with word error rates below 10 percent in many languages. This guide explains how the technology works, what drives accuracy, and how to choose and implement the right transcription workflow for your application.
Speaking is roughly three times faster than typing, yet most applications still force users to capture ideas through a keyboard. That gap is exactly why the ability to convert speech to text has become one of the most requested features in modern software, from meeting notes apps to telehealth platforms and voice agents. When you can transcribe speech accurately and in real time, you unlock hands-free documentation, searchable meeting archives, live captions, and conversational AI.
This article walks through the full picture: what speech-to-text conversion actually is, how the underlying technology stack works, which factors influence transcription accuracy, and how to choose between cloud speech-to-text APIs and on-device models. You will also get a practical, no-code implementation workflow, best practices for optimizing quality, and a look at where the field is heading in 2026.
What Is Speech-to-Text Conversion?
Speech-to-text conversion is defined as the process of transforming spoken audio into written text using software. The engine behind it is called automatic speech recognition (ASR), a branch of machine learning that maps raw audio signals to sequences of words. When you convert speech to text, an ASR system listens to an audio stream, segments it into manageable chunks, predicts which words were spoken, and assembles those predictions into a readable transcript.
There are two broad deployment models. Offline, on-device solutions run the recognition model directly on the user's hardware, such as a phone or laptop, which keeps audio private and works without an internet connection. Cloud-based solutions send audio to a remote speech-to-text API, where powerful server-side models do the heavy lifting. Cloud services generally deliver higher accuracy, more languages, and advanced features like speaker diarization, at the cost of network latency and data leaving the device. Most production applications in 2026 use a hybrid of the two, falling back to on-device recognition when connectivity is poor.
How Convert Speech to Text: The Core Technology Stack
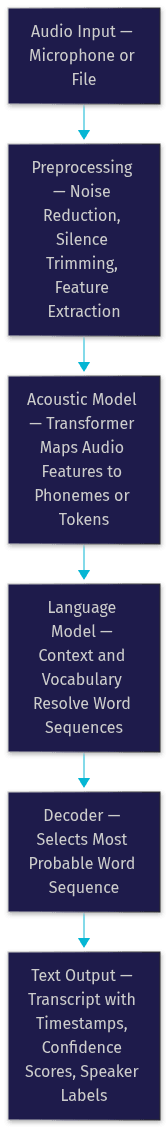
Every system that converts speech to text follows a recognizable pipeline: audio capture, preprocessing, acoustic modeling, language modeling, and final text output. Audio capture records the raw waveform, usually as compressed audio from a microphone or an existing file. Preprocessing cleans and normalizes that signal, removing silence, reducing noise, and converting the audio into features the models can interpret, such as spectrograms that represent how sound energy varies across frequency and time.
The acoustic model then maps those features to linguistic units like phonemes or subword tokens. Modern acoustic models are transformer-based deep learning networks trained on thousands of hours of labeled speech. Finally, the language model applies context, deciding between homophones and assembling the most probable word sequence. The result is a transcript, often enriched with timestamps, confidence scores, and speaker labels.
Acoustic Modeling and Deep Learning
Acoustic modeling is where deep learning transformed the field. Earlier systems relied on hand-engineered features and statistical models that struggled with accents and noise. Today's transformer-based models learn phoneme patterns directly from data, treating speech as a sequence problem much like language models treat text. Because these networks are trained on massive, diverse speech corpora, they generalize across accents, speaking styles, and recording conditions far better than their predecessors. Models like OpenAI's Whisper were trained on hundreds of thousands of hours of multilingual audio, which is why they perform well even on imperfect, real-world recordings.
Language Modeling and Context Awareness
Context is what separates a mediocre transcript from a great one. Language modeling reduces homophone errors, the classic cases where "their," "there," and "they're" sound identical but mean different things. A strong language model uses surrounding words, sentence structure, and even domain vocabulary to pick the correct spelling. For example, in a medical transcription, the phrase "patient shows signs of arrhythmia" is far more likely than a phonetically similar but nonsensical alternative. This is also why custom vocabulary support matters: feeding domain terms into the language model measurably improves transcription quality metrics like word error rate.
Key Factors That Influence Accuracy When You Convert Speech to Text
Transcription accuracy is never guaranteed; it is engineered. Six factors dominate the outcome when you convert speech to text.
First, audio quality. A clean 16 kHz or higher recording from a decent microphone can cut word error rates dramatically compared to a compressed, low-bitrate phone recording. Second, speaker accents and dialects. Models trained on diverse data handle variation better, but strong regional accents still degrade accuracy for most engines. Third, background noise. Reverberant rooms, keyboard clicks, and cross-talk all confuse acoustic models, which is why noise suppression is now a built-in feature in services like VideoSDK's real-time transcription.
Fourth, speaker diarization, the task of separating who said what. Multi-speaker audio without diarization produces merged, hard-to-read transcripts. Fifth, language support. English dominates training data, so multilingual transcription quality varies widely across providers. Sixth, domain-specific vocabulary. Product names, jargon, and acronyms frequently get mangled unless you supply a custom vocabulary or fine-tune the model. When evaluating providers, test against your own audio and measure word error rate and character error rate rather than trusting vendor benchmarks.
Choosing the Right Solution: Cloud API vs. On-Device
The cloud versus on-device decision comes down to four axes: cost, latency, privacy, and scalability.
Cloud speech-to-text APIs, such as Google Cloud Speech-to-Text, Deepgram STT, and AssemblyAI, offer the highest accuracy, broad language coverage, and features like real-time transcription, speaker diarization, and punctuation. You pay per minute of audio processed, which scales cleanly but adds up at high volume. Latency is typically low enough for live captions, though round-trip network time is unavoidable.
On-device models, such as a locally deployed Whisper model, keep audio entirely on the hardware. That is a strong fit for privacy-focused transcription in healthcare, legal, or enterprise environments where audio cannot leave the premises. The trade-offs are model size, device performance requirements, and generally lower accuracy than the best cloud engines.
Choose a cloud API when you need real-time transcription for live conversations, multilingual support, or speaker diarization at scale. Choose on-device when privacy or offline operation is non-negotiable. Many teams run both: cloud for live meetings, on-device for sensitive recordings. If you are building transcription into a real-time communication app, VideoSDK's real-time transcription integrates ASR directly into the media pipeline, so transcripts arrive as participants speak without you stitching together a separate upload workflow.
Step-by-Step Implementation Guide (No Code)
Here is the practical workflow to convert speech to text in a production application, described in plain language.
Step 1: Prepare Your Audio
Start with the best source audio you can get. Record at 16 kHz or higher for speech, use a close microphone where possible, and apply noise suppression before sending audio to the recognizer. If you are working with existing files, convert them to a format your service supports and trim long silences, which reduces processing time and cost.
Step 2: Select a Service or Model
Match the engine to your use case. For live meeting transcription, pick a streaming-capable cloud API with low transcription latency. For batch processing of archived recordings, an offline model like Whisper may be more cost-effective. Evaluate two or three candidates against a sample of your real audio and compare word error rates.
Step 3: Upload or Stream the Audio
For live transcription, open a streaming connection so audio flows continuously to the service and partial results return within a second or two. For files, upload the recording or point the service at a storage URL. Keep your API credentials on the server side, never embedded in the client application, and use short-lived tokens for authenticated requests.
Step 4: Retrieve the Transcript
Streaming APIs return interim hypotheses that refine as more context arrives, followed by finalized segments. Batch APIs return the complete transcript with timestamps and, depending on the service, confidence scores per word. Design your application to handle both interim and final results so live captions update smoothly.
Step 5: Post-Process the Output
Raw transcripts need polish. Apply automatic punctuation and casing if the engine does not provide it, attach speaker labels using diarization results, and format the output for its destination, whether that is a searchable database, a document, or subtitles. If you handle personal data, ensure GDPR compliance by informing users, minimizing retention, and processing or storing audio in appropriate regions.
Best Practices to Optimize Your Convert Speech to Text Workflow
A few habits separate reliable transcription pipelines from fragile ones.
Preprocess audio consistently. Even simple gain normalization and noise reduction before recognition improves accuracy more than most people expect. Use custom vocabularies for domain jargon, product names, and acronyms; most cloud speech-to-text APIs let you supply word lists that bias the language model toward your terms.
For multi-speaker recordings, enable speaker diarization and structure your output around speaker turns rather than a single wall of text. This makes transcripts readable and searchable by speaker. Automate your export formats: generate plain text for search, structured formats with timestamps for subtitles, and speaker-attributed documents for meeting notes, all from a single transcription pass.
Finally, monitor transcription quality continuously. Sample transcripts regularly, compute word error rate against a small hand-labeled set, and alert when quality drifts, because model updates and changing audio conditions can silently degrade output over time.
Emerging Trends in Speech-to-Text
Four trends are reshaping the field in 2026. Real-time multilingual transcription is maturing, with engines that detect the spoken language on the fly and code-switch mid-sentence, which matters for global user bases. Edge AI is bringing near-cloud accuracy to on-device models, shrinking the privacy-versus-performance trade-off. Zero-shot language models can transcribe languages they were barely trained on, expanding coverage beyond the roughly hundred languages well served today.
Perhaps most significant is the convergence with conversational agents. Speech-to-text is no longer just a documentation tool; it is the front door of AI voice agents, where the transcript feeds an LLM that decides what to say next. Platforms like VideoSDK's AI voice agents chain STT, LLM, and TTS into a single real-time pipeline, and the quality of that first transcription step directly determines how well the entire agent understands its user.
Definitions Glossary
Automatic Speech Recognition (ASR): The machine learning technology that converts spoken audio into text by mapping sound patterns to words. It is the engine behind every speech-to-text service.
Word Error Rate (WER): The standard metric for transcription quality, calculated from substitutions, deletions, and insertions relative to a reference transcript. Lower WER means higher accuracy.
Speaker Diarization: The process of separating an audio recording by speaker, labeling which words were spoken by whom. Essential for readable multi-speaker transcripts.
Real-Time Transcription: Streaming speech recognition that returns text within seconds of it being spoken, enabling live captions and conversational agents.
Custom Vocabulary: A list of domain-specific terms supplied to a speech-to-text API so the language model favors correct spellings of jargon, names, and acronyms.
Key Takeaways
- Converting speech to text relies on a pipeline of audio preprocessing, acoustic modeling, and language modeling, and the quality of each stage compounds into the final transcript.
- Audio quality, accents, background noise, and domain vocabulary are the biggest controllable drivers of transcription accuracy.
- Choose a cloud speech-to-text API for real-time transcription, multilingual support, and diarization; choose on-device models when privacy or offline operation is non-negotiable.
- Measure word error rate against your own audio rather than trusting vendor benchmarks, and monitor quality continuously in production.
- Speech-to-text is now the entry point of AI voice agents, and platforms like VideoSDK integrate it directly into real-time communication pipelines.
Conclusion
The ability to convert speech to text has moved from a novelty to a core feature, powering meeting transcription, live captions, accessibility, and conversational AI. The technology stack is mature, the accuracy is good enough for production, and the choice between cloud and on-device comes down to your latency, privacy, and cost requirements. Start by testing two or three services against your own audio, wire the workflow into your application, and measure the results. If you are building real-time voice or video experiences, explore VideoSDK's real-time transcription and AI voice agent documentation or try the platform free at app.videosdk.live. What are you building with speech-to-text? Drop a comment, I'd love to hear about your transcription use case.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ