


AWS speech to text is delivered through Amazon Transcribe, a fully managed service that converts audio and speech into text using automatic speech recognition. It supports batch transcription of stored media files and real-time streaming transcription over WebSocket or HTTP/2, with features like speaker diarization, custom vocabularies, and automatic content redaction. If you want to add live transcription to an application, VideoSDK's real-time transcription integrates directly with your calling and streaming pipelines, and the official Amazon Transcribe docs cover the full API surface.
Every application that touches audio eventually needs the same thing: turning speech into searchable, analyzable text. Call centers want conversation analytics, media teams want subtitles, and product teams want in-app captions. Building accurate speech recognition from scratch means training acoustic models, handling accents, and maintaining inference infrastructure, which is why most teams use a managed service instead.
Amazon Transcribe, the engine behind AWS speech to text, handles all of that as a pay-per-second API. This guide walks through both batch and streaming workflows, the audio settings that matter most, security and compliance considerations, and the cost and accuracy optimizations that separate a prototype from a production pipeline. By the end, you'll know exactly how to architect a transcription workflow on AWS and where it fits alongside real-time communication platforms like VideoSDK.
What Is AWS Speech to Text?
AWS speech to text is defined as the automatic speech recognition capability provided by Amazon Transcribe, a managed AWS service that converts spoken audio into machine-readable text. It works by accepting either a stored media file (batch mode) or a live audio stream (streaming mode), running the audio through AWS's speech recognition models, and returning a structured JSON transcript that includes word-level timestamps, confidence scores, and optional metadata like speaker labels.
The service fits naturally into the AWS ecosystem. Input files live in Amazon S3, access is controlled through IAM, encryption is handled by KMS, and outputs can flow into downstream services like Amazon Comprehend for sentiment analysis or Amazon Translate for multilingual subtitles. It supports dozens of languages, multi-language identification, medical and call analytics variants, and PII redaction built in.
Core Use Cases for AWS Speech to Text
The most common production use case is call-center analytics. Transcribe's call analytics variant processes recorded conversations and returns sentiment, talk-time ratios, interruption detection, and category matching, which support teams use to score calls and surface coaching opportunities.
Video subtitle generation is the second big category. Batch transcription of a media file produces word-level timestamps, which map directly to subtitle tracks. Combined with Amazon Translate, one pipeline can generate subtitles in multiple languages from a single source video.
Podcast and media indexing rounds out the batch scenarios. Once episodes are transcribed, the text becomes searchable, enabling keyword search, topic clustering, and chapter generation across an entire archive.
Accessibility compliance is a legal driver in many markets. Captions for recorded and live content are required under regulations like the ADA and EN 301 549, and Transcribe provides both the batch and real-time paths to meet those requirements.
Finally, real-time captioning for live events, webinars, and in-app calls uses streaming transcription. If you're building live captioning into a video calling app, VideoSDK's real-time transcription feature delivers captions inside the call itself, while Transcribe handles standalone streaming workloads.
Architecture Overview: From Audio to Text
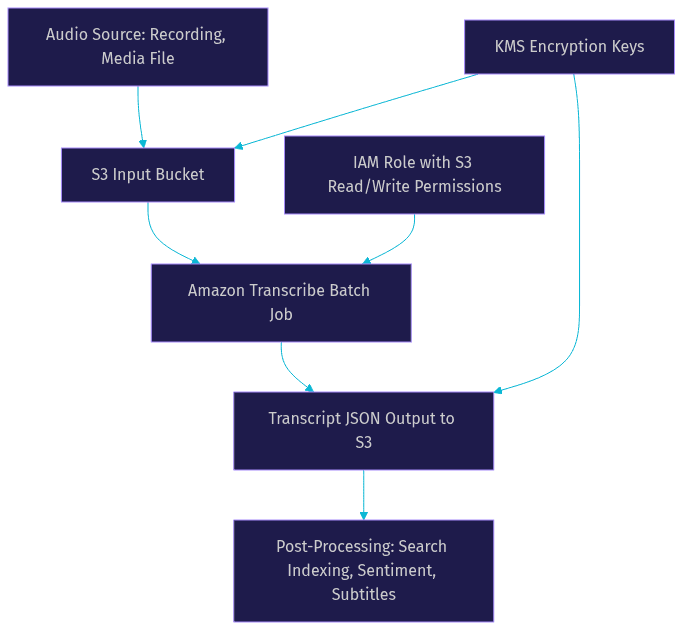
A production AWS speech to text pipeline has four stages: audio ingestion, transcription, output storage, and downstream processing. In batch mode, media files are uploaded to an S3 input bucket, a transcription job is created referencing that object, Transcribe reads the audio, processes it, and writes a JSON transcript to an output location. In streaming mode, audio chunks flow directly from a client application to the Transcribe streaming endpoint, and partial results return in near real time.
The diagram below shows the batch architecture, including the optional post-processing step where transcripts feed analytics or search systems:
The streaming architecture is simpler on the storage side but adds a persistent connection:
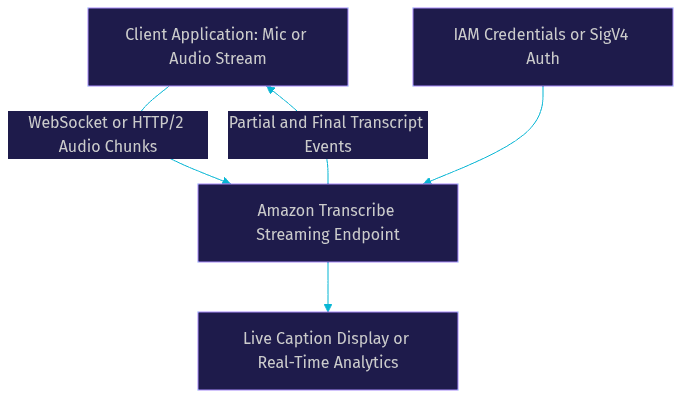
Both paths return the same core transcript structure, so downstream processing logic can be shared between batch and streaming pipelines.
Batch Transcription Workflow
Batch transcription is the right choice when you have recorded files and don't need results immediately. The workflow has five steps, and the details around permissions are where most teams stumble.
Step 1: Prepare the audio. Verify the file is in a supported format (FLAC, WAV, MP3, MP4, or AMR), check the sample rate, and confirm the file is under the service's size and duration limits. Lossless formats like FLAC and WAV give the best accuracy.
Step 2: Upload to S3. Place the file in an input bucket. The bucket should have server-side encryption enabled, and its region should match the region where you'll run the transcription job to avoid cross-region data transfer costs.
Step 3: Create the transcription job. You reference the S3 object, specify the language (or enable automatic language identification), and optionally attach a custom vocabulary, enable speaker diarization, or turn on content redaction. The job runs asynchronously, so you'll receive a job identifier to track.
Step 4: Monitor status. Poll the job status or subscribe to EventBridge notifications, which fire when jobs complete or fail. EventBridge is the better production pattern because it avoids polling loops and lets you trigger downstream processing automatically.
Step 5: Retrieve results. The completed transcript lands in your output location as JSON, containing the full text, word-level timestamps, confidence scores, and any diarization or redaction metadata.
The critical permission detail: the IAM role or user creating the job needs read access to the input bucket and write access to the output location. A common failure mode is a job that starts successfully but cannot write its output, leaving a completed job with no retrievable transcript. Grant least-privilege access scoped to the specific buckets rather than broad S3 permissions.
Streaming Transcription Workflow
Streaming transcription converts audio to text in near real time, typically returning partial results within a few hundred milliseconds. It's the right mode for live captions, voice-controlled interfaces, and real-time analytics during calls.
The workflow starts by establishing a bidirectional connection to the Transcribe streaming endpoint over WebSocket or HTTP/2, authenticated with AWS credentials signed via Signature Version 4. Once the session is open, your application sends encoded audio chunks continuously, typically in 10 to 100 millisecond intervals.
As audio arrives, Transcribe returns two kinds of events. Partial results are interim hypotheses that change as more audio context arrives, and they're what you display for live captions. Final results are committed segments that won't change, and they're what you persist for your transcript record. A well-built client renders partials immediately and replaces them with finals as they arrive, which is what gives live captions their smooth, self-correcting behavior.
Audio format requirements are stricter for streaming than batch. The streaming endpoint expects raw PCM audio, not container formats like MP3 or FLAC. You specify the sample rate when opening the session, and it must match the audio you actually send, because a mismatched sample rate is the single most common streaming error. For most voice applications, 16 kHz mono PCM is the standard choice, matching telephone and microphone input.
Language handling also differs. You can specify a single language, or enable multi-language identification so the service detects the dominant language from the first few seconds of speech. Multi-language mode adds some startup latency, so for single-language applications, always pin the language code explicitly.
Choosing the Right Audio Settings
Audio quality decisions made upstream determine most of your transcription accuracy. Lossless formats (FLAC, WAV PCM) consistently outperform lossy formats, and mono audio is preferred unless you specifically need channel-based diarization, where each speaker occupies a separate channel.
| Setting | Recommended Value | Notes |
|---|---|---|
| Format (batch) | FLAC or WAV PCM | Lossless, best accuracy |
| Format (streaming) | PCM | Required by the streaming endpoint |
| Sample rate | 8 kHz (phone) or 16 kHz (mic) | Must match actual audio |
| Channels | Mono | Use stereo only for channel diarization |
| Bit depth | 16-bit | Standard for speech |
The one rule that causes the most production incidents: the declared sample rate must match the audio's actual sample rate. A 16 kHz stream declared as 8 kHz produces garbled output or outright errors, and the error messages aren't always obvious about the cause.
Managing Language Identification and Multi-Language Support
Amazon Transcribe supports two language strategies. Explicit language specification, where you provide a language code per job or stream, is faster and more accurate when you know the language. Automatic language identification, where the service analyzes the opening seconds of audio and selects from a list of candidate languages you provide, is the right choice for user-generated content of unknown origin.
Best practice is to pin the language whenever you can. Language identification adds startup latency in streaming and a small accuracy risk in batch, since a misdetected language transcribes the entire file incorrectly. When you do use automatic identification, restrict the candidate list to the languages you actually expect, because a shorter candidate list improves detection confidence.
For multi-lingual content where speakers switch languages mid-recording, Transcribe's multi-language mode identifies the dominant language per segment rather than per file, which handles code-switching far better than older approaches.
Enhancing Accuracy with Custom Vocabularies and Filters
Custom vocabularies are the highest-leverage accuracy tool in Transcribe. A custom vocabulary is a curated list of domain-specific terms, brand names, acronyms, and jargon that the base model doesn't recognize reliably. You create the vocabulary once, reference it by name in transcription jobs, and the model biases recognition toward those terms. For a medical application, a vocabulary of drug names and clinical terminology can transform unusable transcripts into accurate ones.
Vocabulary filters work in the opposite direction: they remove terms from transcripts. The primary use case is profanity filtering for customer-facing output, but they're also useful for suppressing recurring false positives that pollute your transcripts.
Content redaction is a separate, compliance-focused feature that masks PII such as names, credit card numbers, and social security numbers in the output transcript. It's available in both batch and streaming modes and is essential for call-center workloads governed by data protection rules. Redaction operates on the transcript text, so the original audio remains unmodified and must be protected separately.
Security, Encryption, and Compliance
Securing an AWS speech to text pipeline means protecting data at rest, in transit, and at the access-control layer. At rest, enable server-side encryption on both input and output S3 buckets, ideally with customer-managed KMS keys so you control key rotation and can prove separation of duties. Transcribe itself supports encryption of output transcripts with KMS.
In transit, all AWS API and streaming connections use TLS, and streaming sessions authenticate with Signature Version 4 signed requests. Never embed long-lived AWS credentials in client applications; for streaming from end-user devices, route audio through a backend proxy that holds the credentials, or use short-lived STS tokens.
At the access layer, scope IAM policies to specific actions and buckets. A transcription service role needs permission to read from the input bucket, write to the output location, and call the transcription APIs, and nothing broader.
On compliance, Amazon Transcribe is included in AWS services eligible under HIPAA BAA arrangements and is GDPR-capable when configured with appropriate region selection and data processing agreements. Always verify current compliance status on the AWS services in scope documentation before making commitments to customers.
Cost-Optimization Tips
Transcribe pricing is per second of audio, with different rates for batch and streaming, and surcharges for optional features like diarization, language identification, and call analytics. Streaming costs more per second than batch, which makes sense given the real-time infrastructure involved. Check current rates on the Amazon Transcribe pricing page.
Practical savings levers: prefer batch over streaming whenever real-time output isn't required, since batch rates are substantially lower. Trim silence and non-speech segments before submitting files, because you pay for every second submitted, not every second transcribed. Disable optional features like diarization and channel identification when your use case doesn't need them, since each adds per-minute cost. For high-volume workloads, watch for region-based price differences and process in the cheapest eligible region when data residency rules allow it.
Finally, the AWS Free Tier includes a monthly allowance of transcription minutes at no charge, which is enough to build and validate a complete pipeline before paying anything.
Common Pitfalls and Troubleshooting
The most frequent batch errors are IAM-related: jobs fail with access denied because the calling role lacks read access to the input bucket or write access to the output location. The fix is always the same: scope the policy to the exact buckets and retry.
In streaming, the dominant error is a sample-rate mismatch between the declared rate and the actual PCM audio, producing either an immediate failure or garbled output. Verify the rate at the capture source, not just in your configuration.
Unsupported format errors in batch usually mean a corrupted file or a mislabeled extension; validate files with a media inspection step before submission. Slow job starts in batch are normal during high-demand periods, so build status polling with backoff rather than tight loops. And if accuracy is consistently poor despite clean audio, the culprit is usually missing custom vocabulary coverage for domain terms, not the model itself.
Best-Practice Checklist
Before launching a production AWS speech to text pipeline, run through this list:
- Use lossless audio formats (FLAC or WAV PCM) for batch, PCM for streaming
- Pin the language code unless content language is genuinely unknown
- Match declared sample rate to actual audio rate, verified at the source
- Enable KMS encryption on input and output buckets
- Scope IAM policies to specific buckets and transcription actions only
- Use EventBridge notifications instead of polling for batch job completion
- Add a custom vocabulary for domain-specific terminology
- Enable PII redaction for any customer conversation workload
- Route streaming credentials through a backend proxy, never embed them in clients
- Monitor per-second spend and disable unused optional features
Definitions Glossary
Batch transcription: The asynchronous processing of a stored media file, where audio is uploaded to S3, a transcription job runs, and the JSON transcript is written to an output location. Best for recorded content where real-time results aren't needed.
Streaming transcription: Real-time conversion of live audio into text over a WebSocket or HTTP/2 connection, returning partial results within milliseconds and final committed segments as speech completes. Best for live captions and voice interfaces.
Speaker diarization: The process of separating a transcript by speaker, labeling which words were spoken by which participant. Essential for call analytics and multi-speaker meeting transcription.
Custom vocabulary: A curated list of domain terms, brand names, and acronyms supplied to Amazon Transcribe to bias recognition toward words the base model handles poorly.
Content redaction: Automatic masking of personally identifiable information, such as names and card numbers, in the output transcript, used for compliance in customer conversation workloads.
Real-time transcription (VideoSDK): Live captioning delivered inside a VideoSDK call or stream, where the SDK's transcription capability converts participant speech to text within the meeting itself. See the VideoSDK transcription docs.
Key Takeaways
- AWS speech to text is delivered through Amazon Transcribe, which supports both asynchronous batch transcription and real-time streaming transcription over WebSocket or HTTP/2.
- Batch mode is cheaper and simpler for recorded media, while streaming mode delivers partial results in milliseconds for live captions and voice interfaces.
- Accuracy is determined mostly upstream: lossless formats, correct sample rates, and a custom vocabulary for domain terms matter more than any model setting.
- Production security requires KMS encryption on input and output buckets, least-privilege IAM policies, and credentials kept off client devices.
- For applications that already run on real-time communication, VideoSDK's built-in real-time and post-call transcription delivers captions inside the call without building a separate pipeline.
Conclusion
AWS speech to text through Amazon Transcribe gives developers a managed, pay-per-second path from audio to structured text, covering everything from call-center analytics to live captioning. The difference between a fragile prototype and a reliable pipeline comes down to the details covered here: correct audio settings, scoped IAM permissions, encryption, and cost-aware feature selection. Start with the Amazon Transcribe getting started guide to run your first batch job, and if you're building transcription into a live video or voice application, explore VideoSDK's video calling SDK with built-in transcription, or grab a free account at app.videosdk.live. What are you building with speech to text? Drop a comment, I'd love to hear what kind of transcription use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ