


Amazon Speech to Text is the developer-facing name for Amazon Transcribe, AWS's fully managed automatic speech recognition service. It converts audio and speech into searchable text using batch transcription for stored files and streaming transcription for live audio, with support for speaker diarization, custom vocabularies, and content redaction. This guide covers how to choose a mode, configure the service, optimize accuracy and cost, and ship transcription features in production. If you also need live transcription inside video or voice applications, VideoSDK's real-time transcription integrates speech-to-text directly into its calling SDKs.
Every podcast episode, customer support call, and recorded meeting holds information that is useless until it becomes searchable text. Amazon Speech to Text, delivered through the Amazon Transcribe service, is AWS's answer to that problem: a managed automatic speech recognition (ASR) system that converts speech to text without you training or hosting any models. Developers increasingly reach for it because it plugs into the AWS ecosystem they already run on, from S3 storage to IAM access control. This article walks through what the service does, how to pick between batch and streaming transcription, how to set it up correctly, and how to keep accuracy high and costs low. By the end, you will know exactly how to configure Amazon Speech to Text for your use case and avoid the mistakes that trip up first-time integrators.
What Is Amazon Speech to Text?
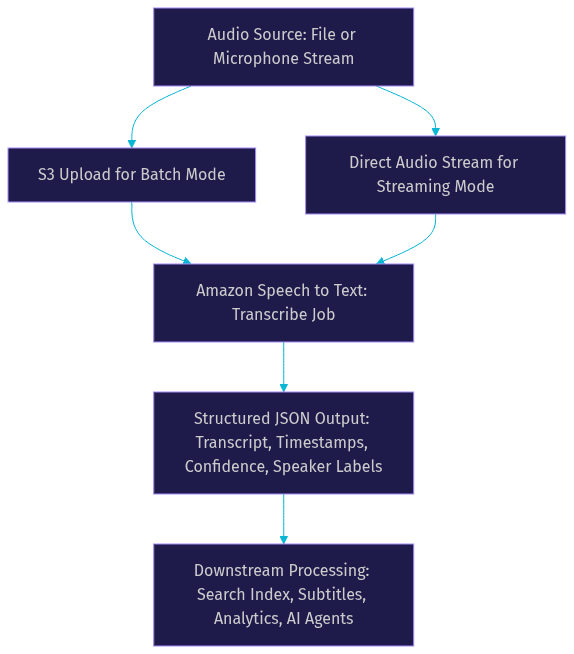
Amazon Speech to Text is defined as the speech recognition capability of Amazon Transcribe, a fully managed AWS service that converts audio into text using large-scale deep learning models trained on massive speech datasets. Amazon Transcribe works by accepting either an audio file or a live audio stream, routing it through its ASR models, and returning structured output that includes the full transcript, word-level timestamps, confidence scores, and optional metadata such as speaker labels.
The service supports two core operating modes. Batch transcription processes files you have already stored, typically in an S3 bucket, and returns results asynchronously. Streaming transcription processes live audio in real time, returning partial and final results as speech happens, which makes it suitable for live captions and voice interfaces.
Beyond raw transcription, Amazon Transcribe offers multi-language support across dozens of languages and dialects, automatic language identification, speaker diarization (separating who said what), custom vocabularies for domain-specific jargon, and content redaction for sensitive information. Because it is fully managed, there are no servers to provision and no models to train; you pay per minute of audio processed. For developers building live voice or video applications, VideoSDK also provides real-time transcription built into its communication SDKs, which pairs well with cloud ASR services like Transcribe.
Choosing the Right Transcription Mode
The single most consequential decision you make with Amazon Speech to Text is choosing between batch and streaming transcription, because it shapes latency, cost, and integration complexity for your entire pipeline.
Batch Transcription vs Streaming Transcription
Batch transcription is the workhorse for stored audio. You upload a file to S3, start a transcription job, and retrieve the JSON result when the job completes. Latency is measured in minutes rather than milliseconds, which is fine for podcast publishing, subtitle generation, and archive search. Batch jobs support larger files, more post-processing features such as speaker diarization and channel identification, and generally cost the same per minute as streaming.
Streaming transcription is built for live audio. You open a persistent connection, send audio chunks as they are captured, and receive interim results almost immediately, with final results arriving shortly after each utterance ends. This is what you need for live captions on a webinar, voice command interfaces, or real-time agent assistance in a call center. The trade-off is integration complexity: you must manage the stream lifecycle, handle reconnection, and design your downstream logic around partial results that can be revised.
When to Use Real-Time vs Post-Processing
Use streaming transcription when the user or another system needs the text while the conversation is still happening: live captions, real-time compliance monitoring, or interactive voice agents. Use batch transcription when the audio already exists and nobody is waiting: transcribing a back catalog of podcasts, generating subtitles for uploaded videos, or analyzing recorded calls overnight.
Two practical criteria settle most decisions. First, latency tolerance: if a delay of several minutes is acceptable, batch is simpler and more feature-rich. Second, audio source: if your audio arrives as a microphone or telephony stream rather than a file, streaming is the natural fit. File size matters too; very long recordings are often easier to handle as batch jobs than as sustained streams.
Setting Up Amazon Speech to Text
Getting Amazon Speech to Text running is mostly an exercise in preparing your AWS environment correctly, because the transcription call itself is the easy part.
Prerequisites: AWS Account, IAM Role, S3 Bucket
You need three things before your first transcription job. First, an AWS account with Amazon Transcribe enabled in your target region. Second, an IAM role or user with permission to start transcription jobs, read from your input S3 bucket, and write results to your output location; the principle of least privilege applies, so scope the policy to the specific buckets involved. Third, an S3 bucket for input audio and output transcripts, or a plan to stream audio directly if you are using streaming mode. Keep input and output in the same region as the Transcribe service to avoid cross-region data transfer charges and latency.
Configuring Input Audio
Amazon Speech to Text accepts common audio formats including FLAC, WAV, MP3, and OGG, plus telephony-oriented formats for call audio. Lossless formats such as FLAC and WAV generally produce the best accuracy because they avoid compression artifacts that confuse the model. Match your declared sample rate to the actual audio sample rate; a mismatch is one of the most common causes of failed or garbled jobs. For telephony audio, 8 kHz is typical, while studio recordings usually arrive at 16 kHz or higher. If your audio has multiple channels, such as a two-channel call recording with agent and customer on separate channels, enable audio channel identification so each channel is transcribed separately and can be attributed correctly.
Enabling Advanced Features
Speaker diarization labels segments by speaker, which is essential for interviews, meetings, and any transcript where attribution matters. Language identification lets the service detect the spoken language automatically, useful for multilingual archives. Custom vocabularies improve recognition of product names, acronyms, and domain jargon that the base model mangles. Content redaction masks sensitive personal information in transcripts, which matters for healthcare and financial workloads. Each feature adds processing overhead, so enable only what your use case actually needs.
The end-to-end pipeline looks like this:
Managing Transcription Jobs and Results
Amazon Speech to Text exposes job management through the AWS console, the command line interface, and the AWS SDKs, so you can start, monitor, and retrieve transcription jobs from whatever surface fits your workflow. A batch job moves through a lifecycle from queued to in progress to completed or failed, and you can poll its status or configure event notifications to trigger downstream processing automatically when a job finishes.
The output is a structured JSON document stored at your designated output location. The top level contains the full transcript text plus job metadata. Beneath it, an items array breaks the transcript into individual words and punctuation, each with a start time, end time, and confidence score between zero and one. Speaker labels, when diarization is enabled, map time ranges to speaker identifiers so you can reconstruct who said what.
Parsing this output is where most of the engineering value lives. Word-level timestamps let you generate subtitles synchronized to the video, jump from search results to the exact moment in the audio, and align transcripts with other media. Confidence scores let you flag low-certainty words for human review, which is a practical pattern for quality-sensitive workflows like medical documentation. For streaming results, your parser must handle interim results that get revised, so design downstream consumers to treat partial transcripts as provisional until a final result arrives.
Optimizing Accuracy and Cost
Accuracy and cost are the two dials every production transcription pipeline ends up tuning, and both respond well to deliberate configuration rather than defaults.
Improving Accuracy
Start with audio quality, because no configuration rescues bad input. Record at 16 kHz or higher for general speech, use a lossless format where practical, and minimize background noise at capture time. Then layer on custom vocabularies for the terms your domain actually uses: product names, industry acronyms, and proper nouns that the base model consistently mishears. Custom language models go further, adapting recognition to your specific audio style, such as casual customer calls versus scripted narration. Review low-confidence words systematically; a pipeline that routes anything below a confidence threshold of roughly 0.6 to human review catches most errors cheaply. Finally, enable diarization and channel identification where attribution matters, since misattributed speech is an accuracy failure even when every word is correct.
Controlling Costs
Amazon Transcribe pricing is based on the first minute of each audio segment processed, so a 61-second file bills as two minutes. Trim silence and dead air before submitting audio, especially for call recordings with long hold times. The service includes a free tier for the first months of usage, after which standard transcription bills per audio minute, with add-ons like Call Analytics and medical transcription priced higher. Batch and streaming standard transcription cost the same per minute, so choose based on need, not price. Disable expensive options like speaker diarization when you do not use the labels, and avoid re-transcribing unchanged audio by caching results keyed to the source file. Storage is usually a minor cost, but lifecycle policies on your output bucket keep transcript archives from accumulating forever.
Real-World Use Cases
Three scenarios illustrate where Amazon Speech to Text delivers measurable business impact.
Podcast transcription for publishing. A media team transcribes its weekly show with batch jobs, generates word-level timestamps, and publishes both a searchable transcript page and chapter markers. The result is better SEO through indexable text, improved accessibility, and listeners who can jump straight to the segment they want.
Call-center analytics. A support organization routes recorded calls through Amazon Transcribe Call Analytics, which adds sentiment detection, intent categorization, and automatic summary generation on top of raw transcription. Supervisors surface angry calls in minutes instead of listening to hours of audio, and quality teams track recurring complaint themes across thousands of interactions.
Medical documentation. A telehealth provider uses Amazon Transcribe Medical, the HIPAA-eligible variant, to convert clinician-patient conversations into draft clinical notes. Physicians review and sign off rather than typing, which reduces documentation time and lets them stay focused on the patient. For teams building telehealth apps with live video, pairing a calling SDK like VideoSDK with a medical-grade ASR backend is a common architecture.
Security, Privacy, and Compliance
Amazon Speech to Text processes your audio within the AWS region you choose, and transcription results are stored in your own S3 bucket under your existing access controls. Audio passed to the service is not used to train AWS models, and you can request deletion of any retained content through standard AWS support channels. Encryption is available both in transit and at rest, and S3 bucket policies plus IAM roles give you fine-grained control over who can read transcripts containing sensitive material.
On the compliance front, Amazon Transcribe is HIPAA-eligible, and AWS maintains GDPR-supporting commitments and regional data residency options that help European workloads stay compliant. Content redaction can mask personal information such as names, addresses, and card numbers directly in the output. For regulated industries, the practical pattern is to combine least-privilege IAM, encryption, redaction, and short retention windows on transcript storage.
Common Pitfalls and Troubleshooting
Most Amazon Speech to Text failures fall into four familiar categories, and each has a straightforward fix.
Mismatched sample rates. Declaring a sample rate that differs from the actual audio produces errors or nonsense transcripts. Always inspect your source audio's true sample rate and declare it accurately, or let the service detect it where supported.
Unsupported or corrupted audio formats. A file with the wrong extension, a broken header, or an unsupported codec fails the job before transcription begins. Validate files with a media inspection step before submission.
IAM permission issues. Jobs fail silently or with access-denied errors when the execution role cannot read the input bucket or write to the output location. Verify the policy covers both buckets and the Transcribe actions, and test with the exact role your application uses.
Streaming connection drops. Live streams that break mid-session lose audio unless your client buffers and reconnects. Build reconnection logic with buffered replay, and treat interim results as provisional so a reconnect does not corrupt your final transcript.
Definitions Glossary
Batch Transcription: An asynchronous Amazon Transcribe mode that processes stored audio files, typically from S3, and returns results as a JSON document when the job completes.
Streaming Transcription: A real-time Amazon Transcribe mode that processes live audio chunks and returns interim and final results as speech occurs, suited for live captions and voice interfaces.
Speaker Diarization: The process of labeling audio segments by speaker identity, so a transcript shows who said what without requiring separate channels.
Custom Vocabulary: A list of domain-specific words and phrases supplied to Amazon Transcribe so the model recognizes product names, acronyms, and jargon accurately.
Confidence Score: A value between zero and one that Amazon Transcribe attaches to each recognized word, indicating how certain the model is, commonly used to flag words for human review.
Key Takeaways
- Amazon Speech to Text is delivered through Amazon Transcribe, a fully managed ASR service with batch and streaming modes, so no model training or infrastructure is required.
- Choose batch transcription for stored files where minutes of latency are acceptable, and streaming transcription when users need text while speech is still happening.
- Accuracy improves most from good input audio, correct sample rates, and custom vocabularies, while cost drops when you trim silence and disable unused features like diarization.
- The JSON output's word-level timestamps and confidence scores are the raw material for subtitles, search, and human-review workflows.
- Amazon Transcribe is HIPAA-eligible and GDPR-supporting, and for live video or voice applications, pairing it with a real-time communication SDK like VideoSDK is a proven production pattern.
Conclusion
Amazon Speech to Text, through Amazon Transcribe, gives developers a managed, pay-per-minute path from raw audio to structured, searchable text, with the flexibility to serve everything from podcast archives to HIPAA-eligible medical documentation. The decisions that matter most are picking the right transcription mode, configuring audio correctly, and tuning accuracy and cost deliberately rather than accepting defaults. Start with the AWS free tier on a small batch job, then layer in diarization, custom vocabularies, and redaction as your use case demands. If your product involves live conversations, explore how VideoSDK's real-time communication SDKs bring transcription, recording, and voice AI together in one integration. What are you building with speech-to-text? Drop a comment and share your implementation experience, and check out the VideoSDK code samples for working transcription-enabled calling apps.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ