


Live meeting transcription is the real-time conversion of spoken meeting audio into searchable, timestamped text, often paired with AI-generated summaries and action items. VideoSDK provides built-in live transcription for its video and audio calling rooms, so developers can add real-time captions and post-call notes to any app without wiring a separate speech-to-text pipeline. This guide explains how transcription works under the hood and how to build or buy it.
Every team has been there. The meeting ends, everyone nods at the action items, and two days later nobody remembers who agreed to what. Notes get lost, decisions go unrecorded, and remote teammates who missed the call have no way to catch up except a 45-minute recording nobody watches.
Live meeting transcription fixes this at the source. Instead of reconstructing what happened, you capture it as it happens, with speaker labels, timestamps, and increasingly an AI layer that turns raw speech into structured minutes, decisions, and tasks. For regulated industries, transcription is also becoming a compliance requirement rather than a convenience.
This article covers how live meeting transcription actually works under the hood, how to build your own pipeline, how the leading tools compare, and the best practices that separate a usable transcript from a garbled one.
What Is Live Meeting Transcription?
Live meeting transcription is defined as the process of converting spoken audio from a meeting into text in near real time, while the conversation is still happening. It differs from post-meeting transcription, where a recording is processed after the call ends and results arrive minutes or hours later.
The two approaches serve different needs. Real-time transcription, sometimes called live captioning, powers on-screen captions, live search inside a conversation, and instant accessibility for participants who are deaf or hard of hearing. Post-meeting transcription powers archives, searchable knowledge bases, and AI-generated meeting minutes delivered after the fact.
Typical use cases span remote team standups, customer support calls, telehealth consultations, online classrooms, sales calls, legal depositions, and podcast recording. In each case the value is the same: a durable, searchable record of what was actually said, produced without anyone pausing to take manual notes.
VideoSDK provides live meeting transcription through its Rooms-based architecture, where every participant's audio stream can be routed to a speech-to-text engine and the resulting transcript delivered back to the room in real time, with post-call transcription and summaries available as a follow-up step.
How Live Meeting Transcription Works Under the Hood
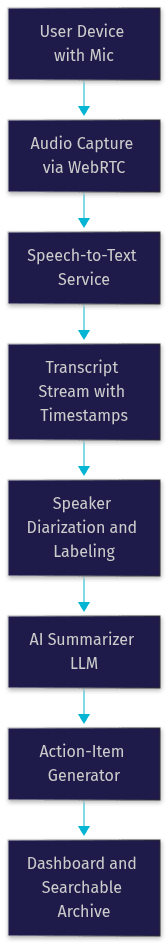
Every live transcription system, from a browser extension to an enterprise platform, follows the same pipeline: capture audio, convert speech to text, attribute text to speakers, and optionally summarize. The engineering choices at each stage determine latency, accuracy, and cost.
The pipeline starts with audio capture, moves through a speech-to-text engine that emits a stream of partial and finalized hypotheses, applies speaker diarization to label who said what, and optionally feeds the finished transcript into a large language model that produces minutes, decisions, and action items.
Audio Capture Options
There are three main ways to get meeting audio into a transcription pipeline. Browser extensions and tab capture grab the audio output of a meeting app running in the browser, which is quick to set up but fragile, since permissions and platform policies change frequently. Native SDKs embedded in your own app capture audio at the source, giving you clean per-participant streams with no mixing problems. Server-side capture, where the media server itself forks each participant's audio track to a transcription service, is the most reliable option because it never depends on the client device.
VideoSDK's Rooms-based architecture supports the server-side approach naturally: each participant's audio track can be routed to a speech-to-text provider while the call continues uninterrupted, which is why VideoSDK's live transcription avoids the echo and permission issues that plague extension-based tools.
Speech-to-Text Engines
The speech-to-text engine is the accuracy and latency heart of the system. Cloud services dominate production deployments. Amazon Transcribe and Google Cloud Speech-to-Text offer broad language coverage and tight integration with their respective clouds. Deepgram focuses on low-latency, high-accuracy streaming recognition, which matters when captions must appear within a second of speech. OpenAI Whisper excels at batch transcription of recordings and handles noisy audio well, though it is not designed for sub-second streaming.
On-premise and self-hosted models appeal to organizations with strict data-residency rules, trading operational burden for full control of the audio data. When choosing an engine, the practical trade-offs are latency for live captioning, word-error-rate on conversational audio, language coverage, and per-minute pricing.
Adding AI Summaries and Action Items
A raw transcript is useful but not readable. The final stage of the pipeline sends the transcript, usually in chunks or at the end of the call, to a large language model such as Anthropic Claude or Google Gemini with instructions to produce structured output: a summary, a list of decisions, and a list of action items with owners.
The key engineering decision is when to summarize. Summarizing during the call gives participants a live digest but costs more API calls and can produce inconsistent results as context grows. Summarizing after the call, using the full transcript, produces cleaner minutes and is the approach most meeting-notes products take. VideoSDK supports both patterns, with post-call transcription and summary available alongside real-time captions.
Building Your Own Live Meeting Transcription Solution
Building your own pipeline gives you control over data handling, branding, and workflow integration that off-the-shelf tools cannot match. The build breaks into four decisions, and each one is independent enough to change later without rebuilding the whole system.
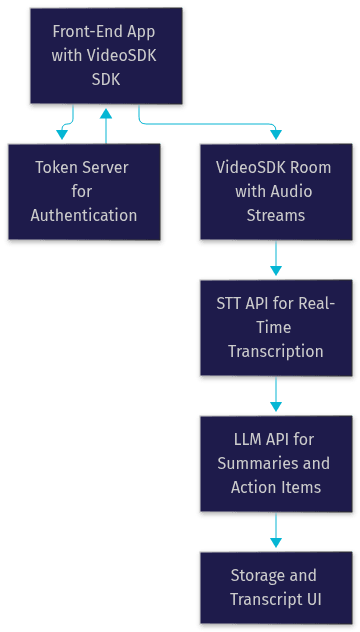
The overall architecture layers cleanly: your front-end captures and renders, a token server handles authentication, and external APIs do the heavy lifting for speech recognition and summarization.
Choose the Right STT Provider
Evaluate providers against five criteria in this order of importance for live use: latency, accuracy on conversational speech, language support, pricing, and data-privacy posture. For live captioning, aim for a provider that returns partial hypotheses in under 500 milliseconds so captions feel attached to the speech. For post-call minutes only, accuracy and price matter more than latency, and a batch model like Whisper becomes viable. Check where the provider processes and stores audio, because that determines your GDPR and HIPAA posture.
Set Up Audio Capture
The cleanest path is to let the meeting platform itself deliver audio to your pipeline. With VideoSDK, participants join a Room, and each participant's audio track is accessible server-side, so you can route it to your chosen STT provider without any browser extension or tab capture. If you must transcribe third-party meetings on Google Meet, Zoom, or Teams, a browser extension that captures tab audio is the fallback, but expect permission prompts and platform-specific quirks. The VideoSDK quick-start guide walks through creating a Room and joining participants, which is the foundation the transcription flow sits on.
Integrate AI Summarisation
Once you have a transcript, send it to an LLM with a structured request: produce a short summary, extract decisions, and list action items with owners and deadlines. Chunk long transcripts or summarize per agenda section to keep responses focused. Store both the raw transcript and the structured output, because the raw text is your searchable archive and the structured output is what people actually read. VideoSDK's post-call transcription and summary feature handles this step natively, returning structured notes once the session ends.
Handle Security and Compliance
Transcription pipelines handle some of the most sensitive data a company owns: unguarded spoken conversation. Use token-based authentication for every room and API call, generate tokens server-side so secrets never reach the client, and enable end-to-end encryption for the media itself. For GDPR, know exactly where audio and transcripts are stored, how long they are retained, and how participants can request deletion. If you are building for healthcare or legal clients, prefer providers that offer Business Associate Agreements and data-residency options, and document your retention policy before launch rather than after.
Evaluating Popular Live Transcription Tools
If building your own pipeline is not on the roadmap, a mature tool gets you 80 percent of the value on day one. The tools below represent the current landscape of real-time meeting transcription and AI notes products.
Tactiq is one of the most established options, offering real-time transcription across more than 30 languages with a free tier and paid add-ons for AI features. It works as a browser extension across major meeting platforms.
FoxyNote provides real-time transcription in 20-plus languages with AI summaries, on a free and paid plan structure aimed at individual professionals and small teams.
MeetingJuice stands out for language coverage, supporting more than 80 languages, with a free-forever core offering and paid add-ons for advanced AI features.
MeetingsBrief is a lightweight, free option covering 10-plus languages, best suited for users who want simple notes without a subscription.
Voxsora takes a different angle, combining live transcription with a voice bot, priced between roughly $8 and $39 per month depending on tier.
VideoSDK Live Transcription is the developer option: real-time transcription built into the RTC platform itself, with AI summaries available through integration, on pay-as-you-go pricing.
| Tool | Real-time? | Languages | AI Summary | Pricing (approx.) |
|---|---|---|---|---|
| Tactiq | Yes | 30+ | Yes | Free tier, paid add-ons |
| FoxyNote | Yes | 20+ | Yes | Free / paid plans |
| MeetingJuice | Yes | 80+ | Yes | Free forever, paid add-ons |
| MeetingsBrief | Yes | 10+ | Yes | Free |
| Voxsora | Yes | 15+ | Yes (voice bot) | $8-$39/mo |
| VideoSDK (Live Transcription) | Yes | 30+ (via provider) | Yes (via integration) | Pay-as-you-go |
The most important row depends on who you are. If you are an end user transcribing other people's meetings, Tactiq or MeetingJuice cover the broadest needs. If you are a developer embedding transcription into your own product, VideoSDK is the only row that gives you an API rather than an app.
When to Choose a Dedicated Tool vs. Building Your Own
Choose a dedicated tool when your team is small, your meetings run on standard platforms, and your privacy requirements are satisfied by the vendor's policy. The setup cost is zero and the workflow is proven.
Build your own when transcription is a feature of your product rather than a personal productivity aid, when you need transcripts to flow into your own CRM, knowledge base, or compliance system, or when data-privacy rules require that audio never leaves your infrastructure. The build-versus-buy line usually falls around customization: the moment you need transcripts to trigger workflows inside your own application, an embedded SDK wins over any extension-based tool.
Best Practices for High-Quality Live Transcription
Transcription quality is determined before the AI ever sees the audio. Microphone quality and placement matter more than engine choice: a decent headset mic on each participant beats a single conference-room mic capturing five voices.
On the network side, transcription pipelines are bandwidth-sensitive, so ensure participants have stable connections and let adaptive streaming handle degradation rather than dropping audio entirely. Encourage speakers to label themselves or use per-participant audio tracks so diarization does not have to guess, since speaker identification errors are the most common source of confusing transcripts.
Handle background noise at the source with noise suppression, which VideoSDK includes natively, rather than hoping the STT engine filters it out. Finally, build a post-meeting review step into your workflow: even the best engines produce errors on names, jargon, and acronyms, and a two-minute human pass over the action items catches the mistakes that matter.
Future Trends in Live Meeting Transcription
Three trends are reshaping the space. Multilingual real-time translation is merging with transcription, so a meeting in Japanese can produce live English captions, collapsing the language barrier in distributed teams. Voice-activated assistants are moving from passive listeners to active participants, able to be asked questions mid-meeting using the live transcript as context. And transcripts are becoming the connective tissue of knowledge bases, with meeting content automatically indexed, linked to documents, and surfaced in search rather than sitting in a silo.
For developers, the direction is clear: transcription is shifting from a feature you add to an assumption you build on, and platforms that expose transcripts as first-class data, as VideoSDK does through its REST APIs, are where these workflows become possible.
Definitions Glossary
Live meeting transcription: The real-time conversion of spoken meeting audio into timestamped text while the conversation is happening, used for captions, accessibility, and instant record-keeping.
Speaker diarization: The process of separating a transcript into segments attributed to individual speakers, either through per-participant audio tracks or acoustic modeling.
Speech-to-text (STT): The engine that converts audio into text, available as cloud services like Deepgram and Google Cloud Speech-to-Text or self-hosted models like Whisper.
Room: A VideoSDK meeting room that participants join and share media streams within, and the unit through which audio is routed to transcription services.
Meeting token: A JWT that authenticates a participant's access to a VideoSDK room, generated server-side to keep credentials off the client.
Key Takeaways
- Live meeting transcription converts speech to text in real time, enabling captions, accessibility, and automatic meeting minutes without manual note-taking.
- The pipeline has four stages: audio capture, speech-to-text, speaker labeling, and optional AI summarization into minutes and action items.
- Dedicated tools like Tactiq and MeetingJuice suit end users; building your own pipeline suits products where transcription must integrate with internal workflows.
- VideoSDK provides built-in live transcription through its Rooms-based architecture, with per-participant audio routing, noise suppression, and post-call summaries.
- Quality depends heavily on microphone setup, stable bandwidth, and per-speaker audio tracks, not just on the STT engine you choose.
Conclusion
Live meeting transcription has moved from a nice-to-have to infrastructure, whether you are capturing compliance records, feeding an AI note-taker, or making meetings accessible. The technology is now mature enough that the real decision is not whether to transcribe but whether to buy a tool or embed the capability.
If you are building a product where meetings happen, embedding transcription directly is the stronger path. Start with the VideoSDK live transcription docs, grab the quick-start guide, and create a free account at app.videosdk.live to test it. What are you building with live meeting transcription? Drop a comment, I would love to hear what kind of use case you are working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ