


Transcription works by converting captured audio into a visual frequency representation called a spectrogram, then using an acoustic model to map sound patterns to phoneme probabilities, and a language model to turn those probabilities into fluent, punctuated text. Modern systems like OpenAI Whisper and Deepgram use transformer-based neural networks for both stages. VideoSDK brings this pipeline into live applications with real-time transcription available directly inside its video and audio calling SDKs.
Every video call you join, every voice note you send, and every meeting you record now generates text almost as a default expectation. Captions for accessibility, searchable meeting notes, telemedicine documentation, and compliance records all depend on one technical process: automatic speech recognition. Yet most explanations of how transcription works stop at "AI listens and writes it down," which tells a developer almost nothing useful.
The reality is a multi-stage pipeline with real engineering trade-offs at every step. Sampling rates, windowing, model architecture, and deployment choices each affect accuracy, latency, and cost in ways you can measure. Understanding the pipeline helps you debug poor transcription quality, pick the right provider, and decide whether you need real-time or batch processing.
This article walks through the full journey from microphone physics to the final string of text inserted into your application UI, including the streaming "stitch and refine" step that most tutorials skip, and practical tips for improving accuracy in production.
The End-to-End Transcription Pipeline
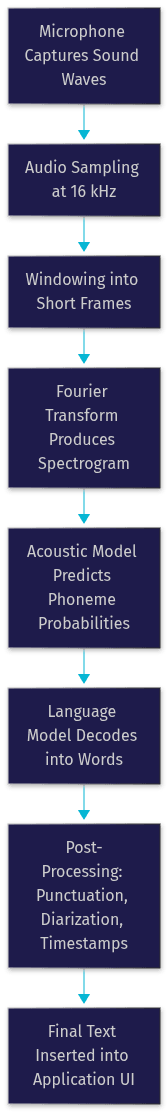
Transcription is a sequential transformation process: raw sound becomes sampled numbers, numbers become a frequency image, the image becomes phoneme probabilities, and probabilities become words. Each stage compresses information and adds interpretation, and a weakness at any stage degrades everything downstream.
The pipeline begins with audio capture, where a microphone converts pressure waves into an electrical signal that gets digitized at a fixed sampling rate. The digitized waveform is then sliced into short overlapping windows and transformed into a spectrogram, a time-frequency representation that neural networks can process like an image. An acoustic model reads the spectrogram and predicts which speech sounds, or phonemes, are likely present at each moment. A language model then decodes those predictions into actual words, resolving ambiguity using context. Finally, post-processing adds punctuation, speaker labels, and timestamps before the text is delivered to your application.
The rest of this article examines each stage in detail, then covers the streaming versus batch distinction, deployment options, and accuracy optimization.
Stage 1: Audio Capture and Sampling
Everything in transcription starts with the microphone, a transducer that converts air pressure variations into a continuously varying electrical voltage. Before any software sees the audio, that analog signal must be digitized by measuring its amplitude at regular intervals, a process called sampling.
The sampling rate determines how much of the original sound survives digitization. Speech recognition systems typically use 16 kHz sampling, which captures frequencies up to 8 kHz. This is not an arbitrary choice. Human speech energy, including most of the fricative sounds like "s" and "f" that distinguish similar words, concentrates below 8 kHz. The Nyquist theorem states that you must sample at least twice the highest frequency you want to capture, so 16 kHz preserves everything relevant to speech intelligibility.
Higher rates add little for transcription. Sampling at 48 kHz captures ultrasonic detail and richer audio for music playback, but speech recognition models discard most of it. In fact, feeding 48 kHz audio into a model trained on 16 kHz data can hurt accuracy unless the audio is downsampled first. Most cloud providers, including Deepgram and AssemblyAI, normalize incoming audio to 16 kHz internally.
One practical consequence: if you control recording, capture at 16 kHz mono. Stereo channels double your bandwidth and payload size for almost no accuracy gain, and mono is what most models expect anyway.
Stage 2: From Waveform to Spectrogram
A raw waveform is nearly useless to a neural network because it mixes all frequencies together over time. The next stage converts it into a representation that separates frequency content across time, making speech patterns visible and learnable.
The process starts with windowing. The audio stream is sliced into very short frames, typically 25 milliseconds, with each frame overlapping the previous one by about 10 milliseconds. Overlapping ensures that sounds spanning frame boundaries are not cut in half and lost. Each window is then passed through a Fourier transform, a mathematical operation that decomposes the signal into its constituent frequencies and their intensities at that moment.
Stacking these frequency snapshots over time produces a spectrogram: a two-dimensional image where the horizontal axis is time, the vertical axis is frequency, and pixel brightness encodes energy. This is why people describe speech recognition models as "looking at" audio, because after this stage, the input genuinely is an image.
Most modern pipelines apply one more transformation: the mel scale. Human hearing perceives frequency differences logarithmically, so we distinguish low frequencies much more finely than high ones. The mel scale warps the frequency axis to match human perception, giving the model more resolution exactly where speech information is densest. The result is a mel spectrogram, the standard input format for models like Whisper.
Stage 3: Acoustic Modeling
The acoustic model is where machine learning does the heavy lifting: it maps spectrogram patterns to probabilities over speech sounds. This is the component that has been transformed most dramatically by deep learning.
Older systems used hidden Markov models with hand-engineered features, treating speech as a sequence of discrete states. Modern systems use neural networks, and increasingly transformer-based architectures, to process the entire spectrogram contextually. OpenAI's Whisper, released in 2022 and still widely used, is a encoder-decoder transformer trained on roughly 680,000 hours of multilingual audio. Deepgram's Nova models and AssemblyAI's Universal model follow similar end-to-end approaches.
For each slice of the spectrogram, the acoustic model outputs a probability distribution over possible phonemes or character sequences. A stretch of audio might be 70 percent likely to contain the "k" sound, 20 percent likely to be "t," and 10 percent something else. These are not final answers; they are evidence. The model also produces confidence scores, which downstream systems use to flag uncertain segments for review or to trigger fallback behavior.
End-to-end models blur the line between acoustic and language modeling by predicting words directly from audio, but the conceptual division still matters for developers. When transcription quality degrades, the cause is usually acoustic: background noise, a distant microphone, or overlapping speakers corrupt the spectrogram before any language knowledge can help.
Stage 4: Language Modeling and Contextual Decoding
Sound alone is fundamentally ambiguous, and the language model is what resolves that ambiguity into coherent text. Consider the sentence fragment "let me check the." The next word could be "mail," "male," or "meal," and they sound nearly identical. The acoustic model cannot fully distinguish them; the language model can, because "check the mail" is vastly more probable in context.
This stage is called decoding: the system searches through the acoustic model's probability outputs to find the word sequence that best fits both the audio evidence and the statistical structure of the language. Modern approaches integrate this directly into the neural network, where the model's internal language knowledge, absorbed during training on vast text corpora, guides word-by-word generation.
The language model also handles punctuation and capitalization. Whisper and similar models predict punctuation tokens as part of their output, which is why modern transcripts arrive fully formatted rather than as lowercase word streams. Contextual decoding additionally enables features like inverse text normalization, converting spoken "twenty five dollars" into written "$25."
For developers, the practical lever here is domain adaptation. A general language model will transcribe "deploy the Kubernetes manifest" poorly if it never saw technical vocabulary in training. Many providers let you supply custom vocabularies or boost specific phrases, which effectively biases the language model toward your domain's terminology.
Stage 5: Post-Processing and Text Insertion
The final stage turns decoded words into a usable transcript. Post-processing covers everything from formatting to speaker attribution, and it is where raw model output becomes an application feature.
Punctuation and casing arrive from the model itself in most modern systems, but several other refinements happen afterward. Speaker diarization labels each segment with its speaker, answering "who said what" in multi-person audio. Diarization runs as a separate model that clusters voice characteristics, and its accuracy drops sharply when speakers overlap or sound similar. Timestamping attaches time offsets to words or segments, which is essential for captions, searchable recordings, and jumping to specific moments in a video.
Text insertion is the step developers own. The transcript must reach your UI in a form that renders well: streamed word-by-word for live captions, or delivered as a complete document for batch processing. In live applications, this means handling partial results that get revised as more context arrives, a topic covered in the next section.
If you are building transcription into a live video or audio application, VideoSDK provides real-time transcription as a built-in capability of its video calling SDK, along with post-call transcription and summaries accessible through its REST APIs. The transcript flows into your participant UI alongside the media streams, so you do not have to wire a separate transcription service into your call infrastructure.
Real-Time vs. Batch Transcription
Real-time and batch transcription run the same core pipeline but with different engineering constraints, and the difference comes down to how much future context the system is allowed to see.
Batch transcription processes a complete recording after the fact. The model sees the entire audio file, so it can use both past and future context when decoding each word, producing the highest possible accuracy. Latency is measured in minutes or hours, which is fine for recorded meetings, voicemail processing, and media archiving.
Real-time, or streaming, transcription must produce text while the person is still speaking. Audio arrives in small chunks, often a few hundred milliseconds each, and each chunk is transcribed with only the preceding context available. This creates the latency-accuracy trade-off: smaller chunks mean faster on-screen text but less context per decision, while larger chunks improve accuracy at the cost of visible delay.
Streaming systems handle this with a technique best described as stitch and refine. The system transcribes each chunk immediately and displays a partial result, then revises earlier words as new chunks arrive and provide more context. Users see captions that occasionally correct themselves a word or two back. This is not a bug; it is the deliberate mechanism that lets streaming transcription approach batch accuracy while keeping perceived latency under a second.
Choose streaming when the text must appear live: captions, live agent assistance, real-time moderation. Choose batch when quality matters more than immediacy: meeting minutes, legal records, published transcripts.
Deployment Choices: On-Device vs. Cloud
Where the pipeline runs shapes privacy, latency, bandwidth, and cost, and the right answer depends on your constraints.
On-device transcription, using frameworks like Apple's Speech framework or Whisper running locally, keeps audio entirely on the hardware. This maximizes privacy, works offline, and eliminates per-minute API costs, at the price of larger app bundles, battery drain, and generally lower accuracy than the largest cloud models. Cloud transcription sends audio to a provider's infrastructure, giving you state-of-the-art models, custom vocabulary support, and diarization, but adding network latency, per-minute pricing, and data governance considerations.
For live calls, cloud transcription is the common choice because the audio is already being transmitted for the conversation itself. For sensitive contexts like telemedicine or legal consultations, on-device or self-hosted options may be mandated by regulation.
Practical Tips to Boost Accuracy
Most transcription quality problems are acoustic, not algorithmic, which means you can fix many of them without changing models.
First, control the microphone. A headset mic positioned a few centimeters from the mouth dramatically outperforms a laptop microphone across a table, because signal-to-noise ratio is the single biggest accuracy factor. Second, reduce noise at the source: encourage headset use in meetings, and prefer providers with built-in noise suppression. Third, use domain adaptation. Supply custom vocabulary for product names, acronyms, and technical terms; most providers support phrase boosting or custom language model training. Fourth, match the model to the audio: telephony audio at 8 kHz needs a model trained on telephone speech, not wideband studio audio. Finally, for multi-speaker recordings, enable diarization and, where possible, record each speaker on a separate channel, which makes speaker attribution nearly perfect compared to single-mixture diarization.
Common Pitfalls and How to Mitigate Them
Even a well-designed integration hits predictable problems, and knowing them in advance saves debugging time.
Background noise is the most common accuracy killer. Mitigate it with noise suppression before the audio reaches the model, and by guiding users toward close-mic setups. Overlapping speech degrades both recognition and diarization, since two voices in one spectrogram confuse the acoustic model; enforce turn-taking norms in meetings and use per-channel audio where the platform allows it. Latency spikes in streaming setups usually trace to oversized chunks or network jitter; smaller chunks with overlap smooth perceived delay. Authentication errors, like expired or malformed tokens when calling a transcription API, cause silent failures where transcripts simply stop arriving, so implement token refresh and explicit error handling rather than assuming success. Finally, language and accent mismatches between the model and your users produce systematically poor results; test with real user audio from your actual audience before committing to a provider.
Definitions Glossary
Spectrogram: A two-dimensional representation of audio where one axis is time, the other is frequency, and intensity encodes energy. Speech recognition models process spectrograms as image-like inputs.
Sampling rate: The number of amplitude measurements taken per second when digitizing audio. Speech recognition typically uses 16 kHz, which captures all frequencies relevant to speech intelligibility.
Acoustic model: The neural network component that maps spectrogram patterns to probability distributions over speech sounds or character sequences.
Language model: The component that uses statistical and learned knowledge of a language to resolve ambiguous sounds into the most probable word sequence, adding punctuation and fluency.
Speaker diarization: The post-processing step that labels transcript segments by speaker, answering who said what in multi-person audio.
Real-time transcription: Streaming transcription that produces text while speech is ongoing, using small audio chunks and partial results that are revised as more context arrives.
Key Takeaways
- Transcription is a five-stage pipeline: audio capture, spectrogram generation, acoustic modeling, language modeling, and post-processing, and weaknesses compound downstream.
- A 16 kHz sampling rate captures everything relevant to speech; higher rates add cost without accuracy benefit for transcription.
- The acoustic model interprets sound patterns while the language model resolves ambiguity, which is why custom vocabulary fixes domain-specific errors.
- Streaming transcription trades accuracy for latency and compensates with stitch-and-refine partial results that self-correct as context arrives.
- VideoSDK includes real-time and post-call transcription directly in its video and audio calling SDKs, so live apps can add captions and meeting notes without wiring a separate service.
Conclusion
Understanding how transcription works transforms it from an opaque API into a debuggable system. When you know that accuracy problems usually originate in the spectrogram stage, that streaming quality depends on chunk size and refinement strategy, and that deployment choice affects privacy and cost, you can make informed decisions at every step of building your product.
If you are adding transcription to a live communication app, explore VideoSDK's real-time transcription capabilities and the REST API reference for post-call transcripts and summaries. You can start free at app.videosdk.live/login, and the VideoSDK Discord community is active if you have implementation questions.
What are you building with transcription? Drop a comment, I'd love to hear whether you are adding live captions, meeting notes, or something more experimental.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ