


Gesture recognition is the automated interpretation of human hand or body movements using cameras, radar, or other sensors combined with machine learning algorithms. Modern systems rely on deep learning pipelines that detect hand landmarks, extract spatial and temporal features, and classify gestures in real time, often running entirely on edge devices. Tools like MediaPipe and TensorFlow Lite make it practical to build gesture control interfaces without cloud dependency, and this guide walks through the full stack from data collection to deployment.
Natural interfaces are quietly replacing buttons, remotes, and touchscreens. You wave at a smart TV to change the channel, pinch in mid-air to resize a virtual object, or flick your wrist to dismiss a notification in a car's infotainment system. None of that happens by magic. It happens because gesture recognition systems have matured from fragile lab experiments into production-grade pipelines that run on phones, headsets, and even tiny embedded boards.
If you build apps, games, AR/VR experiences, or assistive technology, understanding gesture recognition gives you a powerful new input modality. This guide covers what gesture recognition is, the technologies behind it, how to build a working system, and how to deploy it on real hardware without killing your latency budget.
What is Gesture Recognition?
Definition and Scope
Gesture recognition is defined as the automated detection and interpretation of human hand, arm, or body movements by software, using data from sensors such as cameras, depth sensors, radar, or wireless signals. A gesture recognition system works by capturing raw input, extracting meaningful features such as hand landmarks or motion trajectories, and classifying the observed movement against a known set of gestures. The output is typically a gesture label plus a confidence score, which an application then maps to a command like "volume up" or "select object."
The scope ranges from static hand poses, such as a thumbs-up, to dynamic movements, such as a circular swipe, and from single-hand interactions to full-body gestures in gaming and fitness applications.
History and Evolution
Early gesture recognition systems from the 1990s and 2000s relied on rule-based computer vision: skin-color segmentation, template matching, and hand-crafted shape descriptors. These approaches broke easily under changing lighting, skin tones, and backgrounds.
The shift came with deep learning. Convolutional neural networks replaced hand-engineered features with learned representations, and the arrival of robust hand landmark models, popularized by frameworks like MediaPipe, made real-time hand tracking accessible on consumer hardware. Today, transformer-based gesture models and sensor-fusion approaches are pushing accuracy and reliability even further, while edge AI tooling brings everything onto the device.
Why Gesture Recognition Matters Today
Applications Across Industries
Gesture recognition has moved well beyond demos. In consumer electronics, smart TVs from brands like Samsung and LG ship with camera-based hand control for channel and volume adjustment. In automotive infotainment, gesture control lets drivers accept calls or adjust climate settings without touching a screen, reducing distraction.
AR and VR headsets treat gestures as a primary input: hand tracking powers object manipulation, menu navigation, and virtual keyboards. Gaming platforms use full-body and hand gestures for controller-free play. In healthcare, surgeons browse medical imaging mid-procedure without breaking sterility, and assistive technology gives users with limited mobility control over their environment through simple movements. Industrial safety applications let workers on factory floors interact with machinery or documentation while wearing gloves, where touchscreens fail.
Each of these use cases shares one requirement: reliable, low-latency interpretation of human movement. That is exactly what a well-built gesture recognition pipeline delivers.
Core Technologies Behind Gesture Recognition
Computer Vision Foundations
Camera-based gesture recognition starts with image acquisition. Frames flow in from a webcam, phone camera, or depth sensor, and the first job is to find the hand. Modern pipelines use landmark detection models that output a fixed set of keypoints, typically 21 points per hand covering finger joints and the wrist, regardless of background or lighting.
Older techniques like background subtraction and skin-color segmentation still appear in constrained environments, but landmark detection has largely replaced them because it generalizes across skin tones, cluttered scenes, and partial occlusion. Once landmarks are available, the downstream gesture classifier works with compact coordinate data instead of raw pixels, which dramatically reduces compute requirements.
Deep Learning Models
Gesture classification splits into two families. For static gestures, a single frame is enough, and a convolutional neural network (CNN) extracts spatial features from the image or from normalized landmark coordinates. For dynamic gestures, such as a wave or a swipe, the temporal dimension matters.
Recurrent neural networks, particularly GRU and LSTM variants, process sequences of landmark frames and capture motion over time. A common production architecture stacks a CNN for per-frame feature extraction with an RNN for temporal modeling. Alternatively, 3D convolutional networks treat the gesture clip as a spatiotemporal volume and learn both dimensions jointly, which performs well on video input but costs more compute. Transfer learning, starting from a pretrained image or pose model, cuts training data requirements dramatically.
Sensor-Based Approaches
Cameras are not the only option. Optical flow analysis estimates motion directly from frame-to-frame pixel movement, useful when you need motion trajectories rather than hand structure.
mmWave radar detects gestures by measuring Doppler shifts and micro-movements, and it works in darkness and through some occlusions, which is why Google's Soli project brought radar gestures to phones. WiFi channel state information (CSI) sensing recognizes gestures from disturbances in wireless signals, requiring no dedicated sensor at all. These approaches also sidestep camera privacy concerns, a meaningful advantage in sensitive environments like bedrooms or healthcare settings.
Building a Gesture Recognition System
Data Collection and Datasets
Every gesture recognition system starts with data. Public datasets such as the 20BN Jester dataset for hand gestures, ChaLearn IsoGD and RGB-D gesture corpora, and NVGesture for radar-based gestures provide labeled examples covering hundreds of gesture classes. Starting from a public dataset lets you validate your architecture before investing in custom collection.
For production systems, custom capture is usually unavoidable. Record video of real users performing your target gestures across varied lighting, distances, angles, and backgrounds. The most common failure mode in custom datasets is labeling inconsistency: define a written gesture specification, including start and end boundaries for dynamic gestures, and have multiple annotators review a sample of labels before training. A smaller, consistently labeled dataset outperforms a large, noisy one.
Preprocessing Steps
Raw video is rarely model-ready. Preprocessing typically involves resizing frames to the model's expected input dimensions, cropping around the detected hand region to focus the classifier, and normalizing coordinates so gestures are invariant to hand position and scale in the frame.
Data augmentation is where robustness is won. Random rotations, scaling, brightness and contrast shifts, horizontal flipping, and simulated motion blur teach the model to handle real-world variability. For landmark-based pipelines, adding small jitter to keypoint coordinates improves tolerance to tracking noise. Skipping augmentation is the single most common reason a gesture model performs well in testing and poorly in the field.
Model Selection and Training
Choose your architecture based on gesture type and deployment target. For static gestures on mobile, a lightweight CNN operating on normalized landmark coordinates is often sufficient and trains fast. For dynamic gestures, a CNN-GRU stack that encodes each frame and then models the temporal sequence is the workhorse choice. If you have abundant video data and compute, 3D convolutional networks can learn spatiotemporal features end to end.
The training workflow follows a standard loop. Split your data into training, validation, and test sets, ensuring that recordings from the same user do not leak across splits. Train with cross-entropy loss, monitor validation accuracy, and apply early stopping to prevent overfitting. Transfer learning shortens the path: initialize from a pretrained hand pose or image classification model and fine-tune on your gesture classes. Expect to iterate, since misclassified gesture pairs usually indicate the model needs more varied examples of those specific classes.
Evaluation Metrics and Performance
Accuracy alone is not enough for gesture interfaces. Track precision and recall per gesture class, since a rarely used but safety-critical gesture must not be missed, and compute the F1-score to balance both. Latency matters as much as accuracy: a gesture control interface that responds in 400 milliseconds feels broken, so measure end-to-end time from movement to action, not just model inference time. Log confusion between similar gestures, such as swipe left versus wave, to target your data collection.
Deploying Gesture Recognition on Edge Devices
Mobile and Embedded Constraints
Cloud inference feels responsive for search queries but not for gestures. Sending camera frames to a server adds network round-trips, bandwidth cost, and a hard privacy problem. On-device inference is the default for production gesture systems, which means living within tight constraints: limited memory on embedded boards, strict power budgets on wearables, and a real-time requirement of roughly 30 frames per second to feel responsive.
Quantized models that use 8-bit integers instead of 32-bit floats shrink memory footprint by around 75 percent and often run faster on mobile neural accelerators. Understanding your target hardware's capabilities before choosing an architecture prevents painful redesigns later.
Using MediaPipe and TensorFlow Lite
Google's MediaPipe provides production-grade, pre-built hand landmark detection that runs in real time on Android, iOS, and web browsers. Rather than training a hand detector yourself, you feed camera frames to MediaPipe's gesture recognizer pipeline, which outputs hand landmarks and, optionally, classified hand poses out of the box. For custom gestures, you take the landmark output as input features for your own classifier.
TensorFlow Lite handles the deployment side. You convert a trained TensorFlow model into an optimized on-device format, apply quantization, and run inference through a lightweight runtime that targets mobile CPUs, GPUs, and dedicated accelerators like the Edge TPU. The typical flow looks like this:
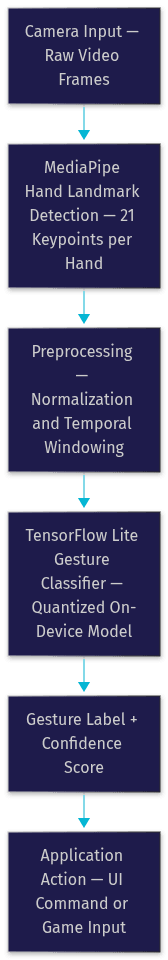
The key insight is the division of labor: MediaPipe solves the hard, general problem of finding and tracking hands, while your custom classifier solves the narrow, product-specific problem of interpreting gestures. This split keeps your model small, your dataset manageable, and your iteration cycles fast.
Optimizing for Real-Time Latency
Even with efficient tools, latency optimization is an active discipline. Model quantization is the first lever, trading a small amount of accuracy for large gains in speed and size. Frame skipping is the second: many gesture classifiers do not need every camera frame, and processing every second or third frame while interpolating in between halves or thirds your compute load.
Hardware acceleration comes third. Delegate inference to the GPU or neural processing unit on modern phones rather than the CPU. Finally, keep your gesture vocabulary small. A five-gesture system with a lightweight classifier will always feel snappier than a fifty-gesture system with a heavy one, and users rarely remember more than a handful of gestures anyway.
Common Challenges and Best Practices
Handling Variability in Lighting and Background
Lighting changes are the classic killer of vision-based gesture systems. A model trained under office lighting can fail completely in a dim living room. The best defense is layered: prefer landmark-based features over raw pixels, since landmarks are far more stable across illumination changes, and train with aggressively augmented data covering brightness, shadow, and color-temperature variation.
Collecting even a small amount of field data from real deployment environments, and folding it into retraining cycles, closes the gap between benchmark accuracy and real-world accuracy. Background diversity in training data matters as much as lighting diversity, since cluttered scenes and moving people behind the user are common in production.
Reducing False Positives
A gesture interface that triggers on random movements destroys user trust faster than one that occasionally misses a gesture. False-positive reduction starts with confidence thresholds: ignore classifier outputs below a minimum score, tuned per gesture class based on the cost of an accidental trigger.
Temporal smoothing adds a second layer. Require a gesture to be detected consistently across several consecutive frames before firing the action, and add a short cooldown period after each recognized gesture so a single wave does not trigger three times. For dynamic gestures, validating that the motion trajectory matches the expected shape, not just the final class label, filters out look-alike movements.
Ensuring Privacy and Security
Gesture recognition systems process camera data of people's bodies and homes, which makes privacy a design requirement, not an afterthought. On-device processing is the strongest guarantee: when frames never leave the device, there is no network exposure, no cloud storage of imagery, and no bandwidth cost. Both MediaPipe and TensorFlow Lite support fully local inference.
Where data must be collected, for example to improve models, anonymize it by stripping identifying context, store only derived features such as landmark trajectories rather than raw video where possible, and obtain explicit user consent. For camera-averse environments, radar and WiFi CSI sensing offer gesture recognition with no imagery at all, which is why they are gaining traction in smart home and automotive contexts.
Future Trends in Gesture Recognition
Multimodal Fusion
The next generation of gesture systems will not rely on a single sensor. Multimodal fusion combines camera data with radar, depth, or WiFi signals, letting each modality cover the others' weaknesses. Cameras provide rich spatial detail but fail in darkness; radar works anywhere but is coarser. Fused systems, where a model learns from multiple input streams jointly, already show higher reliability in automotive and smart home research, and the same fusion pattern extends to combining gestures with voice for more natural multimodal interfaces.
Transformer-Based Models
Vision transformers are reshaping gesture recognition the way they reshaped image classification. Unlike RNNs, which process sequences step by step, transformer models use attention to relate any two points in a gesture sequence, capturing long-range temporal patterns such as a slow gesture that spans several seconds. Transformer-based gesture models are showing strong results on benchmark datasets, and as efficient transformer variants are optimized for edge hardware, expect them to replace CNN-RNN stacks in more production systems through 2026 and beyond.
Definitions Glossary
Gesture recognition: The automated detection and interpretation of human hand or body movements using sensors and machine learning, producing a gesture label and confidence score that an application maps to a command.
Hand landmark detection: A computer vision technique that locates a fixed set of keypoints on the hand, typically 21 points covering finger joints and the wrist, providing compact features for gesture classification.
CNN-RNN stack: A common gesture recognition architecture where a convolutional neural network extracts spatial features from each frame and a recurrent network models the temporal sequence of the gesture.
Model quantization: The process of converting a model from 32-bit floating point weights to lower precision, typically 8-bit integers, reducing memory footprint and speeding up on-device inference.
WiFi CSI sensing: Gesture detection using disturbances in WiFi channel state information, enabling device-free gesture recognition without cameras or dedicated sensors.
Edge AI: Running machine learning inference directly on the device, such as a phone or embedded board, rather than sending data to a cloud server, improving latency and privacy.
Key Takeaways
- Gesture recognition combines sensor input, feature extraction, and machine learning classification to turn human movement into application commands, and modern deep learning pipelines make it reliable enough for production use.
- Landmark-based approaches, such as MediaPipe's hand tracking, are more robust across lighting, skin tones, and backgrounds than raw-pixel methods, and they keep downstream classifiers small.
- Building a system follows a clear path: choose or collect a consistently labeled dataset, preprocess with aggressive augmentation, train a CNN-RNN or 3D convolution model, and evaluate with per-class precision, recall, F1-score, and end-to-end latency.
- On-device deployment with TensorFlow Lite, quantization, frame skipping, and hardware acceleration delivers the sub-second response a gesture interface needs while keeping user imagery private.
- False-positive reduction through confidence thresholds, temporal smoothing, and cooldowns protects user trust, which is the most fragile asset of any gesture-controlled product.
- Multimodal fusion and transformer-based models are the two trends most likely to reshape gesture recognition through 2026 and beyond.
Conclusion
Gesture recognition has crossed the threshold from research novelty to production interface, powered by deep learning, robust landmark detection, and edge deployment tooling. The practical path is well marked: start with a public dataset, lean on MediaPipe for hand tracking, train a compact classifier on your own gesture vocabulary, and deploy on-device with TensorFlow Lite and quantization to hit real-time latency. Keep your gesture set small, guard against false positives, and design for privacy from day one. If you are building gesture-driven experiences and want to pair them with real-time video, voice, or AI interaction, explore VideoSDK's real-time communication SDKs to see how gesture control can extend into live video applications. What kind of gesture interface are you building? Drop a comment, I'd love to hear what use case you are working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ