


An LLM for education is a large language model fine-tuned or engineered specifically for learning contexts, combining curriculum grounding, diagnostic reasoning, and pedagogical tutoring to deliver personalized instruction at scale. VideoSDK extends these capabilities into voice-first tutoring through its AI Voice Agent SDK, connecting educational LLMs to real-time audio pipelines. Explore the AI Voice Agent introduction to start building interactive tutoring experiences.
Generative AI promised every student a personal tutor. In 2026, that promise is closer to reality than ever, but the gap between a generic chatbot and a genuinely educational language model remains wide. A general-purpose LLM can answer questions, but it cannot reliably map a student's confusion to a specific curriculum standard, scaffold a hint without giving away the answer, or diagnose whether a math error stems from a conceptual gap or a careless mistake.
An LLM for education is purpose-built for these tasks. It is trained or fine-tuned on curriculum documents, authentic student-tutor dialogues, and pedagogical strategies that prioritize guided learning over instant answers. This article covers the core capabilities that distinguish educational LLMs from general models, the leading open-source options available today, how to build a fine-tuning pipeline, and the practical challenges of deploying AI in real classrooms.
Why LLMs Are Transforming Education
The shift from static digital textbooks to interactive, AI-driven tutoring represents the most significant pedagogical change in decades. Traditional online learning platforms deliver content uniformly: every student sees the same video, answers the same quiz, and receives the same feedback regardless of their individual understanding.
Educational LLMs break that mold. They adapt in real time to what a student knows, what they are struggling with, and how they learn best. According to Benjamin Bloom's foundational research on the "Two Sigma Problem," one-on-one tutoring produces a two-standard-deviation improvement in student outcomes compared to traditional classroom instruction. That effect size means an average tutored student outperforms 98 percent of students in a conventional classroom. Educational LLMs aim to approximate that tutoring quality at a fraction of the cost, making personalized instruction scalable for the first time in history.
The data-driven insights these models generate add another layer of value. Every interaction produces a record of student reasoning, common misconceptions, and learning patterns that teachers and administrators can aggregate to inform curriculum design and intervention strategies.
Core Capabilities of LLMs for Education
Educational LLMs differ from general-purpose models in six capability areas that matter for real classroom use. Each capability addresses a specific failure mode of generic chatbots when applied to learning.
Curriculum Grounding
Curriculum grounding means the model maps every student question and response to a specific educational standard, such as Common Core math standards or Next Generation Science Standards. Without grounding, a model might explain a concept at a college level to a fifth grader. A curriculum-grounded LLM knows that a student asking about fractions is working within a specific grade-level expectation and calibrates its language, examples, and depth accordingly.
Diagnostic Reasoning
Diagnostic reasoning is the model's ability to detect why a student made an error, not just that they made one. If a student writes that 3/4 plus 1/2 equals 4/6, a diagnostic LLM identifies whether the student misunderstands common denominators, added numerators and denominators separately, or made an arithmetic slip. This diagnosis drives the quality of the subsequent feedback.
Pedagogical Tutoring
Pedagogical tutoring is the art of helping without doing the work. A well-tuned educational LLM provides hints, asks guiding questions, and scaffolds understanding step by step. It resists the temptation to simply output the correct answer, which is what most generic LLMs do by default. This capability requires training on authentic tutoring dialogues where experienced educators model the patience and strategy of guided instruction.
Content Creation
Educational LLMs generate quizzes, draft lesson plans, create rubrics, and assist with essay feedback. Teachers use these models to produce differentiated materials: the same concept at three difficulty levels for three different student groups, generated in minutes rather than hours.
Multimodal Support
Modern educational LLMs handle text, images, and PDFs. Students can create flashcards from PDF files and use them for more effective revision. A teacher can upload a textbook chapter and ask the model to generate a comprehension quiz aligned to specific standards.
The Education Loop
These capabilities work together in a continuous loop. The diagram below illustrates how curriculum standards, student questions, diagnostic reasoning, tutoring, and feedback form a cycle that refines itself over time.
Leading Open-Source Educational LLMs
The open-source ecosystem for educational LLMs has expanded rapidly. Several model families now offer purpose-built alternatives to proprietary APIs, giving schools and edtech developers control over data, deployment, and customization.
OmniEdu Family (4B, 9B, 27B)
The OmniEdu family is a series of curriculum-grounded LLMs designed specifically for educational reasoning. The 4B parameter model suits edge deployment in low-bandwidth schools, while the 9B and 27B variants target hosted inference for richer tutoring scenarios. OmniEdu models score well on diagnostic reasoning benchmarks and pedagogical tutoring evaluations, with the 27B variant approaching proprietary model quality on K-12 math and science tasks.
NVIDIA Nemotron Teacher STEM
NVIDIA's Nemotron Teacher STEM model focuses on reasoning-intensive STEM education. It features multi-token prediction for faster inference and a one-million-token context window, allowing it to process entire textbooks or curriculum frameworks in a single pass. This model excels at generating complex problem sets and providing detailed step-by-step explanations for advanced mathematics and physics.
InnoSpark Series
The InnoSpark series targets Chinese-language education, with domain-specific fine-tuning for Chinese literature, mathematics, and science curricula. These models demonstrate that educational LLMs must be culturally and linguistically grounded, not merely translated from English-centric training data.
MuduoLLM
MuduoLLM specializes in K-12 mathematics and physics. It is fine-tuned on large volumes of worked problems and student error patterns, giving it strong diagnostic reasoning for the specific misconception types that recur in these subjects. Benchmark tables show MuduoLLM outperforming larger general-purpose models on grade-specific math tasks despite its smaller parameter count.
TeachLM
TeachLM uses parameter-efficient fine-tuning on authentic tutoring data collected from real educator-student interactions. Its strength lies in pedagogical quality: the model produces hints and scaffolding that closely mirror experienced teacher behavior, rather than the answer-forward style of generic LLMs.
Comparison of Open-Source Educational LLMs
[LINKABLE ASSET: comparison table]
| Model | Parameters | Key Strength | Best Use Case |
|---|---|---|---|
| OmniEdu-27B | 27B | Curriculum grounding, diagnostic reasoning | Hosted K-12 tutoring across subjects |
| OmniEdu-4B | 4B | Lightweight, edge-deployable | Low-bandwidth school environments |
| Nemotron Teacher STEM | Large | 1M token context, multi-token prediction | STEM reasoning, textbook-scale tasks |
| InnoSpark | Varies | Chinese-language curriculum alignment | Chinese-language K-12 and higher education |
| MuduoLLM | Medium | K-12 math/physics specialization | Math tutoring with misconception diagnosis |
| TeachLM | Medium | Authentic pedagogical tutoring style | Hint generation and guided instruction |
The most important row depends on your deployment context. For schools with limited infrastructure, OmniEdu-4B and MuduoLLM offer strong educational performance without requiring large GPU clusters. For platform developers building hosted tutoring services, OmniEdu-27B and Nemotron Teacher STEM provide the reasoning depth needed for advanced subjects.
Building an Educational LLM Pipeline
Creating a production-quality educational LLM requires a structured pipeline that moves from raw data to deployed model to continuous improvement. Each stage has specific decisions that affect the final quality of the tutoring experience.
Data Collection
The foundation of any educational LLM is its training data. You need three primary data categories. First, curriculum documents: standards frameworks, textbook chapters, lesson plans, and learning objectives organized by grade and subject. Second, student-tutor dialogues: authentic transcripts of experienced educators helping students work through problems, including the hints, questions, and scaffolding steps they use. Third, exam archives: standardized test questions, student responses, and scoring rubrics that teach the model what correct and incorrect reasoning looks like.
Pre-Processing
Raw educational data requires careful preparation before training. Anonymization is non-negotiable: every student name, ID, and personally identifiable field must be stripped or replaced with synthetic identifiers to comply with FERPA and GDPR. Token budgeting ensures that long curriculum documents fit within the model's context window without truncation. Curriculum tagging labels each training example with its corresponding standard, grade level, and subject so the model learns to calibrate responses appropriately.
Fine-Tuning Strategies
You have two primary paths for adapting a base model to educational use. Full-model fine-tuning updates every parameter and produces the strongest results, but requires significant GPU resources and is impractical for models above roughly 13B parameters on standard hardware. Parameter-efficient fine-tuning methods like LoRA and adapter layers update a small subset of parameters while freezing the rest, reducing compute requirements by orders of magnitude while retaining most of the quality. For most educational teams, LoRA-based fine-tuning on a strong base model is the practical starting point.
Evaluation Metrics
Educational LLMs need specialized evaluation beyond standard language model benchmarks. Exact-match and F1 scores on K12-Bench measure factual accuracy on grade-level questions. Question-generation quality metrics evaluate whether generated quizzes are pedagogically sound, grade-appropriate, and free of ambiguity. Diagnostic accuracy measures whether the model correctly identifies student misconceptions from their responses. No single metric captures educational quality, so teams should run a composite evaluation across all three dimensions.
Deployment Options
Deployment strategy depends on your infrastructure and user base. Hosted inference using frameworks like vLLM with OpenAI-compatible APIs is the fastest path to production, serving models from cloud GPU instances. On-premise GPU clusters give schools and districts full control over data, which is critical for institutions with strict data residency requirements. Edge inference on smaller models like OmniEdu-4B enables tutoring in low-bandwidth environments where cloud connectivity is unreliable.
The diagram below shows the complete pipeline from data collection through deployment and back to improvement through the feedback loop.
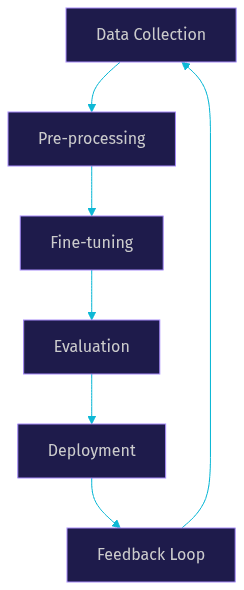
The feedback loop is what separates a static model from a continuously improving educational system. Production interactions generate new data about student misconceptions, effective hint patterns, and curriculum gaps. Feeding this data back into the pipeline, with proper anonymization, lets the model improve over time without starting from scratch.
Practical Considerations and Challenges
Deploying LLMs in education introduces challenges that go beyond standard software engineering. These considerations determine whether an educational AI system earns trust from teachers, parents, and administrators.
Privacy and Data Protection
Student data is among the most sensitive information any system processes. In the United States, FERPA governs educational records and requires strict access controls. In Europe, GDPR adds consent requirements and the right to erasure. Any educational LLM pipeline must anonymize training data, encrypt data in transit and at rest, and provide clear audit trails for how student interactions are used. On-premise deployment or private cloud instances with data residency guarantees are often necessary for compliance.
Bias and Fairness
Educational content must serve diverse student populations. LLMs trained predominantly on data from one demographic or educational tradition may produce examples, language, or pedagogical approaches that do not resonate with all students. Evaluating for bias requires testing across demographic groups, curriculum traditions, and language varieties. The InnoSpark series demonstrates this principle: Chinese-language education requires Chinese-specific training data, not translated English content.
Computational Cost and Scaling
Running a 27B parameter model for thousands of concurrent students requires substantial GPU infrastructure. Costs scale with model size, concurrency, and response latency targets. LoRA fine-tuning and smaller specialized models like MuduoLLM help control costs, but teams must budget for inference as an ongoing operational expense, not a one-time setup cost.
Curriculum Relevance Over Time
Educational standards evolve. A model fine-tuned on 2024 curriculum documents will gradually drift from current standards. Teams need a maintenance plan for retraining or updating the model's curriculum knowledge, ideally tied to the feedback loop in the pipeline diagram above.
Human-in-the-Loop Oversight
No educational LLM should operate without human oversight. Teachers must be able to review model interactions, override incorrect guidance, and flag problematic outputs. The most effective deployments position the LLM as a teacher assistant, not a teacher replacement. This framing also aligns with parent and administrator expectations.
Future Trends for LLMs in Education
The next wave of educational LLM innovation is already visible in research and early-stage deployments. Four trends will shape the field through 2026 and beyond.
Retrieval-augmented tutoring connects LLMs to real-time knowledge bases, letting models pull current curriculum updates, textbook corrections, and local school district policies without retraining. This approach keeps the model's knowledge fresh while reducing fine-tuning frequency.
Multimodal instruction is expanding beyond text and images. Video understanding, AR/VR integration, and interactive whiteboard capture will let LLMs tutor in the same modalities that modern classrooms use. A student working on a geometry proof on a digital whiteboard could receive real-time guidance from a multimodal LLM that sees the diagram and reads the proof steps.
Adaptive assessment powered by continuous student modeling moves beyond end-of-unit tests. The LLM builds a running model of what each student knows and does not know, adjusting difficulty and topic selection in real time. This approach mirrors how skilled human tutors calibrate their instruction.
Open-source community collaborations are accelerating the field. Shared benchmarks like K12-Bench, open datasets of anonymized tutoring dialogues, and model-agnostic evaluation frameworks are making it easier for researchers and edtech developers to compare approaches and build on each other's work.
Definitions Glossary
Curriculum Grounding: The process of mapping LLM responses to specific educational standards and grade-level expectations so that explanations are calibrated to the student's learning context.
Diagnostic Reasoning: An LLM capability that identifies the root cause of a student's error, distinguishing between conceptual misunderstandings, procedural mistakes, and careless errors.
Parameter-Efficient Fine-Tuning (PEFT): A training approach that updates a small subset of model parameters using methods like LoRA, reducing compute requirements while retaining most of the quality of full fine-tuning.
K12-Bench: A benchmark designed to evaluate educational LLMs on grade-level factual accuracy, question generation quality, and diagnostic accuracy across K-12 subjects.
Pedagogical Tutoring: An instructional approach where the LLM provides hints, guiding questions, and scaffolding rather than direct answers, modeling the behavior of an experienced human tutor.
Key Takeaways
- An LLM for education is purpose-built for curriculum grounding, diagnostic reasoning, and pedagogical tutoring, making it fundamentally different from a generic chatbot applied to learning.
- Open-source models like OmniEdu, MuduoLLM, and TeachLM give schools and edtech developers viable alternatives to proprietary APIs, with options ranging from 4B edge-deployable models to 27B hosted inference models.
- A production educational LLM pipeline requires structured data collection, anonymization, curriculum tagging, fine-tuning, multi-dimensional evaluation, and a feedback loop for continuous improvement.
- Privacy compliance under FERPA and GDPR, bias evaluation, computational cost management, and human-in-the-loop oversight are non-negotiable for any educational AI deployment.
- VideoSDK's AI Voice Agent SDK and Conversational Graph extend educational LLMs into voice-first tutoring, enabling real-time spoken-language interactions powered by the same models covered in this guide.
Conclusion
Educational LLMs have moved from research curiosity to deployable infrastructure. The models, pipelines, and evaluation frameworks available in 2026 give developers and educators the tools to build tutoring systems that approximate Bloom's two-sigma ideal at scale. The open-source ecosystem is mature enough for production use, and the challenges around privacy, bias, and cost are well understood with established mitigation strategies. If you are building an educational product, start by experimenting with the models highlighted here and the pipeline architecture described above. For voice-first tutoring experiences that connect your educational LLM to real-time audio, explore VideoSDK's AI Voice Agent SDK and the Python SDK for AI pipeline integration. What are you building with educational LLMs? Drop a comment below, and check out the VideoSDK Discord community to connect with other developers working at the intersection of AI and real-time communication.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ