


OpenAI speech to transcription is the process of converting spoken audio into text using OpenAI's specialized audio models, such as gpt-4o-transcribe and Whisper. Developers can integrate this capability through file-based API endpoints for recorded audio or real-time WebSocket sessions for live captioning. By leveraging the OpenAI audio transcription API, applications can achieve high-accuracy multilingual transcription with sub-second latency in real-time scenarios.
Developers building modern communication apps, meeting recorders, or AI voice agents need reliable speech-to-text capabilities. The shift from generic transcription to AI-powered models has dramatically improved accuracy, especially in noisy environments or multilingual contexts. OpenAI speech to transcription provides a robust suite of models designed to handle everything from pre-recorded podcasts to live, interactive voice calls. This article covers how the OpenAI audio transcription API works, compares the latest models, and outlines practical workflows for both file-based and real-time transcription. By the end, you will understand how to prepare audio, choose the right model, and scale your transcription pipeline effectively.
In 2026, real-time communication infrastructure relies heavily on accurate speech recognition. Whether you are building a telehealth platform that requires live captioning for accessibility or a customer support dashboard that transcribes voicemails, the underlying transcription engine dictates the user experience. OpenAI has consolidated its speech models into a powerful API surface that handles diverse audio conditions. We will explore how these models function, how to optimize your audio input, and how to architect your backend to handle both batch processing and live streaming without hitting rate limits or latency walls.
Understanding OpenAI Speech to Transcription
OpenAI speech to transcription is defined as the conversion of spoken language into written text using machine learning models hosted on OpenAI's infrastructure. It works by sending audio data to the OpenAI API, which processes the audio through neural networks trained on vast multilingual datasets and returns the transcribed text.
The service fits into the broader OpenAI API ecosystem alongside text generation, image processing, and embeddings. Developers typically interact with it through two primary modes: file-based and real-time. File-based transcription involves uploading a complete audio file (like an MP3 or WAV) and receiving the full transcript in response. This mode is ideal for processing recorded meetings, podcasts, or voicemail drops where immediate results are not necessary. Real-time transcription uses a WebSocket connection to stream audio chunks incrementally, returning text deltas as the speech happens. This distinction is crucial for developers architecting systems like VideoSDK AI voice agents, where low-latency conversational transcription is required to maintain natural dialogue flow.
When integrating OpenAI speech to transcription, developers must consider how the audio is captured and routed. In a typical VideoSDK integration, the raw audio tracks from participants are accessible via the SDK. For file-based processing, these tracks can be recorded and sent to the OpenAI API post-call. For real-time processing, the live audio stream must be extracted from the VideoSDK room and piped directly into the OpenAI WebSocket endpoint. This architectural choice determines whether you use the standard REST API or the Realtime API surface.
The underlying technology relies on transformer architectures that excel at sequence-to-sequence tasks. These models do not merely match phonetic sounds to words. They use contextual attention mechanisms to understand the surrounding sentence structure, which allows them to differentiate between homophones and correct minor audio misinterpretations. This contextual awareness is what separates modern OpenAI speech to transcription from legacy hidden Markov model approaches.
Choosing the Right Model for OpenAI Speech to Transcription
Selecting the correct model is critical for balancing accuracy, latency, and cost. OpenAI offers several models for speech to transcription, including the newer gpt-4o-transcribe variants and the legacy whisper-1 model. Each model is tuned for specific performance characteristics and price points.
| Model | Best For | Latency | Cost | Key Feature |
|---|---|---|---|---|
| gpt-4o-transcribe | High-accuracy general transcription | Medium | Higher | Superior noise robustness |
| gpt-4o-mini-transcribe | High-volume, cost-sensitive tasks | Low | Lower | Good accuracy at scale |
| gpt-4o-transcribe-diarize | Meetings, multi-speaker audio | Medium | Higher | Speaker identification |
| whisper-1 | Legacy compatibility, basic needs | High | Lower | Wide language support |
Model accuracy and latency considerations
Benchmark findings from sources like Artificial Analysis indicate that the gpt-4o-transcribe model achieves lower word error rates compared to whisper-1, particularly in conversational audio with background noise. The newer models are trained on more diverse datasets, allowing them to handle accents and overlapping speech more effectively. Latency varies significantly between models. The mini variant is optimized for faster response times, making it suitable for near-real-time applications where strict sub-second latency is not required but speed is still a priority. In contrast, the diarize model adds processing overhead because it must segment the audio by speaker, increasing the time to first token.
When building interactive applications, developers must measure the round-trip time from audio capture to text display. The gpt-4o-transcribe model offers the best balance for production voice agents, providing high accuracy without the extreme latency of older models. For applications where the user waits for the full transcript, such as a post-meeting summary tool, the slightly higher latency of the diarize model is an acceptable tradeoff for speaker-labeled output.
Cost implications
OpenAI transcription pricing is generally calculated per minute of audio processed. . The gpt-4o-transcribe models carry a higher per-minute cost than whisper-1 or the mini variant. A higher-cost model is justified when the downstream application requires high precision, such as legal or medical transcription, where errors are costly. For voicemail transcription or basic meeting captions, the mini model often provides sufficient accuracy at a fraction of the cost.
Developers should calculate the expected monthly audio minutes and multiply by the per-minute rate to estimate baseline costs. If your application processes 10,000 minutes of audio per month, the price difference between the standard and mini models can be substantial. Implementing a fallback strategy, where you use the mini model for initial processing and only escalate to the full model if confidence scores are low, can optimize spending.
Preparing Audio for Optimal Results
The quality of the input audio directly impacts the accuracy of OpenAI speech to transcription. Developers should ensure audio is clear, properly formatted, and free of excessive background noise. OpenAI supports common formats like WAV, MP3, and FLAC. For best results, use a 16kHz sample rate with mono audio, as this matches the training data of most speech models and reduces file size.
Audio preprocessing is often overlooked but yields the highest return on investment for transcription accuracy. If your audio is captured from a browser or mobile device, it likely contains echo, keyboard noise, and network artifacts. Passing this raw audio directly to the API will degrade results. Using a real-time communication SDK like VideoSDK, which includes built-in noise suppression and echo cancellation, ensures the audio stream is clean before it reaches the transcription endpoint.
Audio preprocessing checklist
- Normalization: Adjust the audio amplitude to a standard level to ensure consistent volume across different speakers and devices.
- Voice Activity Detection (VAD): Strip out long silences to reduce processing time and API costs. VAD ensures you only pay for audio that contains speech.
- Clipping Removal: Identify and fix distorted audio segments that can cause transcription errors. Clipping happens when the microphone volume is too high.
- Noise Suppression: Apply a noise gate or AI-based noise suppression to remove background hums and keyboard typing. This is critical for remote work audio.
- Language Hinting: If the audio language is known, pass it to the API to bypass automatic language detection and improve accuracy. This is especially useful for single-language applications.
File-Based Transcription Workflow
The file-based workflow is the standard approach for processing recorded audio. First, generate an OpenAI API token from your developer account. Next, prepare the audio file and initiate an upload to the OpenAI audio transcription endpoint. The API request must include the audio file, the target model (such as gpt-4o-transcribe), and the desired response format (json, text, srt, or verbose_json). The server processes the file and returns the complete transcript. For large files, developers should chunk the audio into smaller segments to avoid timeout errors and manage rate limits effectively.
When handling the response, developers can choose between plain text, standard JSON, or verbose JSON. Verbose JSON includes timestamps for each word or segment, which is essential for building features like clickable transcripts or subtitle generation. If you are building a video calling application with VideoSDK, you can use the verbose JSON output to align the transcript with the recorded video timeline, creating a searchable meeting archive.
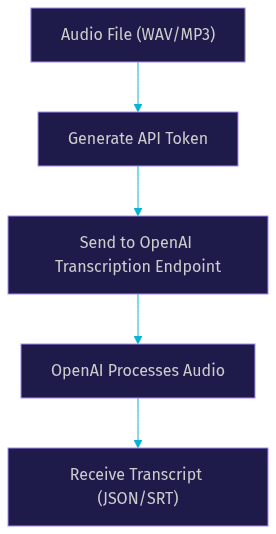
Error handling in the file-based workflow is straightforward. If the file format is unsupported, the API returns a 400 error. If the file is too large, you will receive a 413 error. Implement a retry mechanism with exponential backoff for 429 rate limit errors. For files exceeding the 25MB limit, split the audio at silent points using a tool like FFmpeg, transcribe each chunk separately, and merge the text outputs. This ensures you can process hour-long podcasts without hitting upload limits.
Real-Time Transcription Workflow
Real-time transcription is essential for live captioning and interactive AI voice agents. This workflow uses a WebSocket connection to the OpenAI Realtime service. Developers establish a session by sending an authentication token and session configuration. As the user speaks, raw audio chunks are streamed over the WebSocket. The OpenAI realtime service processes these chunks and sends back text deltas incrementally. Turn detection mechanisms on the server side identify when a user has finished speaking, signaling the end of a transcription segment. This allows applications to render text on screen as it is spoken or feed the transcript into an LLM for immediate response generation.
Setting up a real-time session requires careful management of the WebSocket lifecycle. The client must maintain the connection, handle ping/pong frames, and gracefully reconnect if the network drops. In a VideoSDK AI voice agent architecture, the agent worker process manages this WebSocket connection. It captures the participant's audio stream from the VideoSDK room, encodes it into the required PCM format, and streams it to OpenAI. As deltas arrive, the agent can push them to the frontend via the VideoSDK pub/sub messaging system for live captioning, or buffer them until turn detection fires to trigger an LLM response.
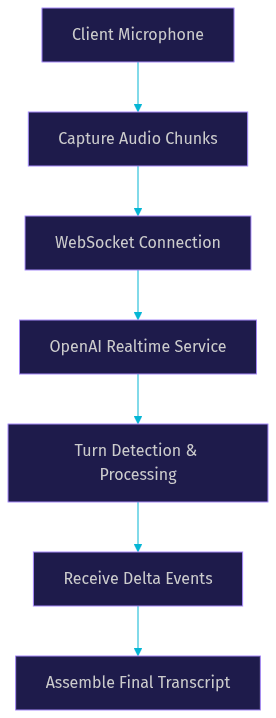
Handling incremental deltas is the most complex part of the real-time workflow. The API sends partial transcripts that may be revised as more context is received. Developers must implement a state machine on the frontend to replace the previous partial text with the updated version without flickering. Once the turn detection event fires, the final transcript for that utterance is locked in, and the UI can commit it to the chat history or caption log. This requires precise audio encoding, typically 24kHz mono PCM, to ensure the OpenAI service can parse the stream without additional transcoding overhead.
Cost, Latency, and Scaling
Scaling OpenAI speech to transcription requires careful budgeting and architecture planning. For high-volume use, monitor your API usage to avoid hitting rate limits. Implement batching for file-based transcription by queueing audio files and processing them concurrently within your limit thresholds. If latency is a bottleneck, consider using the gpt-4o-mini-transcribe model or optimizing your audio chunk sizes in real-time streams. Caching transcripts for repeated audio playback can also reduce redundant API calls.
When scaling real-time transcription, the primary constraint is the number of concurrent WebSocket connections. Each active voice agent or live captioning session holds an open connection to the OpenAI servers. Developers must provision sufficient backend capacity to manage these connections and route audio efficiently. Using a managed agent cloud, like the one provided by VideoSDK, offloads this connection management and allows your application to scale horizontally without maintaining persistent WebSocket pools on your application servers.
Best Practices & Troubleshooting
Common pitfalls in OpenAI speech to transcription include invalid audio formats, token expiry, and network interruptions. If you encounter invalid audio format errors, verify that your file adheres to the supported formats and sample rates. Token expiry can be mitigated by implementing automatic token refresh logic in your backend. For network interruptions during real-time WebSocket sessions, implement reconnection logic with exponential backoff to ensure the transcription stream resumes gracefully.
Another frequent issue is high word error rate in noisy environments. Before blaming the model, inspect the audio payload being sent. Use a tool to record the exact stream being transmitted to OpenAI. If you hear echo or static, integrate a noise suppression layer. VideoSDK provides built-in noise suppression that can be enabled on custom audio tracks, ensuring the audio leaving the client device is already clean. Additionally, always use secure token generation practices. Never expose your OpenAI API key in a client-side application. Route all transcription requests through a secure backend proxy that injects the API key.
Definitions Glossary
OpenAI Speech to Transcription: The process of converting spoken audio into text using OpenAI's audio models, supporting both file-based and real-time streaming modes.
gpt-4o-transcribe: A high-accuracy OpenAI audio model designed for robust transcription in noisy and multilingual environments.
Real-Time Transcription: The process of converting speech to text instantaneously as the user speaks, typically using a WebSocket connection for low-latency delta updates.
Turn Detection: A mechanism used in real-time audio sessions to determine when a speaker has finished talking, allowing the system to process the complete utterance.
Diarization: The process of partitioning an audio stream into segments based on who is speaking, useful for multi-speaker meeting transcription.
Key Takeaways
- OpenAI speech to transcription offers both file-based and real-time modes to accommodate different application needs.
- Choosing the right model, such as gpt-4o-transcribe for accuracy or the mini variant for cost, is critical for production success.
- Proper audio preprocessing, including noise suppression and normalization, significantly improves transcription accuracy.
- Real-time workflows rely on WebSocket connections and turn detection to deliver sub-second text deltas for live captioning.
- Scaling requires careful management of rate limits, audio chunking, and cost-per-minute budgeting.
Conclusion
Integrating OpenAI speech to transcription into your application unlocks powerful capabilities for meeting captions, voicemail routing, and AI voice agents. By understanding the differences between file-based and real-time workflows, selecting the appropriate model, and applying rigorous audio preprocessing, developers can build highly accurate and scalable transcription pipelines. For deeper integration details, refer to the official OpenAI API documentation. What are you building with OpenAI transcription? Drop a comment and let me know your use case.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ