


The multimodal Live API is Google's bidirectional streaming interface for the Gemini models, letting a single connection carry audio in, audio out, and live video frames at the same time. This guide shows you how to run it entirely inside Google Colab using the Google GenAI SDK, covering setup, WebSocket streaming, audio chunking, video frame interleaving, and conversation turn management. By the end, you will have a working mental model and a repeatable notebook workflow for real-time voice and video agents, and you can extend the same patterns with VideoSDK's real-time communication SDKs when you move beyond a notebook prototype.
Introduction
Real-time AI stopped being a demo curiosity somewhere in the last two years. Developers now expect models that listen, watch, and respond in the same conversational beat a human would. Google's Gemini Live API delivers exactly that: a persistent, bidirectional stream where audio, video, and text flow in both directions with sub-second responsiveness.
The catch has always been the barrier to experimentation. Setting up a local streaming environment, managing audio devices, and handling WebSocket lifecycles is a lot of scaffolding before you hear your first AI response. Google Colab changes that equation. With a browser, a notebook, and an API key, you can prototype a voice agent in an afternoon.
This multimodal Live API Colab guide walks the full path: environment setup, secret-based authentication, WebSocket fundamentals, audio streaming, video frame interleaving, and turn management. Everything is explained in plain language, so you understand what each step does before you wire it together.
What Is the Multimodal Live API?
The multimodal Live API is defined as a streaming interface for Gemini models that accepts and returns multiple media types over a single long-lived connection. Unlike a standard request-response API, where you send a prompt and wait for a finished answer, the Live API keeps a session open and processes media as it arrives.
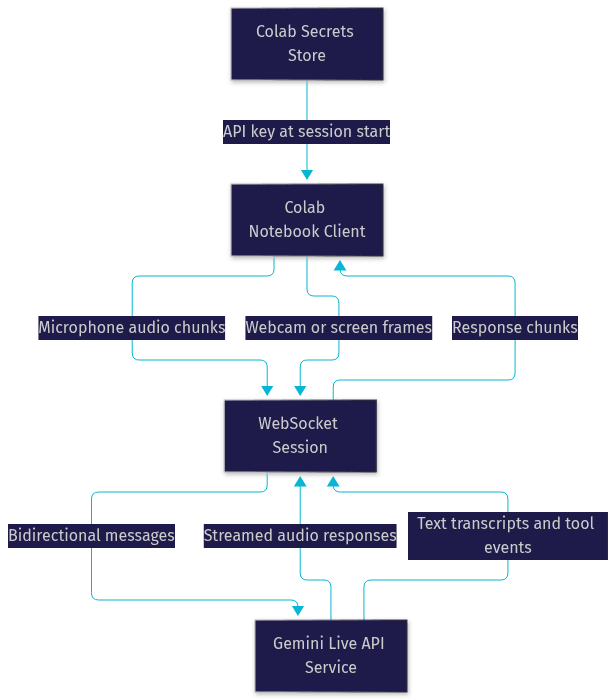
The API works by establishing a WebSocket-style session with the Gemini service, then exchanging structured messages in both directions. You can configure a session for audio-only, video-only, or combined audio-video modalities. In audio-only mode, the model behaves like a phone interlocutor: it listens to your speech chunks and replies with synthesized audio. In combined mode, it can watch your webcam or screen while listening, which unlocks use cases like live tutoring or guided walkthroughs.
VideoSDK provides comparable real-time transport for production applications through its video calling SDKs, which handle the media capture and delivery layer that a Colab prototype eventually outgrows.
The diagram below shows the overall data flow:
Setting Up Your Colab Environment
Getting a Live API session running in Colab takes three preparation steps, and each one matters for a smooth experience.
Create the Notebook and Runtime
Start a fresh Colab notebook and select a GPU runtime if you plan to do any local audio processing or frame encoding. The Live API itself does the heavy lifting server-side, so a standard CPU runtime works fine for pure streaming. A GPU only helps if you add local preprocessing such as noise reduction or frame resizing.
Install the Google GenAI SDK
The Google GenAI SDK is the official Python client for Gemini, and it includes the Live API surface. Installing it in Colab means adding the package through the notebook's package installation mechanism, then restarting the runtime if prompted. The SDK handles session creation, message serialization, and the async event loop that streaming requires. Because the Live API is asynchronous, your notebook code will use async and await patterns, which Colab supports natively in recent versions.
Store Your API Key as a Colab Secret
Never paste an API key directly into a notebook cell. Colab provides a built-in secrets manager on the left sidebar where you can store sensitive values under a named key. Your notebook then grants itself access to that secret and reads it at runtime. This keeps the key out of the notebook file itself, which matters because notebooks get shared, versioned, and published far more often than people expect. Google's own Gemini API documentation covers key creation in the AI Studio console.
Once the SDK is installed and the secret is readable, you initialize the client with your key and you are ready to open a session.
Understanding WebSocket Basics for Live Streaming
The Live API is built on a persistent, bidirectional connection, and the WebSocket protocol is the mental model to use. A WebSocket session starts with a handshake, stays open for the life of the conversation, and allows either side to send messages at any time.
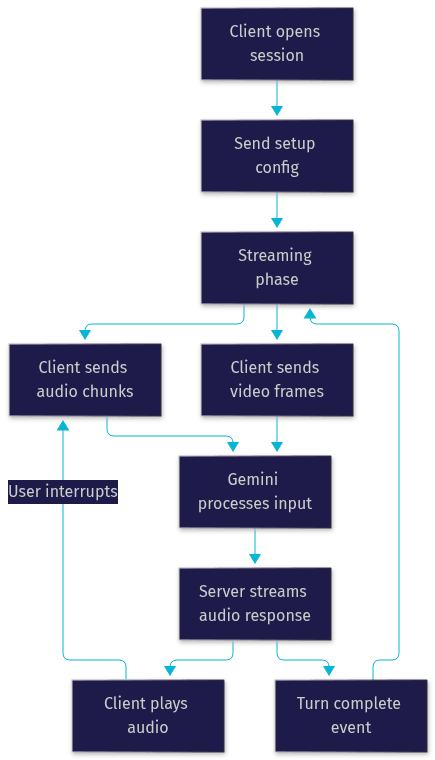
The connection lifecycle has four phases. First, the client opens the session and sends an initial configuration message describing the modalities, the model, and any system instructions. Second, the session enters a streaming state where the client pushes media chunks and the server pushes responses. Third, interruptions and control messages flow in both directions to manage turn-taking. Fourth, the session closes cleanly when the conversation ends, or times out if it goes idle beyond the configured limit.
Gemini expects messages in a structured format: each message carries a type marker and a payload, such as an audio chunk, a video frame, or a text prompt. Responses arrive as a stream of events, including partial audio, final transcripts, and tool-call requests.
Streaming Audio in Colab
Audio is the core modality of any live voice agent, and getting the flow right determines whether your prototype feels conversational or sluggish.
Capture and Chunk Microphone Input
In Colab, microphone capture happens through browser-based recording widgets that deliver audio into the notebook as a stream. The critical step is chunking: raw audio must be split into small, evenly sized segments, typically on the order of tens of milliseconds each, before being sent over the session. Sending one large blob defeats the purpose of streaming, because the model cannot start processing until the whole recording arrives.
Send Chunks and Handle Interruptions
Each chunk is wrapped into a message and pushed to the open session. While the user speaks, your code keeps sending. When the user stops, a brief silence window signals the end of a turn. If the user starts speaking while the model is responding, you send an interruption message, which tells Gemini to stop generating audio mid-sentence and start listening again. This pre-emptive behavior is what makes the interaction feel natural.
Receive Streamed Audio Responses
Responses arrive as a sequence of audio chunks from the server. Your notebook accumulates them and plays them back in order. Because chunks arrive incrementally, playback can begin before the full response is generated, which is where the perceived low latency comes from.
Two best practices matter here. First, use voice activity detection, or VAD, on the client side to avoid streaming silence and wasting quota. Second, keep chunk sizes consistent, because irregular chunking causes audible artifacts in playback. When you graduate from Colab to a production app, VideoSDK's audio calling capabilities provide the same transport with built-in noise suppression and adaptive bitrate handling.
Adding Video Streams
Video turns a voice agent into a multimodal one. In Colab, the practical path is capturing frames from a webcam widget or from periodic screenshots, then sending them alongside your audio chunks.
Capture and Encode Frames
Browser widgets in Colab can expose camera frames to the notebook as images. Each frame needs to be encoded into a format the API accepts, typically a compressed image representation, and wrapped into a video-frame message. You do not need to send every frame. A frame every half second to one second is usually enough for the model to follow what you are showing.
Interleave Frames with Audio
The session accepts audio and video messages interleaved on the same connection. Your sending loop pushes audio chunks continuously while a slower timer pushes frames. The model treats the video as a live visual context for the ongoing audio conversation, so you can hold up an object, point at a diagram, or share your screen and ask questions about it.
Frame Rate Trade-Offs
Higher frame rates give the model fresher visual context but consume more bandwidth and quota. Lower frame rates are cheaper but can miss fast motion. For static content like documents or whiteboards, one frame per second is plenty. For dynamic content like hand gestures or moving objects, aim for the higher end. Experiment to find the balance for your use case, and remember that the model only needs enough visual continuity to ground its responses, not cinematic smoothness.
Managing Conversation Turns and Interruptions
The Live API uses a turn-taking model that mirrors human conversation. The session alternates between a listening state and a responding state, and your code manages the transitions.
When the user finishes speaking, the model takes the turn and begins responding. You can pause the session, which stops processing without closing the connection, and resume it later. You can also pre-empt the model by sending an interruption message while it is mid-response, which immediately returns the session to listening mode.
System instructions shape behavior across the whole session. Set them at session creation to define the agent's persona, language, and constraints. Tool calls extend the model's reach: you can declare functions the model may invoke mid-conversation, such as looking up a fact or triggering an action, and the model sends a structured request that your code answers before the conversation continues. Structured output settings constrain responses to a defined format, which is useful when the agent's replies feed into another system.
For flows where every step must happen in a fixed order, such as guided intake or compliance-driven dialogs, a deterministic orchestration layer like VideoSDK's Conversational Graph is a stronger foundation than free-form model judgment.
Practical Use Cases and Mini-Projects
Three small projects cover the modal spectrum and make excellent first builds.
Voice-First FAQ Bot
Configure an audio-only session with system instructions containing your product's frequently asked questions. Users speak, the model answers aloud, and tool calls can fetch live data when a question falls outside the baked-in knowledge. This project exercises audio chunking, VAD, and interruption handling.
Live Captioning Assistant
Run an audio session that transcribes speech in real time and displays the text as it arrives. The response stream includes transcript events, so your notebook can render captions with minimal extra logic. This project is the simplest way to verify your streaming pipeline end to end.
Screen-Guided Tutorial Agent
Combine screen capture frames with voice questions. The user shares their screen while working through software, and the agent watches the frames and coaches them aloud. This project exercises video interleaving, frame rate tuning, and multimodal grounding, and it maps directly onto production patterns like remote support and edtech tutoring.
Troubleshooting Common Issues
Most first-run failures fall into four buckets.
Authentication failures usually mean the Colab secret was not granted to the notebook or the key lacks the right permissions. Re-check the secret's access toggle and confirm the key is active in AI Studio.
WebSocket timeouts happen when the session goes idle past its configured limit or the network drops. Keep-alive activity, such as periodic messages, prevents idle disconnects, and clean reconnection logic handles the rest.
Audio format mismatches surface as garbled playback or rejected chunks. Confirm your capture settings match the configuration declared at session setup, especially sample rate and channel count, and keep chunk sizes uniform.
Quota errors appear once experimentation ramps up. Check your project's usage limits, reduce video frame frequency, and gate audio streaming behind voice activity detection to cut wasted requests.
Security and Cost Considerations
Treat the API key as production-sensitive from day one. Colab secrets keep it out of the notebook file, but shared notebooks can still leak access if you are careless with permissions. For anything beyond personal experimentation, route requests through a server-side proxy, such as one built on Vertex AI, so the key never reaches client devices.
Cost scales with session duration and media volume. Audio-only sessions are the cheapest starting point; adding video frames multiplies message count. Voice activity detection, sensible frame rates, and short session timeouts all reduce spend without hurting the experience.
For production deployment, add rate limiting per user, log session analytics, and put a real-time transport layer in front of the model. VideoSDK's REST APIs and SDKs handle room management, participant sessions, and recording, which pairs naturally with a streaming model backend.
Definitions Glossary
Multimodal Live API: Google's bidirectional streaming interface for Gemini models that carries audio, video, and text over a single persistent session.
WebSocket: A communication protocol that keeps a connection open between client and server so both sides can send messages at any time, forming the transport model for live streaming.
Audio Chunking: The practice of splitting a continuous audio stream into small, evenly sized segments so a streaming model can process speech as it arrives rather than waiting for a complete recording.
Voice Activity Detection (VAD): A technique that determines when a user is actually speaking, used to avoid streaming silence and to signal natural turn boundaries.
System Instructions: Session-level configuration that defines an AI agent's persona, constraints, and behavior across the entire conversation.
Tool Call: A structured request from the model to your code, asking it to execute a function and return the result before the conversation continues.
Key Takeaways
- The multimodal Live API streams audio, video, and text bidirectionally over one persistent session, enabling real-time conversational AI rather than batch request-response calls.
- Google Colab is a legitimate prototyping environment for live agents: install the Google GenAI SDK, store your API key as a Colab secret, and stream from the browser.
- Audio quality depends on consistent chunking, voice activity detection, and correct interruption handling, while video depends on deliberate frame rate trade-offs.
- Turn management, system instructions, and tool calls turn a raw stream into a controllable agent with predictable behavior.
- When your prototype outgrows the notebook, VideoSDK's real-time communication SDKs and REST APIs provide the production transport, room management, and recording layer to ship it.
Conclusion
This multimodal Live API Colab guide covered the full path from an empty notebook to a working bidirectional audio-video agent: environment setup, secret-based authentication, WebSocket session flow, audio chunking, video interleaving, and turn management. The fastest way to internalize it is to build one of the three mini-projects and iterate on chunk sizes and frame rates until the interaction feels natural.
When you are ready to move beyond Colab, explore the VideoSDK quickstart for production-grade real-time transport, browse the code samples, and grab a free tier at app.videosdk.live to start shipping. What are you building with live multimodal AI? Drop a comment, I'd love to hear which modality combination your use case needs.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ