


Whisper text to speech refers to using OpenAI's Whisper speech model, inverted to generate audio from text, as popularized by the open-source WhisperSpeech project. It produces natural-sounding speech at speeds reported around 12 times faster than real-time on a modern GPU, with an MIT/Apache-friendly licensing posture and commercial-safe training data. If you need a self-hosted, customizable alternative to paid TTS APIs, this guide explains the architecture, benchmarks, and setup path, plus how it compares to ElevenLabs, OpenAI TTS, and Google Cloud TTS in 2026.
High-quality text-to-speech used to mean one of two things: lock yourself into a commercial API with per-character pricing, or wrestle with research-grade models that sounded robotic and ran slowly. That trade-off is exactly why developers have been watching the open-source TTS space so closely.
Whisper text to speech flips a familiar tool on its head. OpenAI's Whisper is famous as a speech-to-text engine, but its encoder turns out to be a powerful component for the reverse direction too. The open-source WhisperSpeech project demonstrated that you can invert Whisper's representations to synthesize speech, and the results are good enough to power real products. By the end of this article you'll understand the pipeline architecture, the realistic performance numbers, how to get started, and where this approach wins or loses against the big commercial TTS platforms.
What Is Whisper Text-to-Speech?
Whisper text-to-speech is defined as a speech synthesis approach that repurposes the Whisper speech recognition model's internal representations to generate audio from text, rather than transcribe audio into text. The most prominent implementation is WhisperSpeech, an open-source project that builds a full TTS pipeline around Whisper's encoder.
It differs from traditional TTS in an important way. Classic systems like concatenative or older neural TTS engines were designed from scratch for generation. Whisper-based TTS instead reuses a model that already learned an extraordinarily rich understanding of what speech sounds like, across many languages and accents, during its original transcription training. That shared foundation is what gives the approach its multilingual potential and its surprisingly compact footprint.
It also differs from Whisper speech-to-text itself: same model family, opposite data direction. One turns audio into words, the other turns words into audio.
How Whisper Text-to-Speech Works
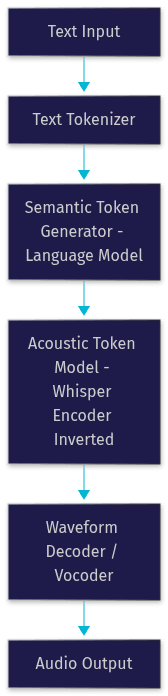
The Whisper TTS pipeline converts text into audio through a staged token-based process rather than a single end-to-end generation step. Understanding those stages matters because each one is a point where you can optimize, swap components, or fine-tune for a custom voice.
The flow looks like this. First, input text is tokenized into language-model-friendly units. A language model then predicts semantic tokens, a compressed symbolic representation of what is being said, capturing meaning and pacing without encoding the exact sound. A second model converts those semantic tokens into acoustic tokens, which describe the actual sound characteristics. Finally, a vocoder-style decoder reconstructs these tokens into a waveform you can play. The clever part is that Whisper's encoder is used in an inverted role: instead of mapping audio to text, its learned speech representations anchor the acoustic stage, which is why the project calls this "Whisper inversion."
Semantic tokens are shared across languages, which is the architectural reason multilingual support is on the roadmap rather than requiring a from-scratch rebuild per language. Once the semantic layer understands a new language, the acoustic stage can reuse much of what it already knows about human speech.
Key Features and Advantages
Whisper text to speech earns developer attention for reasons that go beyond audio quality. The licensing and data story is arguably the biggest differentiator.
Open-source and commercial-safe. The WhisperSpeech project is released under permissive MIT/Apache-style licensing, and it was trained on commercially safe data sources. That means you can ship products on top of it without the licensing anxiety that shadows models trained on scraped, unclear-provenance datasets. For a company building voice features, this alone can be the deciding factor.
Real-time capable inference. Community benchmarks report generation speeds around 12 times faster than real-time on an RTX 4090 class GPU. That headroom matters for streaming applications, where you need synthesis to finish before the playback buffer runs dry.
Voice cloning. The token-based architecture lets you condition generation on a reference voice, enabling custom voice creation from samples rather than requiring you to train a model from scratch.
Multilingual foundation. English is the primary supported language, with Polish and French demonstrated, and the shared semantic token design makes adding languages a tractable engineering problem rather than a research moonshot.
Low memory footprint. Because the pipeline reuses compact token representations instead of one massive end-to-end model, memory requirements are friendlier than many large neural TTS systems, opening the door to smaller GPU deployments.
Setting Up Whisper Text-to-Speech
Getting started with Whisper TTS is a matter of environment, model acquisition, and a first generation run, and the fastest path runs through a hosted notebook.
Prerequisites
You need a Python environment and, for reasonable performance, an NVIDIA GPU. A CUDA-capable card in the RTX 30-series or better is the practical floor for real-time work; CPU-only inference works for experimentation but is too slow for streaming. If you don't have local hardware, Google Colab's GPU runtimes are sufficient for evaluation, and the project's public Colab notebook is the recommended first stop.
The Setup Path in Plain Language
The process, described without code, goes like this. You install the project's Python package from its GitHub repository, which pulls in the model dependencies. You then load a pretrained model checkpoint, which the project hosts publicly. Once loaded, you provide text and a reference audio sample if you want voice cloning, and the pipeline returns a waveform you can save or play back. The whole loop, from install to first generated audio, is realistically under an hour on Colab.
Local Versus Cloud
For local deployment, keep an eye on VRAM: the token-based pipeline is lighter than end-to-end giants, but batch generation of long texts still benefits from headroom. For cloud deployment, Hugging Face Spaces offers a zero-infrastructure way to expose a demo, while a dedicated GPU instance suits production traffic. Whichever route you take, pin your dependency versions, because the project moves quickly and breaking changes do land.
Performance and Quality Benchmarks
Reported numbers put Whisper-based TTS generation at roughly 12 times real-time speed on an RTX 4090, with community tests on more modest hardware still achieving comfortable real-time margins. Two engineering techniques drive most of that speed: kernel compilation of the model graph, which fuses operations for faster execution, and key-value caching during token generation, which avoids recomputing attention over already-generated tokens.
On quality, community listening tests place WhisperSpeech output clearly above older open-source neural TTS and in the same conversation as commercial APIs, though subjective mean-opinion-style scores are still informal rather than rigorously published. Long-form generation is where gaps show: very long texts can hit token length limits and need chunking, and prosody on unusual phrasing can occasionally sound flat.
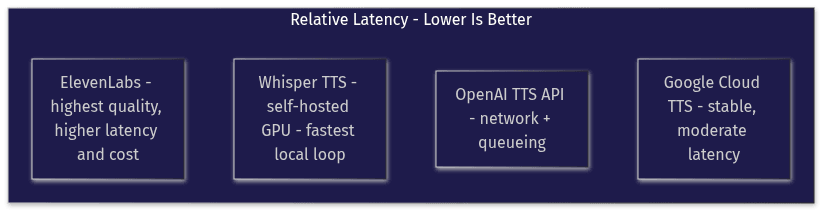
The chart below gives a qualitative sense of relative latency characteristics across popular options. Commercial APIs add network round-trips; self-hosted Whisper TTS keeps the whole pipeline on your GPU.
Use Cases and Real-World Applications
The combination of open licensing, fast inference, and voice cloning makes Whisper text to speech a strong fit for several concrete product categories.
Interactive voice assistants. Sub-real-time latency means you can synthesize responses on the fly as an assistant thinks, which is essential for natural conversational pacing. Teams building voice agents often pair a TTS engine like this with a speech-to-text layer and an LLM in a single pipeline.
Audiobook and long-form content generation. Per-character API pricing makes generating hours of audio expensive. Self-hosted synthesis turns that cost into a fixed GPU bill, which changes the economics of audiobook, podcast, and e-learning narration entirely.
Game character dialogue. Voice cloning from short reference samples lets small studios give characters distinct voices without hiring talent for every line, and the open license permits commercial distribution of the generated audio.
Accessibility tools. Screen readers, literacy apps, and assistive communication tools benefit from a free, high-quality, offline-capable voice engine, especially in scenarios where cloud dependency is a privacy or reliability problem.
Real-time captioning with voice output. Live transcription pipelines that also need spoken output, such as event accessibility systems, can run both directions of speech processing on the same Whisper-family foundation.
Comparison with Other TTS Solutions
Choosing a TTS engine in 2026 is a licensing, latency, and cost decision as much as a quality one. The table below compares Whisper text to speech against the major commercial options.
| Criteria | Whisper TTS (WhisperSpeech) | OpenAI TTS API | ElevenLabs | Google Cloud TTS |
|---|---|---|---|---|
| Licensing | Open source, commercial-safe data | Proprietary API | Proprietary API | Proprietary API |
| Latency | Fastest self-hosted, ~12x real-time on RTX 4090 | Low, network-dependent | Higher, quality-first | Moderate, stable |
| Multilingual | English, Polish, French; roadmap for more | Broad language coverage | Broad, strong quality | Broadest standard coverage |
| Voice cloning | Yes, from reference samples | Limited preset voices | Industry-leading cloning | Limited custom voices |
| Cost | GPU hosting only, no per-character fees | Pay per character | Pay per character, premium tier | Pay per character |
| Best for | Self-hosted, customizable, cost-sensitive products | Quick API integration | Maximum voice quality | Enterprise reliability |
Whisper TTS wins on cost control, customizability, and data sovereignty. ElevenLabs still wins on out-of-the-box voice quality and cloning polish, and OpenAI or Google win when you want zero infrastructure and broad language coverage today. The honest verdict: use Whisper TTS when you can host a GPU and need control; use a commercial API when time-to-market beats everything else.
Best Practices and Tips for Production
Running Whisper TTS in production is straightforward if you respect a few operational realities.
Manage GPU resources deliberately. Batch generation improves throughput for offline workloads, but for streaming, generate in small chunks and keep the pipeline warm to avoid cold-start stalls. Monitor VRAM, since long inputs and concurrent requests compound quickly.
Handle token length limits proactively. Very long texts should be split at sentence or paragraph boundaries and stitched after generation, with brief cross-fades to avoid audible seams. Consistent sample rates across chunks prevent pitch artifacts.
Post-process for consistency. Light normalization, loudness matching, and optional noise gating make batch-generated audio feel like a single production rather than a patchwork.
For commercial use, keep records of the model versions and licenses you ship with. The permissive licensing is a genuine advantage, but documenting provenance protects you if the upstream project changes terms in a future release.
Future Roadmap and Community
The WhisperSpeech roadmap points toward broader multilingual releases, building on the shared semantic token architecture, alongside research into emotion and prosody control so generated speech can carry intentional expressiveness rather than neutral delivery. Lighter model variants and custom voice fine-tuning workflows are also on the project's stated direction, which would lower the hardware bar further.
The project lives on GitHub under the WhisperSpeech repository, with an active community on the VideoSDK and general speech-AI Discord scenes, and public Hugging Face Spaces where you can hear the output before installing anything. Contribution is genuinely open: bug reports, language data contributions, and benchmark results all move the project forward. For developers who want to stay current, watching the repository releases is the most reliable signal, since the field moves fast enough that blog posts, this one included, age quickly.
Definitions Glossary
Semantic tokens: Compressed symbolic representations of speech content that capture meaning and pacing without encoding exact sound, shared across languages in the Whisper TTS pipeline.
Acoustic tokens: Token representations describing the actual sound characteristics of speech, generated from semantic tokens before waveform reconstruction.
Whisper inversion: The technique of using Whisper's speech recognition encoder in reverse, leveraging its learned speech representations to drive audio generation instead of transcription.
Voice cloning: Conditioning a TTS model on a reference audio sample so generated speech resembles a target speaker's voice characteristics.
KV-caching: An inference optimization that stores attention key-value computations for already-generated tokens, avoiding redundant recomputation and significantly speeding autoregressive generation.
Key Takeaways
- Whisper text to speech repurposes OpenAI's Whisper speech recognition model for generation, popularized by the open-source WhisperSpeech project with permissive, commercial-safe licensing.
- The pipeline runs text through tokenization, semantic tokens, acoustic tokens, and a waveform decoder, with Whisper's encoder inverted to anchor the acoustic stage.
- Community benchmarks report roughly 12 times faster than real-time generation on an RTX 4090, driven by kernel compilation and KV-caching.
- It wins against commercial APIs on cost control, customizability, and data sovereignty, while ElevenLabs and OpenAI TTS still lead on out-of-the-box quality and zero infrastructure.
- The fastest way to evaluate it is the public Colab notebook or Hugging Face Space, with local GPU deployment as the natural production path.
Conclusion
Whisper text to speech is a compelling open-source option in 2026 because it removes the two biggest objections to self-hosted TTS: slow inference and murky licensing. With real-time-capable speeds, a commercial-safe data foundation, voice cloning, and a credible multilingual roadmap, it deserves a spot on any shortlist alongside the commercial APIs. Try the public Colab notebook, explore the WhisperSpeech GitHub repository, and if you're building interactive voice experiences, pair it with a real-time communication layer like VideoSDK's audio and video calling SDKs or AI voice agent tooling. What project will you power with Whisper TTS? Drop a comment, I'd love to hear what you're building.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ