


The best Lovo AI text-to-speech alternatives in 2026 are ElevenLabs for premium voice quality and voice cloning, Microsoft Azure Neural Speech for enterprise SLAs and custom neural voices, Google Gemini Flash TTS for low-cost multilingual generation, OpenAI Text-to-Speech for simple token-based pricing, and open-source engines like Coqui TTS for fully self-hosted control. Pick based on your budget, latency needs, and language coverage, then validate quality with a Mean Opinion Score test before committing.
Every few months, a new speech synthesis model resets the bar for what "natural" sounds like, and the developers and creators who bet on the wrong TTS provider end up re-recording entire content libraries. Lovo AI earned its popularity with a polished voice catalog aimed at marketers and e-learning teams, but it is far from the only option, and it is not always the right one. Tight budgets, real-time latency requirements, or the need for a programmatic API can all push you toward a different provider. This guide breaks down the strongest Lovo AI text-to-speech alternatives, how they compare on the criteria that actually matter, and how to choose between them without wasting weeks on trials.
What Is Lovo AI Text-to-Speech?
Lovo AI is a commercial AI voice generator focused on AI voice-over production rather than raw developer infrastructure. Its core offering is a browser-based studio where you paste a script, pick from a voice catalog of several hundred voices spanning dozens of languages, and export finished audio for marketing videos, e-learning modules, podcasts, and audiobooks. Lovo's differentiators are emotional voice styles, a built-in online video editor, and per-seat subscription pricing rather than per-character API billing.
That subscription model is exactly where the friction starts for some teams. If you generate audio programmatically, per-seat pricing scales poorly compared to per-character or per-token API billing. If you need sub-second latency for an interactive voice agent, a studio-first product is the wrong shape entirely. And if you need to self-host for compliance or cost reasons, a closed commercial platform cannot follow you there. Those three gaps, pricing model, latency, and deployment control, define where the alternatives below win.
How to Evaluate Text-to-Speech Alternatives
Choosing a TTS provider is an engineering decision as much as a creative one, and five criteria separate the serious options from the demos.
Voice quality. The industry-standard measure is Mean Opinion Score (MOS), a 1-to-5 human rating of naturalness. Independent evaluations such as the Speech Arena rankings published by Artificial Analysis are more trustworthy than vendor marketing pages, because vendors tend to benchmark on their own best voices.
Language and accent coverage. A provider with 400 voices in 30 languages beats one with 100 voices in 100 languages if your audience is concentrated in a few markets. Match coverage to your actual user base.
Pricing and usage limits. Compare per-character, per-token, and per-second billing at your real monthly volume, not at the free tier. Watch for concurrency caps and rate limits that silently throttle production workloads.
API design and SDK support. Look for streaming responses, first-party SDKs in your stack, and sensible error semantics. A REST API you can integrate in an afternoon saves days.
Latency and customization. Real-time applications need low-latency streaming synthesis, while brand applications need voice cloning, emotion tags, and SSML control.
Top Lovo AI Text-to-Speech Alternatives in 2026
1. ElevenLabs TTS
ElevenLabs is the quality benchmark most developers name first when comparing AI voice generators, and for good reason. Its multilingual models produce speech that routinely tops independent MOS comparisons, and its voice library spans thousands of community and professional voices across more than 30 languages. The standout capability is voice cloning: upload a few minutes of reference audio and you get a consistent synthetic voice for your brand, which is invaluable for podcast series and long-form e-learning where voice consistency across chapters matters.
On the developer side, ElevenLabs offers a well-documented REST API with streaming support, first-party Python and JavaScript SDKs, and granular control over stability and similarity settings per generation. Pricing is credit-based, with tiers scaling from a free starter plan to enterprise contracts. The honest trade-off is cost: at high volume, ElevenLabs is typically the most expensive option on this list, and its latency, while good for streaming, is not positioned for hard real-time voice agents. Use it when output quality is the product, not when you are synthesizing thousands of hours of audio on a budget.
2. Google Gemini Flash TTS
Google's Gemini Flash TTS brings the Gemini model family's multilingual strength to speech generation, and its biggest advantage is price-to-quality ratio. Billing is per character, and the Flash-tier pricing is aggressive enough that high-volume workloads, such as generating narration for an entire video library or localizing content into a dozen languages, cost a fraction of what premium providers charge.
Integration is straightforward if you are already in the Google Cloud ecosystem. The API sits alongside the broader Gemini API surface, so authentication, quotas, and monitoring behave the way your team already expects, and multilingual coverage is strong across widely spoken languages with natural accent handling. The trade-offs are customization depth and voice identity. You get fewer named personas and less fine-grained voice cloning than ElevenLabs or Azure, and the voice catalog, while improving quickly, is younger than established players. For developers prioritizing cost-efficient, high-volume, multilingual TTS for podcasts, video, and e-learning content, Gemini Flash TTS is the value pick in 2026.
3. Microsoft Azure Neural Speech
Azure Neural Speech is the enterprise answer to text-to-speech, and it wins on the dimensions enterprises actually buy: SLAs, compliance certifications, regional data residency, and professional support. Its neural voice catalog covers more than 140 languages and locales with a wide range of speaking styles, and full SSML support gives you precise control over pronunciation, pauses, pitch, and rate, which matters for accessibility applications where exact articulation is non-negotiable.
The differentiator is Custom Neural Voice, Azure's voice cloning program. You can train a proprietary voice on your own recordings, subject to Microsoft's responsible-AI review process, and deploy it with the same reliability guarantees as standard voices. Pricing follows a standard per-character model with a generous free monthly allotment, plus a committed-use tier for high volume. The trade-off is complexity: the Azure portal, resource provisioning, and endpoint configuration involve more moving parts than a single-endpoint API like OpenAI's. Teams already on Azure or building regulated products get the most value here.
4. OpenAI Text-to-Speech
OpenAI's text-to-speech API is the simplicity pick. One endpoint, a handful of well-tuned voices, and token-based billing that matches how developers already pay for OpenAI models. The voice quality sits comfortably in the top tier for English and major languages, with natural prosody that holds up well for conversational content, video narration, and app UI audio.
The developer experience is the real product. Authentication works with the same key infrastructure as the rest of the OpenAI API, streaming responses arrive quickly enough for near-real-time use, and the surface area is small enough that integration takes an afternoon rather than a week. The trade-offs are breadth and control: the voice catalog is intentionally curated rather than vast, there is no self-serve voice cloning, and fine-grained SSML-style control is limited compared to Azure. If your team already uses OpenAI models and wants dependable TTS without evaluating five vendors, this is the path of least resistance.
5. Open-Source TTS Options
For teams with compliance constraints, unpredictable volume, or a preference for full control, open-source neural voice synthesis removes the per-call cost entirely. Coqui TTS remains the most widely used open framework, supporting multiple model architectures, fine-tuning on custom datasets, and deployment on your own hardware or cloud GPUs. Piper offers lightweight, fast synthesis that runs on modest hardware, and newer community models continue to close the quality gap with commercial APIs.
The economics are simple: you trade capital and operational cost for zero marginal cost. A GPU instance running your own model handles unlimited synthesis with no per-character bill, which is transformative for high-volume workloads like audiobook production or accessibility features serving thousands of users. The trade-offs are real too. You own the model lifecycle, the hardware sizing, the latency tuning, and the quality evaluation. Community support replaces vendor SLAs, and reaching top-tier MOS usually requires fine-tuning on domain-specific data. Choose open source when volume is high, requirements are stable, and your team has ML operations skills.
Detailed Comparison: Lovo AI vs the Alternatives
The table below compares Lovo AI against the five alternatives across the evaluation criteria from earlier. Use it as a shortlist generator, then trial the top two candidates on your own content.
| Provider | Voice Quality (MOS tier) | Language Coverage | Pricing Model | Real-Time Streaming | Voice Cloning | Best For |
|---|---|---|---|---|---|---|
| Lovo AI | High | 100+ languages, 500+ voices | Per-seat subscription | Limited | Yes (select voices) | Studio-based voice-over production |
| ElevenLabs | Top tier | 30+ languages, large library | Credit-based, premium per character | Yes | Yes, best-in-class | Premium brand audio, podcasts |
| Google Gemini Flash TTS | High | Strong multilingual | Low per-character | Yes | Limited | High-volume, cost-sensitive workloads |
| Azure Neural Speech | High | 140+ languages and locales | Per-character, free allotment | Yes | Yes, enterprise program | Regulated and enterprise deployments |
| OpenAI TTS | High | Major languages, curated voices | Token-based | Yes | No | Fast integration, existing OpenAI stacks |
| Open-source (Coqui, Piper) | Variable, fine-tunable | Depends on model | Infra cost only | Self-managed | Yes, via fine-tuning | Unlimited volume, full control |
The most important row distinction is pricing model. Lovo's per-seat subscription suits small creative teams, but any programmatic or high-volume workload shifts the math decisively toward per-character APIs or self-hosted models.
Decision Flow for Choosing a TTS Provider
A structured decision process beats feature-list browsing. Start with your budget ceiling and monthly volume, because that immediately eliminates providers whose pricing model cannot scale with you. Then ask whether you need real-time streaming, which rules out studio-first tools. Then check language coverage against your actual audience, and finally evaluate customization needs like cloning and emotion control.
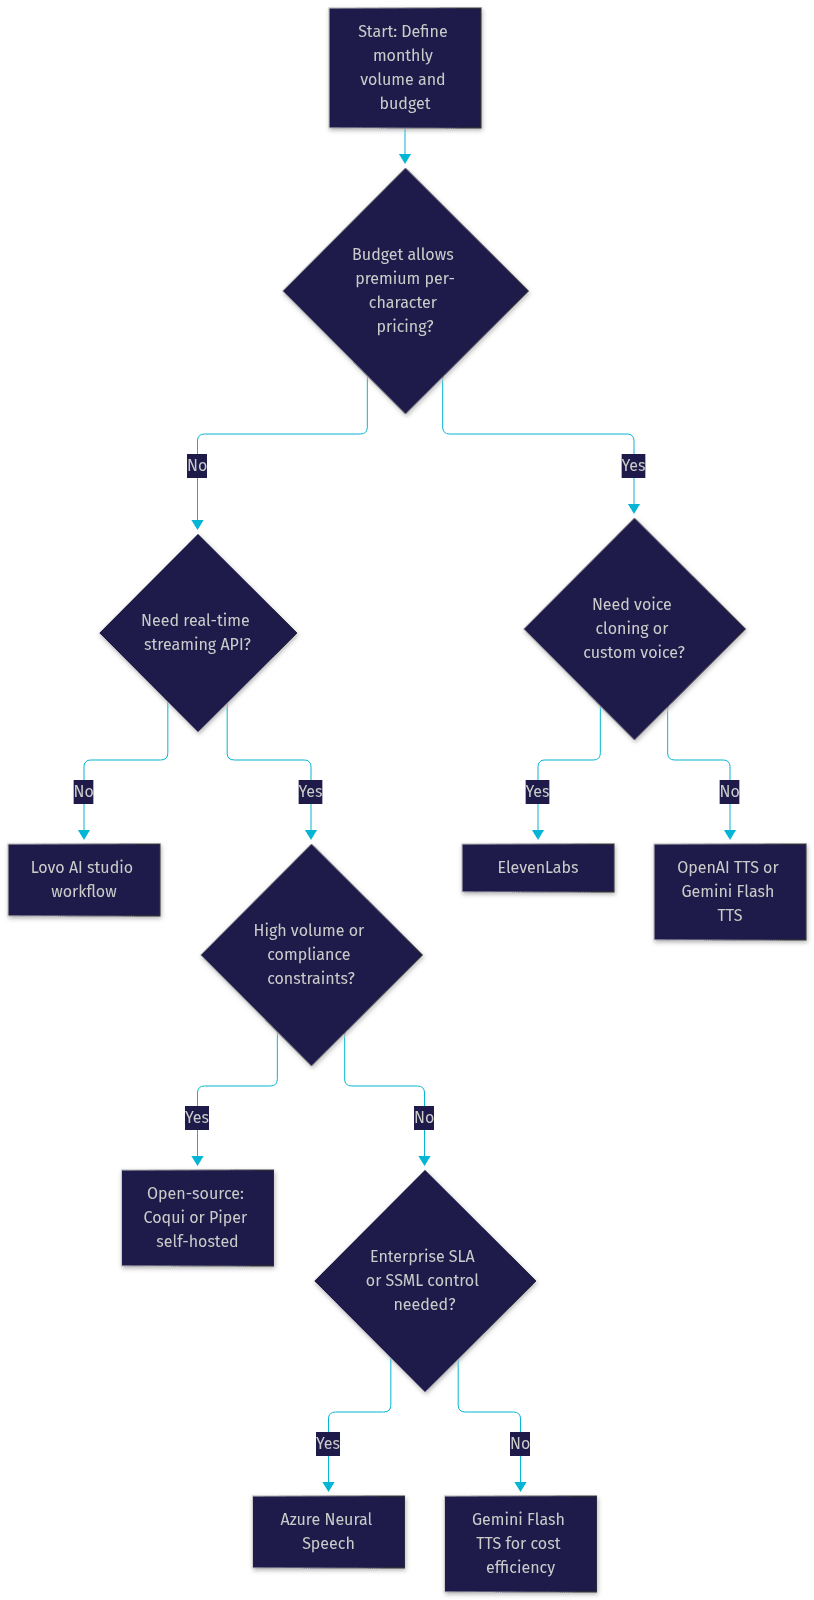
Walk the tree with your real numbers plugged in. Most teams land on either a premium API for brand-critical audio or a low-cost API for volume, with open source reserved for the highest-volume, most control-hungry cases.
Implementation Tips and Best Practices
Once you pick a provider, a few engineering habits separate smooth production deployments from painful ones.
Authentication. Store API keys in a secrets manager, never in client-side code or version control, and rotate them on a schedule. For user-facing apps, proxy all TTS calls through your own backend so keys never reach the browser.
Rate limits and batching. Read the provider's concurrency limits before launch, not after your first outage. Queue non-urgent synthesis jobs, batch long scripts into chunks, and implement exponential backoff on 429 responses so transient throttling degrades gracefully instead of failing.
Latency optimization. For interactive use, keep connections warm rather than establishing a fresh TLS handshake per request, cache repeated phrases such as greetings and prompts, and serve generated audio through a CDN when the same clips replay often.
Voice consistency. For long scripts, split text at sentence boundaries rather than arbitrary character counts, keep generation parameters fixed across chunks, and store the voice identifier and settings with your project so re-renders months later still sound identical.
Definitions Glossary
Mean Opinion Score (MOS): A 1-to-5 human-rated measure of speech naturalness, the standard metric for comparing synthetic voice quality across TTS providers.
Voice cloning:** Training a synthetic voice on reference audio of a specific speaker so generated speech matches their timbre and delivery, used for brand consistency in podcasts and e-learning.
SSML:** Speech Synthesis Markup Language, an XML-based standard for controlling pronunciation, pauses, pitch, and speaking rate in neural TTS engines like Azure's.
Neural voice synthesis:** Deep-learning-based speech generation that models prosody and acoustics end to end, producing far more natural output than older concatenative systems.
Real-time TTS:** Speech synthesis delivered as a stream with low enough latency to support interactive applications such as voice agents and live narration.
Key Takeaways
- Lovo AI excels at studio-based voice-over production, but per-seat subscription pricing, limited real-time APIs, and no self-hosting make it a poor fit for programmatic and high-volume workloads.
- ElevenLabs leads on voice quality and cloning, Azure Neural Speech wins on enterprise SLAs and SSML control, and Gemini Flash TTS is the value pick for multilingual volume.
- OpenAI TTS offers the fastest integration path for teams already in its ecosystem, while open-source engines like Coqui TTS eliminate per-call costs at the price of operational ownership.
- Evaluate providers on MOS, language coverage, pricing model, API design, and latency, in that order of rigor, and always trial with your own scripts.
- If you are building interactive voice experiences, pair your TTS choice with a real-time communication layer; VideoSDK's AI agent infrastructure integrates with leading TTS providers to deliver sub-second voice interactions.
Conclusion
The right Lovo AI text-to-speech alternative depends entirely on your constraints: budget ceiling, latency requirements, language coverage, and how much control you need over the voice itself. Premium quality points to ElevenLabs, enterprise guarantees point to Azure, cost-efficient volume points to Gemini Flash TTS, and full control points to open source. Trial at least two candidates, run a small MOS evaluation on your own content, and compare the actual monthly bill before committing. If your project involves real-time voice, explore how VideoSDK's AI agents connect STT, LLM, and TTS providers into low-latency voice pipelines, and start free at app.videosdk.live. What are you building with TTS? Drop a comment, I'd love to hear which use case you are working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ