


If you need a cheaper or lower-latency ElevenLabs text to speech alternative in 2026, the strongest options are Inworld AI for expressive real-time voices, Palabra for sub-100 ms streaming synthesis in voice agents, Natural TTS Voice for cost-efficient multi-provider access, and SpeechSDK for an open-source, provider-agnostic hub. Choose based on your latency budget, per-character cost ceiling, and voice cloning requirements. VideoSDK users can pair any of these with the VideoSDK AI Agents pipeline for end-to-end voice experiences.
ElevenLabs set the bar for AI speech synthesis, and for many teams it still clears it. But pricing that scales painfully with character volume, latency that works for voice-over but strains real-time agents, and a single-vendor dependency have pushed a lot of developers to search for an ElevenLabs text to speech alternative in 2026.
This article breaks down why teams look beyond ElevenLabs, the criteria that actually matter when evaluating a text to speech API, the four strongest contenders this year, benchmark data, and a practical migration checklist. By the end, you will have a shortlist matched to your specific workload, whether that is bulk voice-over generation or a sub-second conversational agent.
ElevenLabs Text-to-Speech Alternative: Why Look Beyond?
The most common reason developers evaluate ElevenLabs competitors is cost at scale. ElevenLabs pricing is metered per character, and conversational AI workloads are character-hungry: a single voice agent session can burn tens of thousands of characters, and volume discounts only soften the curve after significant spend commitments.
Latency is the second driver. ElevenLabs is excellent for batch synthesis, but real-time voice agents need time-to-first-audio well under a few hundred milliseconds. If your TTS provider is the slowest link in an STT-to-LLM-to-TTS chain, users notice the dead air.
Vendor lock-in rounds out the top three. When your voice library, cloning data, and application logic all live inside one provider's API surface, negotiating leverage and architectural flexibility both shrink. A provider-agnostic or self-hosted option protects you from price changes and model deprecations.
None of this means ElevenLabs is a bad product. It means the right choice is conditional, and the rest of this article gives you the framework to make that call honestly.
Core Criteria for Choosing a TTS Alternative
Evaluating a text to speech API on marketing pages is a losing game. Four criteria separate real differences from demo polish.
Audio Quality and Naturalness
Objective quality is measurable. Mean Opinion Score (MOS) studies and community-driven rankings like Artificial Analysis's Speech Arena provide comparable numbers across providers, rating naturalness, prosody, and intelligibility on conversational audio. Subjectively, listen for the failure modes benchmarks miss: odd pauses, flat emotional range on long passages, and pronunciation drift on domain-specific vocabulary. A provider that scores well on short sentences can still fall apart on a 500-word support script.
Latency and Real-Time Capabilities
Time-to-first-audio is the metric that matters for interactive systems: how many milliseconds pass between sending text and hearing the first syllable. Streaming synthesis, where audio is returned in word-level or sentence-level chunks while generation continues, is what keeps conversational agents feeling live. Batch synthesis, which returns a complete audio file, is fine for voice-over automation but unusable for a real-time assistant. Any ElevenLabs alternative you shortlist for agents should stream natively.
Pricing and Cost Efficiency
Compare cost per 1,000 characters, but also compare what is included: free tier size, concurrent request limits, caching of repeated phrases, and whether cloned voices cost extra. A provider with a slightly higher per-character rate but built-in TTS caching can end up dramatically cheaper for agents that repeat common phrases.
Multilingual Support and Voice Cloning
Check language count, but more importantly check accent fidelity per language, because a provider supporting 30 languages with weak accent handling may serve you worse than one supporting 12 well. For cloning, the key variables are required sample length (three seconds versus thirty seconds of reference audio changes your data collection effort), whether cloning is available on lower tiers, and whether cloned voices are portable or locked to the platform.
Top Contenders in 2026
These four alternatives cover the main architectural positions: expressive real-time synthesis, marketplace cost efficiency, streaming-first agent TTS, and open-source provider aggregation.
Inworld AI: Real-Time Expressive TTS
Inworld AI focuses on expressive, low-latency speech synthesis aimed at gaming and interactive characters. Its strengths are emotional range, character-consistent voices, and latency profiles designed for live interaction rather than batch rendering. Voice cloning is supported, and the API is built for streaming workloads. Pricing sits in the mid-range among commercial providers. Inworld is the pick when personality and expressiveness of the voice matter as much as raw speed.
Natural TTS Voice: Multi-Provider Marketplace
Natural TTS Voice aggregates multiple underlying engines, including ElevenLabs-class models alongside Google and Azure voices, behind one API. The value proposition is cost efficiency and selection: you can route each request to the cheapest engine that meets your quality bar, and switch voices without switching vendors. For bulk content generation and multi-voice projects, marketplace routing frequently beats single-provider pricing. The trade-off is that you depend on the aggregator's uptime and feature parity, not just one upstream provider.
Palabra: Streaming-First TTS for Voice Agents
Palabra is built specifically for real-time conversational AI. Its headline capabilities are word-level streaming synthesis, sub-100 ms time-to-first-audio, and a de-accenting feature that normalizes pronunciation across accents for consistent agent delivery. For IVR, telephony, and voice assistant workloads where every 100 ms of delay compounds user frustration, a streaming-first architecture is a genuine differentiator over batch-oriented providers.
SpeechSDK: Unified Open-Source TTS Hub
SpeechSDK takes the opposite approach: instead of one more proprietary engine, it offers a single open-source API surface over ten or more providers, letting you swap ElevenLabs for Cartesia, OpenAI TTS, or Google TTS without rewriting application logic. That provider-agnostic abstraction is powerful for teams that want negotiating leverage, fallback routing, and the option to self-host parts of the stack. The cost is integration effort: you own the routing logic and the operational responsibility that a managed provider would absorb.
Deep-Dive Comparison Table
The table below condenses the evaluation into the dimensions that drive most decisions. Treat it as a starting grid, then validate against your own workload.
| Provider | Time-to-First-Audio | Cost Position | Languages | Voice Cloning | Streaming |
|---|---|---|---|---|---|
| ElevenLabs (baseline) | Moderate | Premium per-character | 30+ | Yes, short samples | Sentence-level |
| Inworld AI | Low | Mid-range | 10+ | Yes | Word-level |
| Natural TTS Voice | Varies by engine | Low via routing | 20+ | Limited | Depends on engine |
| Palabra | Sub-100 ms claimed | Mid-range | Growing | Yes | Word-level |
| SpeechSDK | Depends on provider | Engine cost only | Provider-dependent | Provider-dependent | Configurable |
[LINKABLE ASSET — comparison table]
Palabra's row is the one to scrutinize for agent workloads, because time-to-first-audio is where batch-oriented providers lose interactive users. SpeechSDK's row is the one that matters for teams prioritizing flexibility over turnkey convenience.
A generic streaming TTS pipeline shows where each provider fits in the chain:
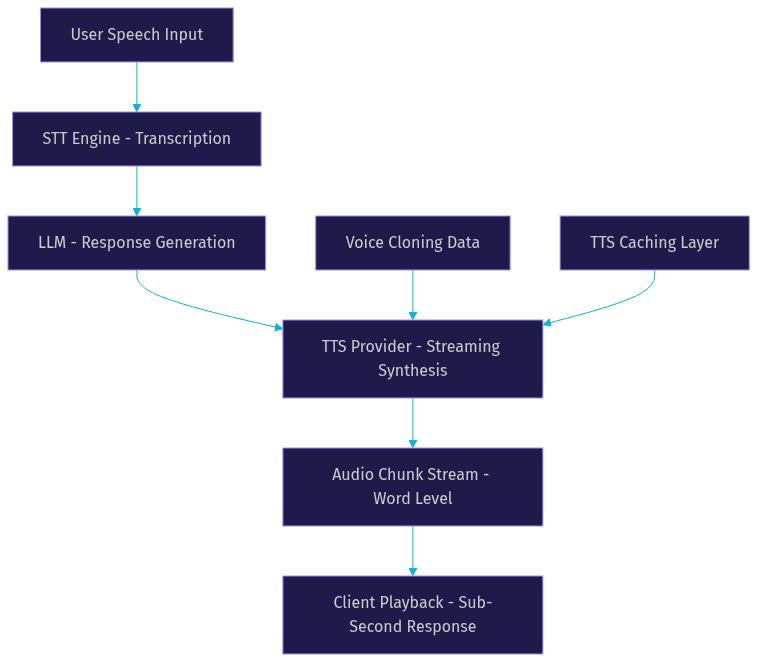
Inworld and Palabra sit at the synthesis stage optimized for streaming. Natural TTS Voice routes the synthesis stage across engines. SpeechSDK abstracts the entire synthesis stage behind one interface.
When to Choose Each Alternative
Use Cases Best Suited for Inworld
Choose Inworld when the voice is a character, not a narrator. Gaming NPCs, interactive fiction, brand mascots, and companion apps all benefit from Inworld's expressive range and consistent persona delivery. Its latency profile also holds up in live chat scenarios where the character responds in real time. It is not the best fit for bulk, cost-sensitive voice-over generation where expressiveness is wasted spend.
Use Cases Best Suited for Natural TTS Voice
Choose a marketplace approach when volume is your dominant constraint. E-learning narration, audiobook pipelines, news reading, and any project needing dozens of distinct voices across long-form content get better unit economics from engine routing. Multi-voice projects also benefit, since you are not locked into one provider's voice library. Avoid it when you need tight, guaranteed latency SLAs for interactive agents, because routing adds a variable layer.
Use Cases Best Suited for Palabra
Choose Palabra when you are building a real-time voice assistant, IVR system, or telephony integration and every fraction of a second counts. Word-level streaming plus de-accenting is purpose-built for phone-grade interactions where clarity and immediacy dominate. Teams building AI phone agents on infrastructure like VideoSDK's telephony and SIP integration will find a streaming-first TTS provider slots naturally into that pipeline. It is less suited to cinematic voice-over work where emotional richness beats raw speed.
Use Cases Best Suited for SpeechSDK
Choose SpeechSDK when provider independence is the requirement. Regulated teams, cost-optimization projects, and platforms that resell voice capability all benefit from one API over many engines, with fallback routing when a provider degrades. It also fits teams wanting an open-source TTS SDK they can inspect and extend. It is not for teams that want a fully managed, single-vendor experience with zero integration overhead.
Real-World Performance Benchmarks
Independent comparison data for TTS in 2026 comes mainly from Artificial Analysis's Speech Arena and community-run latency tests. The pattern across sources is consistent: no single provider wins on quality, latency, and price simultaneously. ElevenLabs-class models tend to lead naturalness rankings, streaming-first providers lead time-to-first-audio, and marketplace routing leads on blended cost.
The chart below illustrates the typical trade-off shape you should expect, using representative figures rather than exact current rankings:
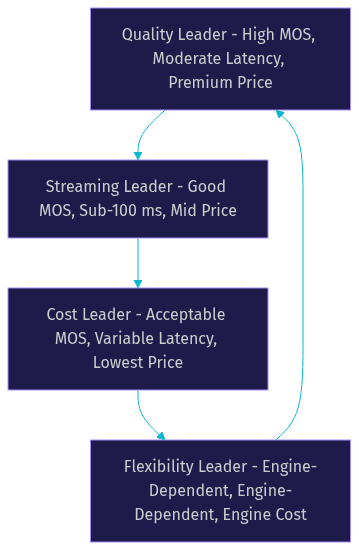
Read this as a cycle, not a hierarchy: every provider occupies one corner of the quality-latency-cost triangle, and your workload determines which corner is non-negotiable. When you benchmark yourself, measure time-to-first-audio from your own infrastructure, not the provider's region, because network distance routinely adds 50 to 150 ms that vendor benchmarks exclude.
Migration Checklist: Moving from ElevenLabs to a New Provider
API Compatibility and Endpoint Mapping
Start by mapping your current request surface: text input, voice selection, model or quality tier, and output format. Most providers cover the same conceptual ground with different names, so build a translation layer rather than rewriting call sites. Authentication differs the most, since header schemes and key rotation policies vary. Plan a dual-provider period where both providers run in parallel behind your abstraction, and cut over per traffic segment once the new provider has cleared a week of production-shaped load.
Voice Model Porting and Cloning
Voice porting is the migration step that bites. Cloned voices are generally not portable between providers, so you will need to re-clone from your original reference audio on the new platform. Check the new provider's required sample length: if you cloned with short samples on ElevenLabs and the new provider needs longer, higher-fidelity audio, you may need to re-record or source better reference material. Keep your reference audio archived and provider-neutral from day one, because that archive is your insurance policy against every future migration.
Future Trends in AI TTS
Three shifts are reshaping the TTS landscape through 2026 and beyond. First, multimodal real-time models, including OpenAI's Realtime API and Google's Gemini Live, are collapsing STT, LLM, and TTS into single speech-to-speech endpoints, which changes the integration question from "which TTS provider" to "pipeline versus end-to-end model." Second, on-device and edge synthesis is maturing, driven by open-weight models, which matters for privacy-sensitive and offline scenarios. Third, pricing pressure is pushing per-character models toward per-minute or per-session pricing as competition intensifies.
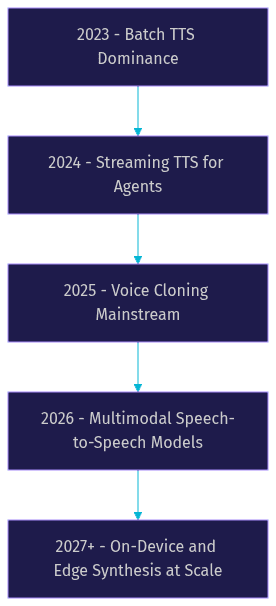
For developers building voice agents, the practical implication is to keep your TTS layer swappable, because the next architectural shift may replace the component rather than the vendor.
Definitions Glossary
Time-to-First-Audio: The delay between sending a synthesis request and receiving the first playable audio chunk. It is the dominant latency metric for real-time voice agents and IVR systems.
Streaming TTS: A synthesis mode that returns audio incrementally in word-level or sentence-level chunks while generation continues, enabling sub-second conversational responses instead of waiting for a complete audio file.
Voice Cloning: The process of creating a custom synthetic voice from reference audio samples of a target speaker. Required sample length and portability of cloned voices vary significantly between providers.
TTS Caching: Storing and reusing synthesized audio for repeated phrases. For voice agents that say the same greetings and confirmations frequently, caching can materially reduce per-character spend.
Speech Arena: Artificial Analysis's community-driven benchmark ranking speech models on naturalness and intelligibility, one of the few independent comparison sources for TTS quality.
Key Takeaways
- There is no single best ElevenLabs text to speech alternative; the right choice depends on whether your non-negotiable is quality, latency, cost, or flexibility.
- Palabra and Inworld lead for real-time agents, Natural TTS Voice leads for bulk cost efficiency, and SpeechSDK leads for provider-agnostic control.
- Measure time-to-first-audio from your own infrastructure, because network distance adds latency that vendor benchmarks exclude.
- Cloned voices are rarely portable between providers, so archive provider-neutral reference audio before any migration.
- Developers building full voice agent pipelines can pair any of these TTS providers with VideoSDK's AI Agents SDK for the real-time transport and session layer.
Conclusion
Choosing an ElevenLabs text to speech alternative in 2026 is a conditional decision, not a ranking exercise. Pin down your latency budget, your cost per 1,000 characters ceiling, and your cloning requirements first, then let those constraints eliminate providers for you. For conversational agents, prioritize streaming-first providers and validate latency yourself. For bulk generation, let unit economics decide. Whatever you pick, keep the TTS layer swappable, because multimodal speech-to-speech models are already changing the shape of this stack. If you are building voice agents end to end, explore the VideoSDK AI Agents documentation and try the free tier at app.videosdk.live. What are you building with TTS? Drop a comment, I would love to hear which workload you are optimizing for.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ