


AI text to speech characters are synthetic voices generated by neural TTS models that are designed to sound like specific personas, such as cartoon heroes, game NPCs, or branded mascots, rather than neutral narrators. Modern character voice generators combine voice cloning, emotion control, and multilingual synthesis, and many expose real-time APIs so developers can power talking avatars, games, and animations. This guide covers how the technology works, what features to evaluate, and how to integrate character voices into your own projects.
Introduction
A single indie animator in 2026 can voice an entire cast of characters without booking a single studio session. That shift is driven by AI text to speech characters: neural models trained to produce expressive, persona-specific speech from plain text. What used to require voice actors, recording booths, and weeks of retakes now takes minutes and a script.
The underlying technology has matured fast. Modern text-to-speech systems no longer produce the flat, robotic delivery of older systems. They model prosody, emotion, pacing, and even breathing, which makes them viable for cartoons, video games, podcasts, e-learning, and interactive avatars.
In this article, you will learn what AI character voices actually are, which features separate a good character voice generator from a generic one, how the leading platforms compare, and how to integrate synthetic character dialogue into your own workflow, from script to synced audio.
What Are AI Text-to-Speech Characters?
AI text-to-speech characters are defined as synthetic voices produced by neural TTS models that carry a distinct persona, accent, age, emotional range, or stylistic identity, rather than a neutral reading voice. They differ from generic TTS in one key way: the voice is treated as a character asset, with consistent personality traits that persist across lines, episodes, or game sessions.
The core technologies behind them are neural vocoders, which reconstruct natural-sounding waveforms from acoustic features; voice cloning, which learns a target voice from reference audio; and prosody and emotion control, which lets you steer pitch, speed, emphasis, and mood per line of dialogue.
Typical use cases illustrate the range. Animation studios use character voices for pre-visualization and even final renders. Game developers use them to voice hundreds of NPCs without casting calls. Podcast producers generate full fictional casts. E-learning teams use consistent character narrators to make courses more engaging. In each case, the value is the same: expressive, on-demand voice with a repeatable identity.
Key Features to Look For in a Character Voice Generator
Not every TTS service is built for character work. When you evaluate a character voice generator, these are the five capabilities that actually determine whether it will hold up in production.
Voice Library Size and Diversity
A strong platform offers a broad catalog of pre-built character voices spanning ages, genders, accents, and archetypes, from gruff villains to cheerful sidekicks. Check language coverage too: multilingual AI TTS matters if your game or animation ships internationally, and the best services preserve a character's personality across languages rather than producing a generic translated voice. A library of a few hundred voices with clear personality labels beats thousands of near-identical neutral voices.
Voice Cloning and Custom Character Creation
Voice cloning lets you create a custom AI voice model from reference audio of your own character performance or a hired actor. Most services need anywhere from a few seconds to several minutes of clean sample audio, depending on whether they offer instant cloning or professional-grade cloning with more training data. Ethically, only clone voices you have explicit permission to use, and prefer platforms that require a recorded consent statement from the person being cloned. We cover the legal side in more detail later in this article.
Emotional and Prosody Controls
Expressive dialogue is what separates character TTS from narration TTS. Look for platforms that expose emotion presets such as cheerful, angry, whispering, or sad, plus fine-grained control over pitch, speaking rate, and emphasis. Some services also support per-word emphasis and pauses, which matters enormously for comedic timing or dramatic beats. Without prosody control, even a great cloned voice will sound monotone across a long script.
Real-Time vs. Batch Generation
Batch generation is fine for pre-recorded animation and podcasts: you submit a script, wait, and retrieve finished audio. Real-time TTS is a different engineering problem. If you are building interactive talking avatars, live game dialogue, or an AI voice agent, you need a real-time TTS API with sub-second first-audio latency and streaming output. Latency budget matters here: anything above a few hundred milliseconds breaks the illusion of a live character. Confirm the platform supports streaming before committing.
Licensing, Commercial Use, and Attribution
Read the licensing terms before you build a product on top of any voice. Key questions: can you use the output in commercial games or monetized videos? Is the license royalty-free or per-project? Do cloned voices require attribution? Some platforms restrict commercial use of specific premium voices, and cloned-voice rights can differ from library-voice rights. Getting this wrong after shipping is expensive, so verify commercial terms up front.
Top AI TTS Platforms Offering Character Voices
The platform landscape in 2026 is broad, spanning web-based generators for creators and API-first services for developers. Here is how the notable options compare for character voice work.
Narakeet focuses on narrated video and e-learning, with a large multilingual voice library covering dozens of languages and accents. It is web-first with an API available, uses a credit-based pricing model with a usable free tier, and its strength is consistent narration characters for courses and explainers rather than highly emotive game dialogue.
MiniMax (Renderful) offers expressive character voices with strong multilingual support and an API for developers. Its character catalog leans toward stylized, personality-rich voices, and pricing is typically pay-as-you-go per character of generated audio. It is a solid middle ground between creator tools and developer infrastructure.
Voices AI is a consumer-oriented character voice generator with a catalog of stylized personas aimed at social content, memes, and short-form video. It is primarily web-based, inexpensive, and easy to use, but it is not designed for low-latency or programmatic production pipelines.
Hedra AI targets the multimodal end of the spectrum: it pairs character voices with facial animation and talking avatars, which makes it attractive for animated shorts and virtual presenters. Its pricing is subscription-based with per-run generation limits, and its standout strength is voice-plus-face synchronization in one tool.
HuggingFace visual_novel model and similar open-weight community models appeal to developers who want self-hosted character TTS. You trade turnkey convenience for control: no per-run costs at scale, full customization, and the ability to fine-tune voices on your own data, but you own the infrastructure and the latency engineering.
The right choice depends on your constraints, and the decision usually follows a predictable path:
For teams building interactive products rather than pre-rendered content, an API-first service with streaming support is almost always the right starting point, because you can prototype quickly and scale without re-architecting.
How to Integrate AI Character Voices Into Your Workflow
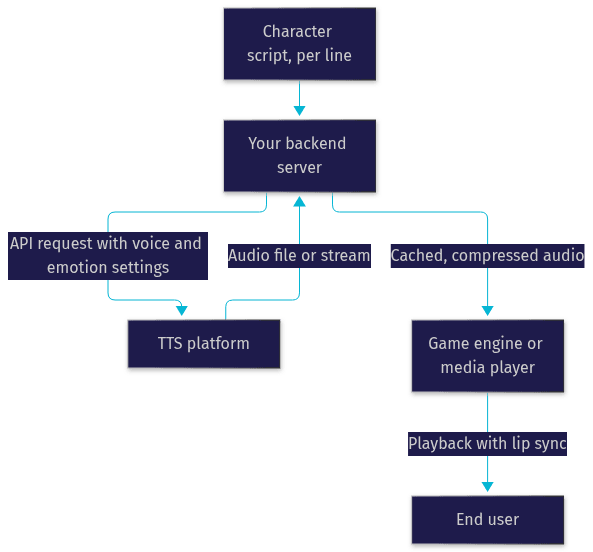
Integrating synthetic character dialogue into a web project, game, or animation follows a consistent pattern regardless of platform. Here is the end-to-end flow in plain terms.
Step 1: Choose a Platform and Obtain API Credentials
Register with your chosen service and generate API credentials from its developer dashboard. Store the secret key on your server, never in frontend code, and route all generation requests through your own backend. This keeps your key safe and gives you a single place to add rate limiting, caching, and logging later.
Step 2: Prepare the Script and Select a Character Voice
Write or import your dialogue script, then pick the character voice that matches the persona. Break long scripts into logical lines or scenes, because per-line generation gives you finer control over pacing, retries, and emotion settings. Tag each line with the intended emotion or delivery style if the platform supports it.
Step 3: Send the Text to the Service
Submit each line to the platform through its web interface during prototyping, or through its REST endpoint from your backend in production. The service synthesizes the audio and returns either a downloadable file or a stream. For interactive applications, request streaming output so playback can begin before the full line is generated.
Step 4: Retrieve the Audio and Sync It With Your Engine
Take the returned audio and attach it to the corresponding scene, animation, or game dialogue trigger. In game engines, you typically import the audio as an asset and bind it to the character's dialogue event. For animations, align the audio track with your lip-sync or facial animation timeline. Some platforms, like Hedra, generate the voice and facial motion together, which removes the manual sync step.
Step 5: Optimize for Size and Latency
Compress generated audio to a format appropriate for your target, cache repeated lines so they are never regenerated, and prefetch dialogue that is likely to play soon. For live avatars, keep first-audio latency low by streaming and by keeping lines short.
Common Pitfalls
Three problems bite most teams. First, credential and token expiration: generation quietly fails when an API token lapses, so build in renewal and clear error handling. Second, voice-style mismatch: a voice that sounded perfect in a sample can feel wrong across a full scene, so always audition voices with real dialogue, not demo text. Third, latency spikes under load: batch services can queue during peak hours, which breaks live experiences, so test under realistic concurrency before launch.
Best Practices for Authentic-Sounding Character Dialogue
Great character voices start with great scripts. Write dialogue that matches the character's personality, vocabulary, and rhythm. A sarcastic sidekick should have shorter, punchier lines than a solemn elder, and the TTS engine can only amplify what the script gives it.
Use emotion tags and prosody controls deliberately. Mark a line as whispered, furious, or exhausted rather than hoping the model infers it. Small adjustments to pitch and speaking rate often do more for believability than switching voices entirely.
Test with short samples and iterate. Generate a few candidate takes of each key line, tweak pitch and speed, and compare them side by side before committing to a full episode. This is far cheaper than re-rendering everything after the fact.
Finally, maintain consistency. Lock the voice ID, emotion defaults, and pacing settings per character, and document them, so episode twelve sounds like episode one. Consistency is what turns a synthetic voice into a recognizable character.
Ethical and Legal Considerations
Cloning a real person's voice without consent is both an ethical violation and, in a growing number of jurisdictions, a legal one. Only clone voices you own or have documented permission to use, and prefer platforms that require a recorded consent statement as part of the cloning workflow.
Disclosure is increasingly expected, and in some regions required, when synthetic voices are used in content that could be mistaken for real people. Label AI-generated character dialogue where the context could mislead, especially in news-adjacent or educational content.
Finally, respect platform policies. Major TTS providers actively enforce deep-fake prevention rules, including bans on cloning public figures and politicians without authorization. Violating these policies can terminate your account mid-project, so read the acceptable-use policy before you build.
Future Trends in AI TTS Characters
The near future of AI TTS characters is multimodal and interactive. Expect character voices to ship increasingly alongside facial animation, so a single generation step produces both voice and lip-synced expression, collapsing the animation pipeline further.
Real-time interactive agents are the bigger shift. LLM-driven characters that listen, think, and respond in natural voice are moving from demos to products, and the same infrastructure that powers AI voice agents is starting to power game NPCs and virtual hosts. If you are building in this space, the VideoSDK AI agents documentation is a good starting point for wiring real-time voice into live rooms and applications.
Audio fidelity is also climbing. High-definition output at 24 kHz and beyond, better breath and emotion modeling, and lower streaming latency are all on current roadmaps, which means the gap between synthetic and recorded character voices keeps shrinking.
Definitions Glossary
Character voice generator: A TTS service or model whose voices are designed as distinct personas with consistent personality, accent, and emotional range, used for games, animation, and interactive media.
Voice cloning: The process of training a custom AI voice model from reference audio of a target voice, ranging from a few seconds of sample audio for instant cloning to minutes of data for professional-grade results.
Prosody control: The ability to adjust pitch, speaking rate, emphasis, and pauses in generated speech, which is essential for expressive character dialogue.
Real-time TTS API: A text-to-speech interface that streams audio with sub-second first-audio latency, enabling live avatars and interactive agents rather than pre-recorded content.
Talking avatar: A digital character that combines synthesized voice with facial animation or lip sync, often generated end-to-end by multimodal AI platforms.
Key Takeaways
- AI text to speech characters are persona-specific neural voices, not generic narrators, and their value comes from consistent identity plus expressive emotion control.
- Evaluate platforms on voice library diversity, cloning quality, prosody controls, real-time streaming support, and commercial licensing terms before committing.
- The integration workflow is consistent across platforms: credentials on the server, per-line scripts, API generation, engine sync, then compression and caching for latency.
- Ethical use requires consent for cloning, disclosure where synthetic voices could mislead, and compliance with platform deep-fake policies.
- The frontier is multimodal: real-time LLM-driven characters with voice and facial animation together, a space where real-time voice infrastructure like VideoSDK's AI agent SDKs is already enabling live interactive products.
Conclusion
AI text to speech characters have moved from novelty to production tool. In 2026, a solo creator can cast an entire show, and a development team can voice a game's full NPC roster, with neural voices that carry real personality. The winners in this space will be the teams that treat voices as characters, with locked settings, deliberate emotion, and consistent identity, rather than as disposable text-to-speech output.
Start small: pick a platform with a free tier, audition voices with your actual dialogue, and prototype one scene before scaling. Compare at least two services on latency and licensing before you commit to a pipeline. And if you are building interactive, real-time characters, explore how VideoSDK's real-time communication SDKs and AI agent infrastructure can bring your talking characters live.
What are you building with AI character voices? Drop a comment, I'd love to hear what kind of character, game, or animation you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ