


Open source speech to text refers to transcription engines whose model weights and source code are freely available under permissive licenses, letting you run speech recognition entirely on your own hardware. In 2026, projects like OpenAI's Whisper, OpenASR, Qwen3-ASR, and Moonshine deliver word-error rates competitive with commercial APIs while keeping audio data private and costs near zero. This guide compares the major engines, their benchmarks, and deployment patterns so you can pick the right one for your project, and shows how VideoSDK's real-time transcription fits into production pipelines that need live captions alongside calls and streams.
Sending every customer call, medical dictation, or meeting recording to a third-party speech API creates three problems at once: recurring cost, data exposure, and vendor lock-in. A single hour of audio transcribed through a commercial API every day adds up to a meaningful annual bill, and for teams operating under GDPR or HIPAA, shipping raw audio off-device can require contracts, audits, and legal review before a single line of integration code is written.
Open source speech to text removes those constraints. You download the model once, run it wherever your infrastructure lives, and pay nothing per minute. The trade-off is that you now own the inference cost, the deployment complexity, and the accuracy-versus-latency decision. This article walks through the major engines as of 2026, compares their benchmarks, maps deployment patterns from a laptop to a Kubernetes cluster to a Raspberry Pi, and gives you a decision framework for choosing between them.
What Is Open Source Speech-to-Text?
Open source speech to text is defined as automatic speech recognition (ASR) software whose source code and, in most cases, pretrained model weights are published under permissive licenses such as Apache 2.0 or MIT, allowing anyone to run, modify, and redistribute the system without per-minute fees. It differs from proprietary services in that inference happens on hardware you control, whether that is a developer laptop, a GPU server, or an edge device, rather than on a vendor's cloud.
Open-source ASR works by converting raw audio into mel-spectrogram features, feeding those features through a neural encoder-decoder (typically Transformer-based), and decoding the output into text, either autoregressively for accuracy or with streaming decoders for low latency. Most modern engines also expose token-level timestamps, which enable forced alignment, subtitles, and speaker-turn detection.
Three characteristics define the category: free licensing with no per-minute billing, community-driven development on GitHub, and on-device execution that keeps audio private. For developers building apps with embedded communication, this matters because transcription can run colocated with your media server, and VideoSDK users can pair these engines with VideoSDK's real-time transcription and summary features when they want managed transcription alongside self-hosted processing.
Major Open-Source Engines Landscape
The open-source ASR landscape in 2026 is broader and more mature than it was even two years ago. Whisper remains the reference point, but a wave of newer projects has pushed hard on latency, edge deployment, and non-English coverage. The table below summarizes the engines most developers evaluate first.
| Engine | Language Coverage | Model Sizes | License | Hardware Profile |
|---|---|---|---|---|
| Whisper | 90+ languages, translation | Tiny to Large-v3 | MIT | CPU-capable, GPU recommended for large models |
| OpenASR | 100+ languages via catalog | Small to Large | Apache 2.0 | Local-first, CPU and GPU |
| DeepSpeech | English primarily | Single acoustic model | MPL 2.0 | GPU acceleration, older architecture |
| WhisperLiveKit | Whisper-compatible | Uses Whisper models | MIT | GPU for real-time streaming |
| Moonshine | English, expanding | Tiny and Base | MIT | Runs on CPU and edge accelerators |
| Qwen3-ASR | Multilingual, strong Chinese | Multiple checkpoints | Apache 2.0 | GPU recommended |
| PaddleSpeech | Chinese-first, multilingual | Full toolkit range | Apache 2.0 | GPU recommended for full stack |
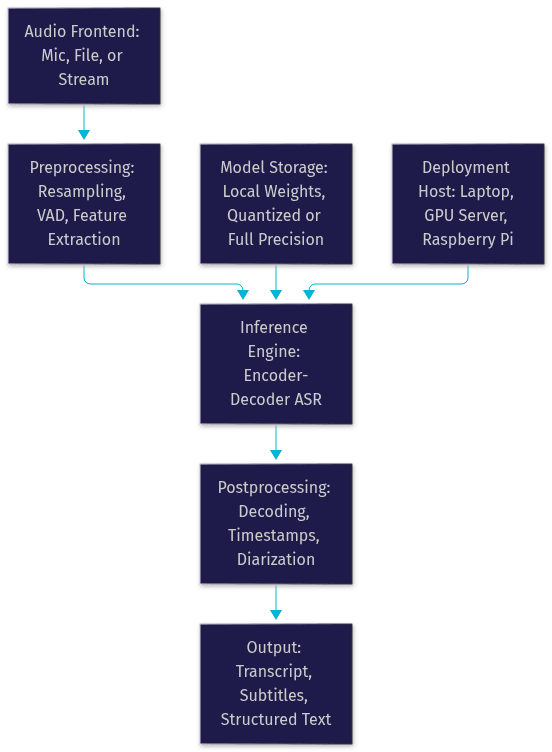
Architecturally, these engines share the same three layers, but they distribute responsibilities differently. The diagram below shows how a frontend captures audio, an inference engine processes it, and model storage feeds the pipeline, with the main variation being whether inference runs locally, on a server, or on an edge accelerator.
Whisper
Whisper, released by OpenAI in 2022 and MIT-licensed, remains the most widely adopted open source speech to text model. Its family spans tiny to large checkpoints, supports more than 90 languages, and includes built-in speech translation into English. Its strengths are multilingual robustness and strong accuracy on noisy, real-world audio, which is why it anchors so many production transcription pipelines. Its weakness is latency: the original architecture processes audio in fixed windows, so real-time use requires streaming wrappers.
OpenASR
OpenASR is a local-first project built around privacy: no telemetry, no cloud calls, and a catalog of downloadable models covering more than 100 languages. Its design goal is that a developer can install it, pick a model, and transcribe entirely offline on commodity hardware. The project also ships an OpenAI-compatible endpoint, which means applications written against the OpenAI transcription API can switch to OpenASR without changing their request logic, a significant lock-in escape hatch.
DeepSpeech
DeepSpeech, originally from Mozilla and later maintained by the community, is a TensorFlow-based engine inspired by Baidu's Deep Speech research. It popularized open-source ASR for a generation of developers and supports GPU acceleration for training and inference. Its architecture is older than modern Transformer models, and English is its primary language, so most new projects in 2026 choose Whisper-family engines instead. It still appears in legacy deployments and remains a useful reference for comparing end-to-end acoustic modeling approaches.
WhisperLiveKit
WhisperLiveKit takes Whisper's weights and wraps them in an ultra-low-latency streaming server, targeting sub-second transcription for live audio. It exposes an OpenAI-compatible API surface, so existing client code often works unchanged. Its sweet spot is live captioning for calls, streams, and events where batch transcription is unacceptable. The trade-off is that real-time streaming inference is GPU-hungry, so plan hardware accordingly.
Moonshine
Moonshine is an edge-optimized engine with tiny and base model variants designed to run fast on CPU-only machines and edge accelerators. Its cross-platform SDKs target environments like Raspberry Pi and mobile-class hardware, where a full Whisper large model would be impractical. Accuracy trails the biggest models on hard audio, but for clean speech and constrained devices, its speed-to-size ratio is among the best in the category.
Qwen3-ASR
Qwen3-ASR pushes state-of-the-art accuracy among open-source ASR models, with particularly strong results on Chinese and multilingual benchmarks. A standout feature is built-in forced alignment, producing word-level timestamps directly from the model, which simplifies subtitle generation and speaker-turn analysis. It is Apache 2.0 licensed and performs best with GPU inference, making it a strong choice for server-side batch pipelines where accuracy matters more than per-minute cost.
PaddleSpeech
PaddleSpeech, from the PaddlePaddle ecosystem, is less a single ASR model and more a full speech toolkit: recognition, synthesis, translation, and speaker tooling in one framework. Its Chinese language support is exceptional, and it covers a wide matrix of other languages. For teams building products where Chinese ASR and TTS must come from one integrated stack, it is often the pragmatic pick. The breadth comes with complexity, so expect a steeper setup curve than a single-purpose engine.
Choosing the Right Engine for Your Project
Engine selection comes down to four axes: accuracy, latency, resource constraints, and language needs. No single engine wins all four, so the honest answer is a conditional one.
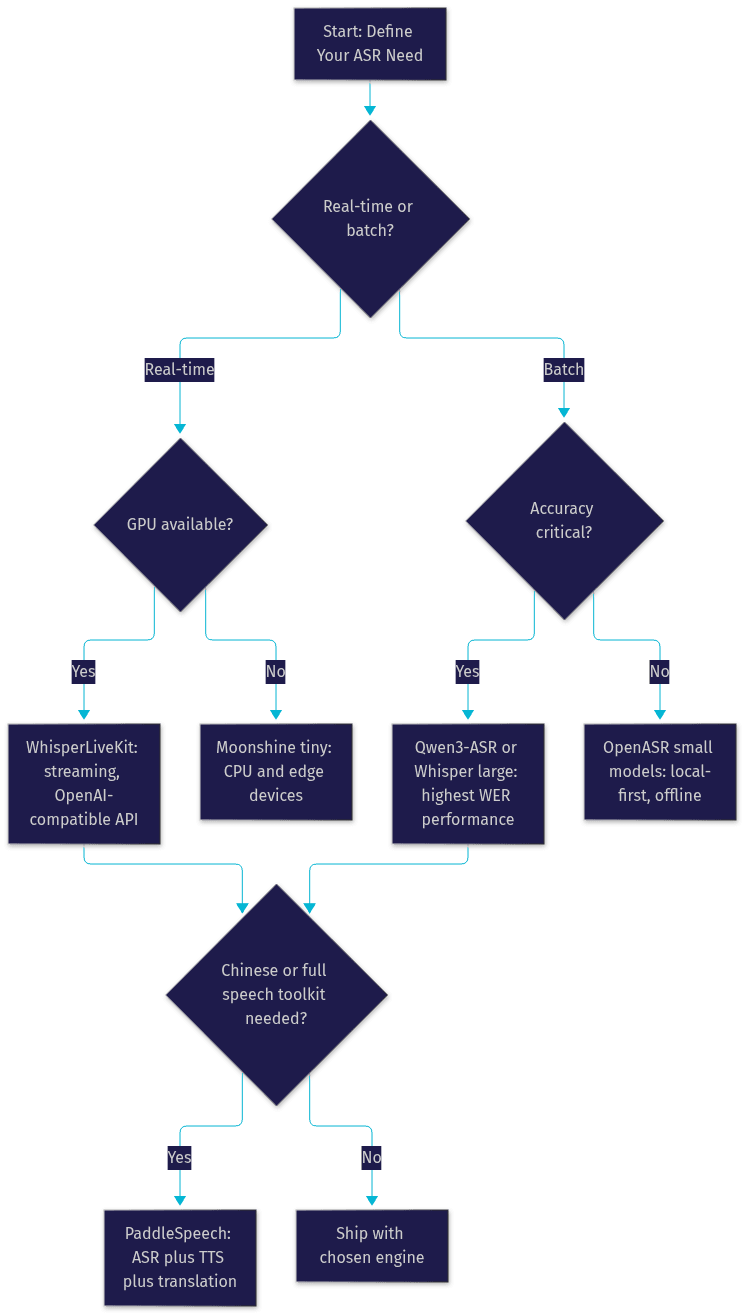
Start with these practical questions. Is your workload batch transcription of recorded files, or live captioning of ongoing audio? Batch work favors accuracy-heavy models like Whisper large or Qwen3-ASR. Live work favors streaming engines like WhisperLiveKit or small Moonshine models. What hardware do you actually have? A GPU server changes your options dramatically compared to a CPU-only box or a Raspberry Pi. Which languages do you need, and do you need translation? Whisper and OpenASR cover the widest matrix. Do you need word-level timestamps or diarization? Qwen3-ASR ships forced alignment natively; others require post-processing. Finally, check licensing: Apache 2.0 and MIT are both permissive, but confirm attribution requirements for any model you redistribute.
The decision tree below visualizes the selection process:
One more consideration: if your application already embeds real-time video or audio calls through a platform like VideoSDK's video calling SDK, check whether its built-in real-time transcription covers your needs before self-hosting an engine, since managed transcription removes the deployment burden entirely.
Deployment Patterns
There are three dominant ways to deploy open source speech to text, and the right one depends on where your audio originates.
The first pattern is on-device, command-line driven transcription. You install the engine locally through a package manager, point it at files or a microphone, and get text out. This suits individual developers, privacy-sensitive workflows, and offline environments. Nothing leaves the machine, which simplifies GDPR and HIPAA conversations because no audio ever crosses a network boundary.
The second pattern is a server-side REST API. You run the engine as a service, either containerized with Docker and orchestrated under Kubernetes for scale, or as a simple long-running process installed via pip or conda for a single server. Containerization gives you reproducible environments, health checks, and horizontal scaling by adding replicas behind a load balancer. This is the pattern to choose when multiple applications or microservices need transcription.
The third pattern is edge deployment on devices like a Raspberry Pi or mobile hardware. Here, model quantization is the key technique: reducing model precision from full floating point to 8-bit integers shrinks memory footprint and speeds inference on devices without GPUs. On Apple platforms, Metal acceleration helps; on Android, NNAPI delegates work to the device's neural engine. Moonshine was designed for exactly this tier.
Security best practices apply across all three patterns. Prefer engines with no telemetry, store audio and transcripts encrypted at rest, scope API tokens narrowly, and keep model files pinned to verified releases. If you expose a transcription endpoint publicly, put authentication in front of it, because an open ASR endpoint is effectively an unauthenticated compute resource.
Example Deployment Flow
Here is a narrative walkthrough of standing up OpenASR as a local service. You install the project locally, which pulls the runtime and its dependencies. On first run, you select a model from the catalog and the weights download once to your machine. You then generate an API token for the local service, which exists purely to prevent other processes on your network from calling your endpoint unauthenticated. Finally, you start the service, and it exposes an OpenAI-compatible transcription endpoint, meaning any client already written to send audio to the OpenAI transcription API can point at your local address instead. You send audio, you receive a JSON transcript with segments and timestamps, and no audio ever leaves your machine. The whole flow typically takes under fifteen minutes from a clean machine to a working, private transcription service.
Performance & Accuracy Benchmarks
Benchmarks for open source speech to text cluster around three metrics: word error rate (WER), latency, and memory footprint. Independent leaderboards, including Artificial Analysis and the Hugging Face Open ASR Leaderboard, provide the most trustworthy comparisons, since vendor-reported numbers tend to use favorable test sets.
The headline findings from recent independent evaluations: Whisper Large-v3 remains near the top of open models on English WER, at roughly 5 percent on clean speech and 8 to 12 percent on noisy, conversational audio. Qwen3-ASR matches or slightly beats it on multilingual sets while offering faster throughput on GPU. Small and tiny models, including Moonshine's variants and Whisper's smaller checkpoints, trade several points of WER for dramatically lower latency and memory, which is exactly the right trade on edge hardware. DeepSpeech trails modern Transformers on accuracy and is best treated as a legacy option.
| Engine / Model | Approx. English WER | Relative Latency | Memory Footprint |
|---|---|---|---|
| Whisper Large-v3 | ~5% clean, 8-12% noisy | High (batch) | ~3 GB GPU |
| Qwen3-ASR | ~4-5% multilingual sets | Medium-high, high throughput | ~2-4 GB GPU |
| Whisper small | ~7-9% | Medium | Under 1 GB |
| Moonshine tiny | ~9-11% | Very low | Under 500 MB, CPU-friendly |
| DeepSpeech | ~10%+ | Medium | Moderate, GPU-assisted |
The trade-off to internalize: accuracy and latency pull in opposite directions. If you are captioning a live event, a sub-second Moonshine or WhisperLiveKit pipeline beats a slightly more accurate batch model. If you are transcribing recorded podcasts for search and archival, Qwen3-ASR or Whisper large wins because nobody is waiting. And if you are building live captions into a video calling product, evaluate whether VideoSDK's real-time transcription already meets your accuracy bar before committing to self-hosted GPU infrastructure.
Community, Support, and Future Roadmap
Every engine in this comparison is developed in the open, and community health is a real selection criterion. Whisper's ecosystem is the largest, with thousands of downstream projects and wrappers. OpenASR and WhisperLiveKit maintain active GitHub repositories with responsive issue trackers. Moonshine and Qwen3-ASR publish regular model updates. Most projects run Discord or Slack channels, and all accept contributions through standard pull-request workflows, with model evaluation contributions being especially welcome.
Looking at the 2026 roadmap across the ecosystem, the visible directions are streaming speaker diarization (identifying who spoke, live rather than post-hoc), multilingual forced alignment, and continued shrinking of edge models. Expect the gap between open-source and commercial ASR accuracy to keep narrowing, which makes the privacy and cost arguments for open source speech to text stronger every quarter.
Definitions Glossary
Word Error Rate (WER): The standard accuracy metric for speech recognition, calculated from substitutions, insertions, and deletions relative to a reference transcript. Lower WER means more accurate transcription.
Forced Alignment: The process of mapping each word in a transcript to a precise timestamp in the source audio. Qwen3-ASR provides this natively, and it is essential for subtitles and speaker-turn analysis.
Speaker Diarization: Segmenting audio by who is speaking, labeling each segment with a speaker identity. It is a common post-processing step after open source speech to text transcription.
Model Quantization: Reducing a model's numeric precision, typically from 32-bit floats to 8-bit integers, to shrink memory use and speed up inference on CPU and edge hardware.
Real-Time Transcription: Converting speech to text with sub-second latency while the audio is still being spoken, as opposed to batch transcription of finished recordings. VideoSDK provides this as a built-in feature for live calls and streams.
Key Takeaways
- Open source speech to text engines now match commercial APIs on accuracy while eliminating per-minute costs and keeping audio fully private on your own hardware.
- Choose Whisper or Qwen3-ASR for batch accuracy, WhisperLiveKit for sub-second live captioning, and Moonshine for CPU-only and edge devices.
- OpenASR's OpenAI-compatible endpoint lets you migrate away from a commercial API without rewriting client code.
- Deployment spans three patterns: local on-device transcription, containerized server-side APIs, and quantized edge models on hardware like the Raspberry Pi.
- If your product already embeds calls or streams, evaluate VideoSDK's built-in real-time transcription before self-hosting GPU inference, since it removes the deployment and scaling burden entirely.
Conclusion
Open source speech to text in 2026 is no longer a compromise. Engines like Whisper, OpenASR, Qwen3-ASR, and Moonshine deliver competitive word error rates, permissive licensing, and deployment flexibility from a laptop to a Kubernetes cluster to a Raspberry Pi. The decision is now conditional rather than categorical: pick the engine that matches your latency budget, hardware, and language matrix, and let privacy and zero per-minute cost come along for the ride. Start by cloning one of the highlighted repositories, running it against your own audio, and measuring WER on your actual data rather than benchmark sets. And if you are building transcription into a live calling or streaming product, explore VideoSDK's real-time transcription and summary features alongside the code samples to see how managed and self-hosted approaches compare. What are you building with open source speech to text? Drop a comment, I'd love to hear which engine and use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ