


The Google Cloud Speech to Text API is a managed speech recognition service that converts audio into text using synchronous, batch, and real-time streaming modes. It supports 100+ languages, specialized models like Chirp and Medical, and features such as speaker diarization and automatic punctuation. Developers can start with a free monthly tier and scale to production workloads, or pair it with VideoSDK for real-time transcription inside live video applications.
Accurate speech-to-text is no longer a nice-to-have. Call centers transcribe thousands of hours of customer calls daily, live streams need captions within seconds, and voice assistants depend on low-latency recognition to feel responsive. Getting transcription wrong at scale means lost analytics, poor accessibility, and frustrated users.
The Google Cloud Speech to Text API is one of the most versatile speech recognition APIs available, offering three operation modes, multiple specialized models, and deep integration with the Google Cloud ecosystem. This guide walks you through setup, model selection, streaming versus batch workflows, cost optimization, and troubleshooting, so you can ship a transcription pipeline that holds up in production.
What Is the Google Cloud Speech to Text API?
The Google Cloud Speech to Text API is defined as a cloud-based speech recognition service that converts audio input into machine-readable text using machine learning models trained on Google's vast audio datasets. It works by accepting audio data through REST or gRPC endpoints, routing it to a recognition model, and returning a transcript with confidence scores, timing metadata, and optional features like speaker diarization.
The API offers three operation modes. Synchronous recognition processes short audio clips (under a minute) and returns results in a single response. Asynchronous batch recognition handles longer recordings, such as meetings or call archives, returning results once processing completes. Streaming recognition accepts a continuous bidirectional audio stream and returns partial transcripts in real time, which is what live captioning and voice assistants rely on.
Google provides several recognition model variants, including the default model for general audio, Chirp for improved multilingual accuracy, and specialized models tuned for phone call audio, medical dictation, and video content. The service supports more than 100 languages and dialects, with automatic punctuation and word-level timestamps available on most models.
Setting Up Your Google Cloud Project
Before you can send a single audio request, you need a Google Cloud project with the Speech-to-Text API enabled, billing activated, and service account credentials configured. Most setup failures trace back to one of these three steps being incomplete.
Enabling the API and Billing
Start by creating a new project in the Google Cloud Console or selecting an existing one. From the API library, enable the Speech-to-Text API for that project. Billing must be active on the project even if you plan to stay within the free tier, because Google gates API access behind a linked billing account. Once enabled, the API appears in your project's enabled services list, and you can verify access through the console's testing interface.
Creating Service Account Credentials
Google Cloud uses service accounts for application authentication rather than personal user credentials. Create a service account in the IAM section, assign it a descriptive name tied to its purpose, and generate a JSON key file for that account. Download the key and store it securely, ideally in a secrets manager rather than in your repository. Treat this key like a password: anyone holding it can make billable API calls under your project.
Configuring Authentication for Your Application
The standard approach is to point the GOOGLEAPPLICATIONCREDENTIALS environment variable at your downloaded JSON key file. Google's client libraries detect this variable automatically and use it to authenticate requests without any manual token handling in your code. For production workloads, consider attaching the service account directly to your compute resources, such as Cloud Run or Compute Engine, which removes the need to manage key files entirely.
On the IAM side, the service account needs the Service Usage Consumer role at minimum to call the API. If you hit 401 or permission errors during setup, an missing IAM role is the most common culprit. You can find detailed authentication guidance in the Google Cloud authentication documentation.
Choosing the Right Recognition Model
Model selection is the single biggest lever for both accuracy and cost. The default model handles general-purpose audio reasonably well, but specialized models can dramatically improve results for their target domain.
Chirp is Google's newer multilingual model, designed for better accuracy across a wide range of languages and acoustic conditions. The phone call model is optimized for narrowband 8kHz telephony audio, which is why it outperforms the default model on call center recordings. The medical model handles clinical dictation and terminology, and the video model suits captioning recorded media with background music or effects.
A practical rule: match the model to the audio's source, not its content. A customer service call should use the phone call model regardless of what is discussed. Long-form audio, like lectures or podcasts, benefits from long-form recognition settings that maintain context across minutes of speech, while short clips work fine with standard recognition.
Model choice also affects pricing, with premium models like Chirp and Medical carrying higher per-minute rates than the default model. Running a quick accuracy comparison on a sample of your real audio before committing to a model across your whole pipeline is a step most teams skip and later regret.
Request Flow Architecture
Every request to the Speech to Text API follows the same high-level flow: your application authenticates using service account credentials, submits audio data or a Cloud Storage reference, the API routes the audio to the appropriate recognition model, and results return as structured text with metadata.
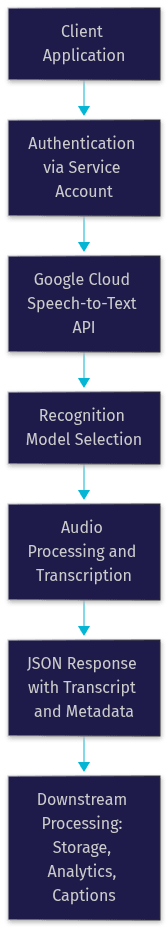
For batch workloads, the flow typically includes an intermediate step where audio is uploaded to Cloud Storage first, and the request references the storage location rather than embedding audio bytes directly. This keeps request payloads small and lets the API handle files far larger than inline limits.
For streaming workloads, the connection stays open: the client sends audio chunks over a bidirectional gRPC stream, and the server returns interim results as speech is recognized, converging on a final transcript once the utterance completes. Understanding this distinction early prevents the most common architectural mistake, which is trying to fake real-time behavior by repeatedly calling the synchronous endpoint.
Synchronous (Batch) Transcription
Batch mode is the right choice when latency does not matter: transcribing archived calls, processing uploaded media files, or generating transcripts for analytics pipelines. You submit audio, wait, and receive complete results.
The typical workflow has three stages. First, upload your audio file to Cloud Storage, which handles files of essentially any size and keeps your API request lightweight. Second, construct a recognition request that specifies the audio's storage location, its encoding format (such as LINEAR16, FLAC, or MP3), the sample rate, and the language. Third, submit the request through the REST endpoint and poll for completion, since long audio processing is asynchronous.
One detail that trips up new users: the encoding and sample rate you declare must match the actual audio. Declaring the wrong sample rate produces garbled or empty transcripts rather than an error, which makes it frustrating to diagnose. If your audio's format is uncertain, tools that inspect file headers before submission save significant debugging time.
Results arrive as structured JSON containing the full transcript, word-level timing, and confidence scores. For very large backlogs, Google's integration with Pub/Sub and Dataflow lets you build pipelines that process transcription jobs concurrently and land results in BigQuery for analysis.
Real-Time Streaming Transcription
Streaming recognition is what powers live experiences: voice assistants, live event captioning, real-time meeting notes, and moderation of live audio. Instead of waiting for complete audio, the client streams audio chunks and receives interim transcripts within fractions of a second.
Streaming uses gRPC's bidirectional streaming capability rather than simple REST calls. Your application opens a stream, continuously sends audio frames, and receives interim results that refine as more context arrives. The final result for each utterance arrives once the system detects a pause or end of speech. This is the same fundamental pattern used by production voice interfaces, and it is the pattern VideoSDK uses for real-time transcription inside live video sessions.
There is one hard constraint to plan around: a single streaming session is limited to approximately five minutes of audio. Long-running applications must implement a reconnection strategy, where the client closes the stream before the limit, opens a new one, and continues sending audio without dropping content. Designing this from the start is far easier than retrofitting it.
For developers building live video applications, pairing a streaming transcription service with a real-time communication SDK gives you both the media transport and the transcription layer. VideoSDK's video calling SDKs support real-time transcription natively, which removes the need to wire a separate streaming pipeline for in-call captions.
Managing Costs and Optimizing Pricing
Google prices Speech to Text per minute of audio processed, with rates varying by model. The default model carries the lowest rate, while Chirp, Medical, and other specialized models cost more per minute. Google offers a free monthly allotment for the standard model, which is enough for prototyping and small projects, and volume discounts apply at enterprise scale. Check the official pricing page for current rates, since they change periodically.
Cost optimization starts with model discipline: use premium models only where their accuracy gain justifies the premium. Pre-processing audio to remove silence and non-speech segments can cut billable minutes significantly for archives with dead air. Choosing efficient audio encodings, like FLAC, reduces payload size and transfer costs for batch workloads without quality loss.
Set up budget alerts in Cloud Billing before you launch, so a runaway loop or a misconfigured batch job notifies you at a threshold rather than on your invoice. Cloud Monitoring dashboards for API usage make anomalies visible early. Teams running transcription at scale consistently find that a simple usage dashboard pays for itself the first time it catches a retry storm.
Common Pitfalls and Troubleshooting
Most production issues with the Speech to Text API fall into four categories, and each has a straightforward fix once diagnosed.
Authentication failures show up as 401 errors or messages about missing credentials. The cause is almost always one of three things: the GOOGLEAPPLICATIONCREDENTIALS variable pointing to a stale or missing key file, the service account lacking the required IAM role, or the key belonging to a different project than the one where the API is enabled. Verify each link in that chain in order.
Quota errors appear when you exceed request or concurrent-stream limits. You can request quota increases through the console, but plan ahead, since increases are not always instant. For batch workloads, implementing client-side throttling and exponential backoff on retry prevents a single surge from cascading into failures.
Audio format mismatches produce garbled output rather than errors. If transcripts look like nonsense, check that the declared encoding and sample rate match the actual file. This is the most common cause of "the API is broken" support tickets.
Noisy environments degrade accuracy across every model. The phone call model handles telephony noise best, and enabling speaker diarization helps when overlapping speech confuses attribution. For very noisy audio, pre-processing with noise reduction before submission often improves accuracy more than switching models.
Security, Compliance, and Data Privacy
Google Cloud Speech to Text is covered under Google Cloud's compliance framework, which includes HIPAA support (under a Business Associate Agreement), ISO 27001, and SOC 2 certifications. For healthcare and regulated workloads, confirm your project is configured within compliance scope before processing patient audio.
Data residency matters for organizations with regional requirements. Google offers regional endpoints that keep processing within specific geographies, and you can restrict API access to regional resources through project configuration. Review Google's data retention terms for the API: by default, Google states that audio data submitted to the API is not used to improve their models, but verify current terms in the official documentation for your compliance scenario.
For sensitive audio, best practices include encrypting audio at rest in Cloud Storage with customer-managed keys, scoping service accounts narrowly, and logging all API access through Cloud Audit Logs.
Alternatives and When to Consider Other Services
The Speech to Text API is not the only strong option, and honest comparison beats defaulting to one vendor.
AWS Transcribe integrates naturally if your stack already lives in AWS, and offers solid speaker diarization and call analytics. Azure Speech is competitive on language coverage and shines if your organization is Microsoft-centric. Deepgram has earned attention for fast, accurate streaming transcription using end-to-end deep learning models, and frequently appears near the top of independent speech benchmarks.
Decision factors worth weighing: language coverage for your specific locales, streaming latency for live use cases, per-minute pricing at your volume, and ecosystem gravity. If your infrastructure is already on Google Cloud, the operational simplicity of staying there often outweighs marginal accuracy differences. If raw streaming latency is your top priority, benchmark Deepgram and Google's Chirp model against your own audio before deciding.
For developers building live video and voice applications, VideoSDK's AI agent infrastructure supports multiple STT providers behind a single integration, which lets you swap or compare providers without rebuilding your pipeline.
Quick Recap and Next Steps
You now have the full picture of the Google Cloud Speech to Text API: how to set up a project with service account authentication, how to choose between the default, Chirp, phone call, medical, and video models, when to use batch versus streaming recognition, and how to keep costs and troubleshooting under control.
The best next step is practical: enable the API, grab the free tier, and transcribe a real sample of your own audio. Compare the default model against a specialized model on that sample, and let accuracy data drive your architecture. Then explore the official Speech-to-Text documentation and client libraries for your language of choice.
Further Reading
- Google Cloud Speech-to-Text documentation
- Speech-to-Text pricing
- Chirp model guide
- VideoSDK real-time transcription and AI agents
- VideoSDK code samples
Definitions Glossary
Speech recognition API: A service that converts spoken audio into text using machine learning models, typically offered over REST or gRPC endpoints with per-minute pricing.
Streaming recognition: A transcription mode where audio is sent continuously over a bidirectional connection and interim results return in real time, suited for live captioning and voice assistants.
Batch transcription: An asynchronous mode where complete audio files are submitted for processing and results are retrieved once the job finishes, suited for archives and analytics.
Speaker diarization: A feature that separates a transcript by speaker, attributing each segment of speech to a distinct participant in the conversation.
Service account: A Google Cloud identity used by applications for authentication, configured through a JSON key file or attached directly to compute resources.
Chirp model: Google's newer multilingual recognition model designed for improved accuracy across many languages and acoustic conditions.
Key Takeaways
- The Google Cloud Speech to Text API supports synchronous, batch, and streaming recognition modes, covering everything from archived call transcription to live captioning.
- Model selection is the biggest accuracy and cost lever: match the model to the audio source, such as the phone call model for telephony audio.
- Streaming sessions are limited to roughly five minutes, so long-running live applications need a reconnection strategy designed in from the start.
- Declared audio encoding and sample rate must match the actual file, since mismatches produce garbled output rather than errors.
- For live video applications, VideoSDK provides real-time transcription natively alongside its video calling SDKs, removing the need to build a separate streaming pipeline.
Conclusion
The Google Cloud Speech to Text API remains one of the most capable speech recognition services for developers, combining flexible operation modes, specialized models, and the reliability of Google Cloud's compliance and security posture. The gap between a mediocre integration and a great one comes down to the details covered here: correct model selection, honest audio format handling, streaming reconnection logic, and cost monitoring from day one.
If you are building live video or voice applications and want transcription built directly into your real-time pipeline, explore VideoSDK's documentation and try the free tier at app.videosdk.live. What are you building with the Google Cloud Speech to Text API? Drop a comment, I'd love to hear what kind of transcription use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ