


Socket.IO polling is the HTTP long-polling transport that Socket.IO uses as a fallback when a WebSocket connection cannot be established or maintained. The client repeatedly sends HTTP GET requests that the server holds open until data is available, and sends data back with separate POST requests. Every Socket.IO connection actually starts with polling and then upgrades to WebSocket when the network allows it, which is why understanding this transport matters even if you never intend to use it deliberately. If you are building production real-time features, pairing Socket.IO with a managed real-time communication platform like VideoSDK removes much of the transport-level guesswork entirely.
Real-time communication is the backbone of chat apps, live dashboards, collaborative editors, and multiplayer experiences. Developers reaching for Socket.IO usually want one thing: a persistent, low-latency connection between browser and server. But the web was not originally built for that. Corporate firewalls, antivirus software, older proxies, and restrictive mobile carriers routinely block or degrade raw WebSocket connections.
This is exactly why Socket.IO ships with a polling fallback baked into its Engine.IO layer. Instead of failing when WebSockets are unavailable, the connection silently degrades to HTTP long-polling and keeps working. That resilience is a genuine engineering win, but it comes with real trade-offs in latency, bandwidth, and server load that many teams discover only after their user base grows.
By the end of this article you will understand what Socket.IO polling actually is, when and why it activates, how it works at the protocol level, what it costs you in performance, and how to configure, monitor, and debug it. You will also see where a managed real-time platform like VideoSDK fits in when you want sub-second delivery without managing transports yourself.
What Is Socket.IO Polling?
Socket.IO polling is defined as the HTTP long-polling transport used by Socket.IO's underlying Engine.IO protocol when a direct WebSocket connection is not possible. Instead of keeping a single bidirectional channel open, the client continuously issues HTTP requests to the server, and the server deliberately delays its response until it has data to deliver.
Socket.IO polling works by splitting communication into two separate HTTP request types. Receiving data happens through repeated GET requests that the server holds open for up to roughly 25 seconds, waiting for new events. Sending data happens through POST requests that carry the client's outgoing messages and receive a quick acknowledgement. This request/response pattern mimics a persistent connection using nothing but plain HTTP, which is why it survives almost every network environment.
What makes this interesting is that polling is not an emergency-only path in Socket.IO. The Engine.IO handshake always begins over polling, even on networks that fully support WebSockets. Once the handshake completes and the server confirms WebSocket support, the client attempts a live upgrade to the WebSocket transport. If that upgrade succeeds, polling stops. If it fails, the connection simply stays on polling, and the application keeps functioning as if nothing happened.
This design decision is deliberate. Starting on polling guarantees the connection works everywhere, then upgrading opportunistically gives you the best available transport without requiring the developer to write any conditional logic. The trade-off is that you inherit polling behavior whether you planned for it or not, which is why the rest of this article focuses on recognizing, measuring, and controlling it.
When Does Socket.IO Use Polling?
Socket.IO falls back to polling whenever the WebSocket transport fails to connect, fails mid-session, or is explicitly disabled. Understanding the trigger conditions helps you predict which users will end up on the slower transport.
The most common trigger is network infrastructure. Corporate proxies and firewalls that only allow standard HTTP traffic will strip or block WebSocket upgrade requests. Some antivirus and endpoint security products inspect and terminate WebSocket frames. Certain mobile carriers and captive portal networks behave the same way. In these environments, the WebSocket handshake simply never completes, and Engine.IO quietly keeps the session on polling.
The second trigger is browser or runtime support. Modern browsers have supported WebSockets for over a decade, so this is rare today, but embedded browsers, older webviews in native apps, and some IoT runtimes still lack full WebSocket support. Socket.IO detects this during the handshake and skips the upgrade attempt entirely.
The third trigger is developer configuration. Socket.IO lets you restrict the allowed transports on both the client and the server, so you can force polling-only mode for testing, or disable polling to require WebSockets. Disabling polling is tempting for performance, but it means users behind hostile networks lose connectivity completely, so treat that as a deliberate product decision rather than a default.
The decision flow below shows how Engine.IO chooses a transport:
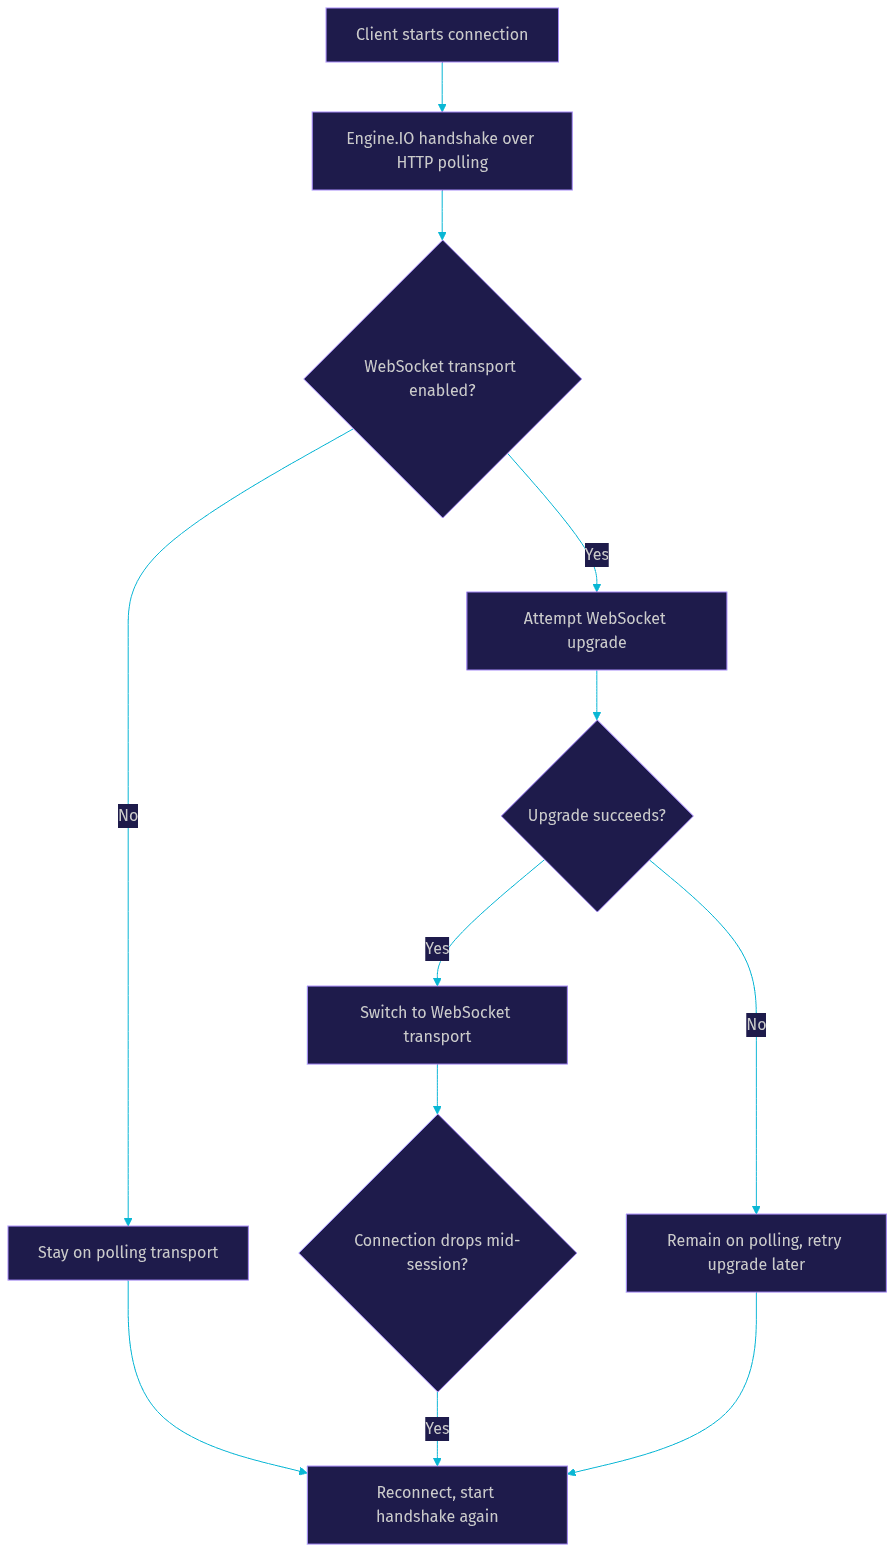
A practical pattern in production deployments is to keep polling enabled as a safety net while monitoring what fraction of your users actually rely on it. If that fraction is near zero, you can consider tightening transport requirements. If it is meaningful, polling is doing real work for you.
How Polling Works Internally
Under the hood, Socket.IO polling is a carefully choreographed cycle of GET and POST requests coordinated through session identifiers and heartbeats. Knowing this cycle makes debugging dramatically easier.
When a client first connects, the server issues a session identifier as part of the Engine.IO handshake. Every subsequent poll request carries this identifier so the server can associate the request with the correct long-lived session. This is also why polling sessions are sensitive to load balancer behavior: if consecutive requests from the same session land on different servers without sticky routing, the session breaks.
Receiving data works through a held GET request. The client asks the server for new events, and instead of responding immediately with an empty result, the server parks the request. The moment an event destined for that client arrives, the server completes the response with the payload. If nothing arrives within the polling timeout window, the server responds with an empty payload, and the client immediately issues a fresh GET. This creates the characteristic request loop of long-polling.
Sending data works through POST requests. When the client emits an event, it packages the message into a POST body and sends it to the server. The server processes the message and returns a small acknowledgement. Notably, the POST response is not used to deliver server-to-client data; that job belongs exclusively to the held GET request. This separation is what allows the transport to be half-duplex yet still feel responsive.
The heartbeat mechanism keeps dead sessions from accumulating. The server periodically sends ping packets through the active transport, and the client is expected to respond with pong packets. If a client stops responding within the configured timeout window, the server considers the session dead and releases its resources. On polling, these control packets travel through the same GET and POST cycle as regular data.
The full cycle looks like this:
One consequence of this design deserves emphasis: a polling client is always making requests, even when idle. A WebSocket client sitting quietly consumes almost no bandwidth. A polling client generates a constant stream of HTTP requests, headers included, whether or not anything is happening. That difference compounds quickly at scale.
Performance Implications: Polling vs WebSocket
Polling costs more than WebSocket on every axis that matters for real-time systems: latency, bandwidth, overhead, and server capacity. The gap is not subtle.
Latency is the most visible difference. On WebSocket, a message travels over an already-open connection, so delivery latency is essentially network round-trip time. On polling, server-to-client delivery can be nearly instant if a GET request happens to be held open at the right moment, but client-to-server messages wait for a POST cycle, and any message arriving between polls waits for the next GET. In practice, effective latency on polling is typically tens to hundreds of milliseconds higher, and worst-case latency is bounded by the polling interval rather than the network.
Bandwidth is the second cost. Every poll request carries full HTTP headers, and every response does too. A mostly idle polling session still exchanges a continuous stream of these request/response pairs, while an idle WebSocket session exchanges only occasional heartbeat frames. At thousands of concurrent connections, header overhead alone becomes a measurable fraction of total traffic.
Server load is the third cost. Each polling client keeps an open HTTP request on the server at all times, plus issues new requests every few seconds. This consumes file descriptors, memory for held requests, and CPU for request parsing that a WebSocket connection simply does not require.
| Metric | HTTP Long-Polling | WebSocket |
|---|---|---|
| Typical delivery latency | Higher, bounded by poll cycle | Near network round-trip time |
| Idle bandwidth usage | Constant request/response overhead | Minimal heartbeat frames only |
| HTTP header overhead | On every request and response | Once, during the upgrade |
| Server resource usage | Held requests plus frequent parsing | Lightweight persistent connections |
| Proxy and firewall compatibility | Excellent, plain HTTP | Good, occasionally blocked |
| Connection resilience | Very high | Can drop on hostile networks |
| Best for | Maximum compatibility, restrictive networks | Low-latency real-time features |
The honest summary is that polling wins only on compatibility. If your users are on clean networks, WebSocket is better in every measurable way. If a meaningful share of your users sit behind restrictive proxies, polling is the difference between a working app and support tickets.
This is also why teams building latency-sensitive features like live audio and video often skip the transport problem entirely and use a managed real-time communication platform. VideoSDK, for example, handles media transport, reconnection, and network adaptation across its video calling SDK, so the polling-versus-WebSocket question never reaches your application code.
Configuring and Testing Polling
Socket.IO exposes transport configuration on both the client and the server, and understanding these options lets you control exactly when polling is used.
On the client side, you can restrict the transports the connection is allowed to use. Forcing polling-only mode is useful when reproducing bugs that only appear on restricted networks, or when deploying into an environment known to block WebSockets. Conversely, you can list WebSocket as the only allowed transport, which guarantees you never silently fall back, at the cost of losing users on hostile networks. The default behavior, allowing both with polling first, is the right choice for most applications.
On the server side, you can similarly restrict supported transports, and you can tune the parameters that govern polling behavior. The ping interval and ping timeout settings control how quickly dead sessions are detected. The maximum HTTP buffer size limits how much data a single POST can carry, which matters if your client emits large payloads. Connection and request timeouts determine how long the server holds a poll before responding empty.
Testing polling behavior requires observing the network, and browser developer tools make this straightforward. Open the network tab, filter for requests to your Socket.IO endpoint, and watch the request pattern. A polling session shows a repeating sequence of GET requests with long wait times, each followed by a new GET, plus POST requests whenever the client emits events. A session that upgraded to WebSocket shows a single connection entry with the WebSocket protocol, and the request list goes quiet.
A practical testing workflow looks like this: connect with default settings and confirm the upgrade happens on your normal network. Then force polling-only mode and repeat your application's critical flows, watching for latency-sensitive features that degrade unacceptably. Finally, simulate hostile conditions, such as a proxy that strips upgrade headers, and verify the fallback engages cleanly without errors surfacing to users.
For teams that need guaranteed low latency without this testing burden, platforms like VideoSDK abstract the entire transport layer. Their interactive live streaming and calling products handle network adaptation automatically, adjusting bitrate and transport behavior to connection quality in real time.
Best Practices and Production Tips
Production Socket.IO deployments live or die by a handful of operational decisions around transports, timeouts, and scaling.
Keep polling enabled as a fallback unless you have data proving your users never need it. Disabling polling feels like a performance optimization, but it converts a degraded experience into a total failure for users behind restrictive networks. The better optimization is ensuring the WebSocket upgrade succeeds quickly for everyone else.
Tune your heartbeat settings to your application's tolerance. Aggressive ping intervals detect dead clients faster and free server resources sooner, but they increase overhead. Relaxed intervals do the opposite. For chat applications, a moderate interval with a timeout a few multiples longer is usually right. For presence-heavy applications where stale sessions cause visible bugs, lean aggressive.
Plan for horizontal scaling from day one. Polling sessions require sticky routing at the load balancer because each session's requests must reach the same server, identified by the session identifier from the handshake. WebSocket connections also benefit from sticky routing during the upgrade phase. If you run multiple Socket.IO servers, pair them with a sticky load balancer and the Socket.IO adapter for your preferred pub/sub backend so events reach clients regardless of which server holds their session.
Monitor your transport mix. Instrument the server to log which transport each connection settles on, and track the percentage of polling sessions over time. A sudden spike in polling share often signals a network change, a misconfigured proxy, or an infrastructure regression, and catching it early turns a mystery outage into a quick fix.
Finally, know when to stop managing transports yourself. If your real-time needs have grown into audio, video, or large-scale streaming, a purpose-built platform is usually the better engineering decision. VideoSDK's Prebuilt UI Kit can embed a full calling experience with no transport code at all, and its REST APIs handle room and participant management server-side.
Common Pitfalls and Debugging
Even with solid configuration, polling-specific problems show up repeatedly in production. Recognizing their signatures saves hours.
The most notorious is overlapping poll requests. The polling protocol expects the client to have exactly one outstanding GET request at a time. If a second GET fires while the first is still held, the server responds to it with an error status, and the client must recover. This usually appears when the page opens multiple Socket.IO connections unintentionally, when a framework's hot reload duplicates clients during development, or when custom retry logic races with the library's own reconnection. The fix is almost always to eliminate the duplicate connection rather than to suppress the error.
The second classic is the unexpected 400 response on a poll request. This typically means the session identifier attached to the request is no longer valid, because the server restarted, the load balancer routed the request to a different node without sticky sessions, or the session already timed out. The client will usually recover by re-handshaking, but frequent occurrences point to an infrastructure problem, most commonly missing sticky routing behind a multi-server deployment.
The third is silent transport mismatch between client and server. If the server is configured to allow only WebSocket while the client allows both, or vice versa, connections fail in ways that look like generic network errors. Always verify that transport configuration is consistent on both ends when debugging connection failures.
A fourth pitfall is assuming a connection is on WebSocket when it is actually on polling. Latency complaints that make no sense on paper often turn out to be users on the fallback transport. Check the network tab or the connection metadata before optimizing anything else.
For systematic debugging, work through the layers in order: confirm the client connects at all, identify which transport the session settled on, verify session identifiers are consistent across requests, and check that your load balancer preserves them. Most polling mysteries resolve at one of those four layers.
Definitions Glossary
Socket.IO polling: The HTTP long-polling transport used by Socket.IO when WebSocket is unavailable, where the client repeatedly issues GET requests that the server holds open until data arrives.
Engine.IO: The lower-level transport protocol inside Socket.IO that manages the handshake, session identifiers, heartbeats, and the upgrade from polling to WebSocket.
HTTP long-polling: A technique where the server deliberately delays its response to a client request until new data is available, simulating push delivery over plain HTTP.
WebSocket upgrade: The process by which an established HTTP connection negotiates a switch to the persistent, bidirectional WebSocket protocol within the same TCP connection.
Session identifier: The token issued during the Engine.IO handshake that ties every subsequent poll request to a specific long-lived connection on the server.
Sticky routing: A load balancer configuration that ensures all requests from the same client session reach the same server, required for polling sessions in multi-server deployments.
Key Takeaways
- Socket.IO polling is the HTTP long-polling fallback transport that keeps real-time features working when WebSocket connections are blocked by proxies, firewalls, or unsupported runtimes.
- Every Socket.IO connection begins on polling and upgrades to WebSocket opportunistically, so polling behavior is present in your system whether you planned for it or not.
- Polling costs more than WebSocket in latency, bandwidth, and server load, with constant HTTP request overhead even on idle connections, so it should be a fallback rather than a default choice.
- Multi-server Socket.IO deployments require sticky routing because polling sessions depend on their session identifier reaching the same server on every request.
- For latency-critical real-time features like audio and video, managed platforms such as VideoSDK handle transport, reconnection, and network adaptation so you never debug polling fallbacks in production.
Conclusion
Socket.IO polling is not a relic or a bug, it is the compatibility layer that makes real-time features survive the messy reality of corporate networks and restrictive proxies. The engineers who run Socket.IO in production successfully are the ones who know which transport their users are actually on, keep polling enabled as a safety net, and tune timeouts and scaling to match. Test both transports deliberately, monitor your transport mix, and debug from the client outward through transport, session, and infrastructure layers. And when your real-time ambitions grow beyond chat into audio and video, explore VideoSDK's documentation or grab the free tier at app.videosdk.live to see how a managed real-time platform handles the transport problem for you. What are you building with real-time communication? Drop a comment, I'd love to hear what kind of Socket.IO use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ