


Speech latency is the measurable delay between the intent to speak and the first audible sound, or between a prompt and the first spoken response. In humans it reflects cortical planning and motor execution measured in milliseconds; in voice AI it is the end-to-end delay from user speech to machine audio, dominated by speech-to-text, language model inference, and text-to-speech stages. Engineers targeting natural conversation should aim for a total response gap near the human turn-taking benchmark of roughly 200 milliseconds, a budget VideoSDK's real-time voice agent pipeline is designed to help you hit docs.videosdk.live/ai_agents/introduction.
A neurosurgeon stimulating a patient's cortex mid-tumor-resection measures it in milliseconds. A psychiatrist tracking a patient's response pauses measures it in seconds. And a voice AI engineer staring at a latency dashboard measures it in milliseconds again, but for an entirely different reason. Speech latency sits at the intersection of neuroscience, clinical diagnostics, and real-time systems engineering, and the same word means something different in each room.
In plain terms, speech latency is the delay between a trigger and the first sound of speech. That trigger can be a thought, a question, a cue, or an audio prompt. What makes the concept powerful is that it is quantifiable, comparable, and increasingly automatable to measure.
This article covers speech latency through three lenses: the brain mechanisms that produce it, its emerging role as a clinical biomarker in psychiatry and neurology, and the engineering discipline of shrinking it in real-time voice AI pipelines. By the end, you will understand how a 200 millisecond conversational gap connects cortical motor planning to your voice agent's time-to-first-audio.
What Is Speech Latency?
Speech latency is defined as the elapsed time between a triggering event and the onset of speech, typically measured in milliseconds. In behavioral experiments it is the interval between a go-cue and the first phonated sound. In conversation it is the turn-taking gap between one speaker finishing and the next beginning. In voice AI it is the delay between the end of a user's utterance and the first audio sample the system plays back.
It helps to separate three flavors. Neural latency is the time cortical areas take to plan and initiate a motor program, often under 200 milliseconds in healthy adults. Behavioral latency is the observable response delay, which includes neural processing plus decision and attention time. System latency is the engineered delay in a machine pipeline, the sum of every processing and transport stage. All three are measured in the same units, which is exactly why insights transfer between the lab and the engineering team.
Neural Foundations of Speech Latency
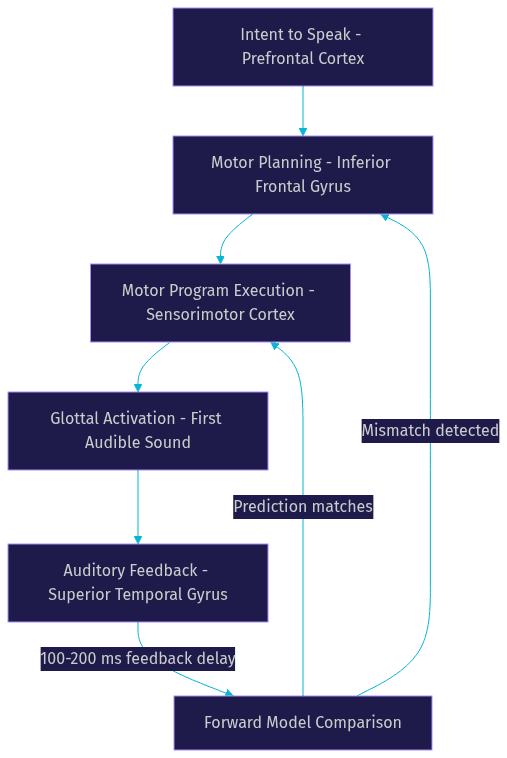
Speech production is a distributed cortical computation, and speech latency emerges from how quickly that network coordinates. Three regions do most of the work: the inferior frontal gyrus (Broca's area), which assembles the motor plan for words; the superior temporal gyrus (Wernicke's area), which maps sound to meaning and supports auditory monitoring; and the sensorimotor cortex, which executes the fine oropharyngeal and laryngeal movements that produce sound.
Direct cortical stimulation studies during awake neurosurgery reveal a striking dissociation between planning and execution. When surgeons stimulate the inferior frontal gyrus, patients often experience speech arrest, a complete pause in ongoing speech that resolves the instant stimulation stops. When stimulation hits ventral sensorimotor sites, the result is instead a distortion or slurring of articulation. The implication for latency research is that planning-stage disruption produces long pauses, while execution-stage disruption produces corrupted but timely speech. In other words, where the delay originates tells you which subsystem is responsible.
Motor control adds a second layer: feedback delay. The brain monitors its own speech through auditory feedback, but that loop carries a transmission delay of roughly 100 to 200 milliseconds. The motor system compensates by running an internal forward model, predicting the sound of an utterance before it arrives. When the prediction and the actual feedback mismatch, as in delayed auditory feedback experiments where a speaker hears their own voice shifted by 200 milliseconds, speech slows and stutters. This is the neurophysiology of speech latency in its purest form: the brain is itself a real-time system fighting a latency budget.
Measuring Speech Latency in the Lab
Measuring speech latency sounds trivial until you try it. The core challenge is defining onset: is it the first glottal pulse, the first audible fricative, or the first full word? Different definitions can shift measurements by 50 to 100 milliseconds, which is often larger than the effect you are studying.
Manual annotation remains the gold standard in small studies. A trained annotator marks the trigger event and the speech onset in a spectrogram, typically in a tool like Praat, and computes the interval. Electroglottography offers a complementary signal by tracking laryngeal contact directly, which catches voicing onsets that a microphone might miss. For larger datasets, automated approaches now dominate: forced aligners and speech-to-text systems like OpenAI Whisper can timestamp word onsets at scale, letting researchers extract response latencies from hours of recorded conversation without manual labeling.
Protocols vary by field. Turn-taking tasks measure the gap between a cue and a subject's verbal response. Picture description tasks measure naming and formulation delay. Bedside language mapping during awake craniotomy measures speech arrest latency under direct cortical stimulation, where the relevant number is how long stimulation must persist before speech stops.
Three sources of error recur across all protocols. Trigger misalignment, where the cue timestamp is off by tens of milliseconds, contaminates every downstream measurement. Onset definition drift between annotators inflates variance, which is why inter-rater reliability checks matter. And preprocessing artifacts, particularly aggressive silence trimming that clips the first consonant, can systematically bias latencies downward. Best practice is to fix an onset definition before data collection, validate automated timestamps against a manually annotated subset, and report both the median and the full distribution, because speech latency data is rarely Gaussian.
Speech Latency as a Clinical Biomarker
Speech latency carries genuine clinical signal, and the last decade of research has made that increasingly hard to ignore. In schizophrenia, studies using structured interview tasks have found that patients show longer and more variable response latencies than controls, with some research linking latency variability to formal thought disorder. In depression, slowed speech onset and longer pauses are part of a broader psychomotor slowing profile, and automated pause analysis has been proposed as an objective marker of severity. In mild cognitive impairment and early Alzheimer's disease, increased hesitation and word-finding delays show up in connected-speech samples years before diagnosis in some cohorts.
The appeal is obvious: speech latency is non-invasive, cheap to capture, and quantifiable from a recorded conversation. Compared with self-report scales, it is harder to fake and faster to administer. Compared with imaging, it costs almost nothing.
The limitations are equally real. Sample sizes in most studies remain small. Latency is sensitive to confounds like medication, fatigue, caffeine, and the testing environment. Diagnostic specificity is weak: a long response pause could indicate depression, cognitive decline, hearing difficulty, or simply a careful speaker. No speech latency threshold has been validated as a standalone diagnostic criterion.
The field's direction is clear, though. Scalable automated extraction, running speech-to-text models over recorded clinical interviews to compute pause distributions and response latencies at population scale, is what would move speech latency from an interesting research variable to a practical screening biomarker. The same measurement infrastructure that voice AI engineers are building for latency monitoring is, almost literally, the tool clinical researchers need.
Voice AI Latency: From Human Speech to Machine Response
When a user speaks to a voice agent, perceived speech latency is the gap between finishing their utterance and hearing the agent's first word. That single perceived number is the sum of a pipeline of stages, and understanding the budget is the core engineering discipline of real-time voice AI.
The pipeline runs in sequence. Voice activity detection (VAD) decides when the user has stopped speaking, and its end-of-speech decision typically costs 50 to 150 milliseconds depending on how aggressively it is tuned. Speech-to-text (STT) transcription adds roughly 100 to 300 milliseconds for a streaming model to produce final text. Language model (LLM) inference is the largest and most variable stage: time-to-first-token ranges from around 150 milliseconds on fast inference providers to well over a second on loaded or distant endpoints. Text-to-speech (TTS) synthesis of the first audio chunk, time-to-first-audio in the synthesis sense, adds 40 to 100 milliseconds on modern streaming TTS engines. Finally, network transport across each hop adds 30 to 300 milliseconds depending on geography and routing.
Time-to-first-audio (TTFA) is the number that matters most: the total elapsed time from end of user speech to the first audible syllable of the agent's response. It is the machine's behavioral speech latency, and users judge the system almost entirely on it. A voice agent with a 700 millisecond TTFA feels sluggish; one near 300 milliseconds feels conversational.
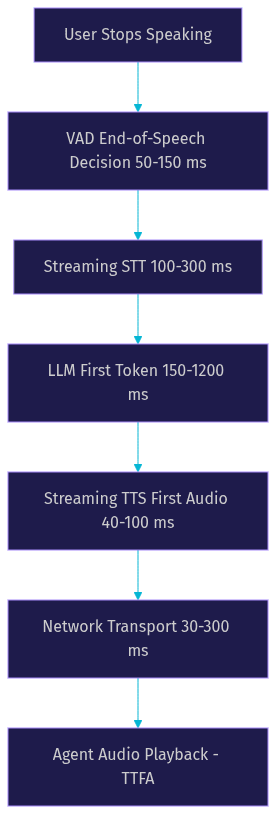
The critical insight is that these stages overlap when engineered well. Streaming STT can emit partial hypotheses while the user is still talking. The LLM can begin generating from a partial transcript. Streaming TTS can synthesize the first sentence while the LLM is still generating the second. A naive sequential pipeline stacks every latency; a well-designed one runs the stages as a cascade where only the first-token path of each stage counts toward TTFA. VideoSDK's AI agent pipeline is built around exactly this streaming architecture, with turn detection, speech-to-text, LLM, and TTS stages orchestrated as a continuous flow rather than a request-response chain docs.videosdk.live/ai_agents/introduction.
Targeting the 200 ms Turn-Taking Benchmark
Human conversation has a remarkably tight rhythm. Research on turn-taking across languages, notably the work of Stivers and colleagues published in the Proceedings of the National Academy of Sciences, found that the median gap between one speaker's turn ending and the next speaker's turn beginning is around 200 milliseconds, consistent across cultures. That number is the benchmark voice AI is implicitly judged against, because users calibrate their expectation of a responsive conversational partner on human behavior.
Hitting a sub-500 millisecond TTFA, let alone 200 milliseconds, requires attacking every stage. Streaming STT eliminates the wait for full utterance transcription. Early token generation, starting LLM inference on partial transcripts, removes the STT-to-LLM handoff from the critical path. Edge or regional inference deployment cuts network round-trip time, which alone can save 100 to 200 milliseconds on cross-continent routes. Local audio buffering on the client side hides transport jitter from the listener.
Every optimization carries a trade-off. Aggressive VAD settings catch fast turn boundaries but produce false end-of-speech detections that cut users off mid-sentence. Starting LLM inference on partial transcripts gains speed but risks responding to an incomplete question. Smaller, faster models reduce first-token latency but can degrade response quality. Latency budgeting is therefore an explicit exercise in deciding where you spend your milliseconds and what accuracy you are willing to trade for each one.
Practical Tips to Reduce Speech Latency in Production
Reducing speech latency in a production voice agent is less about heroic optimization and more about disciplined checklist execution. The teams that consistently hit low TTFA do the following.
Tune VAD per use case. A customer support agent tolerates a longer end-of-speech threshold than a fast-paced game companion. Measure false-cutoff rates and adjust. Cache aggressively: TTS caching for common phrases and greetings, and warm model instances so the first request does not pay cold-start cost. Deploy regionally, placing the agent worker, the STT and TTS providers, and the media infrastructure close to the user, because network round-trip time is often the cheapest latency to eliminate. Handle concurrency explicitly, sizing the inference layer so p99 latency under load stays close to p50, since a system that is fast when idle and slow at peak is a system users experience as slow. Size client buffers small enough to avoid adding perceptible delay but large enough to absorb transport jitter without audio gaps.
Then monitor. Instrument every pipeline stage with timestamps so you can attribute a latency spike to VAD, STT, LLM inference, TTS, or transport, rather than staring at a single end-to-end number. Set alerting on TTFA percentiles, not averages, because a p95 regression is what drives users away even when the mean looks healthy. VideoSDK's agent observability tooling provides exactly this per-stage pipeline visibility, letting teams see where each conversation's milliseconds went docs.videosdk.live/ai_agents/introduction.
Future Directions: Merging Neuroscience and Voice AI
The two halves of this article are converging. Neuroscientists now use speech latency as a window into cortical function; voice AI engineers use it as a product quality metric. The next step is neuro-inspired latency budgeting: using what is known about human motor planning and feedback delays to set realistic, principled targets for machine response timing rather than arbitrary product requirements.
Adaptive turn-taking models are the most active frontier. Current systems use fixed VAD thresholds; research systems increasingly predict when a user is about to finish speaking from prosodic and syntactic cues, the way human listeners do, and begin preparing a response before the turn ends. That is precisely how humans achieve a 200 millisecond gap: they are not faster at generating speech, they start planning earlier. The same trick, anticipatory inference, is the clearest path to voice agents that feel genuinely conversational.
Clinical research feeds this loop too. As automated speech latency extraction scales in psychiatric and neurodegenerative research, the resulting datasets of naturalistic pause distributions will give voice AI designers a far richer picture of human timing norms than any lab study could.
Definitions Glossary
Speech latency: The measurable delay between a triggering event and the onset of speech, expressed in milliseconds, studied in neuroscience, clinical diagnostics, and voice AI engineering.
Time-to-first-audio (TTFA): The total elapsed time from the end of a user's speech to the first audible syllable of a voice agent's response, the primary perceived latency metric in real-time voice AI.
Turn-taking gap: The interval between one speaker finishing and the next beginning, with a cross-cultural human median of roughly 200 milliseconds.
Voice activity detection (VAD): The pipeline stage that decides when a user has started or stopped speaking, whose end-of-speech decision directly adds to response latency.
Speech arrest latency: In cortical stimulation studies, the time between electrical stimulation of a speech region and the observable halt in ongoing speech, used to map critical language areas.
Key Takeaways
- Speech latency is a single measurable quantity that spans cortical motor planning, clinical response timing, and voice AI pipeline engineering, which is why insights transfer across all three domains.
- Human conversation maintains a median turn-taking gap of roughly 200 milliseconds, and this benchmark is the implicit standard users apply when judging whether a voice agent feels responsive.
- In a voice AI pipeline, LLM inference time-to-first-token is the largest and most variable latency stage, ranging from roughly 150 milliseconds to over a second depending on provider and load.
- Streaming architectures that overlap STT, LLM, and TTS stages are the key to low time-to-first-audio, and VideoSDK's AI agent pipeline is built around this cascade model.
- Speech latency shows real clinical signal in schizophrenia, depression, and mild cognitive impairment, but scalable automated extraction is needed before it becomes a practical screening biomarker.
Conclusion
Speech latency is one of the rare concepts that matters equally to a neurosurgeon, a psychiatrist, and a backend engineer. The brain fights a latency budget with forward models and anticipatory planning; clinicians extract diagnostic signal from response pauses; and voice AI teams spend their milliseconds across VAD, STT, LLM, and TTS stages to approach the human 200 millisecond rhythm. If you are building the engineering side of this problem, start with VideoSDK's low-latency voice AI tooling and its streaming agent pipeline at docs.videosdk.live/ai_agents/introduction, or grab a free API key with credits at app.videosdk.live/login. What are you building with real-time voice? Drop a comment, I'd love to hear what kind of speech latency problem you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ