


Voice AI applications are software systems that let users speak naturally and receive intelligent, spoken responses in real time, built by chaining speech-to-text, an LLM or agent, and text-to-speech. VideoSDK provides an open-source AI Agent SDK that connects these pipelines into live rooms, enabling sub-second voice interactions over the web, mobile, or phone. This guide covers the architecture, industry use cases, and technical decisions behind production-grade voice AI applications in 2026.
Introduction
Voice is the fastest interface humans have. In 2026, voice AI applications have moved from novelty demos to production systems handling millions of real conversations: AI phone agents answering support lines, voice tutors coaching language learners, and multilingual intake bots in hospitals. What changed is latency. Once response times dropped below a second, voice stopped feeling like a menu system and started feeling like a conversation.
For developers, this shift matters. Building a voice AI application today means orchestrating speech-to-text providers, large language models, and text-to-speech engines into one responsive pipeline, then delivering it reliably over the network. This article walks through what voice AI applications actually are, where they deliver the most value across industries, and the technical considerations that separate a working prototype from a dependable production system.
What Are Voice AI Applications?
Voice AI applications are defined as software systems that accept human speech as input, interpret it with AI reasoning, and respond with synthesized speech, all within a conversational loop. They differ from older speech technology in a crucial way: traditional IVR and dictation systems transcribe or route words, while voice AI applications understand intent, hold context across turns, and decide what to do next.
A voice assistant that only converts your words to text is speech-to-text. A voice AI application reasons about those words, calls tools when needed, remembers the conversation, and speaks back naturally. That reasoning layer, typically an LLM or a deterministic agent framework, is what makes the category distinct.
VideoSDK provides the real-time communication layer for these systems through its AI Agent SDK, which connects STT, LLM, and TTS providers into live sessions that users can join from a browser, mobile app, or even a regular phone number via SIP telephony.
Core Components of a Voice AI Application
Every voice AI application is built from the same four building blocks. First, a speech-to-text engine converts incoming audio into text, ideally streaming partial results so the system can start reasoning before the user finishes speaking. Second, an LLM or agent brain interprets the transcript, maintains conversation context, and decides on a response or an action. Third, a text-to-speech engine converts the response back into natural-sounding audio. Fourth, optional tool calling lets the agent look up account data, book appointments, or trigger workflows mid-conversation.
The glue holding these together is the real-time session layer. VideoSDK's Agent Worker, a Python process, manages the session lifecycle inside a VideoSDK room, coordinating the pipeline while users connect from any client platform.
Typical Architecture Flow
The end-to-end flow works like this. The user speaks into their device, and audio streams to the agent session. The STT engine produces a live transcript. The LLM evaluates the transcript against conversation history and any business rules, possibly invoking tools. The TTS engine converts the chosen response into speech, which streams back to the user's device for playback. Turn detection runs throughout, deciding when the user has finished speaking and whether the agent should respond or wait.
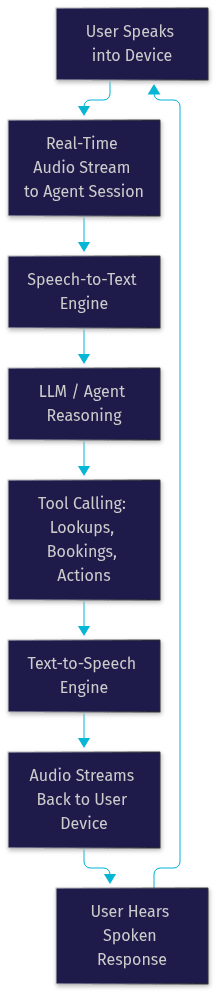
The loop repeats for every conversational turn. When any stage stalls, the user perceives it as an awkward pause, which is why latency engineering dominates the technical agenda.
Key Voice AI Applications Across Industries
Voice AI applications are defined less by the technology and more by the problems they solve. Across sectors, the pattern repeats: replace slow, scripted, or understaffed voice interactions with responsive, context-aware agents. The five sectors below show the breadth of what is shipping in 2026.
Customer Support & Call Centers
AI-driven call centers are the most visible voice AI application today. Instead of navigating a phone tree, callers describe their problem in plain speech and an agent resolves it or routes intelligently to a human. Real-time assistance matters on both sides: the AI handles tier-one queries instantly, while human agents get live transcription and suggested responses for complex escalations.
Barge-in support is essential here. Callers interrupt constantly in natural speech, and an agent that keeps talking over them feels broken. Modern implementations detect interruption mid-sentence, stop TTS playback immediately, and re-process the new input. Sentiment handling adds another layer, letting the system detect frustration and escalate to a human before the caller abandons the call.
Healthcare & Tele-medicine
In healthcare, voice AI applications handle patient intake, collecting symptoms and history through natural conversation before a telemedicine visit begins. Medication reminder agents call patients on schedule, confirm adherence, and flag missed doses to care teams. Multilingual triage is a standout use case: an agent that conducts intake in a patient's preferred language removes a genuine barrier to care.
Compliance shapes everything in this sector. Systems handling protected health information need encryption in transit and at rest, strict access controls, and audit trails, which makes HIPAA-ready infrastructure a hard requirement rather than a nice-to-have.
Finance & Banking
Banks deploy voice AI agents for identity verification and KYC flows, walking customers through document submission and confirmation steps conversationally. Transaction confirmation agents read back payment details and require explicit verbal confirmation before executing, creating a clear audit record. Fraud alert agents call customers the moment suspicious activity is detected, gathering verification faster than SMS loops.
Deterministic behavior is the priority here. A loan application or payment flow must follow every required step in order, which is why structured, graph-driven conversation orchestration matters more than free-form LLM judgment. VideoSDK's Conversational Graph exists precisely for these compliance-driven flows.
Retail, E-commerce & Voice Shopping
Voice shopping lets customers search a catalog by describing what they want, compare options aloud, and place orders entirely through conversation. Live shopping streams add a social layer: a host presents products while a voice AI answers viewer questions in real time about sizing, availability, and shipping, driving conversion during the stream itself.
Upsell happens naturally in this format. Because the agent knows the catalog and the customer's cart, it can suggest complementary items at exactly the right conversational moment, something a static product page cannot do.
Education & Tutoring
Language learning is arguably the perfect voice AI use case: learners need unlimited patient conversation practice with instant correction. Voice tutors conduct spoken practice sessions, evaluate pronunciation, and adjust difficulty on the fly. Beyond languages, tutoring agents explain concepts on demand, answer follow-up questions without breaking pace, and keep learners engaged through dialogue rather than passive reading.
For live classroom scenarios, VideoSDK's interactive live streaming capabilities let tutors run low-latency sessions where AI assistants handle Q&A while the human instructor focuses on teaching.
Technical Considerations for Building Voice AI Applications
The gap between a voice AI demo and a production application is measured in milliseconds, error rates, and edge cases. Four technical areas decide whether your system feels magical or frustrating.
Latency & Real-Time Turn-Taking
Sub-second response time is the benchmark that separates conversational from clunky. Users perceive responses under roughly 800 milliseconds as natural dialogue; beyond that, the interaction starts feeling like waiting. Achieving it requires streaming at every stage: partial STT results, early LLM token generation, and chunked TTS output that starts playing before the full response is synthesized.
Network-adaptive streaming keeps latency stable under real conditions. When bandwidth drops, the system should reduce audio bitrate and resolution automatically rather than stuttering. Turn detection and voice activity detection work together to decide when a user has finished speaking versus merely pausing, and preemptive response handling lets the agent begin replying to predictable phrases before the user fully completes them. VideoSDK's Agent SDK includes turn detection, VAD, and preemptive response handling as built-in pipeline components.
Accuracy & Multilingual Support
Speech-to-text accuracy is usually measured in word error rate, and independent benchmarks are the honest source for comparing providers. Artificial Analysis's Speech Arena and provider-published evaluation sets offer current WER comparisons across engines like Deepgram, OpenAI Whisper, Google STT, and ElevenLabs Scribe. Accuracy varies sharply by domain: medical vocabulary, product names, and accented speech can double error rates compared to clean benchmark audio.
Multilingual support goes beyond language count. Code-switching, where speakers mix languages mid-sentence, is common in real conversations and breaks many STT engines. If your users are global, test with realistic multilingual audio, not just clean single-language samples, and verify that your TTS engine produces natural output in every supported language.
Security, Privacy & Compliance
Voice data is biometric-adjacent and highly sensitive, so security cannot be an afterthought. Encrypt audio in transit and at rest, generate session tokens server-side and scope them narrowly, and never expose API secrets to client applications. Consent recording matters too: in many jurisdictions, you must inform callers they are speaking to an AI and obtain consent to record.
Regulatory scope depends on your sector. GDPR governs any EU user data, HIPAA applies to healthcare workloads in the United States, and financial services add their own recording and retention rules. VideoSDK supports end-to-end encryption and geo-fencing for restricting where media is processed, which helps with data residency requirements.
Choosing a Voice AI Platform
Picking a platform comes down to five questions: does it hit your latency target, does it support your languages, does it let you swap STT, LLM, and TTS providers freely, does it integrate with your existing channels including phone, and does the pricing model survive your call volume. Provider lock-in is the silent killer here. A platform tied to one LLM vendor inherits that vendor's pricing changes and outages.
VideoSDK's approach is provider-agnostic: the open-source Agent SDK works with multiple STT, LLM, and TTS providers, including OpenAI, Google Gemini, Anthropic Claude, Deepgram, ElevenLabs, and Cartesia, so you can optimize each pipeline stage independently. Deployment flexibility matters too, with managed Agent Cloud and self-hosted Docker or Kubernetes options available.
Evaluation Matrix
Use a decision tree to narrow your choice systematically. Start with latency requirements, since they eliminate platforms first. Then filter by language coverage, then pricing at your expected volume, and finally integration effort.
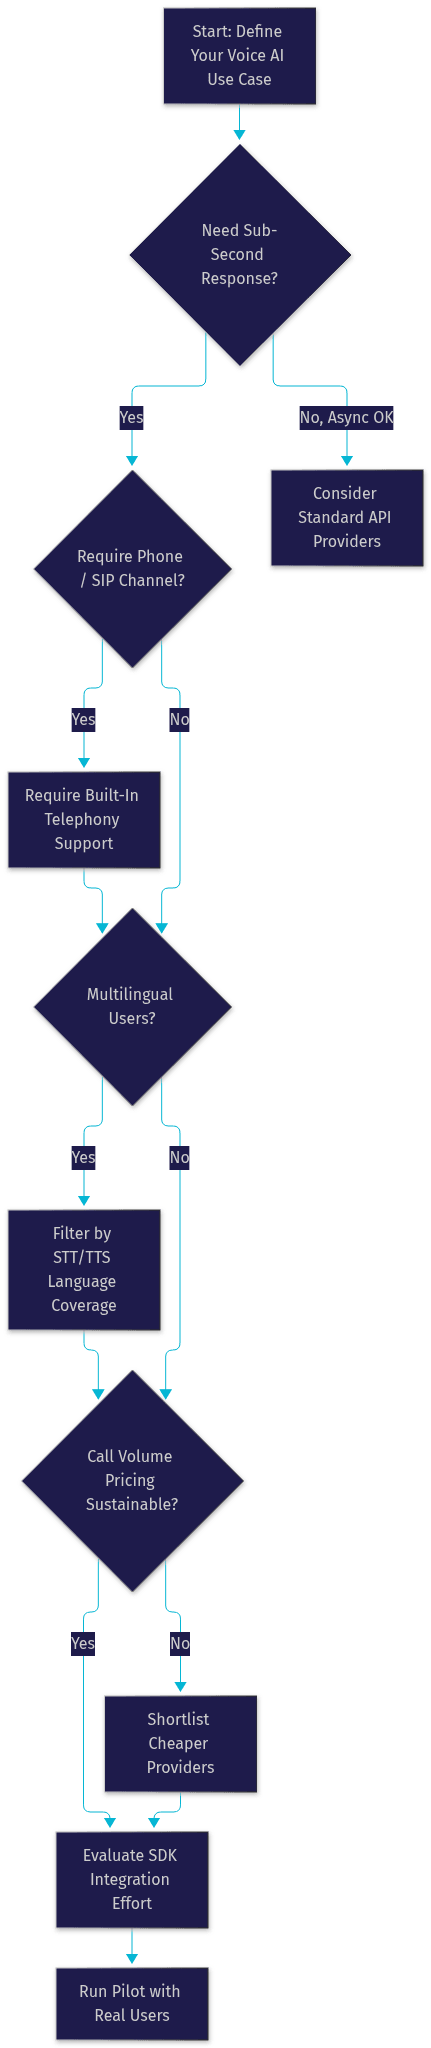
Run a pilot before committing. A two-week pilot with real callers exposes latency, accuracy, and integration issues that vendor benchmarks never will.
Best Practices & Common Pitfalls
Production voice AI fails in predictable ways. Teams that ship reliably plan for disconnections, authentication edge cases, and bad networks from day one.
Handling Disconnections & Re-joins
Users drop calls constantly on mobile networks. Your session layer should support automatic reconnection with conversation state preserved, so the agent resumes mid-context rather than restarting the dialogue. Checkpointing, saving conversation state at each turn, lets an interrupted session resume exactly where it stopped. VideoSDK rooms handle rejoin semantics, and the Conversational Graph's checkpointing feature supports save-and-resume for structured flows.
Managing Token Expiry & Rate Limits
Authentication tokens expire mid-session more often than teams expect, especially on long calls. Generate tokens server-side, refresh them proactively before expiry rather than reactively after failure, and scope each token to a single session. For rate limits, implement graceful backoff and queueing so a burst of concurrent calls degrades politely instead of dropping users. Monitoring token and quota usage in real time turns surprise outages into routine alerts.
Optimizing Audio Quality on Low-Bandwidth Networks
On weak connections, raw audio streams stutter and STT accuracy collapses. Adaptive bitrate adjustment reduces audio quality gracefully under congestion instead of dropping packets. Built-in noise suppression cleans background sound before it reaches STT, improving both accuracy and perceived quality. De-noise features in VideoSDK's agent pipeline preprocess audio upstream of recognition, and audio-only sessions dramatically cut bandwidth needs compared to video, which is why voice-first use cases perform well even on 3G-class connections.
Future Trends in Voice AI Applications
Three trends will define the next wave. Multimodal agents are already emerging, combining voice with vision so an agent can see a document a user holds up while discussing it, enabled by multimodal LLMs and VideoSDK's vision support in agent pipelines. On-device inference is shrinking latency further by running smaller STT and TTS models locally, keeping sensitive audio on the device and cutting cloud round-trips for simple interactions. And AI-driven voice personalization is letting applications tailor tone, pace, and vocabulary to individual users over time, so a tutoring agent sounds different for a shy beginner than for a confident advanced learner.
The common thread is that voice AI applications are becoming ambient. As latency drops and models improve, speaking to software will feel less like using a tool and more like the default way humans already communicate.
Definitions Glossary
Speech-to-Text (STT): The engine that converts spoken audio into text, ideally streaming partial results so downstream reasoning can begin before the user finishes speaking. Accuracy is typically measured in word error rate.
Text-to-Speech (TTS): The engine that converts generated text responses into natural-sounding spoken audio, streamed back to the user in chunks to minimize perceived latency.
Agent Worker: The Python process in VideoSDK's AI Agent SDK that manages an agent's session lifecycle inside a VideoSDK room, coordinating the STT, LLM, and TTS pipeline.
Turn Detection: The mechanism that decides when a user has finished speaking and the agent should respond, distinguishing genuine turn endings from natural pauses.
Conversational Graph: VideoSDK's deterministic orchestration layer that defines conversation flow as a directed graph of nodes and transitions, keeping business rules in control while the LLM handles natural language.
Barge-in: The ability of a voice AI system to detect a user interrupting and immediately stop its own speech to listen, which is essential for natural conversation.
Key Takeaways
- Voice AI applications chain speech-to-text, LLM reasoning, and text-to-speech into a real-time conversational loop, and sub-second response time is the benchmark that makes them feel natural.
- Industry adoption is broad and accelerating: AI call centers, healthcare intake, banking KYC, voice shopping, and language tutoring all ship in production today.
- Latency, STT accuracy, multilingual coverage, and compliance are the four technical pillars that separate demos from dependable systems.
- Choose a provider-agnostic platform so you can swap STT, LLM, and TTS engines independently as benchmarks and pricing shift.
- VideoSDK's open-source AI Agent SDK, Conversational Graph, and built-in SIP telephony provide the real-time session layer that connects these pipelines to users on web, mobile, and phone.
Conclusion
Voice AI applications have crossed the threshold from impressive demos to strategic infrastructure, and the deciding factor was latency engineering. Teams that treat sub-second response, accuracy benchmarks, and compliance as first-class requirements are shipping agents that customers genuinely prefer over hold music and phone trees. The building blocks are mature: strong STT and TTS engines, capable LLMs, and platforms like VideoSDK's AI Agent SDK that assemble them into reliable real-time sessions. Start with the quickstart guide, join the VideoSDK Discord community to compare notes with thousands of developers, and sign up free at app.videosdk.live/login to build your first voice AI application. What are you building with voice AI? Drop a comment, I'd love to hear which use case you're tackling.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ