


LLM voice assistants are AI-driven conversational systems that combine real-time speech-to-text, large language model reasoning, and text-to-speech synthesis to enable natural, context-aware voice interaction. Unlike traditional rule-based voice bots, they understand open-ended queries, maintain conversational state, and call external tools or APIs to complete tasks. VideoSDK provides an AI Voice Agent SDK that connects these components into real-time rooms with sub-second latency.
The shift from scripted voice menus to genuinely conversational AI happened fast. In 2026, developers are no longer asking whether LLM voice assistants are production-ready. They are asking how to build them with acceptable latency, how to choose between cascaded pipelines and full-duplex models, and how to deploy them at scale without sacrificing audio quality.
If you have ever tried wiring a speech-to-text engine to an LLM and then piping the response through a text-to-speech synthesizer, you know the hard part is not any single component. The hard part is the glue. Latency accumulates at every boundary. Turn detection fails in noisy rooms. Tokens expire mid-conversation. Background noise confuses the transcription layer. These are engineering problems, not research problems, and they have engineering solutions.
This guide walks through the full architecture of an LLM voice assistant, compares the major integration patterns, and covers what it takes to ship one to production. Whether you are building a customer support agent, a telehealth intake bot, or an internal productivity assistant, the decisions you make about model selection, streaming strategy, and transport protocol will determine whether users stay on the call or hang up.
What Are LLM Voice Assistants?
LLM voice assistants are defined as voice-based conversational interfaces where a large language model replaces the traditional intent-classification and slot-filling logic of older voice bots. Instead of mapping spoken commands to a fixed set of intents, the LLM processes transcribed speech as natural language, generates a contextually appropriate response, and synthesizes it back to speech in real time.
The user experience feels fundamentally different from older systems. A caller can speak in full sentences, change topics mid-conversation, ask follow-up questions, and reference earlier context without repeating themselves. The assistant can ask clarifying questions, call external APIs to fetch real-time data, and adapt its tone based on the conversation flow. This is what makes LLM voice assistants distinct from both IVR systems and text-only chatbots.
Core Components of an LLM Voice Assistant
Every LLM voice assistant, regardless of deployment strategy, relies on three core processing layers working in sequence. Understanding what each layer does and where latency enters the system is essential before you make architectural decisions.
Speech-to-Text (STT) Layer
The STT layer converts incoming audio into text that the LLM can process. Real-time transcription is the goal here, but the definition of "real-time" varies by engine. Some models stream partial transcripts as the user speaks, while others wait for a pause before returning a final transcript. That distinction matters enormously for perceived latency.
OpenAI Whisper and its optimized variant faster-whisper are popular choices for developers who want local or self-hosted transcription. Cloud-based options like Deepgram, AssemblyAI, and Google Cloud STT offer lower latency for streaming workloads but introduce network dependency. According to Artificial Analysis's Speech Arena benchmark, Deepgram's Nova series consistently ranks among the fastest streaming STT engines for conversational audio, with median transcription latency under 200 milliseconds.
The STT layer also handles voice activity detection, or VAD, which determines when the user has started and stopped speaking. Poor VAD is one of the most common causes of awkward pauses or premature interruptions in LLM voice assistants.
Large Language Model (LLM) Engine
The LLM engine is the reasoning core. It takes the transcribed text, applies any system prompts or persona instructions, references conversation history, and generates a response. Modern LLMs used in voice assistants also support tool-calling, which means they can invoke external functions like checking a calendar, querying a database, or fetching weather data as part of generating a reply.
Conversational state management is critical here. The LLM needs to maintain context across turns, which means the system must track a sliding window of recent exchanges and pass them with each new request. Some frameworks use structured state objects, while others rely on raw conversation buffers. VideoSDK's Conversational Graph takes a different approach by defining conversation flow as a deterministic graph, letting the LLM handle language generation while business logic controls branching and state transitions.
Model choice involves a trade-off between reasoning quality and latency. Smaller models like Llama 3 8B or Mistral 7B can run on local hardware with sub-second response times, while larger models like GPT-4o or Claude 3.5 Sonnet produce richer responses but add network round-trip latency.
Text-to-Speech (TTS) Layer
The TTS layer converts the LLM's text response back into spoken audio. This is where the assistant's voice personality comes alive, and it is also where streaming strategy has the biggest impact on perceived latency.
Streaming TTS engines begin synthesizing audio as soon as the first sentence or chunk of text is available, rather than waiting for the full LLM response to complete. This can reduce time-to-first-audio by several hundred milliseconds. ElevenLabs, OpenAI TTS, Cartesia Sonic, and AWS Polly are all commonly used in LLM voice assistant pipelines. EdgeTTS is a popular free option for prototyping, though it lacks the naturalness and streaming control of commercial alternatives.
The key architectural decision is whether to stream TTS output directly to the user's audio device as chunks arrive, or to buffer the full response first. Streaming wins on latency. Buffering wins on consistency and audio quality. Most production systems use streaming with a small initial buffer to smooth out chunk boundaries.
Typical Architecture of an LLM Voice Assistant
The standard cascaded architecture flows audio through five stages, with optional branches for tool-calling and persistent memory. This diagram shows the vertical data flow from microphone input to speaker output, including the feedback loop where tool results re-enter the LLM for final response generation.
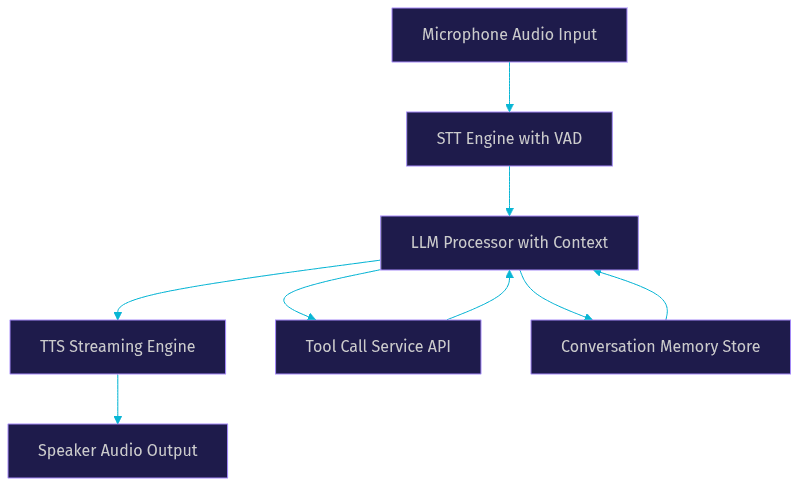
This architecture represents the cascaded pipeline pattern, which is the most common approach in open-source and self-hosted projects. Each stage communicates with the next through a streaming interface, and the tool-calling and memory modules operate as side channels that the LLM can invoke asynchronously. The critical latency path runs from microphone to speaker, and every handoff between stages adds overhead.
Choosing the Right Models for Your Voice Assistant
Model selection for an LLM voice assistant is not a single decision. You are choosing three separate models (STT, LLM, TTS), and each one has its own latency, cost, and privacy profile. The right combination depends on your deployment target, budget, and latency budget.
On-device inference gives you the lowest network latency and the strongest privacy guarantees, but it limits model size and requires significant compute resources on the host device. Cloud models offer better reasoning quality and naturalness but add network round-trips and raise data privacy questions. Hybrid approaches, where STT runs locally and the LLM runs in the cloud, are increasingly common.
| Component | On-Device Option | Cloud Option | Best For |
|---|---|---|---|
| STT | faster-whisper, Vosk | Deepgram Nova, Google STT | On-device for privacy, cloud for streaming latency |
| LLM | Llama 3 8B, Mistral 7B | GPT-4o, Claude 3.5 Sonnet | On-device for sub-second response, cloud for complex reasoning |
| TTS | Piper, EdgeTTS | ElevenLabs, Cartesia Sonic | On-device for offline use, cloud for natural voice quality |
The table above simplifies a complex decision space. In practice, most production LLM voice assistants use a mix. A common pattern is local STT for privacy and low latency, a cloud LLM for reasoning quality, and cloud TTS for voice naturalness. This hybrid approach keeps sensitive audio data on-device while leveraging cloud infrastructure for the computationally heavy reasoning and synthesis steps.
Cost is another factor that developers often underestimate. Cloud LLM inference is billed per token, and a voice assistant that maintains long conversations can accumulate significant costs. Streaming TTS is typically billed per character or per minute of audio. For high-volume deployments, on-device models can reduce per-conversation cost to near zero after the initial hardware investment.
Integration Patterns for LLM Voice Assistants
There are two primary architectural patterns for building LLM voice assistants, and choosing between them is one of the most consequential decisions you will make. Each pattern has distinct latency characteristics, flexibility trade-offs, and ecosystem requirements.
Full-Duplex Streaming (Single-Model Approach)
Full-duplex streaming is the newer pattern, popularized by real-time multimodal models like OpenAI's Realtime API and Google Gemini Live. In this approach, a single model handles audio input and audio output directly, without an explicit STT-to-LLM-to-TTS pipeline. The model listens to incoming audio and generates outgoing audio in a continuous stream.
The advantage is latency. Because there is no handoff between separate STT, LLM, and TTS components, the end-to-end latency can be significantly lower. The model can also handle interruptions more naturally, since it is processing audio in real time rather than waiting for a complete transcript.
The disadvantage is flexibility. You are locked into a single provider's model and voice options. You cannot swap out the STT engine for a more accurate one, or replace the TTS with a voice that better matches your brand. Tool-calling support depends entirely on what the provider exposes. For developers who need maximum control over each pipeline stage, the cascaded approach remains the better choice.
Cascaded Pipeline (STT to LLM to TTS)
The cascaded pipeline is the modular approach where each component is independently selected and configured. Audio flows from the microphone through an STT engine, the transcript is passed to an LLM, and the LLM's response is sent to a TTS engine for synthesis. This is the pattern used by most open-source voice assistant frameworks.
The strength of this pattern is composability. You can pair a fast local STT with a powerful cloud LLM and a premium TTS voice, optimizing each stage independently. You can also insert custom processing between stages, such as profanity filters, sentiment analysis, or response formatting.
The trade-off is latency. Each handoff between components adds overhead, and the total latency is the sum of all stage latencies plus inter-process communication costs. Streaming between stages helps, but the architecture is inherently slower than a single-model approach. VideoSDK's AI Voice Agent SDK supports this cascaded pattern with a Python-based pipeline that connects STT, LLM, and TTS providers into VideoSDK rooms, with built-in turn detection and voice activity detection to manage the handoffs.
Tool-Calling and External APIs
Tool-calling is what transforms an LLM voice assistant from a conversational toy into a functional agent. When the LLM determines that it needs external data to answer a question, it emits a structured tool-call request that the system executes against an external API. The result is fed back into the LLM, which incorporates it into the final response.
Common tool integrations include weather APIs, calendar services, database queries, web search, and internal business systems. The LLM decides when to call a tool based on the user's intent, and the system handles the actual API execution. This separation is important because it means the LLM does not need direct network access, which simplifies security and access control.
In a voice context, tool-calling introduces a latency challenge. If the LLM calls a weather API that takes 800 milliseconds to respond, the user is waiting in silence. Production systems handle this by having the TTS layer synthesize a brief acknowledgment like "Let me check that for you" while the tool executes, then delivering the full answer once the result returns. This keeps the conversation feeling natural even when external APIs are slow.
Best Practices for Production-Ready Voice Assistants
Shipping an LLM voice assistant to production requires attention to details that prototyping tutorials rarely cover. Token management, turn-taking, noise handling, transport protocol selection, and latency monitoring are the difference between a demo that impresses in a quiet room and a system that works in real-world conditions.
Token management is the first thing that breaks in production. LLM API tokens expire, and if your assistant is mid-conversation when a token refresh fails, the call drops. Implement proactive token rotation with a buffer of at least 60 seconds before expiry, and always handle authentication errors with a retry mechanism that preserves conversation state.
Turn-taking detection is what prevents the assistant from talking over the user or waiting too long to respond. The system needs to distinguish between a natural pause and the end of a speaking turn. This is where voice activity detection quality matters. A VAD that triggers too aggressively will interrupt users who pause to think. A VAD that is too lenient will create awkward silences. Tuning the VAD silence threshold to your typical use case is essential, and different scenarios require different settings. A telemedicine intake assistant needs a longer silence threshold than a pizza ordering bot.
Background noise handling is critical for real-world deployments. Users call from cars, coffee shops, and busy offices. The STT layer needs audio preprocessing that includes noise suppression and echo cancellation before transcription begins. VideoSDK's AI agent pipeline includes built-in de-noise processing to handle this, but if you are building a custom pipeline, you need to add a dedicated audio preprocessing stage before the STT engine.
Transport protocol selection determines how audio moves between the user and the assistant. WebRTC is the standard for browser-based and mobile voice assistants because it handles NAT traversal, adaptive bitrate, and sub-second latency. For server-to-server communication between pipeline components, gRPC is preferred for its streaming support and low overhead. VideoSDK uses WebRTC for the user-facing transport layer, which is why its voice agents achieve sub-second end-to-end latency in production deployments.
Latency monitoring should be continuous, not just a pre-launch check. Instrument every stage of the pipeline with timing metrics, and alert when any stage exceeds its latency budget. The key metric to track is time-to-first-audio, which is the elapsed time from when the user stops speaking to when the first audio chunk reaches their speaker. Anything over 1.5 seconds feels sluggish. Anything over 3 seconds feels broken.
Common Pitfalls and How to Avoid Them
Even with a solid architecture, specific issues recur in LLM voice assistant deployments. Knowing these pitfalls in advance saves debugging time and prevents user-facing failures.
Audio echo occurs when the assistant's output audio feeds back into the microphone input, causing the STT layer to transcribe the assistant's own voice. The fix is echo cancellation at the audio capture layer, before the audio reaches the STT engine. Most WebRTC implementations include built-in echo cancellation, but custom audio pipelines often skip this step.
Token expiry mid-conversation happens when the LLM API token expires during a long call. The assistant suddenly stops responding, and the user hears silence. Implement token refresh logic that runs on a timer, not just on initial connection, and cache a fresh token before the current one expires.
Model warm-up latency is the delay introduced when a model is loaded into memory for the first time. Cloud models typically have cold-start latency of 1 to 3 seconds. On-device models can take even longer if the model weights are loaded from disk. Pre-warm your models before the first user interaction by sending a dummy request during system startup.
Mismatched language locales cause subtle but frustrating bugs. If your STT engine is configured for en-US but the user speaks British English, transcription accuracy drops. If your TTS engine synthesizes American English pronunciation for a British English response, the voice sounds inconsistent. Align the locale settings across all three pipeline stages, and detect the user's language early in the conversation to adjust dynamically.
Future Trends in LLM Voice Assistants
The LLM voice assistant landscape is evolving rapidly, and several trends are shaping what developers will build in the next 12 to 18 months.
Multimodal perception is the most significant frontier. Future voice assistants will not just hear the user. They will see the user's environment through camera input, read screen content, and process contextual signals like location and device state. This enables scenarios like a support agent that can see the error message on your screen while you describe the problem verbally.
Continuous memory is moving from research to production. Instead of resetting context at the end of each call, voice assistants are beginning to maintain long-term memory across sessions. This requires persistent storage of conversation summaries, user preferences, and interaction history, with retrieval mechanisms that feed relevant context into the LLM at the start of each new session.
On-device inference breakthroughs are making local LLM voice assistants practical. Model quantization techniques and specialized hardware like Apple's Neural Engine and mobile NPUs are bringing 7B and 8B parameter models to phones and laptops with acceptable latency. This trend will accelerate privacy-first voice AI deployments that never send audio to the cloud.
Standardization efforts like the OpenAI Realtime API and emerging WebRTC-based agent protocols are reducing the integration burden. VideoSDK's open-source Agent SDK on GitHub reflects this trend, providing a standardized Python framework for connecting STT, LLM, and TTS providers into real-time communication rooms.
Definitions Glossary
STT (Speech-to-Text): The process of converting spoken audio into text. In LLM voice assistants, the STT layer typically runs in streaming mode, producing partial transcripts as the user speaks and a final transcript when they stop.
TTS (Text-to-Speech): The process of converting text into spoken audio. Streaming TTS engines synthesize audio in chunks as text arrives, reducing the time between LLM response generation and the user hearing the reply.
VAD (Voice Activity Detection): A signal processing technique that determines when speech is present in an audio stream. VAD is critical for turn-taking in LLM voice assistants, as it tells the system when the user has started and stopped speaking.
Full-Duplex Streaming: An architecture where a single multimodal model handles audio input and output simultaneously, without separate STT and TTS stages. This approach minimizes latency but reduces component flexibility.
Cascaded Pipeline: An architecture where STT, LLM, and TTS run as separate components connected in sequence. This approach maximizes flexibility and composability at the cost of additional inter-component latency.
Tool-Calling: The ability of an LLM to invoke external functions or APIs as part of generating a response. In voice assistants, tool-calling enables real-time data retrieval and action execution without breaking the conversational flow.
Turn-Taking Detection: The mechanism that determines when a speaking turn has ended and the assistant should begin responding. This combines VAD silence thresholds with semantic cues from the STT output to avoid premature or delayed responses.
Key Takeaways
- LLM voice assistants replace rule-based voice bots with natural language reasoning, enabling open-ended conversation, context retention, and external tool integration.
- The cascaded pipeline (STT to LLM to TTS) offers maximum flexibility and composability, while full-duplex streaming models offer lower latency at the cost of provider lock-in.
- Model selection should be done per component, not globally. A hybrid approach with local STT, cloud LLM, and cloud TTS balances privacy, latency, and quality for most production deployments.
- Production readiness requires attention to token management, turn-taking detection, background noise handling, transport protocol selection, and continuous latency monitoring.
- VideoSDK's AI Voice Agent SDK provides a Python-based cascaded pipeline with built-in VAD, de-noise processing, and WebRTC transport, enabling sub-second voice agent deployment without building the infrastructure from scratch.
Conclusion
Building an LLM voice assistant that works in production is an exercise in systems engineering. The individual components (STT, LLM, TTS) are mature and accessible, but the integration layer is where most projects stall. Latency budgets, turn-taking logic, noise handling, and transport protocol choices are the decisions that determine whether your assistant feels natural or frustrating.
The good news is that the tooling has caught up. Open-source frameworks, standardized APIs, and platforms like VideoSDK's AI Voice Agent SDK are removing the infrastructure burden so you can focus on conversation design and user experience. If you are ready to build, start with the VideoSDK AI agents quickstart and join the VideoSDK Discord community to connect with other developers shipping voice AI. You can sign up for a free account at app.videosdk.live/login and get started with free credits.
What are you building with VideoSDK? Drop a comment below. I would love to hear what kind of LLM voice assistant use case you are working on, whether it is a customer support agent, a telehealth intake system, or something entirely new.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ