


Conversational AI voice is a real-time system that listens, understands, and speaks back with human-like timing, built from speech-to-text, a large language model, and text-to-speech working in a low-latency pipeline. Unlike traditional TTS or dictation tools, it handles turn-taking, interruptions, and emotion in a single continuous conversation. VideoSDK's AI Agent SDK lets developers wire these components into production voice applications over WebRTC and telephony in days rather than months.
Between 2024 and 2026, conversational AI voice crossed a threshold. Voice agents moved from stilted, press-one-for-yes phone trees to systems that banter, interrupt gracefully, and hold context across a ten-minute call. The driving force is a stack of streaming speech models and large language models that now respond in under a second, fast enough that the conversation feels natural rather than scripted.
For developers, this shift matters commercially. AI-driven customer support, AI-powered sales bots, and voice-first applications are moving from demos to production budgets. The engineering challenge is no longer whether the models work, but how to assemble a low-latency voice pipeline that survives real networks, real users, and real compliance requirements. This guide covers the architecture, the capabilities driving adoption, the build process, and how the leading platforms compare in 2026.
What Is Conversational AI Voice?
Conversational AI voice is defined as an AI system that conducts spoken, multi-turn dialogue in real time, combining speech recognition, language reasoning, and speech generation into one continuous interaction loop. It differs from traditional text-to-speech in a fundamental way: TTS reads prepared text aloud, while a conversational system generates what to say, decides when to say it, and adapts to how the user responds.
It also differs from plain speech-to-text. Dictation software transcribes words and stops there. A conversational AI voice system interprets the transcript, retrieves context, plans a response, and speaks it back, all while tracking conversational dynamics like interruptions and unfinished sentences. The result behaves closer to a phone conversation with a capable colleague than a command interface.
VideoSDK provides this capability through its AI Agent SDK, which connects STT, LLM, and TTS providers into a managed real-time session that users can join from web, mobile, or the plain telephone network.
Core Components of a Conversational Voice System
Every production voice agent shares the same core components. A speech-to-text engine converts incoming audio into text. A large language model reasons over that text, applying context, tools, and business rules. A text-to-speech engine converts the response into natural speech. Around those three sit the orchestration layers: voice activity detection to know when the user is speaking, turn detection to decide when they have finished, and optionally multimodal inputs like vision or DTMF keypad events. The quality of the whole system is set by the weakest of these parts, which is why platform selection matters so much.
Real-Time Voice Interaction Architecture
A conversational AI voice pipeline works by streaming audio through a chain of components, each adding intelligence and handing off to the next in well under a second. The user's microphone audio first passes through voice activity detection, which filters silence and noise so the system only processes actual speech. The audio then reaches the speech-to-text engine, which streams a live transcript as words are spoken rather than waiting for the sentence to end.
The transcript feeds the large language model, which generates a response token by token. As soon as the first sentence is ready, the text-to-speech engine begins speaking it while the LLM continues generating the rest. This overlapping, streaming design is what keeps end-to-end latency below one second. Finally, the synthesized audio streams back to the user's speaker over a real-time transport like WebRTC, or over SIP when the user is on a regular phone line.
Turn detection runs in parallel across the whole loop. It watches the incoming audio stream for natural pause patterns and semantic completion, deciding when the agent should start responding and when the user has interrupted it mid-sentence. When the user barges in, the pipeline cancels the in-flight TTS audio immediately, a behavior known as preemptive response handling.
Here is how the full pipeline fits together, including where VideoSDK sits as the real-time session layer:
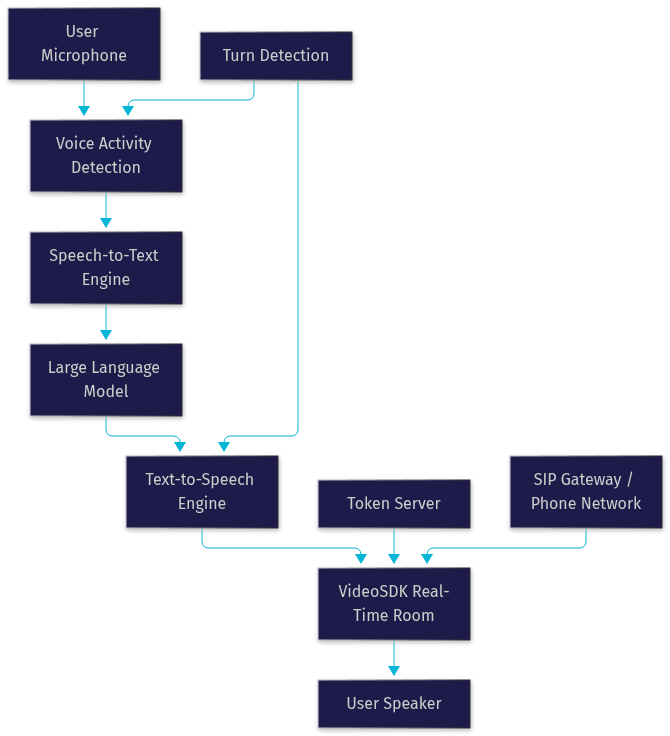
The VideoSDK room in the middle is the piece most teams underestimate. It handles media transport, participant session management, and the bridge between web users on WebRTC and phone users arriving over SIP, so your pipeline logic stays identical regardless of how the caller connected.
Key Capabilities Driving Adoption
Several capabilities matured simultaneously between 2024 and 2026, and together they turned voice agents from novelty into infrastructure. Voice cloning now needs only a few seconds of reference audio. Emotion-aware TTS can be directed with natural-language instructions. Multilingual models switch languages mid-conversation. Full-duplex turn-taking lets users interrupt the agent the way they would interrupt a human. End-to-end latency has dropped below one second on well-built pipelines, which is the threshold where users stop perceiving the system as laggy.
Integration depth matters just as much as model quality. Agents that can join SIP trunks, answer phone calls, and route DTMF inputs extend AI-driven customer support to the billions of callers still using plain telephony. VideoSDK's telephony integration handles this bridge natively, so the same agent serves web users and phone callers.
Voice Cloning and Accent Preservation
Modern voice cloning lets a developer create a production-quality custom voice from a few seconds of clean audio. Providers like ElevenLabs and Cartesia have reduced the reference requirement from minutes of studio recording to a short sample, which changes the economics of personalized agents. A brand can now ship an agent that speaks with a consistent, recognizable voice across every channel. Accent preservation matters especially for multilingual deployments, where a cloned voice that keeps its natural accent across languages feels dramatically more authentic to callers.
Emotion-Aware Speech Generation
Emotion-aware TTS works by accepting natural-language direction alongside the text to speak. A developer or an LLM can instruct the engine to deliver a line as warm, apologetic, or enthusiastic, and the model adjusts prosody, pacing, and pitch accordingly. In practice, this is often driven dynamically: the LLM tags its own response with an emotional intent based on the conversation state, and the TTS engine renders it. For customer support, an agent that shifts from neutral to empathetic when a caller is frustrated measurably improves call outcomes.
Multilingual Real-Time Conversation
Multilingual voice AI handles language detection and switching on the fly. The STT layer identifies the spoken language, the LLM responds in kind, and the TTS engine renders the reply in a matching voice, sometimes even preserving the speaker's voice across languages. For global AI-powered sales bots and support lines, this removes the need to build per-language deployments. The main engineering caution is that translation-in-the-middle designs add latency, so native multilingual models that process each language end to end perform better in real-time settings.
Building a Conversational AI Voice Application
Building a conversational AI voice application is a six-step process, and the order matters. Skipping the infrastructure steps is the most common reason promising demos never reach production.
- Choose your providers. Select an LLM for reasoning, an STT engine for transcription, and a TTS engine for speech. Optimize for streaming behavior and measured latency, not just benchmark accuracy. A model that is brilliant but buffers full sentences before responding will feel broken on a live call.
- Set up authentication and a token server. VideoSDK uses token-based authentication: you generate a token server-side from your API key and secret, then pass it to the agent session. Never expose credentials in client code. The authentication guide covers the pattern, which is the same for voice agents.
- Configure turn detection and VAD. Tune how aggressively the system decides the user has finished speaking. Too eager and the agent interrupts constantly; too relaxed and callers experience dead air. This single setting has an outsized effect on perceived conversation quality.
- Connect the pipeline. Wire the STT, LLM, and TTS stages into the agent session so audio streams continuously and responses begin as soon as the first sentence is generated. VideoSDK's Agent SDK manages this orchestration, including the Conversational Graph layer for deterministic flows like booking and claims.
- Test latency and quality. Measure end-to-end response time from end of user speech to first audible syllable of the reply. Test on poor networks, with background noise, and with accented speech. Anything above roughly one second degrades the experience noticeably.
- Deploy with production infrastructure. Serve over HTTPS, ensure TURN server fallback for restrictive networks, and host the agent worker close to your users to cut transport latency.
Common Pitfalls
Three problems bite nearly every team. Network jitter causes choppy audio when the transport layer lacks adaptive buffering, so use a real-time transport rather than naive HTTP streaming. Token expiry mid-session drops agents from rooms, so issue tokens with appropriate lifetimes and refresh them before long calls. Microphone permissions fail silently in some browsers until the user interacts with the page, so test permission flows explicitly on every target platform.
Production Considerations
At production scale, four concerns dominate. Scaling means running multiple agent workers and letting the platform route sessions to healthy instances, which VideoSDK's Agent Cloud handles as a managed option. Monitoring means tracking latency percentiles, interruption rates, and conversation completion, not just uptime. Privacy means understanding where audio and transcripts are processed and retained, and configuring retention to match your policy. Compliance means that for regulated industries like healthcare and finance, deterministic conversation flows with checkpointing and human-in-the-loop handoff are often required, which is exactly what a graph-based orchestration layer provides over free-form LLM dialogue.
Comparing Leading Platforms
Choosing a conversational AI voice platform in 2026 means comparing real-time speech models on latency, voice quality, breadth, and cost. The three most consequential offerings are OpenAI's real-time speech-to-speech model, ElevenLabs' realtime conversational platform, and Deepgram's Flux STT engine. The table below summarizes how they compare on the dimensions developers actually weigh.
| Dimension | OpenAI Realtime | ElevenLabs Realtime | Deepgram Flux |
|---|---|---|---|
| Core strength | Speech-to-speech model, full-duplex | Voice quality and cloning | Streaming STT accuracy and speed |
| Latency | Sub-second, model-inherent | Sub-second with streaming TTS | Very low STT latency, pipeline-dependent |
| Voice count | Curated set plus custom options | Large library plus few-second cloning | STT only, pairs with any TTS |
| Emotion support | Natural prosody, limited direct control | Strong, prompt-directed emotion | Not applicable (STT layer) |
| Multilingual | Strong, broad language coverage | Strong, voice-preserving languages | Strong conversational transcription |
| Pricing | Token-based, audio-priced | Character and session-based | Per-minute audio pricing |
| Best for | Full-stack simplicity in one model | Brand voice and expressive agents | Precision transcription in custom stacks |
OpenAI's realtime model excels when you want the fewest moving parts: one speech-to-speech model handles understanding and generation, which simplifies architecture. Its weakness is less granular control over voice identity and emotional direction than dedicated TTS providers offer. ElevenLabs excels for brand-critical voice experiences, where cloning and emotional expressiveness are the product. It falls short for teams that want to swap LLM reasoning freely, since its value concentrates in the speech layer. Deepgram Flux excels as the transcription layer in a custom pipeline, delivering fast, accurate conversational STT; it is not a complete voice agent on its own, so you assemble the rest of the stack yourself.
This is where an orchestration layer earns its keep. VideoSDK's AI Agent SDK connects any of these providers into one real-time session, so you can pair Deepgram STT with an OpenAI LLM and ElevenLabs TTS, then swap individual components as benchmarks shift without rebuilding your transport and session logic. The code samples show this composition pattern across providers.
Future Trends in Conversational AI Voice
Four trends will shape the next two years. Real-time multimodal models will let agents see and hear simultaneously, so a support agent can read a photo of a broken part while the customer describes it. On-device inference will bring sub-100-millisecond voice loops to phones and IoT hardware, enabling private, offline-capable agents. Tighter AR and VR integration will make voice the primary interface for spatial computing, where hands are occupied and screens are peripheral. And emerging standards around WebRTC, SIP interop, and agent-to-agent protocols will make multi-agent voice systems interoperable rather than siloed. Developers who build on composable, standards-based pipelines today will absorb these shifts cheaply.
Definitions Glossary
Conversational AI Voice: A real-time AI system that conducts spoken multi-turn dialogue by combining speech recognition, language reasoning, and speech generation in one continuous loop.
Voice Activity Detection (VAD): The component that determines when incoming audio contains actual speech, filtering silence and noise so the pipeline only processes real utterances.
Turn Detection: The mechanism that decides when a user has finished speaking and the agent should respond, including handling interruptions mid-response.
Agent Worker: The Python process that runs a VideoSDK AI agent, managing its session lifecycle inside a real-time room.
SIP: Session Initiation Protocol, the signaling standard that bridges traditional phone networks into WebRTC-based AI voice rooms.
Preemptive Response: The behavior where a voice agent stops its in-flight speech immediately when the user interrupts, then resumes listening.
Key Takeaways
- Conversational AI voice combines STT, an LLM, and TTS with turn detection and VAD into a sub-second interaction loop, which is fundamentally different from traditional TTS or dictation.
- Latency below one second is the practical threshold where users perceive a voice agent as natural, so streaming every pipeline stage matters more than raw model accuracy.
- Platform choice is conditional: OpenAI's realtime model wins on architectural simplicity, ElevenLabs on voice quality and cloning, and Deepgram Flux on transcription precision in custom stacks.
- Production success depends on the unglamorous parts: server-side token generation, HTTPS and TURN infrastructure, permission handling, and latency monitoring.
- VideoSDK's AI Agent SDK and built-in SIP telephony let one agent serve web, mobile, and phone callers over the same real-time session, with the Conversational Graph layer available for deterministic, compliance-driven flows.
Conclusion
Conversational AI voice has become the interface layer for the next generation of support, sales, and companion products, and the teams that master its low-latency architecture now will own the category. The models are ready; the differentiator is the pipeline you build around them. Start with the VideoSDK AI Agents documentation, grab a free tier at app.videosdk.live, and ship your first voice agent this month. What are you building with conversational AI voice? Drop a comment, I'd love to hear what kind of voice-first use case you're working on.
Understanding the Technology Behind Conversational AI Voice
Natural Language Processing (NLP)
Natural Language Processing (NLP) is the core technology that allows computers to understand, interpret, and generate human language. NLP techniques are used to analyze the meaning of spoken words, identify the user's intent, and formulate appropriate responses. NLP algorithms are constantly evolving, enabling conversational AI systems to handle increasingly complex and nuanced language.
Speech Recognition and Text-to-Speech (TTS)
Speech recognition (also known as Automatic Speech Recognition or ASR) converts spoken audio into text. Text-to-Speech (TTS) does the opposite, converting text into synthesized speech. These two technologies work together to enable bidirectional communication between humans and machines. Advancements in deep learning have significantly improved the accuracy and naturalness of both speech recognition and TTS.
Machine Learning (ML) and Deep Learning (DL) in Voice AI
Machine learning (ML) and deep learning (DL) are crucial for training conversational AI models. These techniques allow systems to learn from vast amounts of data, improve their accuracy over time, and adapt to different accents, languages, and speaking styles. Deep learning models, such as recurrent neural networks (RNNs) and transformers, have revolutionized the field of conversational AI, enabling more human-like and engaging interactions.
Code Snippet: Python example of simple text-to-speech using a library like pyttsx3
python
1import pyttsx3
2
3# Initialize the TTS engine
4engine = pyttsx3.init()
5
6# Set the speaking rate (optional)
7engine.setProperty('rate', 150)  # words per minute
8
9# Set the voice (optional) - you may need to experiment to find available voices
10# voices = engine.getProperty('voices')
11# engine.setProperty('voice', voices[0].id) # Use the first available voice
12
13# The text you want to speak
14text = "Hello, world! This is a simple example of text-to-speech using pyttsx3."
15
16# Speak the text
17engine.say(text)
18
19# Wait for the speech to finish
20engine.runAndWait()
21
22# Stop the engine
23engine.stop()
Key Features of Advanced Conversational AI Voice Systems
Contextual Understanding and Memory
Advanced conversational AI systems can understand the context of a conversation and remember previous interactions. This allows for more natural and fluid conversations, as the system can refer back to earlier topics and provide more relevant responses. Contextual understanding is essential for building engaging and satisfying user experiences.
Personalized Interactions
By leveraging user data and preferences, conversational AI systems can personalize interactions to meet individual needs. This includes tailoring responses, providing customized recommendations, and adapting to different communication styles. Personalized interactions can significantly enhance user engagement and satisfaction.
Emotion Detection and Expression
Some advanced systems can detect emotions in a user's voice and respond accordingly. This enables more empathetic and human-like interactions. Furthermore, AI voice cloning techniques can be used to customize the emotion and tone of voice of a AI Voice Assistant. AI systems can also express emotions through synthesized speech, making the interactions more engaging and believable.
Multi-lingual Support
Conversational AI systems with multi-lingual support can understand and respond to users in multiple languages. This is crucial for global businesses that need to serve customers from diverse linguistic backgrounds. Multi-lingual support requires sophisticated NLP and speech recognition technologies that can handle the nuances of different languages.
Integration with Other Systems (CRM, etc.)
Integrating conversational AI systems with other business systems, such as CRM, ERP, and marketing automation platforms, allows for seamless data exchange and workflow automation. This enables businesses to provide more efficient and personalized customer service, improve operational efficiency, and gain valuable insights from customer interactions.
Designing Effective Conversational AI Voice Experiences
Understanding User Needs and Expectations
Before designing a conversational AI voice application, it's crucial to understand the needs and expectations of your target users. What tasks do they want to accomplish? What type of information are they seeking? What is their level of technical expertise? Answering these questions will help you create a voice experience that is both useful and enjoyable.
Defining Conversational Flows and Dialog Management
A well-defined conversational flow is essential for creating a positive user experience. The flow should guide the user through the interaction in a logical and intuitive manner. Dialog management techniques are used to handle user input, maintain context, and provide appropriate responses. Careful planning and testing are crucial for ensuring a smooth and effective conversational flow.
Creating Engaging and Natural-Sounding Voice Interactions
The quality of the synthesized voice is crucial for creating engaging and natural-sounding interactions. Choose a TTS engine that produces high-quality speech with natural intonation and rhythm. Also, pay attention to the wording and phrasing of your responses. Use clear, concise language that is easy to understand and avoid overly technical jargon.
Testing and Iterative Improvement
Testing is an essential part of the design process. Conduct user testing to identify areas for improvement and refine your conversational flow. Use analytics to track user behavior and identify pain points. Continuously iterate on your design based on user feedback and data analysis. This iterative approach will help you create a conversational AI voice experience that is both effective and enjoyable.
Building Your Own Conversational AI Voice Application
Choosing the Right Platform or Framework
Several platforms and frameworks are available for building conversational AI voice applications, including:
- Google Dialogflow: A powerful and versatile platform that offers a wide range of features, including intent recognition, entity extraction, and dialog management.
- Amazon Lex: A service for building conversational interfaces into any application using voice and text. Lex uses the same conversational engine as Alexa.
- Microsoft Bot Framework: A comprehensive framework for building, deploying, and managing bots across various channels, including voice.
Choose a platform or framework that meets your specific needs and technical expertise. Consider factors such as ease of use, scalability, cost, and available features.
Data Collection and Preprocessing
To train a conversational AI model, you'll need a large dataset of text and audio data. Collect data from various sources, such as customer service transcripts, online forums, and social media. Preprocess the data to remove noise, correct errors, and normalize the text. The quality of your data will directly impact the performance of your model.
Model Training and Optimization
Use machine learning techniques to train your conversational AI model. Experiment with different algorithms and hyperparameters to optimize the model's accuracy and performance. Consider using transfer learning to leverage pre-trained models and accelerate the training process.
Deployment and Monitoring
Once your model is trained and optimized, deploy it to a production environment. Monitor the model's performance and identify areas for improvement. Continuously retrain the model with new data to maintain its accuracy and relevance.
Code Snippet: Conceptual overview of a conversational AI architecture using a diagram
The Future of Conversational AI Voice
Advancements in NLP and Speech Technology
The future of conversational AI voice is bright, with ongoing advancements in NLP and speech technology. We can expect to see even more accurate and natural-sounding speech recognition, more sophisticated NLP algorithms that can understand nuanced language, and more advanced TTS engines that can generate human-like speech.
Increased Personalization and Emotional Intelligence
Future conversational AI systems will be able to personalize interactions to an even greater extent, adapting to individual user preferences and communication styles. They will also be able to detect and respond to a wider range of emotions, creating more empathetic and human-like interactions.
Emerging Applications and Use Cases
New applications and use cases for conversational AI voice are constantly emerging. We can expect to see conversational AI voice integrated into more devices and platforms, from smart homes and cars to wearables and virtual reality headsets. Voice AI for business will become even more prevalent.
Ethical Considerations and Responsible Development
As conversational AI becomes more powerful and pervasive, it's crucial to address the ethical considerations and ensure responsible development. This includes addressing issues such as data bias, user privacy, and the potential for misinformation and manipulation.
Top Conversational AI Voice Platforms and Tools
Overview of leading platforms (mentioning at least 3 with brief descriptions)
- Google Dialogflow: A web-based platform designed to quickly develop conversational interfaces. Offers a free tier and integrates well with other Google services.
- Amazon Lex: Enables the building of conversational interfaces using voice and text. Integrates seamlessly with AWS services, offering scalability and cost-effectiveness.
- Microsoft Bot Framework: A comprehensive platform providing tools to build and connect intelligent bots across various channels including voice. Offers flexibility and enterprise-grade features.
Comparing features and pricing models
Each platform offers varying features regarding intent recognition, language support, integrations, and analytics. Pricing models also vary, with some offering free tiers, pay-as-you-go options, and enterprise subscriptions. Developers should evaluate their specific needs and budget when choosing a platform.
Case Studies: Successful Implementations of Conversational AI Voice
Showcase at least 2 successful implementations across different industries. Highlight results achieved.
- Healthcare: A major hospital implemented a virtual nurse powered by conversational AI voice to handle patient inquiries, schedule appointments, and provide medication reminders. This resulted in a 30% reduction in call center volume and improved patient satisfaction.
- Retail: A leading e-commerce company implemented a voice-enabled shopping assistant that allowed customers to browse products, place orders, and track shipments using voice commands. This resulted in a 20% increase in mobile sales and improved customer engagement.
Challenges and Opportunities in Conversational AI Voice
Data Bias and Ethical Concerns
Data bias in training datasets can lead to unfair or discriminatory outcomes. Addressing data bias and ensuring ethical considerations are crucial for responsible development.
Maintaining User Privacy and Security
Protecting user privacy and security is paramount. Implement robust security measures to safeguard user data and comply with privacy regulations.
The Potential for Misinformation and Manipulation
Conversational AI can be used to spread misinformation or manipulate users. Developing safeguards to prevent misuse is essential.
Conclusion: Embracing the Potential of Conversational AI Voice
Conversational AI voice is a rapidly evolving technology with the potential to transform how we interact with machines. By understanding the technology, designing effective voice experiences, and addressing the ethical considerations, developers can unlock the full potential of conversational AI voice and create innovative solutions that benefit society.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ