


LLM voice AI is a system architecture that chains speech-to-text, a large language model, and text-to-speech so users can hold natural spoken conversations with software. The hard part is not any single component but orchestration: turn detection, latency budgets, and interruption handling determine whether the agent feels human or frustrating. VideoSDK's open-source AI Agent SDK provides this full pipeline as a managed layer, letting you plug in providers like OpenAI, Deepgram, and ElevenLabs and focus on conversation design instead of plumbing.
Most voice assistants built before 2023 were brittle: rigid intent trees, canned responses, and a failure mode that users could spot within seconds. LLM voice AI changed that equation. A large language model in the loop means the agent can handle open-ended questions, recover from misunderstandings, and adapt its tone. But wiring an LLM into a real-time audio conversation introduces problems that chatbots never faced: you now have milliseconds, not seconds, to decide whether the user finished their sentence.
By the end of this article you will understand the full end-to-end architecture of an LLM voice AI system, how to choose STT, LLM, and TTS components, how to read latency benchmarks, and whether to deploy in the cloud, on the edge, or both.
Understanding LLM Voice AI: Foundations and Trends
What is LLM Voice AI?
LLM voice AI is defined as a real-time conversational system in which a large language model generates dialogue from transcribed speech, and a speech synthesis engine speaks the response back to the user. It works by capturing microphone audio, converting it to text with a speech-to-text (STT) model, passing that text (plus conversation history) to an LLM, and streaming the LLM's output to a text-to-speech (TTS) engine that renders audible speech.
The category has split into two architectural camps. Cascaded pipelines chain separate STT, LLM, and TTS components, giving you flexibility to swap each piece. Speech-to-speech models, such as OpenAI's Realtime API and Google's Gemini Live, process audio in and audio out through a single multimodal model, trading provider flexibility for lower end-to-end latency. As of 2026, both approaches coexist, and most production teams run cascaded pipelines for control or native speech models for speed.
Core components: STT, LLM, TTS, and orchestration
Every LLM voice AI stack has four moving parts. The STT layer converts raw audio into text, and its accuracy directly bounds the quality of everything downstream. The LLM handles reasoning, dialogue management, and tool calling. The TTS layer converts generated text into natural speech, with streaming synthesis now standard for responsiveness. The orchestration layer is the piece most teams underestimate: it manages turn detection (deciding when the user has stopped speaking), voice activity detection (VAD), barge-in handling when the user interrupts, and the latency budget across all three models.
VideoSDK's AI Agent SDK treats this orchestration as a first-class concern, providing turn detection, VAD, and a pipeline abstraction that works with multiple STT, LLM, and TTS providers so you are not locked into a single vendor's stack.
Building an End-to-End LLM Voice AI Pipeline
Building a production voice agent is a sequence of component decisions followed by an integration effort that is mostly about latency and interruption handling. Here is how to approach each decision.
Choosing the right Speech-to-Text model
Your STT choice sets the ceiling on conversation quality because the LLM can only reason about what the transcription captures. For conversational audio, look for models trained on spontaneous speech rather than dictation: hesitation, filler words, and overlapping speech. Deepgram's Nova series, OpenAI's Whisper family, and AssemblyAI's Universal model are the most common choices in 2026, and each publishes word-error-rate figures on conversational corpora. Streaming STT is mandatory for real-time agents, since batch transcription forces you to wait for the user to finish before processing begins. Also check language coverage, diarization support (distinguishing speakers), and whether the provider streams partial hypotheses so your turn detector can react early.
Selecting a language model for dialogue
The LLM decision is about reasoning depth versus speed. A voice conversation cannot tolerate the multi-second generation times acceptable in chat. Providers like OpenAI, Google, and Anthropic all offer fast dialogue-tier models, and inference accelerators like Cerebras push token generation rates high enough for spoken cadence. Two capabilities matter more than raw intelligence: tool calling (so the agent can look up an order or book an appointment mid-conversation) and instruction stability (the model must reliably respect its system prompt about brevity and tone). A model that writes three-paragraph answers will destroy your latency budget no matter how fast your TTS is.
Text-to-Speech options for real-time response
Modern TTS is judged on three axes: naturalness, latency, and streaming behavior. ElevenLabs, Cartesia, OpenAI TTS, and AWS Polly are the most widely deployed options, and independent comparisons on Artificial Analysis's Speech Arena provide a useful neutral reference for quality. The critical technical requirement is streaming synthesis: the TTS engine must start speaking the first sentence while the LLM is still generating the rest of the response. Without streaming, you add the full generation time of every response to your perceived latency. Also consider voice cloning if your product needs a consistent brand voice, and check whether the provider offers caching for repeated phrases, which cuts latency on common responses like greetings and confirmations.
Orchestrating the pipeline: turn detection and latency handling
Orchestration is where cascaded pipelines succeed or fail. Turn detection decides when the user has finished speaking, and it must balance two errors: cutting the user off mid-thought, and leaving dead air that feels unnatural. Voice activity detection feeds the turn detector, and barge-in handling lets the system stop TTS playback instantly when the user interrupts. A practical latency budget for a responsive agent is under one second from end-of-speech to first spoken syllable, which means every component must stream.
The diagram below shows the full data flow of a cascaded LLM voice AI pipeline:
Evaluating Performance and Latency
Key metrics: word-error-rate, latency, token-per-second
Three metrics dominate any LLM voice AI evaluation. Word error rate (WER) measures transcription accuracy and is usually reported on standard conversational benchmarks; anything above roughly 10 percent on spontaneous speech will produce visible conversational failures. Latency should be measured end-to-end, from the moment the user stops speaking to the first audible response syllable, not per component. Tokens per second measures LLM generation speed, which matters because a model generating 20 tokens per second cannot keep pace with a TTS engine that consumes text faster than that. Track all three together, because optimizing one in isolation usually degrades another: faster, smaller STT models often trade accuracy for speed.
Benchmark sources: Artificial Analysis Speech Arena, LMSYS Chatbot Arena
Avoid vendor marketing pages for performance claims. Artificial Analysis runs a Speech Arena that compares TTS quality and STT accuracy across providers with human preference voting, and its LLM leaderboards track generation speed. LMSYS's Chatbot Arena provides crowd-sourced model rankings useful for judging dialogue quality. For WebRTC-level network performance, webrtcstats.com publishes real-world connectivity data. Cross-referencing at least two of these sources before committing to a provider stack is the cheapest risk reduction available.
Interpreting results for production
Benchmarks are run on clean audio and ideal networks, and production is neither. When interpreting results, discount headline numbers by 15 to 25 percent for real-world conditions: background noise, accented speech, and mobile networks. Run your own evaluation on traffic that matches your users, because a model that tops a benchmark on American English broadcast audio may struggle with multilingual call-center audio. Finally, measure the 95th percentile of your latency, not the average: users remember the worst experience, and averages hide the tail.
Deployment Scenarios: Cloud vs Edge
Cloud-native voice agents with managed APIs
Cloud deployment is the default for most teams. You call managed STT, LLM, and TTS APIs, and the heavy compute lives in the provider's data centers. The advantages are fast iteration, no GPU fleet to manage, and access to the largest models. The trade-offs are per-minute costs that scale with usage, network dependency, and data leaving your infrastructure. For teams building on VideoSDK, the Agent Cloud runs the agent worker as a managed service, while self-hosting the same open-source SDK via Docker or Kubernetes keeps the pipeline in your own infrastructure when compliance requires it.
On-device stacks for privacy and low-bandwidth
On-device voice AI runs smaller quantized models directly on the phone, speaker, or IoT device. This matters for three reasons: privacy (audio never leaves the device), bandwidth (no round trips needed), and offline operation. The cost is capability: on-device LLMs in 2026 are dramatically weaker than frontier cloud models, and on-device TTS quality lags cloud engines. On-device stacks shine for wake-word detection, simple commands, and privacy-sensitive domains like healthcare, while complex reasoning still benefits from a cloud fallback.
Hybrid approaches and cost considerations
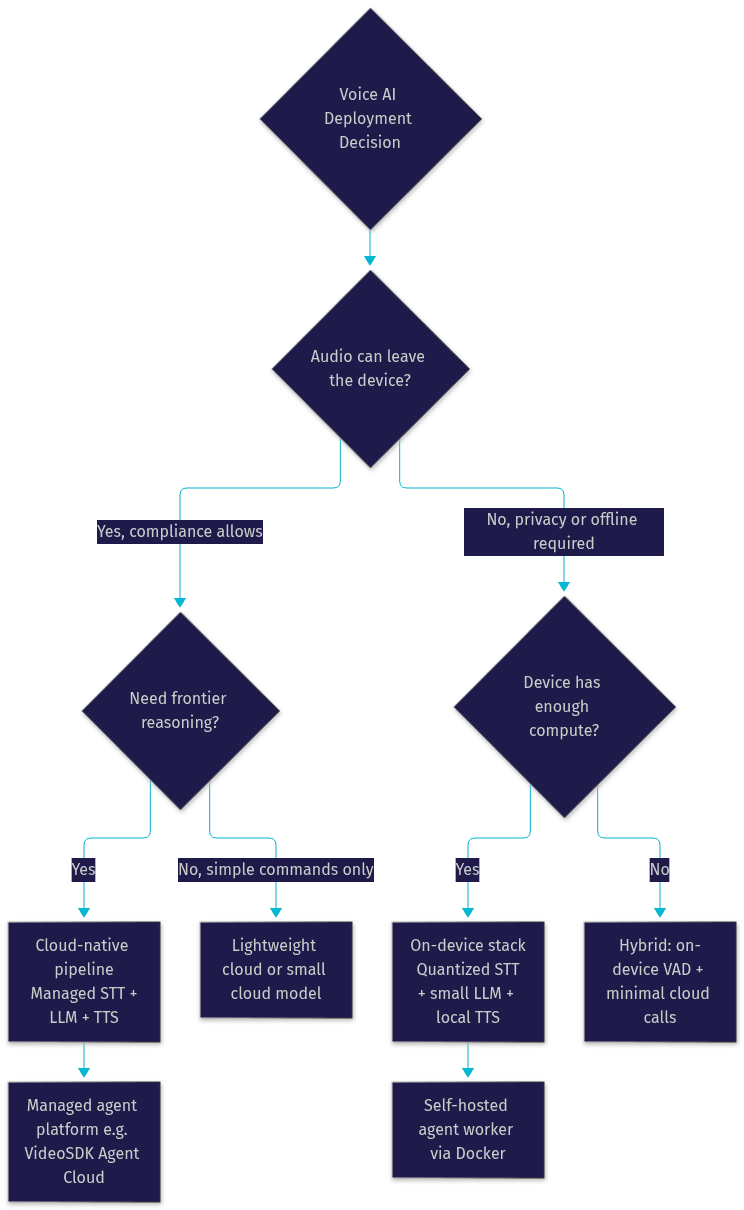
Most production systems end up hybrid: on-device VAD and wake-word detection, cloud STT and LLM for the actual conversation, and edge caching for common responses. This structure cuts cloud costs significantly because silence and non-speech audio never leaves the device.
The decision tree below summarizes the choice:
Real-World Use Cases and Best Practices
Customer support chatbots
Voice agents are replacing legacy IVR trees in call centers. An LLM voice AI agent can look up order status, process returns, and escalate to a human with full conversation context attached. The winning pattern in production deployments is deterministic flow control for regulated steps (payment details, identity verification) combined with LLM flexibility for open-ended questions. VideoSDK's Conversational Graph exists precisely for this: it lets you define the conversation as a directed graph where business rules, not the LLM, control branching, while the LLM handles natural language within each step. Telephony integration via SIP lets the same agent answer regular phone calls through providers like Twilio or Telnyx.
Interactive voice assistants for IoT
Smart speakers, appliances, and vehicles need voice interfaces that work without a screen. Here the constraints are wake-word accuracy, memory footprint, and tolerance for noisy environments. On-device VAD with a cloud LLM is the standard pattern, and VideoSDK's IoT and C++ SDK support covers embedded targets where a browser-based stack is not available.
Multilingual voice agents in education
Language tutoring is one of the most demanding voice AI use cases because the system must understand accented, imperfect speech from learners, and respond with clear pronunciation. STT models with strong multilingual coverage, such as those from Google and ElevenLabs Scribe, handle learner accents better than English-centric models. Pairing the agent with real-time transcription display helps learners see corrections, and VideoSDK's real-time transcription feature supports this directly.
Pitfalls to avoid: token expiry, audio quality, speaker overlap
Four failure modes account for most broken deployments. First, authentication token expiry: agents that run long sessions need token refresh logic, or the session dies mid-conversation. Second, poor input audio: echo, clipping, and low sample rates degrade STT accuracy more than model choice does, so invest in echo cancellation and noise suppression before swapping models. Third, speaker overlap: without proper turn detection, two parties talking simultaneously produces transcriptions the LLM cannot parse. Fourth, ignoring the HTTPS and network requirements of production: WebRTC-based voice needs proper connectivity fallback, which is why VideoSDK includes TURN infrastructure and network-adaptive handling.
Future Directions in LLM Voice AI
Full-duplex conversational models
The biggest architectural shift underway is full-duplex interaction: models that listen and speak simultaneously, like humans do, rather than alternating turns. Google's Gemini Live and OpenAI's Realtime API point toward native speech-to-speech models where the cascaded STT-LLM-TTS chain collapses into one model. Research on full-duplex speech models continues to advance, and by late 2026 the practical gap between cascaded and native speech architectures is narrowing for common use cases, though cascaded pipelines retain the flexibility advantage.
Multimodal extensions: vision plus voice
Voice agents are gaining eyes. Vision-capable models let a user show their camera during a call and ask questions about what is visible, which transforms use cases like remote technical support, telehealth triage, and live shopping. VideoSDK's agent SDK supports vision and multi-modality, so the agent can process frames from a participant's video stream alongside the voice conversation.
Emerging standards for voice agent interoperability
Interoperability is the next frontier: function calling conventions, the Model Context Protocol (MCP) for tool integration, and transport standards for SIP-to-WebRTC bridging are converging on a common layer where agents, tools, and telephony interoperate without bespoke glue code. Teams that build on open standards today will swap components cheaply tomorrow.
Quick Recap and Action Checklist
Core steps to launch your LLM voice AI
- Pick a streaming STT model with strong conversational word-error-rate on your users' audio.
- Pick a dialogue-tier LLM with reliable tool calling and instruction stability.
- Pick a streaming TTS engine and enable caching for common phrases.
- Build or adopt an orchestration layer with turn detection, VAD, and barge-in handling.
- Measure end-to-end latency at the 95th percentile before and after every change.
- Choose cloud, edge, or hybrid deployment based on privacy, bandwidth, and cost.
Resources and next-step links
Start with the VideoSDK AI Agents introduction, explore the open-source agents SDK on GitHub, browse code samples, and join the VideoSDK Discord community of over 3,000 developers building voice agents.
Definitions Glossary
STT (Speech-to-Text): The model that converts spoken audio into text. In an LLM voice AI pipeline, its accuracy sets the ceiling on conversation quality, and streaming STT is required for real-time agents.
TTS (Text-to-Speech): The engine that converts generated text into audible speech. Streaming TTS starts speaking the first sentence while the LLM is still generating the rest, which is essential for low perceived latency.
Turn Detection: The mechanism that decides when a user has finished speaking and the agent should respond. Poor turn detection either cuts users off mid-sentence or leaves unnatural pauses.
Voice Activity Detection (VAD): A lightweight signal-processing layer that distinguishes speech from silence in raw audio, typically running before STT to avoid wasting processing on non-speech segments.
Agent Worker: The Python process that runs a VideoSDK AI agent, managing its session lifecycle inside a VideoSDK room and coordinating the STT, LLM, and TTS pipeline.
Conversational Graph: VideoSDK's deterministic flow engine that defines multi-turn voice conversations as a directed graph, where business rules rather than LLM judgment control branching between steps.
Key Takeaways
- LLM voice AI chains STT, an LLM, and TTS, but orchestration (turn detection, VAD, barge-in) determines whether the agent feels natural in production.
- Measure end-to-end latency from end-of-speech to first spoken syllable at the 95th percentile, not component averages.
- Use independent benchmarks like Artificial Analysis Speech Arena and LMSYS Chatbot Arena rather than vendor marketing when choosing STT, LLM, and TTS providers.
- Cloud deployment wins for frontier reasoning and fast iteration; on-device wins for privacy, bandwidth, and offline use; most production systems are hybrid.
- VideoSDK's open-source AI Agent SDK provides the full pipeline, turn detection, and telephony integration so you can swap providers without rebuilding orchestration.
Conclusion
LLM voice AI in 2026 is a solved problem at the component level and an engineering problem at the orchestration level. The STT, LLM, and TTS markets are mature and benchmarked, so your differentiation comes from latency discipline, interruption handling, and deployment choices that match your users' constraints. The fastest path to a working agent is to adopt an orchestration layer rather than build one: sign up free at app.videosdk.live/login, read the AI Agents docs, and have a voice agent running against your choice of providers in an afternoon. What are you building with LLM voice AI? Drop a comment, I'd love to hear what kind of voice agent use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ