


An LLM for sales automation is a large language model integrated into your sales workflow to draft personalized outreach, qualify leads, detect conversation stages, and update your CRM with minimal human effort. The winning architecture pairs the model with retrieval-grounded product data, tool access to your CRM, and rule-based compliance gates. Developers who get the orchestration layer right see reply rates climb while token costs and hallucination incidents stay measurable and low.
Sales teams generate enormous amounts of unstructured work: automated prospecting, writing emails, logging calls, deciding who to follow up with and when. That work is exactly what large language models are good at, which is why LLM-driven sales tooling went from novelty to mainstream between 2023 and 2026. For developers, this shift creates a genuinely interesting engineering problem, because a sales LLM is not just a chatbot. It is a stateful, tool-using, compliance-constrained agent that has to perform under real business stakes.
This guide walks through the full stack: what an LLM actually contributes to sales automation, the core components of a production system, how to build a context-aware agent that knows which sales stage a conversation is in, how to keep it compliant and grounded, and how to measure whether it is working. By the end, you will have a clear architectural roadmap you can implement with any modern LLM provider or open-source model.
What Is an LLM and Why It Matters for Sales Automation
A large language model is a neural network trained on massive text corpora to predict and generate natural language. Modern LLMs, such as OpenAI's GPT family, Anthropic's Claude, and Google's Gemini, can draft coherent emails, summarize long conversation histories, classify text into categories, and extract structured data from messy inputs. Those four capabilities map almost perfectly onto the repetitive core of sales work.
LLM for sales automation matters because it attacks the highest-volume, lowest-judgment tasks first. Outreach personalization, where the model weaves firmographic details into a first-touch email, is the classic example. Qualification is another: an LLM can read a prospect's reply, infer intent, and route the lead to the right stage without a human scanning every inbox. Follow-up sequencing, meeting scheduling, and CRM hygiene all benefit from the same pattern.
The economic argument is straightforward. A human SDR might send 50 to 100 researched emails a day. A well-built LLM pipeline drafts thousands of personalized messages in the same period, with a human approving the exceptions. The model does not replace judgment; it removes the typing.
Why LLM for Sales Automation Is Transforming Your Revenue
The reason LLM for sales automation is transforming revenue operations is that it changes the cost curve of personalization. Before LLMs, deeply personalized outreach scaled linearly with headcount. Now it scales with compute, and compute is cheap relative to a sales salary. Teams that treat the LLM as an orchestration component rather than a magic text box consistently report higher reply rates, faster lead response times, and cleaner CRM data.
There is a second-order effect too. Because the LLM reads every conversation, it produces structured signal from unstructured text: stage labels, objection themes, sentiment shifts. That signal feeds forecasting and routing decisions that were previously gut-feel territory.
Core Components of an LLM-Powered Sales Automation Stack
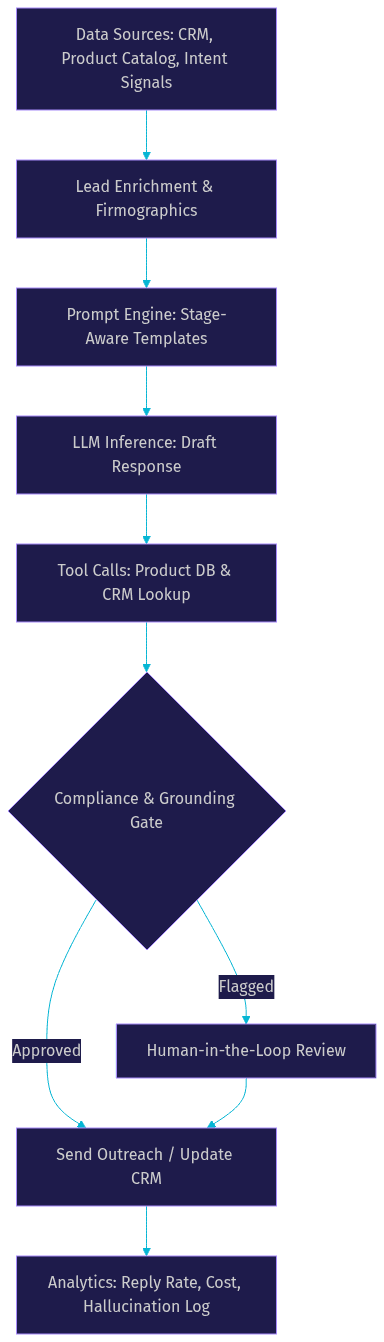
A production LLM sales stack has four building blocks: data sources, a prompt library, tool integration, and an orchestration layer. Data sources include your CRM, product catalog, automated prospecting, and intent-signal feeds. The prompt library encodes your messaging strategy as versioned, testable templates. Tool integration lets the model read and write external systems instead of guessing. The orchestration layer ties everything together, managing state, retries, budget caps, and human approval gates.
The flow through the system is linear and auditable: prospect data enters, the prompt engine assembles context, the LLM generates a response, tools verify and ground it, and the result lands back in the CRM.
Data Ingestion and Lead Enrichment
The LLM is only as good as the context you feed it. Lead enrichment pipelines pull firmographics (company size, industry, funding stage), technographics (which tools the prospect already uses), and behavioral intent signals (pricing page visits, content downloads) from providers and your own analytics. Normalize this data into a structured prospect profile before it ever reaches the prompt. Enriched, deduplicated context is the single biggest lever on output quality, because a model writing to a rich profile produces specific, relevant copy while a model writing to a bare name and email produces generic filler that gets ignored.
LLM for Sales Automation: Prompt Engineering
Prompt engineering for sales is about stage awareness. A first-touch prompt should emphasize brevity, a single relevant hook, and a soft ask. A negotiation-stage prompt should reference the specific objection, the pricing context, and the timeline. Keep prompts versioned like code, with a small evaluation set of real conversations you rerun on every prompt change. Include few-shot examples of your best human-written emails so the model learns your voice, and always constrain output length, because unbounded LLMs drift toward three-paragraph emails nobody reads.
Building a Context-Aware Sales Agent
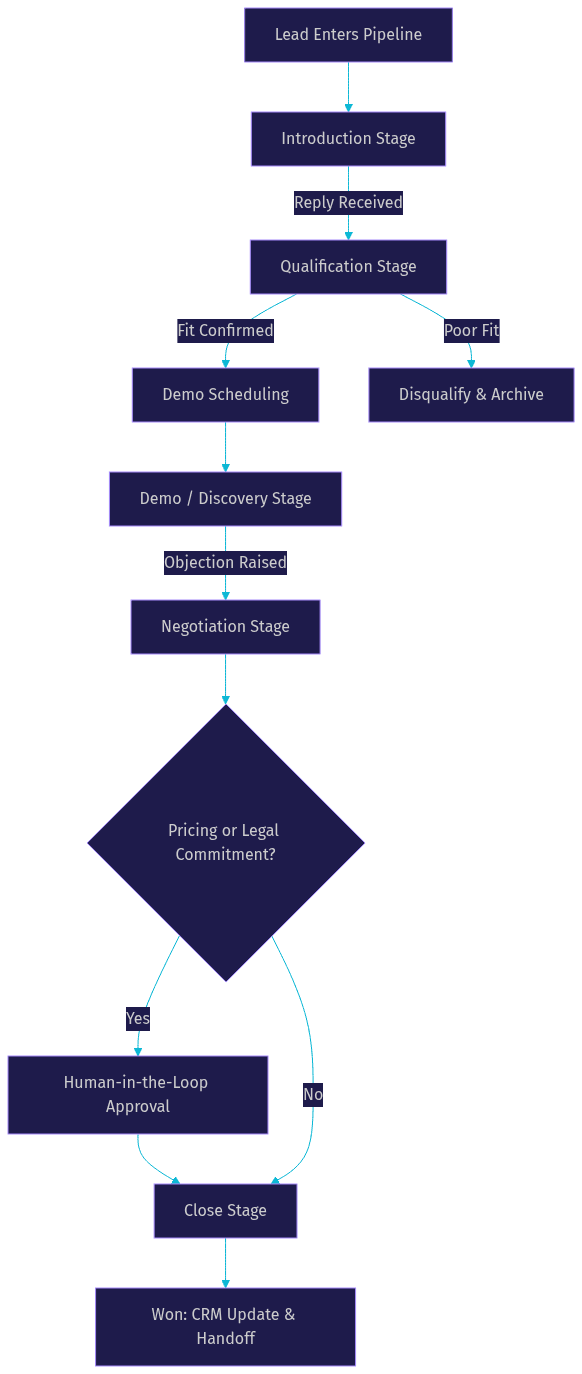
A context-aware sales agent is a stateful system that knows which conversation it is in, which stage that conversation has reached, and which actions are appropriate at that stage. The architecture has three layers: a conversation store holding full history and extracted facts, a stage classifier that labels the current state, and a response generator whose prompts are selected by that label. Tool access sits underneath, letting the agent pull live product data and CRM records rather than relying on memorized, possibly stale knowledge.
The state machine below shows how the agent moves a deal through stages, with human approval gates at the transitions that carry legal or pricing risk.
Conversation Stage Detection
Stage detection is a classification problem you can solve cheaply. The simplest robust approach is a dedicated LLM call with few-shot examples: show the model five to ten labeled conversation snippets spanning introduction, qualification, demo, negotiation, and close, then ask it to label the current thread and return a structured result. For higher volume, run a smaller, fine-tuned classifier and reserve the large model for generation. Log every stage transition, because misclassified stages are the root cause of most tone-deaf automated replies, such as sending a cheerful first-touch template to someone who just asked for a discount.
Tool Use: Product Catalog and CRM Lookup
Tool-augmented LLM agents hallucinate less because they do not need to recall facts from training data; they look them up. Give the agent callable access to your product database for pricing, feature availability, and documentation, and to your CRM API for deal history, contact roles, and prior interactions. When a prospect asks whether your platform supports a specific integration, the agent queries the catalog and answers from the result. This is retrieval-augmented generation applied to sales, and it is the difference between an agent that occasionally invents a feature and one that never does. Log every tool call for auditability.
Managing Compliance and Hallucination Risks
Sales automation operates inside a dense regulatory perimeter. CAN-SPAM in the United States governs commercial email, including opt-out handling and accurate sender identity. GDPR in Europe restricts how you process prospect personal data and requires a lawful basis for automated outreach. TCPA tightly regulates automated calls and texts in the US, with statutory damages per violation that make careless SMS automation genuinely expensive. Similar rules exist elsewhere, such as CASL in Canada and PECR in the UK.
The engineering answer is layered safeguards. First, rule-based gates that run before any message is sent: suppression-list checks, opt-out verification, jurisdiction checks, and sending-hour windows. These should be deterministic code, not LLM judgment, because compliance is exactly the place where you do not want probabilistic behavior. Second, human-in-the-loop approval for anything risky: pricing commitments, legal language, or outreach to enterprise accounts with sensitive relationships. Third, retrieval-augmented generation so factual claims are grounded in your product data rather than model memory.
For hallucination mitigation specifically, keep a logged incident register. When the agent states something factually wrong, capture the prompt, the output, and the correction. Feed recurring failure patterns back into your prompt library and evaluation set. Teams that treat hallucinations as a measurable defect rate, rather than an embarrassment, converge on reliable systems much faster.
Deployment Options: Cloud vs Self-Hosted
Cloud LLM APIs from OpenAI, Anthropic, and Google offer the fastest path: state-of-the-art model quality, managed scaling, and per-token pricing that is trivially cheap for text outreach. Latency for a single email draft is typically a few hundred milliseconds to a couple of seconds, which is fine for asynchronous email but marginal for real-time voice. The trade-off is that prospect data leaves your infrastructure, which matters for GDPR-heavy pipelines and enterprise customers with data residency clauses.
Self-hosted open-weight models, such as Meta's Llama family or Mistral's models, flip those trade-offs. You keep all data on-premise, you control latency end to end, and marginal inference cost drops to hardware amortization at high volume. The cost is operational: you need GPU capacity, serving infrastructure, and an evaluation pipeline to know when a smaller model is good enough. A common 2026 pattern is hybrid routing: a small self-hosted model handles classification and stage detection, while a frontier cloud model handles high-value generation.
Measuring Success: Metrics and KPIs
Treat the LLM pipeline like any production system: instrument it. The business metrics are reply rate, positive-reply rate, meeting-booking conversion, and average deal size for LLM-assisted versus human-only sequences. The operational metrics are LLM token cost per outreach, end-to-end latency per generated message, stage-classification accuracy against a labeled sample, and hallucination incident rate per thousand sends.
Two ratios deserve dashboards of their own. Cost per booked meeting, which combines token spend, enrichment fees, and human review time, tells you whether the automation is actually cheaper than headcount. Hallucination rate trend tells you whether your grounding and prompt improvements are working. If reply rates rise while hallucination incidents stay flat, you are winning. If both rise together, you are buying engagement with credibility, and that trade eventually collapses.
Common Pitfalls and Best Practices
The most frequent failure mode is over-prompting: stuffing every available datapoint into the context window until the model produces bloated, unfocused output. More context is not better; relevant context is better. The second is ignoring token limits and cost ceilings, where a runaway loop or an oversized history silently inflates spend. The third, and most dangerous, is missing compliance gates, where a technically impressive pipeline sends messages that violate opt-out lists or jurisdiction rules.
A practical best-practice checklist: version and test every prompt against a fixed evaluation set before deployment. Enforce deterministic compliance checks in code before any send. Cap daily send volume and per-prospect message counts. Route pricing and legal language through human approval. Ground all factual claims in tool lookups, never model memory. Log every generated message, tool call, and stage transition for audit. Monitor cost and hallucination metrics weekly, and roll back prompt versions that regress either one.
Future Trends: Real-Time LLMs and Multi-Channel Automation
The frontier is moving from asynchronous drafting to real-time interaction. Real-time multimodal APIs, such as OpenAI's Realtime API and Google's Gemini Live, enable voice-enabled sales agents that can hold a natural qualification call, detect objections from tone, and book meetings mid-conversation. Platforms like VideoSDK now let developers connect these LLM pipelines directly into live voice and video rooms, so an AI sales agent can join a web call, listen, and assist or respond in real time with sub-second latency.
The second trend is unified omnichannel orchestration: one agent maintaining coherent state across email, SMS, LinkedIn, and website chat, so a prospect gets a consistent conversation regardless of channel. The engineering challenge shifts from generating good text to maintaining a single, shared conversation state graph across every touchpoint, which is exactly the context-aware agent architecture described above, extended to more channels.
Definitions Glossary
LLM (Large Language Model): A neural network trained on massive text datasets that generates and classifies natural language. In sales automation it drafts outreach, classifies conversation stages, and extracts structured data from replies.
Context-Aware Sales Agent: A stateful LLM system that tracks which sales stage a conversation has reached and selects prompts and actions appropriate to that stage.
Retrieval-Augmented Generation (RAG): A technique where the model answers from retrieved documents or live tool lookups rather than training memory, sharply reducing hallucinated product claims.
Human-in-the-Loop (HITL): A design pattern where risky agent actions, such as pricing commitments or legal language, pause for human approval before execution.
Stage Detection: Classifying a sales conversation into introduction, qualification, demo, negotiation, or close, typically via a few-shot LLM call or a fine-tuned classifier.
Tool-Augmented Agent: An LLM that can call external systems, such as a product database or CRM API, to ground its responses in live, accurate data.
Key Takeaways
- An LLM for sales automation works best as an orchestrated agent with data ingestion, a versioned prompt library, tool access, and compliance gates, not as a standalone text generator.
- Stage detection is the backbone: labeling each conversation as introduction, qualification, demo, negotiation, or close keeps every generated message contextually appropriate.
- Ground all factual claims through tool lookups into your product catalog and CRM; never let the model answer pricing or feature questions from memory.
- Compliance safeguards must be deterministic code, with human-in-the-loop approval for pricing, legal language, and sensitive accounts.
- Measure reply rate, cost per booked meeting, and hallucination incidents per thousand sends; roll back any prompt version that regresses them.
Conclusion
LLM for sales automation is a strategic investment because it converts your most expensive repetitive work, personalized outreach, qualification, and follow-up, into a measurable, instrumented pipeline. The roadmap is consistent: enrich your data, build stage-aware prompts, ground the agent in tools, gate it with deterministic compliance checks, and measure everything. Start with a single channel, prove the metrics, then expand into real-time voice and omnichannel orchestration. If you want to explore how real-time voice agents fit into this stack, the VideoSDK AI Agents documentation is a solid next read, and the VideoSDK quickstart lets you spin up a free tier in minutes. What are you building with LLMs in your sales stack? Drop a comment, I'd love to hear which channel you are automating first.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ