


Self hosted LLMs are large language models that run on infrastructure you control, whether a workstation GPU, an on-premise server, or a private Kubernetes cluster, instead of a vendor API. Teams choose self hosting for privacy, predictable cost, and full control over model behavior. A complete stack needs four layers: a model, a runtime engine like Ollama or vLLM, a serving layer with an OpenAI-compatible API, and a UI or agent framework on top.
Running your own large language model used to be a research project. In 2026, it is a routine engineering decision. The tooling has matured, open-weight models have closed most of the quality gap with frontier cloud APIs, and the economics have flipped for teams with steady inference volume.
The drivers are familiar. Privacy regulations make sending customer data to a third-party API a legal review exercise. Per-token pricing turns a popular internal feature into a runaway bill. And product teams want control over model versions, fine-tuning, and tool-calling behavior that a hosted endpoint simply cannot offer.
This guide walks through the full self-hosted LLM stack: why it makes sense, what each layer does, how to plan hardware, and how to deploy, scale, and secure a production setup.
Why Choose Self-Hosted LLMs?
Self hosted LLMs trade operational responsibility for privacy, cost predictability, and control. For most teams, the decision comes down to data sensitivity and inference volume.
Privacy & Data Sovereignty
For healthcare, finance, legal, and government workloads, data leaving your perimeter is a compliance problem before it is a technical one. HIPAA, GDPR, and sector-specific rules often require data processing agreements, audit trails, and regional data residency that a shared cloud inference endpoint cannot always satisfy.
Self hosting keeps every prompt, every document chunk, and every generated token on hardware you own. Nothing crosses a vendor boundary, so there is no third party to audit and no data processing agreement to negotiate. Internal incident response and log retention policies apply directly, because the LLM is just another service in your infrastructure.
Cost Efficiency at Scale
Cloud inference is cheap for sporadic use and expensive for steady traffic. A per-token API that costs pennies per request becomes a significant monthly line item once an internal assistant serves hundreds of employees or an agent pipeline runs thousands of calls per day.
Self hosting inverts the model: you pay a fixed hardware cost and marginal electricity, and every additional token is effectively free. The crossover point depends on volume, but teams running consistent daily workloads often recover hardware costs within months.
| Scenario | Cloud API (monthly) | Self-Hosted (monthly) | Break-even |
|---|---|---|---|
| Light use, 1 team, ~10K requests | Low, pay-as-you-go | High fixed hardware cost | Rarely breaks even |
| Internal assistant, ~500K requests | Moderate and growing | Fixed amortized hardware | 3 to 6 months |
| Agent pipeline, millions of calls | Very high, unpredictable | Fixed plus power and maintenance | 1 to 3 months |
The honest caveat: self hosting shifts cost from opex to capex and adds an engineering time cost. If your traffic is spiky and unpredictable, elastic cloud capacity may still win.
Full Control & Customization
Self hosting means you decide everything. You pin a model version so a vendor update never silently changes your product's behavior. You fine-tune on proprietary data without sharing it with anyone. You expose exactly the tool-calling interface, system prompts, and sampling parameters your application needs.
You also get freedom at the API layer. Most self-hosted runtimes expose OpenAI-compatible endpoints, which means your existing application code, agent frameworks, and evaluation harnesses work unchanged. Swapping a cloud model for a local one becomes a configuration change, not a rewrite.
Core Components of a Self-Hosted LLM Stack
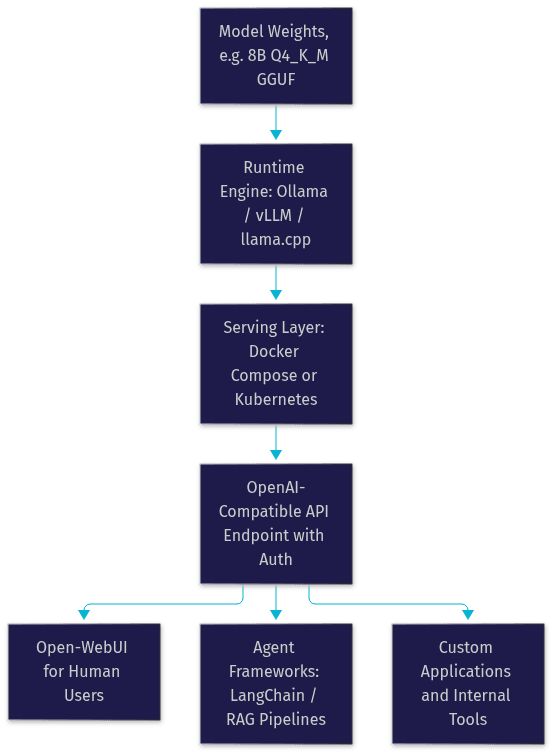
A self-hosted LLM stack has four layers: the model itself, the runtime that executes it, the serving layer that exposes it, and the interface layer where users and agents consume it.
Runtime Engines (vLLM, llama.cpp, Ollama, LocalAI)
The runtime is the inference engine, and choosing one is the most consequential decision in your stack.
vLLM is the production workhorse. It uses paged attention to deliver high throughput and supports continuous batching, which lets it serve many concurrent requests efficiently. It is the default choice for multi-user production serving on NVIDIA GPUs.
llama.cpp is the lightweight champion. It runs quantized models on CPUs, Apple Silicon, and modest GPUs, making it ideal for edge devices, laptops, and low-resource servers. Its GGUF model format has become the de facto standard for distributed open-weight models.
Ollama wraps llama.cpp in a friendly package. It handles model downloads, versioning, and a local API out of the box, which makes it the best starting point for developers experimenting on their own machines.
LocalAI positions itself as a drop-in self-hosted replacement for cloud APIs, supporting multiple model families and an OpenAI-compatible surface with minimal setup.
Model Management & Quantization
Model selection means balancing quality, size, and license. Open-weight families like Llama, Mistral, and Qwen span sizes from 1B to over 100B parameters, and most are available in quantized GGUF or safetensors formats.
Quantization reduces the precision of model weights to shrink memory footprint and increase speed at a modest quality cost. Common levels include 4-bit variants like Q4KM, which cut memory roughly to a quarter of full precision with small quality loss, 8-bit variants that preserve nearly all quality, and full FP16, which is only practical for smaller models or large multi-GPU setups. A practical rule: start at 4-bit for experimentation, move to 8-bit if quality matters and memory allows, and reserve FP16 for fine-tuning workflows.
Serving Frameworks & APIs
The serving layer turns a runtime into a network service. In practice this means running the engine behind an OpenAI-compatible endpoint so that any client built for the cloud API works against your local model.
For small deployments, a simple containerized arrangement is enough: the model runtime and the user interface each run as their own service on a shared private network, with the interface reaching the model by its service name. For production, Kubernetes becomes attractive. Operators like LLMKube schedule model workloads across GPU nodes, handle replica scaling, and integrate with standard cluster tooling. The choice is mostly about scale: keep the simple single-host arrangement until you need multiple nodes, autoscaling, or rolling model updates.
UI & Integration Layers (Open-WebUI, LM Studio, LangChain, Agent Frameworks)
The top layer is where humans and software meet the model. Open-WebUI provides a polished ChatGPT-style interface with user management, document upload, and RAG built in, and it connects to Ollama or any OpenAI-compatible backend. LM Studio serves desktop users who want a GUI for model management and local inference.
For programmatic use, frameworks like LangChain, LlamaIndex, and multi-agent libraries consume the same OpenAI-compatible endpoint. This is where self hosting shines for agents: your agent's LLM calls, tool executions, and retrieval steps all stay inside your network. Teams building voice or meeting AI can go further, connecting a private LLM to real-time communication platforms, for example pairing a self-hosted model with VideoSDK's AI agent infrastructure so the model, the speech pipeline, and the live media session all run under one roof.
The full stack flows in one direction, from model weights to the user-facing interface:
Hardware Planning for Self-Hosted LLMs
Hardware planning is mostly a VRAM arithmetic problem, with a GPU ecosystem decision layered on top.
VRAM Requirements by Model Size
A useful rule of thumb: full-precision (FP16) inference needs roughly 2 GB of VRAM per billion parameters, while 4-bit quantization needs roughly 0.5 to 0.6 GB per billion, plus overhead for the context window.
| Model size | FP16 VRAM | 4-bit quantized VRAM | Typical hardware |
|---|---|---|---|
| 7-8B | ~16 GB | ~5-6 GB | Single RTX 4060/4070 or MacBook |
| 13-14B | ~28 GB | ~9-10 GB | RTX 4070 Ti or better |
| 32-34B | ~68 GB | ~20-22 GB | RTX 4090 or 2x 3090 |
| 70B | ~140 GB | ~40-45 GB | Dual 3090/4090 or A100/H100 |
Context length adds memory on top of these figures, so a long-context RAG workload needs headroom beyond the base model footprint.
GPU Choices (NVIDIA, AMD, Apple Silicon)
NVIDIA remains the path of least resistance. CUDA support is first-class in every major runtime, and vLLM in particular is optimized around it. AMD has made real progress with ROCm, and llama.cpp runs well on recent Radeon cards, but you should verify runtime support for your specific card before buying. Apple Silicon is a genuinely viable option for personal and small-team use: unified memory lets a Mac Studio with 128 GB of RAM load models that would need multiple discrete GPUs, and the Metal backend in llama.cpp and Ollama performs well for single-user workloads.
Cost-Effective Build Options
Three tiers cover most teams. A consumer build around a single RTX 4090 (24 GB VRAM) comfortably serves 8B to 14B models for a small team. A prosumer build with dual used RTX 3090s delivers 48 GB of VRAM for the price of one new 4090, enough for 32B models and light 70B serving. For teams that want to avoid hardware ownership entirely, cloud GPU instances from providers like Lambda, RunPod, or AWS give you self-hosted software semantics on rented hardware, which is a reasonable middle ground for evaluation phases.
Step-by-Step Deployment Guide
This walkthrough covers the full path from model choice to a working, API-driven deployment. Every step is described in prose; consult the linked documentation for exact commands.
1. Pick a Model & Quantization
Start from your use case, not the leaderboard. For chat and general assistance, a 7B to 14B model at 4-bit quantization is a strong starting point that runs on a single consumer GPU. For code review or complex reasoning, a 32B or 70B model justifies the extra hardware. Check the model's license for commercial use, confirm the runtime supports its format, and prefer well-maintained quantized releases from the model publisher over random community uploads.
2. Choose a Runtime
The decision is straightforward once you know your constraints. Choose Ollama if you are a beginner or want the fastest path from zero to a working local model; it handles downloads and serving automatically. Choose vLLM for production multi-user serving on NVIDIA GPUs, where its throughput and batching advantages matter most. Choose llama.cpp for low-resource environments, CPU-only servers, or Apple Silicon, and choose LocalAI when you need broad drop-in API compatibility across model types.
3. Set Up the Serving Layer
For a first deployment, run the runtime as a container alongside your UI in a Compose-style setup: define the model service, expose its internal port to the shared network, and let the UI container reach it by service name. For production, move to Kubernetes with an operator like LLMKube, which manages model loading as a custom resource, schedules workloads onto GPU nodes, and supports replica scaling and rolling updates. The migration path is clean because both approaches expose the same OpenAI-compatible API.
4. Expose an OpenAI-Compatible API
Configure the runtime through environment settings: the host binding (listen only on the internal network, not the public internet), the port, and an API key requirement so that every request is authenticated. Place a reverse proxy in front for TLS termination, and restrict which model endpoints are available. The goal is that your local endpoint is indistinguishable from a cloud API from the client's perspective, so existing SDKs and agent frameworks connect without modification. VideoSDK developers building agent experiences can follow the same pattern when wiring private models into real-time communication pipelines.
5. Add a Web UI or Agent Framework
Finally, put a face on the stack. Deploy Open-WebUI pointed at your API endpoint for human users; it gives you chat, document upload, RAG, and multi-user management out of the box. For programmatic consumers, connect LangChain or your preferred agent framework to the same endpoint, and start building retrieval pipelines and tool-calling agents. Because everything speaks the OpenAI-compatible protocol, you can add consumers without touching the serving layer.
Scaling & Monitoring
Scaling a self-hosted LLM is about concurrency and queue depth, not raw request count.
Autoscaling with Kubernetes and vLLM Metrics
On Kubernetes, a Horizontal Pod Autoscaler can scale model replicas based on GPU utilization or queue-based custom metrics. vLLM exposes token throughput and pending-request metrics that make good autoscaling signals: scale on waiting queue length rather than CPU, because an overloaded LLM shows high latency long before it shows high CPU. Set a maximum replica count that matches your GPU budget, and use pod anti-affinity so replicas spread across nodes.
Monitoring Tools
Prometheus plus Grafana is the standard pairing. Most runtimes expose metrics endpoints natively, and community dashboards exist for vLLM and Ollama covering tokens per second, time to first token, request latency, and cache hit rates. Track four things at minimum: request latency, throughput, queue depth, and GPU memory headroom.
Alerting for Silent Failures
The dangerous failures in LLM serving are silent: the model still responds, just slowly, or with degraded quality after a bad model swap. Alert on latency percentiles, not averages, and alert when time-to-first-token crosses a threshold, because that is what users actually feel. Add an alert for model version drift so an unpinned update never reaches production unnoticed.
Security & Maintenance Best Practices
Treat your LLM endpoint like any other internal service that handles sensitive data.
Network isolation: keep the model endpoint on an internal network, never directly internet-exposed. Terminate TLS at a reverse proxy, require API keys on every request, and rotate them like database credentials.
Maintenance discipline: pin model versions explicitly so updates are deliberate, not accidental. Back up model weights and any fine-tuned artifacts, since regenerating a fine-tune is expensive. Schedule runtime updates during low-traffic windows and validate output quality after each change.
Compliance auditing: retain request logs with appropriate retention policies, and log enough to answer "who asked the model what" without storing raw sensitive prompts longer than your policy allows. For regulated industries, this audit trail is often the reason self hosting was chosen in the first place.
Real-World Use Cases
Internal knowledge base chatbot: a legal or HR team deploys a 14B model with RAG over internal policy documents. Employees get instant answers, and no document ever leaves the company network. Open-WebUI plus Ollama on a single GPU server covers this completely.
Automated code reviewer: a platform team runs a 32B code-specialized model behind an internal API, wired into pull request workflows. Every review runs on private code, with consistent behavior because the model version is pinned.
Multi-step data extraction agent: a finance operations team builds an agent that reads invoices, extracts structured fields, and writes to internal systems. The LLM calls, tool executions, and document data all stay on-premise, satisfying data residency requirements that a cloud API could not.
Definitions Glossary
Self-hosted LLM: A large language model that runs on infrastructure you own or control, such as a workstation, on-premise server, or private cloud, rather than through a third-party inference API.
Quantization: The process of reducing the numerical precision of model weights, for example from 16-bit to 4-bit, to shrink memory requirements and increase inference speed at a small cost in output quality.
GGUF: A single-file model format used by llama.cpp and Ollama that packages quantized model weights with metadata, making open-weight models easy to distribute and load.
vLLM: A high-throughput inference engine that uses paged attention and continuous batching, designed for serving many concurrent requests in production on NVIDIA GPUs.
Ollama: A beginner-friendly local LLM runtime that handles model downloads, management, and an OpenAI-compatible local API, built on top of llama.cpp.
OpenAI-compatible API: An endpoint that mimics the request and response format of OpenAI's API, allowing existing SDKs, agent frameworks, and tools to work with any self-hosted model without code changes.
Key Takeaways
- Self hosted LLMs give you privacy, predictable fixed costs, and full control over model versions, fine-tuning, and behavior, at the price of operational responsibility.
- A complete stack has four layers: model weights, a runtime engine (Ollama, vLLM, llama.cpp, or LocalAI), a serving layer with an OpenAI-compatible API, and a UI or agent framework on top.
- Plan hardware as a VRAM arithmetic problem: roughly 2 GB per billion parameters at FP16, or about a quarter of that at 4-bit quantization.
- Start with Ollama for experimentation, move to vLLM on Kubernetes when concurrency and reliability requirements grow.
- Monitor latency percentiles, queue depth, and time-to-first-token, because the dangerous failures in LLM serving are silent.
Conclusion
Self hosted LLMs in 2026 are a practical option for any team with privacy requirements, steady inference volume, or a need for control that cloud APIs cannot provide. The stack is mature, the models are capable, and the tooling, from Ollama to vLLM to Kubernetes operators, has removed most of the friction. Start small: pick a 7B or 8B model, run it locally with Ollama, and iterate toward a production serving layer as your requirements grow. When you are ready to connect your private models to real-time applications, explore VideoSDK's AI agent documentation and the code samples library. What are you building with self hosted LLMs? Drop a comment, I would love to hear what kind of private AI use case you are working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ