


Noise cancellation AI uses deep learning models and adaptive filtering to remove unwanted background sounds from audio streams in real time. Unlike traditional active noise control, AI-driven approaches learn noise patterns dynamically and adapt to changing acoustic environments. VideoSDK integrates built-in noise suppression directly into its video calling SDK, letting developers ship clean audio without training custom models.
The demand for crystal-clear audio in real-time communication has never been higher. A 2024 study by Cornell University found that background noise in video calls reduces participant comprehension by up to 27 percent and increases cognitive load significantly. For developers building conferencing apps, telehealth platforms, or voice-based customer support tools, poor audio quality is no longer just an annoyance. It is a measurable drag on user retention, productivity, and accessibility.
Noise cancellation AI has emerged as the practical answer. Instead of relying on fixed-frequency filters that struggle with non-stationary noise like keyboard typing or passing traffic, AI-driven systems use neural networks to predict and suppress unwanted sounds frame by frame. This article walks through the core technologies, system architecture, real-world use cases, performance benchmarks, and implementation considerations that developers and product managers need to understand before integrating noise cancellation AI into their applications.
What Is Noise Cancellation AI?
Noise cancellation AI is defined as the application of machine learning models, particularly deep neural networks, to identify and remove unwanted acoustic signals from an audio stream. Traditional active noise cancellation (ANC) relies on fixed digital signal processing algorithms that generate anti-phase signals to cancel predictable, low-frequency noise. AI-augmented noise cancellation works by learning complex noise patterns from training data and applying that knowledge to suppress noise that classical filters cannot handle.
The core difference is adaptability. Classical ANC assumes noise is relatively stationary. Noise cancellation AI assumes the opposite: that noise changes constantly and unpredictably. Deep learning models trained on diverse noise datasets can distinguish human speech from background interference with high accuracy, even in conditions where traditional filters fail completely. VideoSDK provides AI-powered noise suppression through its real-time communication SDK, enabling developers to embed this capability without building custom ML pipelines.
Core Technologies Behind AI Noise Cancellation
Two technology stacks power modern noise cancellation AI: deep learning models for noise prediction and AI-guided adaptive filtering. Most production systems combine both approaches to balance accuracy with real-time performance constraints.
Deep Learning Models for Noise Prediction
Convolutional neural networks (CNNs) excel at extracting spatial features from spectrograms, making them effective for identifying noise patterns in frequency-domain representations. Recurrent neural networks (RNNs), particularly long short-term memory (LSTM) architectures, capture temporal dependencies in audio signals, allowing the model to predict how noise will evolve over the next few milliseconds. Transformer-based models have recently entered this space, using self-attention mechanisms to model long-range audio context with greater accuracy than RNNs.
In practice, developers rarely train these models from scratch. Open-source pretrained models like RNNoise (developed by Mozilla) and DeepFilterNet provide strong baselines that can be fine-tuned for specific noise environments. The choice depends on the target platform. CNN-based models tend to be smaller and faster for on-device inference, while transformer models deliver higher accuracy but require more computational resources.
Adaptive Filtering with AI Guidance
Classical adaptive filters like least mean squares (LMS) and Kalman filters have been used for decades in noise reduction. They work by iteratively adjusting filter coefficients to minimize the difference between the desired signal and the observed input. The limitation is that these filters converge slowly when noise characteristics change rapidly.
Noise cancellation AI solves this by using neural networks to predict optimal filter coefficients in real time. Instead of waiting for the filter to adapt through error feedback, the AI model estimates the current noise profile and sets filter parameters proactively. This reduces convergence time from hundreds of milliseconds to single-digit milliseconds, which is critical for real-time communication where any audible delay degrades the conversation.
System Architecture of an AI-Powered Noise Cancellation Solution
A production-grade noise cancellation AI pipeline follows a straightforward signal flow: audio capture, feature extraction, AI inference, adaptive filtering, anti-noise generation, and speaker output. Each stage must complete within a strict time budget to avoid introducing perceptible latency.
The microphone captures raw audio frames, typically 10 to 20 milliseconds in length. A feature extraction stage converts these frames into a format the AI model can process, usually a log-mel spectrogram or raw waveform representation. The AI model then predicts the noise component present in the current frame. An adaptive filter controller uses this prediction to generate an anti-noise signal that, when combined with the original audio, cancels out the unwanted sounds. The cleaned signal is sent to the speaker or transmitted over the network.
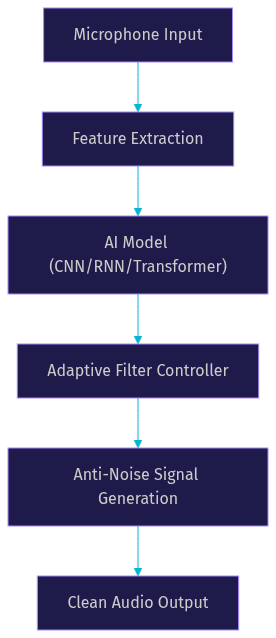
For developers building real-time communication apps, this entire pipeline must run in under 5 milliseconds per frame to avoid noticeable echo or lag. VideoSDK handles this processing internally through its media pipeline architecture, which includes built-in noise suppression as part of the video calling SDK infrastructure.
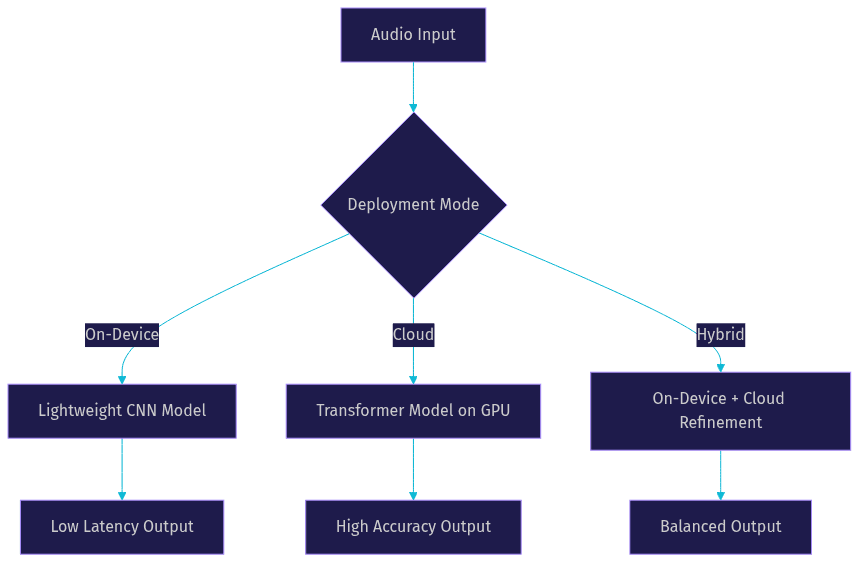
The deployment architecture also matters. Developers must choose between on-device processing, cloud-based inference, and hybrid approaches depending on their latency requirements and target platforms.
Real-World Use Cases for Noise Cancellation AI
Mobile Voice Calls and Video Conferencing
Video conferencing platforms like Zoom, Microsoft Teams, and Google Meet have made AI noise suppression a baseline expectation. Users joining calls from coffee shops, airports, or open offices expect the application to filter out ambient noise automatically. For developers building custom conferencing apps with SDKs like VideoSDK's video calling API, built-in noise suppression eliminates the need to integrate a separate audio processing library. The SDK applies AI-based noise reduction to each participant's audio track before transmission, reducing bandwidth consumption and improving call quality for all participants.
Automotive Cabin Noise Reduction
Automotive manufacturers are increasingly turning to noise cancellation AI to reduce cabin noise from engines, road surfaces, and wind. Unlike headphone ANC, which operates in a small enclosed space, automotive ANC must handle a larger acoustic environment with multiple microphones and speakers. AI models trained on vehicle-specific noise profiles can predict engine RPM-related noise and road surface vibrations, generating counter-signals through the car's speaker system. This application requires ultra-low-latency inference, typically under 2 milliseconds, because the cancellation signal must reach the listener's ears at the exact moment the noise arrives.
Wearables and Earbuds
Wireless earbuds face the tightest constraints: limited battery, minimal compute, and strict latency requirements. On-device AI models for earbuds are typically quantized to 8-bit integers and compressed to under 1 megabyte to fit within the available memory. Despite these constraints, modern earbud AI noise cancellation can suppress transient noises like door slams and keyboard clicks that traditional ANC misses entirely. The key is using lightweight CNN architectures optimized for edge inference, often running on dedicated digital signal processor cores within the earbud's system-on-chip.
Evaluating AI Noise Cancellation Performance
Objective Metrics
Developers evaluating noise cancellation AI should focus on four primary metrics. Signal-to-noise ratio (SNR) improvement measures how many decibels the system adds to the clean speech signal relative to background noise. Short-time objective intelligibility (STOI) scores predict how well human listeners will understand the processed speech, with scores above 0.85 considered excellent. Perceptual evaluation of speech quality (PESQ) rates the overall quality of processed audio on a scale of 1 to 5, with 4.5 or higher representing near-transparent processing. Latency, measured as the time between audio input and processed output, must stay below 20 milliseconds for real-time communication to avoid noticeable desynchronization.
Benchmark Comparisons
Recent academic benchmarks highlight the gap between AI-driven and classical noise cancellation. A 2024 study published in the IEEE Transactions on Audio, Speech, and Language Processing reported that a transformer-based noise suppression model achieved a 20.3 dB SNR improvement on the DNS Challenge dataset, compared to 12.1 dB for classical spectral subtraction and 15.8 dB for RNNoise. The same study reported 91 percent prediction accuracy for transient noise events and a real-time factor of 0.015, meaning the model processes audio 66 times faster than real time on a standard GPU.
For developers, these numbers translate to practical outcomes. A 20 dB SNR improvement means that background noise which was previously as loud as the speaker's voice becomes barely perceptible. The 0.015 RTF confirms that the model can run comfortably within a real-time communication pipeline without bottlenecking the audio stream. Independent benchmarks from Artificial Analysis provide ongoing comparisons of speech processing models, helping developers track which architectures deliver the best accuracy-to-latency ratios. The W3C WebRTC specification also defines the browser-level audio processing constraints that developers must work within when building web-based communication apps.
Implementation Considerations for Noise Cancellation AI
Model Selection and Size Trade-offs
Choosing the right noise cancellation AI model involves balancing accuracy, model size, and inference speed. Lightweight models like RNNoise occupy under 500 kilobytes and run on CPU-only devices with minimal power draw, making them suitable for mobile apps and IoT devices. Mid-range models like DeepFilterNet2 offer better accuracy at 2 to 5 megabytes, requiring a GPU or neural processing unit for real-time inference. High-accuracy transformer models can exceed 50 megabytes and typically need server-grade GPUs, making them appropriate for cloud-based audio processing rather than on-device deployment.
The decision framework is straightforward. If your application runs on battery-powered devices with limited compute, choose a quantized CNN model. If you process audio server-side as part of a conferencing backend, a larger transformer model delivers measurably better results. For developers using VideoSDK, the built-in noise suppression handles this trade-off automatically by selecting the appropriate processing mode based on the participant's device capabilities and network conditions.
Latency and Real-Time Constraints
Real-time communication demands sub-20 millisecond end-to-end audio latency, and ideally under 5 milliseconds for the noise cancellation stage alone. Every additional millisecond of processing delay accumulates. If the noise suppression adds 10 milliseconds, the echo cancellation adds another 5, and the codec adds 20, the total pipeline latency can exceed what listeners perceive as natural conversation.
AI noise cancellation pipelines meet these constraints through frame-based processing, where the model processes small audio chunks (typically 10 milliseconds) as they arrive rather than buffering longer segments. Model quantization, pruning, and knowledge distillation further reduce inference time. VideoSDK's audio calling capabilities integrate noise suppression directly into the WebRTC media pipeline, ensuring that audio processing happens with minimal added latency before the signal is encoded for transmission.
Deployment Options
Developers can deploy noise cancellation AI in three primary configurations. Cloud-based inference sends raw audio to a server for processing, which works well for backend conferencing systems but adds network latency. On-device SDKs like Picovoice Koala and open-source projects like JointAEC-NS run models locally on the user's device, eliminating network latency but requiring careful optimization for each platform. Hybrid approaches use lightweight on-device models for initial noise suppression and cloud-based models for additional refinement when network conditions permit.
For most real-time communication applications, on-device processing is the right choice. It eliminates network dependency, preserves user privacy by keeping audio local, and reduces server costs. VideoSDK's Prebuilt UI Kit includes noise suppression out of the box, so developers embedding video calling with a single component get AI-enhanced audio without any additional integration work.
Future Trends in Noise Cancellation AI
The next generation of noise cancellation AI is moving beyond single-channel audio processing. Direction-preserving ANC uses multi-microphone arrays to identify the spatial location of noise sources and suppress them while preserving the spatial characteristics of desired sounds. This creates a more natural listening experience where the user can still perceive the direction of voices they want to hear.
Multimodal sensing represents another frontier. Systems that combine audio input with visual data from cameras can detect noise sources before they reach the microphone. A camera that sees a door opening can pre-activate noise suppression for the expected slam, reducing the reaction time from milliseconds to proactive prevention.
The integration of noise cancellation AI with conversational AI agents is perhaps the most significant trend for developers. As voice agents become more common in customer support, telehealth, and IoT applications, clean audio input becomes critical for accurate speech recognition. VideoSDK's AI voice agent platform benefits directly from advanced noise suppression, as cleaner input audio improves STT accuracy and reduces agent response latency. The convergence of noise cancellation AI and conversational AI will define the next wave of voice-driven applications.
Definitions Glossary
Noise Cancellation AI: The application of machine learning models, particularly deep neural networks, to identify and remove unwanted acoustic signals from audio streams in real time. VideoSDK integrates this capability directly into its RTC SDKs.
Active Noise Cancellation (ANC): A traditional signal processing technique that generates anti-phase sound waves to cancel predictable, low-frequency noise. AI-augmented ANC extends this approach with adaptive neural network prediction.
Signal-to-Noise Ratio (SNR): A measure comparing the level of desired speech signal to the level of background noise, expressed in decibels. Higher SNR improvement indicates more effective noise suppression.
Real-Time Factor (RTF): The ratio of processing time to audio duration. An RTF below 1.0 means the system processes audio faster than real time, which is required for live communication pipelines.
Adaptive Filtering: A signal processing technique that iteratively adjusts filter coefficients to minimize error between desired and observed signals. AI-guided adaptive filtering uses neural networks to predict optimal coefficients proactively.
Key Takeaways
- Noise cancellation AI uses deep learning to suppress non-stationary noise that classical ANC filters cannot handle, making it essential for modern real-time communication apps.
- CNN, RNN, and transformer architectures each offer different accuracy-to-latency trade-offs, with CNNs suited for on-device inference and transformers for cloud-based processing.
- Production systems require sub-5 millisecond processing latency for the noise suppression stage alone to avoid perceptible echo or desynchronization in live calls.
- On-device deployment eliminates network latency, preserves user privacy, and reduces server costs compared to cloud-based audio processing.
- VideoSDK includes built-in noise suppression in its video calling SDK and Prebuilt UI Kit, letting developers ship clean audio without integrating a separate ML pipeline.
Conclusion
Noise cancellation AI has moved from a premium feature to a baseline expectation in real-time communication. For developers, the technology is now accessible through both open-source models and commercial SDKs, with deployment options ranging from cloud inference to on-device processing. The key is understanding your latency budget, target platform constraints, and accuracy requirements before choosing an approach. VideoSDK's built-in noise suppression makes this decision simpler by integrating AI-enhanced audio processing directly into its video calling SDK and Prebuilt UI Kit. What are you building with VideoSDK? Drop a comment. I'd love to hear what kind of noise cancellation AI use case you're working on. You can get started for free at app.videosdk.live/login.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ