


A Google Translate live stream is a real-time pipeline that captures your broadcast audio, sends it to Google's speech recognition and translation models, and returns translated subtitles or synthesized speech fast enough to overlay on a live stream. Google's Gemini Live API and Cloud Speech-to-Text services make sub-second translation achievable when the pipeline is engineered correctly. This guide walks through the full workflow, from model selection to OBS overlay configuration, and compares Google's stack with third-party alternatives.
Introduction
Live streaming stopped being an English-only medium years ago. A Twitch broadcaster in Berlin may have viewers in São Paulo, Seoul, and Jakarta watching the same broadcast, and most of them receive nothing but the original language. Platforms report that a growing share of live audiences watch from countries where the broadcaster's language is not spoken, which means every untranslated stream silently loses a portion of its potential audience.
Google's translation stack has matured to the point where real-time translation of a live stream is a practical engineering project rather than a research demo. The combination of streaming speech recognition, the Gemini Live API for multimodal translation, and Google Cloud's Translation API gives developers the building blocks for a low-latency multilingual pipeline that outputs subtitles, synthesized voice, or both.
This article covers what a Google Translate live stream actually is, how the pipeline works, how to integrate it with OBS Studio, Streamlabs, and mobile broadcasting apps, what latency to expect, and how Google's offering compares with third-party live translation tools. By the end, you will have a complete mental model of the workflow and a checklist you can act on immediately.
What Is Google Translate Live Stream?
Definition
A Google Translate live stream is defined as a real-time translation workflow that applies Google's speech recognition and machine translation models to the audio track of a live broadcast, producing translated captions or synthesized speech with low enough delay to feel synchronous to viewers. It is not a single Google product you switch on. It is a pipeline you assemble from Google's AI services, typically streaming Speech-to-Text for transcription, the Gemini Live API for translation-aware processing, and optionally a Text-to-Speech engine for voice output.
How It Works
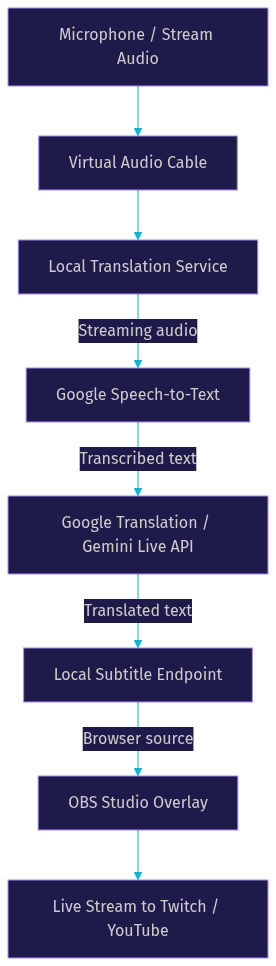
The pipeline works by continuously capturing small chunks of broadcast audio, streaming them to Google's cloud services, and rendering the translated result as an overlay on the stream. Audio first passes through a speech recognition layer that converts spoken words into text in the source language. That text is then translated into the target language, either by a dedicated translation model or by a multimodal model such as Gemini that handles understanding and translation in one pass. Finally, the translated text is displayed as a subtitle overlay, or converted into synthesized speech for a secondary audio channel.
The critical engineering constraint is latency. Every stage, capture, recognition, translation, and rendering, adds delay, and the total budget for a live stream is roughly one to two seconds before viewers notice the subtitles lagging behind the speaker.
Setting Up Real-Time Translation for Your Live Stream
Choosing the Right Google AI Model
Model choice determines your latency ceiling and language coverage. Google's Gemini Live API is designed for bidirectional, real-time audio and supports low-latency speech understanding, which makes it the strongest candidate for a Google Translate live stream where translation and response must happen in near real time. Google Cloud's streaming Speech-to-Text paired with the Translation API is the more traditional route: it offers predictable per-language pricing, mature streaming recognition, and wide language coverage, but the two-hop architecture adds latency because transcription and translation run as separate stages.
For subtitle-only output, the streaming Speech-to-Text plus Translation API combination is often sufficient and easier to control. For voice translation, where the viewer hears the translation spoken aloud, the Gemini Live API's native audio-in, audio-out design reduces the number of pipeline stages and typically delivers lower end-to-end delay.
Required Tools and Platform Compatibility
The pipeline runs on any modern operating system, Windows, macOS, or Linux, because the heavy processing happens in Google's cloud. On the broadcasting side, you need streaming software that supports browser sources or text overlays: OBS Studio, Streamlabs Desktop, and XSplit all qualify. On the integration side, you need a Google Cloud project with billing enabled, API credentials for the Speech-to-Text, Translation, and optionally the Gemini Live API, and a lightweight local service that captures broadcast audio and relays it to Google.
A virtual audio cable is the one piece of supporting software most setups require. It routes your microphone or stream audio into the translation service without interfering with what your audience hears directly.
Step-by-Step Workflow
The logical flow has four stages. First, capture the broadcast audio through a virtual audio device. Second, stream the audio to Google's recognition and translation services. Third, receive translated text or synthesized speech back from the API. Fourth, render the result as a subtitle overlay or secondary audio track inside your broadcasting software.
Integrating Google Translate Live Stream with Popular Broadcasting Software
Integration is where the pipeline becomes visible to your audience. The translation service runs locally as a small helper application, and your broadcasting software displays its output.
OBS Studio Overlay Configuration
OBS Studio is the most common target because its browser source feature can display dynamic content that updates in real time. The approach works like this: your local translation service writes the latest translated subtitle lines to a small web page or local endpoint, and OBS renders that page as a browser source layered over your stream canvas. You position and style the source like any other overlay, controlling font, size, background opacity, and placement.
The key configuration detail is the refresh behavior. The browser source must update as new translations arrive, not on a fixed polling interval, because polling introduces visible lag. A locally served page that pushes updates as they arrive keeps the subtitle timing tight. You should also cap the visible history, showing only the current line plus optionally the previous one, because a growing wall of text becomes unreadable on mobile players.
Streamlabs and XSplit Alternatives
Streamlabs Desktop, built on the same core as OBS, supports the identical browser-source approach, so the overlay you build for OBS transfers with minimal adjustment. XSplit Broadcaster supports browser-based overlays through its own web page source, and the same local translation endpoint works there too. The principle is uniform across all three tools: your translation service exposes its output as a web resource, and the encoder renders it as a layer.
Mobile Streaming Apps
Mobile broadcasters can use the same Google APIs through a lightweight client app that captures the device microphone, streams audio to Google, and renders translated subtitles directly on the screen being captured. Because the rendering happens on-device before the stream is encoded, no overlay feature in the streaming app is required. The trade-off is battery and thermal load, since continuous audio streaming keeps the radio and processor active for the duration of the broadcast.
The full pipeline looks like this:
Performance and Latency Considerations
Expected Latency Benchmarks
Latency is the metric that decides whether your translation feels live or feels like delayed captions. Google's documentation for streaming Speech-to-Text reports recognition latency in the hundreds of milliseconds range for interim results, and the Gemini Live API is engineered for conversational, sub-second audio round trips. In a well-built pipeline, the realistic end-to-end budget is roughly one to two seconds from a word being spoken to its translation appearing on screen: a few hundred milliseconds for audio capture and upload, several hundred for recognition, a few hundred for translation, and the remainder for rendering and encoder delay.
Interim recognition results matter here. Streaming recognition returns partial hypotheses while the speaker is still talking, and a pipeline that displays interim translations and replaces them with finalized ones achieves a perceived latency far below the finalized-only approach.
Network and Hardware Tips
Three practical optimizations make the biggest difference. Use a wired network connection for the broadcasting machine, because Wi-Fi jitter shows up directly as subtitle timing irregularities. Reserve upload bandwidth for the translation audio stream by keeping its bitrate modest, since translated text is tiny compared to video. And if your local network blocks outbound real-time connections, configure a TURN relay so the audio path to Google's services stays open, the same technique used in WebRTC deployments to traverse restrictive firewalls.
Comparison with Third-Party Live Translation Solutions
Feature Matrix
Google's stack competes with dedicated live translation tools and open-source overlay projects. Here is how the main options compare:
| Feature | Google AI Stack | Dedicated Translation Tools | Open-Source Overlays |
|---|---|---|---|
| Latency control | High, you engineer the pipeline | Medium, fixed by vendor | Medium, depends on your build |
| Language coverage | Very wide, 100+ languages | Varies by vendor | Depends on underlying API |
| Pricing model | Pay-per-use API billing | Monthly subscription | Free software, API costs remain |
| Customization | Full control over display and logic | Limited to vendor settings | Full control, more effort |
| Voice translation | Supported via Gemini Live API | Supported by some vendors | Rare, significant build effort |
| Best for | Developers wanting control | Streamers wanting speed | Tinkerers and custom workflows |
The most important row is latency control. Google's stack is the only option where you own every stage of the pipeline, which means you can optimize interim results, caching, and rendering in ways a closed vendor tool never permits.
When to Choose Google vs. Alternatives
Choose the Google AI stack when you have development capacity, need fine-grained control over subtitle behavior, want voice translation through the Gemini Live API, or expect volume high enough that pay-per-use API billing beats a flat subscription. Choose a dedicated third-party tool when you need a working translated stream this week and cannot invest engineering time, or when your use case is a single recurring webinar where customization does not matter. Choose an open-source overlay project when your requirements are modest, subtitle-only, and you want to avoid vendor lock-in on the display layer while still using a cloud API underneath.
The lock-in question deserves honesty: building directly on Google's APIs ties your pipeline to Google's pricing and model roadmap. The mitigation is architectural, keeping the translation stage behind your own interface so the underlying provider can be swapped without rebuilding the overlay and capture layers.
Best Practices and Common Pitfalls
Audio Quality and Noise Suppression
Translation quality starts with recognition quality, and recognition quality starts with the microphone. A headset or broadcast microphone positioned close to the speaker consistently outperforms a laptop microphone, because distance amplifies room noise that the recognizer then has to fight. Enable noise suppression on the capture path before the audio reaches the translation service, either through your broadcasting software's built-in filter or through Google's own noise suppression capabilities where available. Music playing behind speech is the single biggest recognition killer, so if your stream has a background music channel, route only the voice channel into the translation pipeline.
Token Management and Language Pair Limits
Treat API credentials as production secrets. Keep them on the broadcasting machine or a small local service, never embedded in anything viewers can access, and rotate them if they are ever exposed. Monitor your quota and rate limits in the Google Cloud console, because a live stream that exceeds its recognition quota mid-broadcast silently stops translating, which looks like a bug to your audience. Verify that your specific source and target language pair is supported by the exact model you selected, since coverage differs between the streaming recognition service and the Gemini Live API.
Future Trends in Live Stream Translation
Three trends will reshape this pipeline over the next few years. Multimodal translation, where models process video frames alongside audio to use visual context such as slides or on-screen text, is already emerging in preview capabilities and will improve accuracy for presentation-heavy streams. On-device inference is the second trend: as translation models shrink, part of the pipeline will move from cloud to the broadcasting machine, cutting latency and removing the network dependency entirely for common language pairs. Finally, language coverage continues to expand, with Google regularly adding languages and improving low-resource language performance, which widens the audience a single translated stream can serve.
Quick Recap and Action Checklist
Here is the essential path to launch:
- Create a Google Cloud project and enable the Speech-to-Text, Translation, and Gemini Live APIs.
- Set up a virtual audio cable to route broadcast audio into your translation service.
- Build or deploy a lightweight local service that streams audio to Google and exposes translated text as a web endpoint.
- Add a browser source in OBS, Streamlabs, or XSplit pointing at that endpoint, styled and positioned for readability.
- Test latency with interim results enabled, and tune audio quality with close mic placement and noise suppression.
- Monitor API quota and credential security before every major broadcast.
Definitions Glossary
Google Translate live stream: A real-time pipeline that applies Google's speech recognition and translation models to live broadcast audio, producing translated subtitles or synthesized speech with low latency.
Gemini Live API: Google's real-time, audio-in audio-out multimodal API designed for conversational and streaming workloads, suited to low-latency voice translation.
Streaming Speech-to-Text: Google Cloud's recognition service that returns partial transcription results while the speaker is still talking, enabling interim subtitle display.
Browser source: A feature of OBS, Streamlabs, and XSplit that renders a live web page as an overlay layer, used to display real-time translated subtitles.
Virtual audio cable: Software that routes audio between applications, letting a translation service capture broadcast audio without disturbing the stream's main output.
Key Takeaways
- A Google Translate live stream is an engineered pipeline, not a single product: audio capture, streaming recognition, translation, and overlay rendering are separate stages you control.
- The Gemini Live API is the strongest choice for voice translation, while streaming Speech-to-Text plus the Translation API suits subtitle-only workflows.
- A realistic end-to-end latency budget is one to two seconds, and displaying interim recognition results cuts perceived latency dramatically.
- Browser sources in OBS, Streamlabs, and XSplit provide a uniform integration path for rendering translated subtitles over any live stream.
- Google's stack wins on control and language coverage; dedicated vendor tools win on time-to-launch, and the honest choice depends on your engineering capacity.
Conclusion
Building a Google Translate live stream in 2026 is a tractable weekend project for a developer and a genuine competitive advantage for a broadcaster. The pipeline is conceptually simple, capture audio, stream it to Google's recognition and translation models, and render the result as an overlay, but the quality lives in the details: interim results, close-mic audio, quota monitoring, and a browser source that updates in real time. If you want to extend the same real-time architecture further, VideoSDK's interactive live streaming SDKs and real-time transcription capabilities offer a ready-made foundation for multilingual streaming workflows with sub-second latency. Start with the VideoSDK interactive live streaming docs, explore the code samples, and sign up free at app.videosdk.live/login. What are you building with live stream translation? Drop a comment, I'd love to hear which language pairs you're targeting.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ