


An AI voice agent example code walkthrough shows how three layers fit together: a speech-to-text engine converts user audio into text, a large language model decides what to say next, and a text-to-speech engine speaks the reply. VideoSDK's open-source, Python-based AI Agent SDK implements this exact pipeline and connects it to real-time rooms, so developers can study and run a working voice agent in hours rather than weeks. This guide explains each component, the architecture patterns, and how to deploy the result.
Building a voice agent used to mean stitching together half a dozen services and hoping the latency math worked out. In 2026, the picture is different. Open-source frameworks and realtime model APIs have collapsed much of that complexity, and developers searching for AI voice agent example code are usually looking for one thing: a working reference they can read, understand, and adapt.
That is exactly what this article provides in prose form. Instead of dumping syntax at you, it walks through how a production-grade voice agent is structured, why each layer exists, and what the example code for a modern agent actually does at each stage. By the end, you will understand the full path from a user's spoken words to the agent's spoken reply, and you will know where to find runnable reference implementations, including the VideoSDK AI Agents documentation and its open-source repositories on GitHub.
Understanding the Core Components of an AI Voice Agent
Every AI voice agent, regardless of vendor or framework, is built from the same three cooperating layers. Understanding what each layer does, and where its performance boundaries sit, is the foundation for reading any example code intelligently.
Speech-to-Text (STT) Layer
The STT layer converts raw microphone audio into text the reasoning layer can act on. Popular providers include OpenAI Whisper, Deepgram, Google Speech-to-Text, and AssemblyAI, and each exposes streaming interfaces designed for realtime use. The critical performance metric is not raw accuracy but partial-result latency: how quickly the engine emits interim transcriptions while the user is still speaking. Fast partial results let the agent begin reasoning before the user finishes their sentence, which is one of the biggest levers on perceived responsiveness. Word-error-rate matters too, and independent comparisons such as Artificial Analysis's Speech Arena benchmarks show meaningful gaps between providers on conversational audio, so verify current figures before committing.
Large Language Model (LLM) Reasoning Layer
The LLM is the brain of the agent. It receives the transcribed user speech plus a system prompt and conversation history, then generates the next reply or decides to invoke a tool, such as checking an appointment calendar or looking up an order status. Modern examples lean on multimodal-capable models like OpenAI's GPT-4o class, Anthropic's Claude, and Google's Gemini, and the reasoning layer is also where function calling is defined: the developer declares which tools exist, and the model requests them by name when appropriate. In a well-structured example, this layer is swappable, meaning you can replace one provider with another without touching the audio layers.
Text-to-Speech (TTS) Output Layer
The TTS layer turns the model's text response into natural spoken audio. Providers such as ElevenLabs, Cartesia, OpenAI TTS, and AWS Polly each offer different trade-offs between voice quality, latency, and cost. Voice customization happens here: persona selection, speaking rate, and emotional tone are all configured at the TTS stage. Two practical considerations dominate real implementations. First, streaming synthesis, where audio starts playing before the full sentence is generated, dramatically reduces perceived delay. Second, response caching, which VideoSDK's agent framework supports natively, avoids re-synthesizing identical phrases and cuts both latency and cost.
Architectural Patterns for Voice Agents
When you examine AI voice agent example code from different sources, you will find it falls into two broad architectural camps. Choosing between them is the single most consequential design decision you will make.
Realtime Model Approach
The first pattern uses a single multimodal model that accepts audio in and returns audio out directly. OpenAI's Realtime API, Google's Gemini Live, and Alibaba's Qwen OMNI family all work this way. The model handles transcription, reasoning, and speech generation internally, so the developer's example code becomes dramatically simpler: there is no manual wiring between STT, LLM, and TTS, and end-to-end latency can drop well below what a chained pipeline achieves because there are no handoffs between services. The trade-offs are fewer choices of voice, less granular control over each stage, tighter vendor coupling, and typically higher per-minute pricing.
Custom Pipeline Approach
The second pattern composes independent STT, LLM, and TTS services into an orchestrated pipeline. This is the architecture used by open-source frameworks like Pipecat and by VideoSDK's own Agent SDK, which lets you mix, for example, Deepgram for transcription, Claude for reasoning, and ElevenLabs for synthesis. The benefits are flexibility, best-in-class quality at each stage, easier cost tuning, and the ability to swap any component as benchmarks shift. The cost is added integration work and the risk of compounding latency if each hop is slow. A well-designed framework absorbs most of that integration burden for you, which is precisely why studying a maintained example beats writing the glue yourself.
When to Choose Each Pattern
Use the realtime model approach when you need the lowest possible latency, a simple integration surface, and your use case fits the provider's voice and tooling constraints. Use the custom pipeline approach when you need provider independence, per-stage optimization, enterprise compliance requirements, or fine-grained control over conversation behavior. Teams building regulated flows, such as loan applications or insurance intake, often prefer pipelines paired with deterministic orchestration like VideoSDK's Conversational Graph.
Walkthrough of a Representative Example
Rather than pasting syntax, this section explains what a representative VideoSDK Agent SDK example does at each stage, so you can map the concepts onto any implementation you find.
Setting Up the Development Environment
A typical Python-based voice agent project starts with a virtual environment and a small set of dependencies: the agent framework itself, the plugin packages for your chosen STT, LLM, and TTS providers, and any tool libraries your agent will call. Credentials for each provider are stored as environment variables, never hard-coded, and the project usually separates the agent definition from the entry point that starts the worker process. VideoSDK's quickstart repos on GitHub follow this layout, and the code samples page links ready-to-run reference projects for web, telephony, and WhatsApp agents.
Initialising the Voice Pipeline
The heart of the example is pipeline construction. The developer creates a pipeline object and injects three components into it: a speech recognizer configured with the chosen STT provider, a reasoning session bound to the selected LLM with its system prompt and tool definitions, and a speech synthesizer pointed at the TTS provider and voice persona. The framework then wires these together so that incoming audio flows automatically from recognition to reasoning to synthesis without the developer writing any glue logic. In VideoSDK's architecture, this pipeline runs inside an Agent Worker, a Python process that manages the session lifecycle and connects the agent to a VideoSDK room, where the human participant joins from a web or mobile client, or over the phone via SIP telephony.
Managing Turn Detection and Interruptions
Turn detection is what makes a voice agent feel conversational rather than walkie-talkie rigid. Voice activity detection, or VAD, continuously monitors the incoming audio stream and decides when the user has started and finished speaking. When the agent is mid-reply and the user interrupts, a well-built example cancels the in-flight TTS audio immediately and lets the LLM incorporate the interruption, exactly as a human would. VideoSDK's framework handles both turn detection and barge-in natively, and it also supports preemptive responses, where the agent begins replying before the user's turn fully closes to shave perceived latency.
Adding Function Calls
Function calling lets the agent act, not just talk. The developer declares tools, such as a weather lookup, a time query, or an appointment booking action, alongside the system prompt. When the LLM decides a tool is needed, it emits a structured request, the framework executes the real function, and the result is fed back into the conversation. VideoSDK's Agent SDK also supports the Model Context Protocol, which lets agents discover and call external tools through a standardized interface.
Visualising the Data Flow
The sequence below shows the complete journey of a single spoken interaction through a pipeline-style voice agent, from microphone capture to the user's speaker. This is the flow that any representative example code implements:
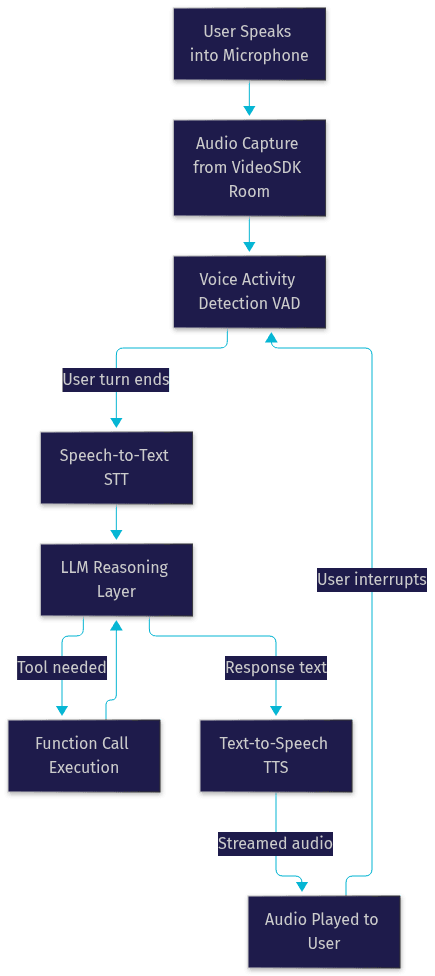
Two things in this diagram deserve attention. First, the tool execution loop: the LLM can request external functions and fold their results back into its reply before a single word is spoken. Second, the interruption path: if the user starts speaking while the agent is talking, VAD catches it and the flow resets, which is what makes realtime voice agents feel genuinely interactive rather than scripted.
Best Practices and Common Pitfalls
Most failed voice agent projects fail for predictable reasons. Avoiding them is easier than fixing them later.
Handle provider failures gracefully. STT, LLM, and TTS providers all have outages and rate limits. Production examples implement fallbacks, such as switching to a secondary TTS provider if the primary fails mid-session. VideoSDK's framework includes a fallback adapter concept for exactly this purpose.
Tune latency at every layer. Measure the time from end-of-user-speech to first audible syllable of the reply, because that single number defines how the agent feels. Enable streaming STT partials, streaming TTS, and response caching, and prefer providers with regional endpoints close to your users.
Protect your API keys. Keys belong in environment variables or a secrets manager, never in client-side code or public repositories. In the VideoSDK model, tokens are generated server-side, and the agent worker runs in a trusted environment, not the browser.
Test with real audio, not clean recordings. Agents that perform well on studio-quality samples often collapse on noisy phone audio. Test with accented speech, background noise, and DTMF tones if you are building for telephony. VideoSDK's framework supports DTMF event handling and voicemail detection, both of which are common blind spots in naive implementations.
Deploying and Scaling Voice Agents
Deployment is where example code meets production reality. VideoSDK offers two paths: Agent Cloud, a managed hosting option where the worker runs on VideoSDK's infrastructure, and self-hosting via Docker or Kubernetes for teams that need full control. Self-hosted deployments should containerize the agent worker, keep provider credentials injected at runtime, and scale horizontally by running one worker process per active session, since each session holds realtime state.
Monitoring should track four metrics from day one: end-to-end response latency, STT word-error-rate in production traffic, TTS synthesis failures, and session drop rates. Pipeline observability, which VideoSDK's framework provides, surfaces per-stage timings so you can tell whether a slow agent is slow because of transcription, reasoning, or synthesis. Without per-stage visibility, latency debugging becomes guesswork.
For phone-based agents, deployment also involves telephony routing. VideoSDK's SIP telephony integration bridges traditional phone networks into the same rooms your agents inhabit, so one agent implementation can serve web users and phone callers alike.
Definitions Glossary
Agent Worker: The Python process that runs a VideoSDK AI agent, manages its session lifecycle, and connects it to a VideoSDK room where human participants join.
Pipeline: The chained sequence of speech-to-text, LLM reasoning, and text-to-speech processing that converts a user's spoken input into the agent's spoken reply.
Voice Activity Detection (VAD): The mechanism that continuously monitors incoming audio to determine when a user has started or finished speaking, enabling natural turn-taking and interruptions.
Function Calling: The capability that lets an LLM request execution of developer-defined tools, such as lookups or booking actions, and incorporate the results into its response.
Turn Detection: The logic that decides when a user's speaking turn has ended and the agent should begin responding, a critical determinant of perceived conversation quality.
Key Takeaways
- Every AI voice agent is composed of three cooperating layers: STT for transcription, an LLM for reasoning and tool calls, and TTS for spoken output, and understanding this triad makes any example code readable.
- Two architectures dominate in 2026: single-API realtime models for lowest latency and simplicity, and custom pipelines for flexibility and provider independence.
- Turn detection and interruption handling, powered by VAD, are what separate genuinely conversational agents from rigid scripted ones.
- VideoSDK's open-source, Python-based Agent SDK implements the full pipeline with built-in VAD, function calling, TTS caching, and telephony support, and its GitHub quickstarts serve as maintained, runnable example code.
- Production readiness means fallback handling, server-side secrets, real-audio testing, and per-stage latency observability, not just a working demo.
Conclusion
Reading AI voice agent example code becomes straightforward once you recognize the three-layer pattern underneath it: speech in, reasoning in the middle, speech out. The best next step is to run a maintained reference implementation rather than write glue code from scratch. Start with the VideoSDK AI Agents quickstart, explore the runnable samples on GitHub, and sign up free at app.videosdk.live/login to get your first agent talking. What are you building with VideoSDK? Drop a comment, I'd love to hear what kind of voice agent use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ