


WebRTC voice activity detection (VAD) is a signal processing technique that determines whether an audio frame contains human speech or silence. WebRTC implements VAD using a Gaussian Mixture Model combined with energy-based heuristics, processing audio in fixed 10, 20, or 30 millisecond frames at sample rates from 8 to 48 kHz. VideoSDK leverages VAD within its real-time communication pipeline to enable automatic mute, bandwidth optimization, and speech-driven analytics across its video calling SDK and AI voice agent platforms.
Real-time voice detection is the unsung backbone of every modern communication app. When a participant in a video call stops speaking, the audio track does not just keep streaming silence. Something has to decide that the frame is non-speech and act on it. That something is voice activity detection, and in the WebRTC ecosystem, it is baked deep into the media stack.
If you are building telehealth platforms, live streaming apps, or AI voice agents, understanding how WebRTC VAD works gives you control over bandwidth, latency, and user experience. By the end of this guide, you will understand the internal algorithm, configuration parameters, integration paths across browsers and native platforms, and how VAD performance compares to alternative open-source solutions.
Understanding WebRTC Voice Activity Detection
Voice activity detection is defined as the process of identifying the presence or absence of human speech in an audio stream. In WebRTC, VAD runs as part of the audio processing module, sitting between the capture device and the encoder. Every audio frame that enters the pipeline is classified as either active (speech) or passive (non-speech), and that classification drives downstream decisions about transmission, encoding, and analytics.
WebRTC VAD works by analyzing spectral characteristics and energy levels of each audio frame against statistical models of speech and non-speech. The implementation traces back to Google's work on the WebRTC project, originally derived from code used in Google Hangouts and Chrome's native media stack. It was designed for production VoIP, meaning it prioritizes low latency and low computational overhead over academic-grade accuracy.
The key benefits of WebRTC VAD include bandwidth savings (non-speech frames can be encoded at lower bitrates or dropped entirely), automatic mute functionality (detecting when a user is not speaking and silencing their track), and speech analytics (providing turn-taking data for conversational AI systems). VideoSDK integrates VAD into its audio calling SDK to provide these capabilities out of the box, so developers do not need to wire up custom signal processing pipelines.
How WebRTC VAD Works Internally
The WebRTC audio processing pipeline follows a strict sequence: audio capture from the microphone, pre-processing (noise suppression, echo cancellation, gain control), VAD classification, and finally media routing through the codec and transport layer. VAD sits late enough in the chain to benefit from cleaned-up audio but early enough to influence encoding decisions.
At its core, the WebRTC VAD algorithm uses a Gaussian Mixture Model (GMM) to distinguish speech from non-speech. The model evaluates multiple sub-band features across the frequency spectrum, comparing them against pre-trained statistical distributions for both speech and non-speech signals. Energy-based heuristics act as a fast pre-filter: if the total energy of a frame falls below a threshold, it is immediately classified as non-speech without invoking the full GMM evaluation.
The decision flow is binary at the frame level. Each frame is either active or passive. However, most implementations apply a smoothing window to avoid rapid toggling at boundaries between speech and silence. This prevents choppy audio and reduces false transitions that would otherwise degrade the listening experience.
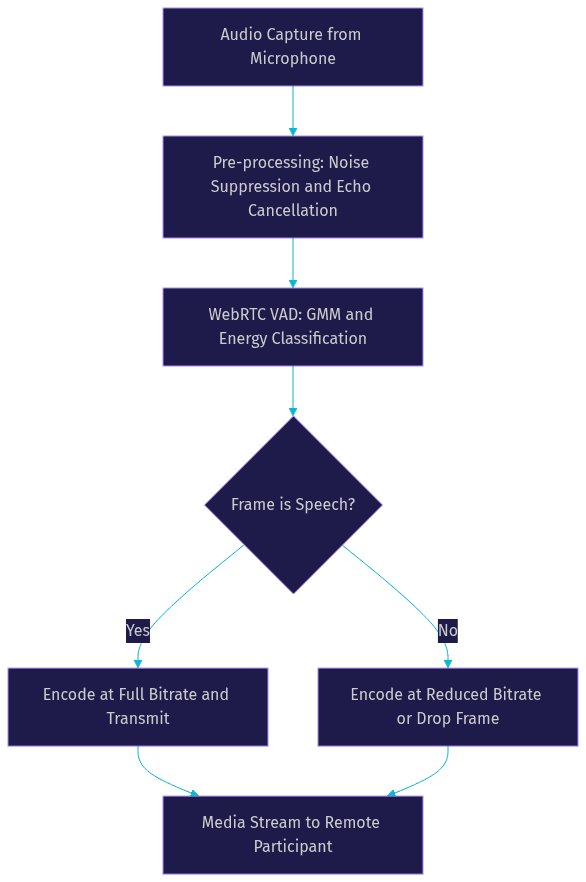
The GMM approach gives WebRTC VAD a strong balance between accuracy and speed. According to the W3C WebRTC specification, the audio processing module is a mandatory part of the WebRTC media stack, and VAD is an integral component of that module. This means any standards-compliant WebRTC implementation, including VideoSDK's infrastructure, has access to VAD at the media layer.
Configuration Parameters
WebRTC VAD supports a specific set of sample rates and frame sizes. The supported sample rates are 8 kHz, 16 kHz, 32 kHz, and 48 kHz. The supported frame sizes are 10, 20, and 30 milliseconds. These constraints exist because the GMM models were trained on these specific configurations, and the internal buffer sizes are fixed accordingly. Passing audio frames that do not match these dimensions will cause the VAD to reject them or produce unreliable results.
VAD Aggressiveness Modes
WebRTC VAD exposes four aggressiveness modes, numbered 0 through 3. Mode 0 is the least aggressive, allowing softer sounds and quieter speech to be classified as active. Mode 3 is the most aggressive, requiring stronger speech signals to trigger an active classification. The trade-off is straightforward: lower modes produce fewer false negatives (missed speech) but more false positives (noise classified as speech), while higher modes reduce false positives but may clip quiet speech or speech at the start of utterances.
In practice, mode 1 or 2 is the sweet spot for most communication applications. Mode 0 is useful in quiet, controlled environments like a telehealth consultation where you cannot afford to miss any speech. Mode 3 is better suited for noisy environments like a live shopping stream where background noise is constant and you want to isolate only clear speech.
Threshold Tuning and Platform Constraints
The VAD outputs a probability score representing the likelihood that a frame contains speech. Developers can tune the decision threshold to bias toward positive or negative classifications. A lower threshold accepts more frames as speech, while a higher threshold demands stronger evidence.
Platform-specific constraints matter significantly. In browsers, VAD typically runs through WebAssembly modules because the native WebRTC API does not expose VAD decisions directly to JavaScript. In native mobile applications, the WebRTC C++ library exposes VAD through JNI on Android and through Objective-C bridges on iOS. VideoSDK's Android SDK and iOS SDK handle this bridge layer internally, so developers interact with VAD through high-level event callbacks rather than low-level C++ APIs.
Integration Scenarios
Integrating WebRTC VAD requires different approaches depending on where the processing happens: in the browser, on a native mobile client, or on a server.
Browser Integration with WebAssembly
In browser-based applications, the native WebRTC API does not expose VAD decisions directly. Developers typically use WebAssembly-based VAD libraries that run alongside the WebRTC media stream. The audio track is routed through a Web Audio API processing node, and frames are passed to the WASM VAD module for classification. The result is then surfaced to the application logic through JavaScript callbacks.
This approach requires serving the WASM binary over HTTPS with proper CORS headers, as browsers restrict WASM instantiation on insecure origins. The WASM module must also be loaded and initialized before audio processing begins, which adds a small startup cost.
Native Mobile Integration
On Android, the WebRTC library exposes VAD through its native audio processing module. Developers can access VAD decisions through JNI bridges or through higher-level SDKs that wrap the functionality. On iOS, a similar pattern applies through Objective-C or Swift bridges to the underlying C++ WebRTC library.
VideoSDK's mobile SDKs abstract this complexity. When you initialize a VideoSDK room on Android or iOS, the audio processing pipeline, including VAD, is configured automatically. You can register for speech-related events through the SDK's participant event system, receiving callbacks when a participant starts or stops speaking without directly interfacing with the native VAD API.
Server-Side Processing with Python
For server-side VAD processing, the Python package known as webrtcvad and its maintained fork called webrtcvad-wheels provide a Python binding to the original WebRTC VAD C library. This is commonly used in AI voice agent pipelines where server-side speech detection is needed to trigger LLM inference or manage turn-taking logic.
VideoSDK's Python SDK and AI Agent SDK integrate VAD as part of the agent pipeline. The Agent Worker process uses VAD to detect when a user has finished speaking, triggering the LLM to generate a response. This is a critical component of real-time conversational AI, where latency between user speech ending and agent response starting must be minimized.
Typical Integration Flow
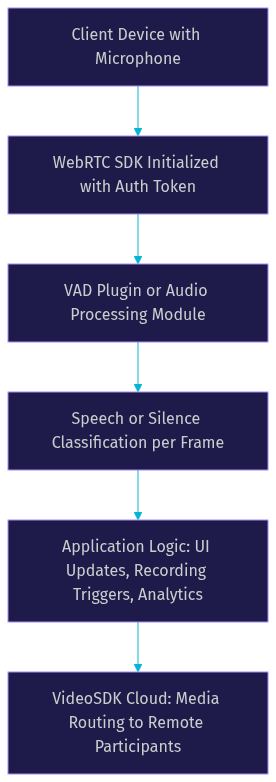
A standard VAD integration flow follows these steps. First, generate an authentication token server-side using your API credentials. Next, initialize the WebRTC SDK on the client with that token. Then, register VAD event listeners with the SDK, specifying your desired aggressiveness mode and sample rate. Finally, handle VAD callbacks in your application logic, updating UI state, triggering recordings, or feeding data to downstream analytics systems.
Best Practices and Common Pitfalls
Choosing the correct sample rate and frame size is the first decision that affects VAD performance. For most real-time communication apps, 16 kHz with 20-millisecond frames is a reliable default. It provides sufficient frequency resolution for the GMM model while keeping processing overhead low. Higher sample rates like 48 kHz offer better spectral detail but increase CPU usage proportionally.
Avoid over-aggressive VAD modes in general-purpose applications. Mode 3 is tempting because it produces clean silence detection, but it clips quiet speech and creates a choppy listening experience at the remote end. Start with mode 1 and increase only if you observe persistent false positives from background noise.
Handle VAD callbacks carefully with respect to threading. On mobile platforms, VAD callbacks may arrive on an audio processing thread rather than the main UI thread. Directly updating UI elements from these callbacks can cause jitter or crashes. Always marshal callback data to the main thread before touching UI state.
For browser deployments, secure your WASM assets properly. Serve them over HTTPS, configure CORS headers to restrict access to your own origin, and consider subresource integrity hashes to prevent tampering. WASM modules that process audio have access to raw microphone data, so treating them with the same security posture as any privileged resource is essential.
Performance Considerations and Benchmarks
WebRTC VAD is designed for low computational overhead. On a typical desktop processor, VAD processing per frame takes well under 10 milliseconds, making it suitable for real-time applications without introducing noticeable latency. On modern mobile devices, the CPU usage is negligible compared to the audio encoding and network transmission costs.
Memory footprint is another advantage. The WebRTC VAD module requires only a few kilobytes of memory for its internal state and model parameters. This makes it practical for edge devices and IoT applications where memory is constrained.
When comparing WebRTC VAD to alternative solutions, the trade-offs become clearer. Silero VAD, a machine-learning-based detector, offers higher accuracy on noisy audio but requires significantly more computational resources and a trained neural network runtime. ONNX-based browser VADs provide good accuracy but add WASM bundle size and initialization latency. WebRTC VAD wins on footprint, speed, and native integration with the WebRTC media stack.
Neural VAD models like Silero achieve lower false-positive rates on challenging audio, but WebRTC VAD maintains a strong advantage in processing speed and resource efficiency for real-time communication workloads.
Comparison with Alternative VAD Solutions
The VAD landscape includes several options beyond the native WebRTC implementation. Each has distinct strengths depending on your deployment target and accuracy requirements.
| Feature | WebRTC VAD | Python webrtcvad-wheels | Silero VAD | ONNX Browser VAD |
|---|---|---|---|---|
| Algorithm | GMM and energy heuristics | Same as WebRTC (C binding) | Deep neural network | Neural network via ONNX |
| Latency | Sub-10 ms per frame | Sub-10 ms per frame | 30 to 80 ms per frame | 20 to 50 ms per frame |
| Memory footprint | Very low (kilobytes) | Low | Medium (model weights) | Medium (WASM and model) |
| Accuracy | Good for clean speech | Good for clean speech | High on noisy audio | High on noisy audio |
| Best for | Real-time VoIP and video calls | Server-side AI agent pipelines | Offline transcription and analytics | Browser-based ML-powered detection |
WebRTC VAD's unique strengths are its low-memory footprint, native integration with the WebRTC media stack, and proven track record in production VoIP systems. For developers building on VideoSDK, VAD is already integrated into the video calling API and AI voice agent pipeline, so the comparison matters primarily when you are evaluating custom builds or alternative platforms.
Real-World Use Cases
WebRTC VAD powers several critical features across different application domains.
Automatic mute in video conferencing. When a participant is not speaking, VAD detects the silence and the application can automatically mute their audio track. This reduces background noise for all participants and saves bandwidth. VideoSDK's Prebuilt UI Kit uses this pattern to provide a clean audio experience in multi-participant calls.
Speech-driven analytics for call centers. VAD data feeds talk-time metrics, agent-customer ratio analysis, and silence detection in customer support calls. Each VAD decision becomes a data point for conversation analytics platforms.
Triggered recording for telehealth sessions. Instead of recording continuously, telehealth apps can use VAD to start recording only when speech is detected, reducing storage costs and protecting patient privacy during silent periods.
Edge-device voice activation for IoT assistants. On resource-constrained devices, WebRTC VAD's low memory footprint makes it ideal for wake-word detection pre-filtering. The VAD runs continuously at minimal cost, and only when speech is detected does the system invoke heavier processing like speech recognition.
Definitions Glossary
Voice Activity Detection (VAD): A signal processing technique that classifies audio frames as containing speech or non-speech. In WebRTC, VAD runs as part of the audio processing module and drives decisions about encoding, transmission, and analytics.
Gaussian Mixture Model (GMM): A probabilistic model used by WebRTC VAD to distinguish speech from non-speech by comparing audio frame features against statistical distributions trained on speech and silence samples.
VAD Aggressiveness Mode: A configuration parameter (0 through 3) in WebRTC VAD that controls how strictly the detector requires speech evidence. Higher modes reduce false positives but may clip quiet speech.
WebRTC Audio Processing Pipeline: The sequence of processing stages in WebRTC that includes noise suppression, echo cancellation, gain control, and VAD, applied to audio frames before encoding and transmission.
Agent Worker: The Python process in VideoSDK's AI agent architecture that manages session lifecycle and uses VAD to detect turn boundaries for real-time conversational AI interactions.
Key Takeaways
- WebRTC voice activity detection uses a Gaussian Mixture Model combined with energy heuristics to classify audio frames as speech or non-speech in under 10 milliseconds per frame.
- VAD aggressiveness modes 0 through 3 control the trade-off between false positives and false negatives, with mode 1 or 2 being the practical sweet spot for most communication applications.
- Browser-based VAD requires WebAssembly modules because the native WebRTC API does not expose VAD decisions to JavaScript directly.
- VideoSDK integrates VAD into its video calling, audio calling, and AI voice agent SDKs, so developers access speech detection through high-level event callbacks rather than low-level signal processing APIs.
- For AI voice agent pipelines, server-side VAD through Python bindings or VideoSDK's Agent Worker is critical for detecting when a user has finished speaking and triggering LLM response generation.
Conclusion
WebRTC voice activity detection is a foundational component of real-time communication systems, offering low-latency speech detection with minimal computational overhead. Whether you are building a video conferencing app with automatic mute, a telehealth platform with triggered recording, or an AI voice agent with turn detection, understanding VAD internals and configuration gives you the control to optimize for your specific use case.
VideoSDK handles VAD integration across its video calling, audio calling, and AI voice agent SDKs, so you can focus on application logic rather than signal processing. Explore the VideoSDK docs to get started, check out the code samples for working integration examples, or join the VideoSDK Discord community to discuss your implementation with other developers. You can sign up for free at app.videosdk.live/login and start building today.
What are you building with WebRTC voice activity detection? Drop a comment below, I would love to hear what kind of real-time speech detection use case you are working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ