


Persian text to speech (TTS) is technology that converts written Farsi text into natural, human-sounding spoken audio using neural speech synthesis. Unlike generic English-first TTS, a proper Persian TTS engine must handle right-to-left script, Arabic-derived letters with multiple contextual forms, and diacritics that change pronunciation. Developers building Persian audio features can integrate a Persian speech API from providers like VideoSDK, ElevenLabs, or Google Cloud TTS, or run open-source models like Piper for full control.
Persian-language digital content is growing fast, and audio is the fastest-growing format. E-learning platforms serving Iran and the Persian-speaking diaspora, podcast producers, call centers, and accessibility teams all need spoken Persian at scale. Recording every sentence with human voice actors does not scale, and machine translation of English audio sounds wrong to native listeners. That gap is exactly what Persian text to speech closes.
For developers, the challenge is not finding a TTS engine. It is finding one that actually handles Farsi well, integrates cleanly with your stack, and stays affordable at production volume. This guide covers how Persian TTS works under the hood, how to choose a provider, how to integrate it, and how to get the most natural-sounding output. By the end, you will know exactly what to evaluate and how to ship Persian voice synthesis in your product.
What is Persian Text to Speech?
Persian text to speech is defined as the automated conversion of written Persian (Farsi) text into synthesized spoken audio. Persian TTS works by analyzing the input text linguistically, converting it into phonemes, generating an acoustic representation with a neural model, and rendering that into an audible waveform through a vocoder.
What makes Persian different from generic TTS is the language itself. Persian is written right to left in a modified Arabic script, where most letters change shape depending on their position in a word. Several letters that look distinct in Arabic are pronounced identically in Persian, such as the three variants of the "z" sound, which forces the engine to rely on context rather than simple letter-to-sound mapping. Persian also frequently omits short vowels in writing, so the model must infer the correct pronunciation from word context, a task that trips up engines trained primarily on English or Arabic.
A quality Persian TTS system therefore needs a language model trained on substantial Persian corpora, not just a multilingual model with Farsi bolted on. The difference is audible: bolted-on support produces flat, robotic speech with misplaced stress, while dedicated Persian voice synthesis delivers natural intonation and correct handling of loanwords, numbers, and dates.
How Persian Text to Speech Works
Every modern Persian TTS system follows a four-stage pipeline, and understanding it helps you debug bad output. The stages are text preprocessing, phoneme conversion, acoustic modeling, and waveform generation.
Text preprocessing normalizes the input. It expands numbers into words, converts dates and currency, resolves abbreviations, and decides how to handle diacritics. In Persian this stage is unusually important because unwritten short vowels must be inferred here. The preprocessed text is then converted into a phoneme sequence, the abstract sound units the language uses. For Persian, this includes sounds that do not exist in English, such as the uvular plosive at the start of "ghorbān".
The acoustic model, typically a neural network architecture such as Tacotron-style attention models or newer transformer-based models, maps phonemes to a spectrogram, a time-frequency representation of speech. Finally, a neural vocoder such as HiFi-GAN or WaveRNN converts the spectrogram into the actual audio waveform you hear.
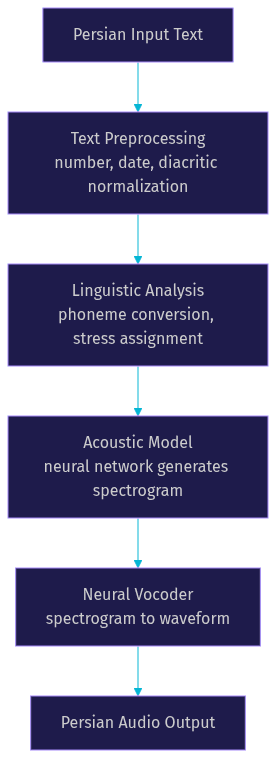
The key takeaway for developers: most quality problems trace back to the first two stages, not the model itself. If your Persian audio mispronounces words, the fix is usually better text normalization on your side, not a different provider.
Choosing the Right Persian TTS Provider
Selecting a Persian TTS provider comes down to six criteria: voice naturalness, latency, pricing model, API availability, language coverage, and customization options. Voice naturalness is the most subjective but most important criterion, so always listen to sample audio in Persian specifically, not just the provider's English demos. Latency matters if you are building interactive voice agents or IVR, where responses must arrive in well under a second. Pricing models vary widely, from per-character billing to per-minute audio billing to subscription tiers, and the cheapest option at low volume is often the most expensive at scale.
API availability means REST endpoints with official SDKs for your stack, ideally JavaScript and Python. Language coverage matters if you plan to expand beyond Persian, since a multilingual engine avoids a second integration later. Customization covers voice cloning, style control, speed and pitch adjustment, and SSML-like markup for pauses and emphasis.
| Provider | Persian Voice Count | Free Tier | Key Differentiator |
|---|---|---|---|
| VideoSDK | Multiple Persian voices | Yes, with free credits | TTS inside real-time rooms, pairs with AI voice agents |
| ElevenLabs | Growing Persian support | Limited free quota | Highest naturalness, voice cloning |
| Google Cloud TTS | Standard and WaveNet Persian | Free monthly character quota | Enterprise reliability, wide language coverage |
| Microsoft Azure Speech | Multiple Persian voices | Free tier (F0) | Strong customization, regional endpoints |
| Piper (open source) | Community Persian voices | Fully free, self-hosted | No API cost, runs on-device |
[LINKABLE ASSET — comparison table]
The most important row depends on your use case. For interactive voice applications, VideoSDK stands out because Persian TTS integrates directly into its real-time communication rooms, so synthesized speech can be delivered to live participants with low latency. For pre-recorded audiobooks where naturalness is everything, ElevenLabs often wins. For teams that cannot send user text to a third party, self-hosted Piper is the honest answer despite lower quality.
Integrating Persian Text to Speech into Your Project
Integration follows four steps, and each one has a decision worth making deliberately.
Step 1: Obtain API credentials. Create an account with your chosen provider and generate an API key from the developer dashboard. Most providers issue a key plus a secret, and some let you create scoped keys restricted to specific operations. Store these in environment variables or a secrets manager, never in your source repository.
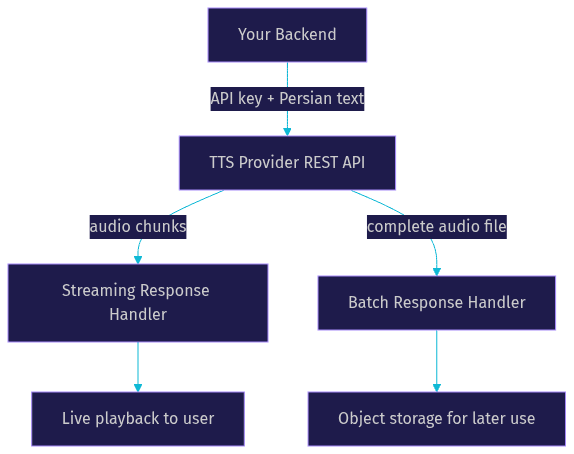
Step 2: Send a synthesis request. Your application sends the Persian text to the provider's REST endpoint, along with parameters such as the voice identifier, output audio format, speaking rate, and pitch. The request is typically a simple HTTP call from your backend, and both JavaScript and Python have official or community SDKs that wrap it. Always send text encoded as UTF-8, since Persian script will break under other encodings.
Step 3: Handle the audio response. The API returns audio as a binary stream or a base64-encoded payload, usually in MP3, WAV, or Opus format. Your backend either saves it to object storage for later playback or streams it directly to the client. Validate the audio duration against the expected length before serving it, because truncated responses are a common silent failure.
Step 4: Choose streaming versus batch processing. Batch processing means synthesizing the full text up front and returning a complete audio file, which suits audiobooks, e-learning modules, and video narration. Streaming synthesis returns audio in chunks as it is generated, cutting perceived latency dramatically, which suits live voice agents, IVR prompts assembled on the fly, and reading assistants. If your users wait for a response, choose streaming.
Handling Authentication Securely
Never call a TTS provider directly from your frontend with your API key, because any key shipped to the browser can be extracted and abused. Instead, run a small backend service that holds the key, receives synthesis requests from your clients, forwards them to the provider, and returns only the audio. Use short-lived tokens for client-to-backend authentication, rotate keys regularly, and set spending caps in the provider dashboard so a leaked key cannot drain your account.
Managing Rate Limits and Quotas
Every provider throttles requests, and hitting a limit mid-launch is avoidable pain. Read the documented rate limits before architecting, then implement client-side queuing so bursts are smoothed into a steady request rate. Cache aggressively: the same sentence synthesized twice is wasted money, so store audio keyed by a hash of the text plus voice and settings. For high-volume workloads, request a quota increase in advance rather than discovering the ceiling in production.
Best Practices for High-Quality Persian Audio
The quality of your Persian audio output depends as much on how you prepare text as on which model you use. Teams that invest in text preparation consistently outperform teams that simply switch providers.
Start with text preparation. Add diacritics to ambiguous words where the pronunciation is not obvious from context, since Persian's unwritten short vowels are the number one source of mispronunciation. Use proper punctuation, because neural models use punctuation to decide pauses and intonation. Spell out abbreviations and foreign loanwords phonetically in Persian script if the model mispronounces them.
Next, select the voice deliberately. Test both male and female Persian voices with your actual content, because naturalness varies by voice, not just by provider. Match the voice style to the use case: a calm narration voice for e-learning, an energetic voice for marketing content, a neutral voice for IVR.
Then tune the delivery. Adjust speaking rate for comprehension, since learners and IVR callers need slower speech than podcast listeners. Adjust pitch slightly when a voice sounds monotone. Insert explicit pauses at sentence boundaries and around lists, either through SSML-style markup where supported or by splitting text into separate synthesis requests.
Finally, post-process the audio. Light noise reduction and loudness normalization make synthesized speech sit correctly alongside recorded audio in a mixed production, which matters for podcasts and video localization.
The loop above is the discipline that separates good Persian audio from great Persian audio. Iterate on text and settings based on listening tests with native speakers, not just automated metrics.
Real-World Use Cases for Persian TTS
Persian text to speech already powers production systems across several industries, and the patterns are well established.
In e-learning, Persian TTS narrates course content at scale, letting platforms produce Persian audio for thousands of lessons without recording studios. A single well-tuned Persian voice can narrate an entire curriculum, and updates cost minutes instead of re-recording sessions. In podcast creation, producers draft scripts in Persian and generate draft narration instantly, recording final episodes only where a human host is essential.
For call centers serving Persian-speaking customers, IVR systems use pre-synthesized or on-the-fly Persian prompts for menus, confirmations, and status updates. Combined with real-time communication platforms like VideoSDK's audio and voice room capabilities, Persian TTS can also voice AI agents that hold live conversations with callers. Video localization teams use Persian TTS to generate narration tracks for videos originally produced in other languages, and accessibility teams use it to give visually impaired Persian readers instant spoken versions of articles, documents, and interfaces.
Future Trends in Persian Text to Speech
Four trends are reshaping Persian TTS right now. First, multilingual models that treat Persian as a first-class language rather than an afterthought are becoming the default, improving naturalness without dedicated per-language training. Second, Persian voice cloning is moving from novelty to production tool: a few seconds of reference audio can now produce a custom Persian voice, which changes audiobook and brand-voice economics entirely.
Third, low-latency edge inference is bringing Persian TTS onto devices, enabling offline reading assistants and privacy-preserving applications where text never leaves the phone. Fourth, emotion-aware synthesis is emerging, where the model adjusts tone based on the emotional content of the text, producing narration that sounds genuinely expressive rather than uniformly pleasant. Providers building real-time voice AI pipelines, such as VideoSDK's AI voice agent platform, are already combining these trends into conversational Persian agents.
Definitions Glossary
Persian Text to Speech (TTS): The automated conversion of written Farsi text into synthesized spoken audio, requiring handling of right-to-left script, contextual letter forms, and unwritten short vowels.
Phoneme: The smallest unit of sound in a language. Persian TTS converts text into phonemes before generating audio, and Persian contains sounds absent from English.
Neural Vocoder: The final pipeline stage that converts a model's spectrogram output into an audible waveform, with HiFi-GAN being a widely used architecture.
Voice Cloning: Creating a synthetic voice from a short sample of a real speaker's audio, increasingly supported for Persian by commercial TTS providers.
Streaming Synthesis: Returning synthesized audio in chunks as it is generated rather than as a complete file, reducing perceived latency for interactive applications.
Key Takeaways
- Persian text to speech requires dedicated language handling, because contextual letter forms and unwritten short vowels defeat generic English-first engines.
- Most audio quality problems trace back to text preprocessing, not the model, so invest in normalization, diacritics, and punctuation before switching providers.
- Choose providers by use case: VideoSDK for real-time Persian voice in live rooms, ElevenLabs for maximum naturalness, Piper for free self-hosted synthesis.
- Always proxy TTS requests through your backend, cache aggressively, and smooth request rates to stay within provider quotas.
- Streaming synthesis is the right choice whenever a user is waiting, while batch synthesis suits audiobooks and e-learning narration.
Conclusion
Persian text to speech has crossed the threshold from usable to genuinely production-ready, and the barrier for developers is now integration effort rather than output quality. The winning approach is simple: pick a provider whose Persian voices pass your listening tests, prepare your text carefully, secure your API keys behind a backend, and iterate on delivery settings with native-speaker feedback. If you are building interactive voice experiences, explore how VideoSDK's AI voice agents combine Persian TTS with real-time rooms, or start with the free tier and hear the difference yourself. What are you building with Persian text to speech? Drop a comment, I would love to hear what kind of Persian audio use case you are working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ