


Azure text to speech is the speech synthesis capability inside Microsoft's Azure AI Speech Service, converting written text into natural-sounding spoken audio using neural voices across more than 140 languages and locales. Developers integrate it through the Azure Speech SDK or a REST speech synthesis API, choosing between real-time streaming and batch synthesis depending on latency needs. If you're building voice-first products, start with Azure Speech Studio to audition voices, then pick an integration path using the Azure Speech docs. You can also pair Azure TTS with real-time communication platforms like VideoSDK to build AI voice agents that speak directly into live sessions.
Voice is becoming the default interface for a growing share of software. Support bots answer calls, e-learning platforms narrate lessons, and accessibility features read screens aloud. Behind all of these experiences sits a text-to-speech engine, and for many development teams that engine is Azure text to speech.
The reason is straightforward: Azure's neural voices produce audio that listeners frequently mistake for human recordings, the service covers an enormous range of languages, and it scales from a single prototype request to millions of characters per month without an architecture rewrite. This guide walks through what the service does, how the synthesis pipeline actually works, which integration method to choose, and how to keep quality high and costs predictable.
Understanding Azure Text to Speech
Azure text to speech is defined as the speech synthesis component of Azure AI Speech, part of Microsoft's Azure AI services (formerly Azure Cognitive Services). It accepts plain text or SSML-formatted input and returns synthesized audio, either as a streamed response for interactive applications or as a file for offline processing.
The service works by passing your text through neural network models trained on large speech corpora. These models, which Microsoft calls neural text-to-speech voices, predict pronunciation, intonation, and speaking rhythm rather than stitching together recorded fragments the way older concatenative systems did. The result is prosody that adapts to context: a question rises at the end, a list item gets a slight pause, an exclamation carries emphasis.
There are two tiers of voices to understand. Standard neural voices are prebuilt and available to every subscription immediately. Custom voice models are fine-tuned versions trained on your own recorded samples, producing a voice that sounds like a specific person or brand persona. Custom voice access requires an approval process because Microsoft enforces responsible-use policies for voice cloning, a distinction that matters for compliance-heavy industries.
Key Capabilities of Azure Text to Speech
Azure text to speech ships with a broad out-of-the-box voice catalog plus optional layers for customization and visual output. Knowing what each tier offers prevents you from over-engineering a solution that a standard voice already covers.
Standard Neural Voices
The prebuilt catalog includes hundreds of neural voices spanning more than 140 languages and locale variants, including multilingual voices that can switch languages mid-utterance. Many voices support speaking styles such as cheerful, empathetic, or newscast, and roles that let a single voice portray different characters in a dialogue. Quality is consistent across the catalog because every voice runs on the same underlying neural architecture, so choosing among them is mostly a matter of brand fit and language coverage rather than technical trade-offs.
Custom Voice Creation
Azure custom voice lets you train a voice model on your own speech recordings. The professional voice option targets enterprise brand voices and requires a minimum amount of clean training data plus Microsoft's responsible-AI review before deployment. The personal voice option, designed for individuals to create a voice resembling themselves, is gated behind explicit consent verification. These guardrails exist because voice cloning carries real misuse potential, and Microsoft restricts custom voice features to approved use cases. If your project needs a distinctive brand voice, plan for the approval lead time in your schedule.
Avatar Integration
For scenarios where a talking face matters as much as the voice, Azure AI Speech also offers a text-to-speech avatar feature. It renders a photorealistic or cartoon-style avatar that lip-syncs to synthesized speech in near real time. Typical uses include virtual news presenters, product demonstrators, and interactive kiosk characters. Avatar usage is priced separately from standard synthesis, so treat it as an add-on capability rather than part of the base TTS offering.
How Azure Text to Speech Works
Azure text to speech works by running your input through a multi-stage neural pipeline, and understanding that pipeline helps you diagnose quality issues later. The flow starts with text normalization, where numbers, abbreviations, dates, and currency amounts are expanded into speakable words. Next comes linguistic analysis, which tags each word with phonemes and part-of-speech information. Prosody prediction then maps those phonemes to pitch contours, durations, and energy levels, deciding where the voice pauses and which words get emphasis. Finally, a neural vocoder converts the prosody-annotated phoneme sequence into an audio waveform in your requested output format.
On the integration side, your application authenticates against a regional Azure endpoint, submits the text, and receives audio either streamed in chunks or returned as a complete file. The diagram below shows the end-to-end path a typical request takes.
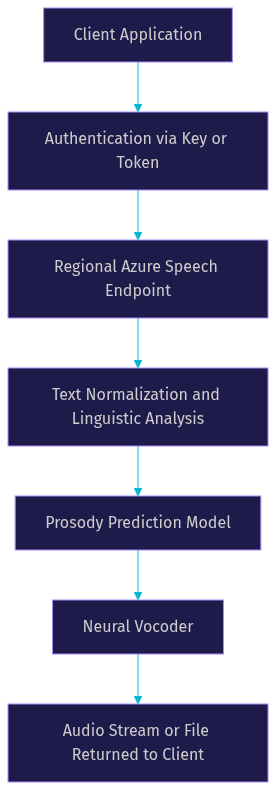
Two details in this flow deserve attention. First, authentication happens per request region, so the endpoint you target must match where your Speech resource was created. Second, streaming responses begin returning audio before synthesis completes, which is what makes sub-second time-to-first-audio possible in interactive applications.
Getting Started: Prerequisites and Resource Setup
To use Azure text to speech you need three things: an active Azure subscription, a Speech resource created in the Azure portal, and the access credentials attached to that resource. Creating the Speech resource involves selecting a region, and that region choice determines your endpoint URL, available voice catalog nuances, and in some cases pricing. After creation, the portal exposes a key pair and a region identifier that your application uses for authentication.
Region selection deserves a moment of thought. Choose a region geographically close to your users to minimize round-trip latency, and confirm that region supports the specific features you need, since custom voice and avatar availability varies by geography. Once the resource exists, you can audition every voice interactively in Azure Speech Studio without writing any integration code, which is the fastest way to shortlist voices before committing to an implementation.
Choosing an Integration Method
Azure exposes speech synthesis through two surfaces: the Azure Speech SDK and a REST text-to-speech API. Both produce the same audio; the right choice depends on your runtime environment and how much control you need over the synthesis lifecycle.
Azure Speech SDK
The Speech SDK is the richer integration path. It handles connection management, streaming audio delivery, word-boundary events, viseme events for lip-sync animation, and automatic token refresh in supported languages. Use it when you're building interactive clients, mobile apps, or real-time voice agents where you need event-level telemetry as speech plays. It's also the only path that surfaces fine-grained synthesis events, which matters for karaoke-style highlighting or avatar synchronization.
REST Text-to-Speech API
The REST API is the lightweight, language-agnostic option. Any environment that can make an authenticated HTTP request and handle the response can use it, which makes it ideal for server-side batch jobs, scripting pipelines, and platforms where the SDK isn't distributed. The trade-off is that you manage authentication headers, request formatting, and error handling yourself, and you lose the SDK's event stream.
| Integration method | Best for | Streaming events | Setup complexity |
|---|---|---|---|
| Azure Speech SDK | Real-time apps, voice agents, lip-sync | Yes, word and viseme boundaries | Moderate, package install per platform |
| REST API | Batch jobs, server scripts, any language | No, response-based only | Low, plain HTTP requests |
For most interactive products the SDK wins on capability; for background narration generation the REST path wins on simplicity.
Real-Time vs. Batch Synthesis
Azure supports two synthesis modes that map to different latency expectations. Real-time synthesis streams audio back as it is generated, with time-to-first-audio typically well under a second on a warm connection, making it the mode for conversational agents, live avatars, and interactive reading. Batch synthesis submits larger text volumes and returns audio files when processing completes, suited to pre-generating podcast episodes, course narration, or IVR prompts where a delay of minutes is irrelevant.
Triggering each mode differs by surface. The SDK's synthesis operations run in real time by default, while batch processing is available through the long-running audio creation API, which accepts documents up to the service's size limits and produces downloadable files. A practical pattern many teams adopt is hybrid: use batch synthesis to pre-render static content and real-time synthesis for anything dynamic or user-specific, which keeps interactive latency low while controlling cost.
Best Practices for Quality and Performance
Quality in Azure text to speech is mostly a function of input preparation and configuration discipline. Choose the voice that matches your content's tone and audience rather than defaulting to the first option, and prefer region-specific voices when your text contains local vocabulary. Use SSML to control pronunciation of unusual terms, insert natural pauses at sentence boundaries, and set speaking rate and pitch where the default prosody doesn't fit. Selecting the right audio output format also matters: compressed formats reduce bandwidth for streaming scenarios, while higher-fidelity formats serve published media.
For performance, keep connections warm in high-frequency interactive scenarios, handle token renewal proactively rather than waiting for expiry errors, and monitor synthesis latency per region. If you're streaming synthesized speech into a live communication session, platforms like VideoSDK's AI agent pipeline handle the delivery side, including turn detection and TTS caching, so your Azure integration only needs to produce the audio.
Pricing and Cost Management
Azure text to speech is billed per character of text submitted for synthesis, with standard neural voices priced lower than custom voice models, and avatar usage billed separately again. Regional price differences exist, so the same character volume can cost different amounts depending on where your resource lives. Free tier allowances let you prototype at no cost before committing, and Microsoft's pricing page carries the current numbers, which change periodically.
To manage spend, estimate monthly character volume from your content pipeline, then apply the per-character rate for your chosen voice tier. Two habits keep bills predictable: cache synthesized audio for repeated phrases instead of re-synthesizing identical text, and route high-volume static content through batch synthesis where you can schedule and audit it. Teams building conversational agents should also watch character counts per turn, since verbose system prompts multiplied across thousands of sessions add up quickly.
Real-World Use Cases
Azure text to speech powers production systems across several recognizable categories, and the neural quality is usually the deciding factor.
Customer Support Bots
Support bots use real-time synthesis to speak responses in voice channels, where robotic delivery would destroy user trust. Azure's neural voices, combined with speaking styles like empathetic, let a bot acknowledge a frustrated customer in a tone that matches the moment. Teams integrating these bots into phone or web-call experiences often bridge Azure TTS through a real-time communication layer such as VideoSDK's telephony integration, which connects synthesized speech to SIP and WebRTC call paths.
E-Learning Narration
E-learning platforms use batch synthesis to narrate course content at scale, converting written curricula into audio lessons without studio recording costs. Multilingual voices let a single course ship in many languages, and consistent voice identity across lessons improves learner focus. Pre-generating audio through the batch API also decouples narration production from playback, so students stream finished files rather than waiting on live synthesis.
Accessibility Features
Accessibility implementations use real-time synthesis to read interface content aloud for users with visual impairments or reading difficulties. Here, latency and pronunciation accuracy matter most: screen-reader-style experiences need audio to begin almost immediately after focus changes, and SSML pronunciation tuning ensures product-specific terminology is spoken correctly. Azure's broad language coverage also makes multilingual accessibility feasible without maintaining separate engines per locale.
Common Pitfalls and Troubleshooting
Four issues account for most Azure text to speech integration pain. Authentication failures usually trace to token or key expiry, so implement proactive renewal and treat a 401 response as a credential refresh trigger rather than a crash. Region mismatch errors appear when your application targets an endpoint that differs from the resource's home region; the fix is verifying that the region in your request matches the one shown in the portal for your resource.
Audio clipping at the start or end of output typically comes from playback starting before the stream opens or stopping at the final chunk boundary rather than after it; padding your playback lifecycle slightly resolves it. Latency spikes in interactive scenarios often indicate cold connections or a distant region, so keep sessions warm and confirm your resource region is near your users. When problems persist, Azure Speech Studio's testing tools let you reproduce synthesis behavior outside your application, isolating whether the issue is in the service call or your client code.
Definitions Glossary
Azure text to speech: The speech synthesis component of Azure AI Speech that converts text input into natural-sounding spoken audio using neural network models.
Neural text-to-speech voice: A voice generated by models that predict pronunciation, intonation, and rhythm from context, rather than assembling recorded speech fragments.
Custom voice model: A voice trained on your own recorded speech samples, available after Microsoft's responsible-use review, producing a brand-specific or person-specific voice.
SSML: Speech Synthesis Markup Language, an XML-based format for controlling pronunciation, pauses, rate, and pitch in synthesized speech.
Batch synthesis: A mode that submits large text volumes and returns completed audio files, suited to pre-generating narration rather than interactive playback.
Key Takeaways
- Azure text to speech provides neural voices across more than 140 languages, with real-time streaming and batch modes covering both interactive and offline scenarios.
- Choose the Azure Speech SDK for event-rich interactive applications and the REST API for language-agnostic or server-side batch work.
- Custom voice models unlock brand-specific voices but require Microsoft's responsible-use approval, so plan lead time.
- Cost is billed per character, so cache repeated phrases and route static content through batch synthesis to control spend.
- For live voice agents, pairing Azure TTS with a real-time communication platform like VideoSDK handles delivery, turn detection, and session management.
Conclusion
Azure text to speech remains one of the most capable speech synthesis services available to developers in 2026, combining broad language coverage, genuinely natural neural voices, and flexible integration paths. The fastest way to evaluate it is to open Azure Speech Studio, audition voices against your own content, and prototype with the free tier before committing to an architecture. When you're ready to build a full voice experience, the Azure Speech quickstart covers setup, and VideoSDK's AI agents documentation shows how to deliver synthesized speech inside real-time sessions. What are you building with Azure text to speech? Drop a comment, I'd love to hear what kind of voice experience you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ