


An LLM voice model is a text-to-speech system that uses a large language model to generate speech directly from text prompts, replacing traditional TTS pipelines with an end-to-end approach. These models leverage audio tokenizers and diffusion decoders to produce highly expressive, multilingual, and natural-sounding speech. Developers use them to build real-time voice agents, multi-speaker podcasts, and interactive conversational applications.
The landscape of speech generation is undergoing a massive shift. Developers are moving away from traditional concatenative and parametric text-to-speech pipelines toward end-to-end LLM voice models. This transition matters because large language models bring contextual understanding, zero-shot voice cloning, and nuanced emotional control to speech synthesis. Older TTS systems often sounded robotic and required extensive manual tuning to handle different languages or emotional tones. They relied on fragile pipelines where errors in early stages compounded in later ones. An LLM voice model learns the patterns of human speech directly from data, allowing it to generate highly expressive audio with minimal configuration. If you are building real-time voice agents, interactive gaming characters, or automated podcast generation tools, understanding the architecture and capabilities of these models is essential. The latest generation of LLM voice models supports sub-100 millisecond streaming latency, multi-speaker dialogue, and mid-sentence language switching. We will explore the core architecture, key innovations, prominent open-source projects, and practical integration considerations for deploying these models in production environments.
What Is an LLM Voice Model?
An LLM voice model is defined as a speech synthesis system where a large language model generates semantic and acoustic tokens that a decoder or diffusion model converts into audio waveforms. Traditional TTS systems rely on complex pipelines involving text normalization, grapheme-to-phoneme conversion, duration prediction, and acoustic feature generation. Each stage requires separate training and optimization, creating bottlenecks and error accumulation. An LLM voice model collapses these steps into a unified neural architecture.
Instead of predicting text tokens, the LLM predicts audio tokens. These tokens represent discrete units of sound. The LLM handles prosody, pacing, and emotional tone based on the input text and any provided speaker prompts. This approach allows the model to capture the nuances of human speech that traditional systems often miss. For example, an LLM voice model can infer that a question should end with a rising pitch or that a sad statement should have a slower cadence, all without explicit prosody tags. The model learns these patterns from the vast amount of audio data it was trained on. VideoSDK provides robust infrastructure for integrating these models into real-time applications through its AI Voice Agent SDK, handling the complex media routing and session management required for live voice interactions.
Core Architecture Overview
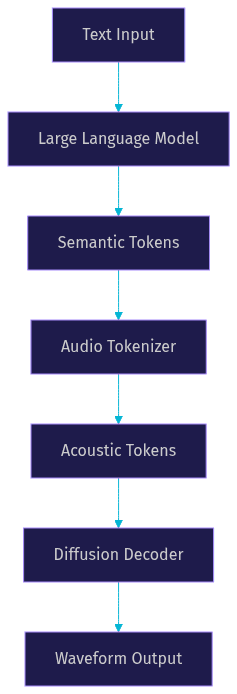
The high-level flow of an LLM voice model starts with text input. The LLM processes this text and generates semantic tokens that represent the linguistic content and prosodic intent. These semantic tokens are then passed to an audio tokenizer, which converts them into acoustic tokens containing finer audio details like timbre and ambient noise. Finally, a diffusion decoder or vocoder transforms these acoustic tokens into a continuous audio waveform. This multi-stage approach allows the LLM to focus on language modeling while specialized components handle audio synthesis.
Key Innovations Driving Modern LLM Voice Models
Modern LLM voice models achieve their impressive performance through several key architectural innovations. Continuous speech tokenizers, diffusion-based generation, and instruction-tuned control are the primary drivers of improved fidelity, efficiency, and expressiveness. These innovations enable long-form generation, multi-speaker dialogue, and low-latency streaming that were previously impossible with older TTS technologies. By reducing the computational load and improving the quality of generated audio, these advancements make real-time voice agents viable for production use.
Continuous Speech Tokenizers
Continuous speech tokenizers represent audio as a smooth, continuous stream rather than discrete, choppy segments. This approach preserves the natural flow of human speech. By using low-frame-rate tokenization, such as 7.5 Hz or 12 Hz, models can process audio more efficiently. A 7.5 Hz tokenizer means the model generates only 7.5 tokens per second of audio, compared to traditional models that might require 50 or 100 tokens per second. Lower frame rates mean fewer tokens to generate per second of audio, which directly reduces computational overhead and enables faster streaming responses. This efficiency is critical for running models on consumer hardware or achieving sub-100 millisecond latency in cloud environments.
Diffusion Heads for Acoustic Detail
While LLMs excel at predicting semantic tokens, they often lack the fine-grained acoustic detail needed for high-fidelity audio. Diffusion heads solve this problem by taking coarse semantic tokens and gradually refining them into high-quality acoustic features. The diffusion process works by starting with random noise and iteratively removing noise to reveal the target audio waveform. This process adds natural breath sounds, mic characteristics, and subtle vocal textures that make the speech indistinguishable from a human recording. The tradeoff is that diffusion requires multiple steps, which can increase latency, but modern optimizations have made it fast enough for real-time applications.
Instruction-Based Control
Instruction-tuned control allows developers to steer the voice model using natural language prompts. You can instruct the model to speak faster, sound happier, or adopt a specific accent without changing the core text. This capability is crucial for building dynamic voice agents that need to adapt their tone based on user interaction. For example, you could prompt the model with "Speak in a cheerful and energetic tone" or "Speak slowly and calmly." By embedding instructions directly into the prompt, the LLM voice model adjusts its prosody and emotional delivery in real time. This level of control was previously only possible with complex markup languages or manual audio editing.
Prominent Open-Source LLM Voice Models
The open-source community has rapidly produced several powerful LLM voice models. Each project takes a slightly different approach to architecture, tokenization, and deployment. Choosing the right one depends on your specific needs for latency, language support, and hardware environment. Let us look at some of the leading options available to developers in 2026.
VibeVoice
VibeVoice specializes in long-form generation and multi-speaker scenarios. It uses a 7.5 Hz tokenizer, which makes it highly efficient for generating extended audio content like podcasts or audiobooks. Its architecture maintains speaker consistency over long contexts, preventing the voice from drifting or changing characteristics over time. This model is a strong choice for narrative applications where maintaining a consistent character voice is essential. The lower frame rate also makes it accessible to developers without access to high-end data center GPUs.
Qwen3-TTS
Qwen3-TTS features a 12 Hz tokenizer designed for sub-100 millisecond streaming latency. This model excels in real-time conversational applications where immediate feedback is critical. Its architecture is optimized for interactive voice agents that need to respond instantly to user input. The 12 Hz frame rate strikes a balance between the efficiency of lower frame rates and the fidelity of higher ones. Qwen3-TTS also supports multiple languages out of the box, making it versatile for global applications.
CosyVoice
CosyVoice offers robust zero-shot multilingual capabilities with a streaming latency of around 150 milliseconds. It can clone voices from a short reference clip and generate speech in multiple languages. This model is ideal for global applications that require rapid deployment across different language markets. The zero-shot capability means you do not need to fine-tune the model for each new voice, saving significant development time. CosyVoice handles cross-lingual voice cloning well, allowing a single speaker's voice to be used across different languages.
Higgs TTS 2
Higgs TTS 2 introduces a dual-FFN adapter and a 25 fps tokenizer. The dual-feed-forward network improves the model's ability to capture complex acoustic details. While the higher frame rate demands more compute, it delivers exceptional fidelity for high-end audio production. This model is suited for applications where audio quality is the top priority, such as professional audiobook narration or virtual assistant interfaces. The dual-FFN adapter helps the model maintain stability during long generation sequences.
Gemini Flash TTS
Gemini Flash TTS provides granular expressive tags for real-time control over speech characteristics. Developers can use these tags to dynamically adjust emotion, pacing, and emphasis during generation. This model is well-suited for interactive gaming and virtual characters that need expressive, adaptive voices. The ability to control speech characteristics in real time allows for more immersive and engaging user experiences. Gemini Flash TTS integrates well with game engines and interactive platforms.
Lightning V3
Lightning V3 focuses on instruction-following and mid-sentence language switching. It can seamlessly transition from English to Spanish within a single sentence if instructed. This feature makes it perfect for bilingual applications and language learning platforms. The model's strong instruction-following capabilities also make it easy to control without needing complex prompt engineering. Lightning V3 is designed to be highly responsive to user commands, making it a good fit for conversational agents.
OmniVoice
OmniVoice is a massively multilingual model optimized for Apple MLX. This optimization allows it to run efficiently on Apple Silicon, making it a top choice for local, on-device deployment without relying on cloud GPUs. OmniVoice supports a wide range of languages and dialects, making it one of the most versatile open-source models available. The Apple MLX optimization ensures that it can leverage the unified memory architecture of Apple devices for fast, efficient inference.
How to Choose the Right LLM Voice Model for Your Project
Selecting the right LLM voice model requires evaluating your project constraints against model capabilities. You need to consider latency requirements, language coverage, speaker count, model size, and hardware limitations. A clear decision framework helps narrow down the options. Licensing is also a critical factor, as some open-source models have restrictions on commercial use.
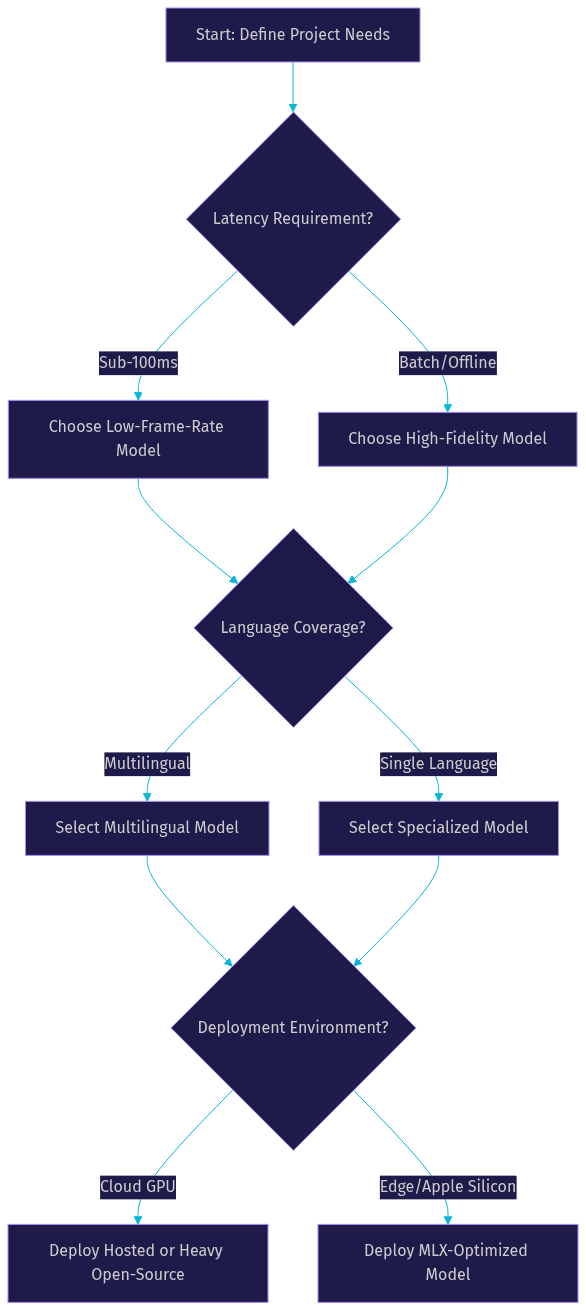
Here is a comparison of the models we discussed across key dimensions.
| Model | Latency | Language Support | Best Feature | Best For |
|---|---|---|---|---|
| VibeVoice | Moderate | Multiple | 7.5 Hz efficiency | Long-form podcasts |
| Qwen3-TTS | Sub-100ms | Multiple | Low-latency streaming | Real-time voice agents |
| CosyVoice | 150ms | Multilingual | Zero-shot cloning | Global applications |
| Higgs TTS 2 | Higher | Multiple | Dual-FFN adapter | High-fidelity audio |
| Gemini Flash TTS | Real-time | Multiple | Expressive tags | Interactive gaming |
| Lightning V3 | Low | Bilingual | Mid-sentence switching | Language learning |
| OmniVoice | Variable | Massively multilingual | Apple MLX support | On-device deployment |
[LINKABLE ASSET — comparison table]
If you need real-time interaction, Qwen3-TTS or Gemini Flash TTS are strong choices. If you need to run locally on a Mac, OmniVoice is the clear winner. For long-form content where latency is less critical, VibeVoice offers excellent efficiency.
Practical Integration Considerations
Integrating an LLM voice model into a production application involves more than just loading a model. You need to handle token generation, streaming APIs, long context windows, and speaker consistency. Deployment environments also dictate your architecture, whether you are using cloud GPUs, Apple Silicon, or a hybrid setup. Production-grade concerns such as HTTPS, rate limiting, and monitoring are essential for a stable deployment. You also need to consider how the voice model integrates with your existing backend services and client applications.
Token Server & Authentication
You should never expose your API keys or model weights directly to the client. A backend token service is essential for secure communication. This service generates short-lived tokens that authenticate client requests to your voice model endpoint. VideoSDK uses token-based authentication to secure access to its rooms and media streams. You can learn more about this in the VideoSDK authentication guide. The token server should run in a trusted environment and validate user sessions before issuing tokens. It should also enforce rate limiting to prevent abuse and ensure fair usage across all clients. When a client wants to initiate a voice session, it requests a token from your server, which it then passes to the VideoSDK client SDK to join a room.
Streaming vs Batch Generation
Streaming mode is critical for real-time voice agents. In streaming mode, the model outputs audio chunks as they are generated, reducing the time to first audio. This allows the user to hear the beginning of the response while the rest is still being generated. Batch generation processes the entire text at once, which is better for offline content like audiobooks where maximum fidelity matters more than latency. You should choose streaming when the user expects an immediate conversational response. Implementing streaming requires careful handling of audio buffers to avoid gaps or pops in the playback. The client application must be able to receive audio chunks over a WebSocket or similar real-time protocol and feed them to the audio playback system seamlessly.
Multi-Speaker Management
Maintaining speaker identity in multi-speaker generation is a common challenge. Techniques include using distinct speaker embeddings for each role and conditioning the LLM on a speaker prompt. You must ensure the model does not bleed vocal characteristics between speakers. Managing context length is also vital, as long dialogues can cause the model to forget the initial speaker profiles. Some models handle this better than natively, while others require external memory management to track speaker state across turns. In a production environment, you might need to implement a speaker tracking system that maintains a database of speaker embeddings and injects them into the model context as needed. This ensures that each speaker maintains a consistent voice throughout the conversation.
Future Trends and Research Directions
The field of LLM voice models is moving rapidly toward fully multimodal voice agents. Future research focuses on real-time voice-to-voice translation without intermediate text representation, which would eliminate translation latency entirely. This requires models that can process audio input directly and generate audio output in a different language, without ever converting to text. Adaptive prosody models that learn a user's emotional state from audio input are also gaining traction. These models could adjust their tone based on whether the user sounds frustrated or happy, creating more empathetic interactions. Benchmark initiatives are emerging to standardize evaluation metrics for these new capabilities, helping developers compare models on objective criteria rather than vendor marketing. As these trends mature, we can expect voice agents to become indistinguishable from human conversational partners, capable of handling complex, multi-turn dialogues with natural emotional intelligence.
Definitions Glossary
LLM Voice Model: A speech synthesis system that uses a large language model to generate audio tokens from text, replacing traditional TTS pipelines with an end-to-end neural approach.
Audio Tokenizer: A component that converts semantic tokens from an LLM into acoustic tokens containing fine-grained audio details for waveform generation.
Continuous Speech Tokenization: A method of representing audio as a smooth stream of tokens at low frame rates, improving generation efficiency and fidelity.
Diffusion Head: A neural network component that refines coarse acoustic tokens into high-fidelity audio waveforms by gradually adding natural acoustic details.
Streaming Latency: The time it takes for a voice model to generate and output the first chunk of audio after receiving a text input.
Key Takeaways
- An LLM voice model replaces traditional TTS pipelines with a unified architecture that generates semantic and acoustic tokens directly from text.
- Continuous speech tokenizers and diffusion heads are the primary innovations driving high fidelity and low latency in modern voice models.
- Open-source models like VibeVoice, Qwen3-TTS, and OmniVoice offer specialized capabilities for different use cases, from long-form podcasts to on-device deployment.
- Secure integration requires a backend token server to manage authentication and protect API keys.
- VideoSDK provides the real-time infrastructure needed to connect LLM voice models into interactive voice agent applications.
Conclusion
The shift to LLM voice models represents a major leap in speech synthesis quality and flexibility. By understanding the architecture, innovations, and available open-source projects, you can select the right model for your specific needs. Whether you are building a real-time voice agent, a multilingual chatbot, or an automated podcast platform, these models provide the tools you need. Explore how VideoSDK can help you deploy these models in production by checking out the VideoSDK AI Voice Agent documentation. What are you building with LLM voice models? Drop a comment below.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ